WO2018188571A1 - 基因组编辑系统和方法 - Google Patents
基因组编辑系统和方法 Download PDFInfo
- Publication number
- WO2018188571A1 WO2018188571A1 PCT/CN2018/082446 CN2018082446W WO2018188571A1 WO 2018188571 A1 WO2018188571 A1 WO 2018188571A1 CN 2018082446 W CN2018082446 W CN 2018082446W WO 2018188571 A1 WO2018188571 A1 WO 2018188571A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- seq
- sequence
- protein
- disease
- crrna
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Images
Classifications
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N15/00—Mutation or genetic engineering; DNA or RNA concerning genetic engineering, vectors, e.g. plasmids, or their isolation, preparation or purification; Use of hosts therefor
- C12N15/09—Recombinant DNA-technology
- C12N15/11—DNA or RNA fragments; Modified forms thereof; Non-coding nucleic acids having a biological activity
- C12N15/113—Non-coding nucleic acids modulating the expression of genes, e.g. antisense oligonucleotides; Antisense DNA or RNA; Triplex- forming oligonucleotides; Catalytic nucleic acids, e.g. ribozymes; Nucleic acids used in co-suppression or gene silencing
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N15/00—Mutation or genetic engineering; DNA or RNA concerning genetic engineering, vectors, e.g. plasmids, or their isolation, preparation or purification; Use of hosts therefor
- C12N15/09—Recombinant DNA-technology
- C12N15/10—Processes for the isolation, preparation or purification of DNA or RNA
- C12N15/102—Mutagenizing nucleic acids
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61K—PREPARATIONS FOR MEDICAL, DENTAL OR TOILETRY PURPOSES
- A61K48/00—Medicinal preparations containing genetic material which is inserted into cells of the living body to treat genetic diseases; Gene therapy
- A61K48/005—Medicinal preparations containing genetic material which is inserted into cells of the living body to treat genetic diseases; Gene therapy characterised by an aspect of the 'active' part of the composition delivered, i.e. the nucleic acid delivered
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P25/00—Drugs for disorders of the nervous system
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P25/00—Drugs for disorders of the nervous system
- A61P25/14—Drugs for disorders of the nervous system for treating abnormal movements, e.g. chorea, dyskinesia
- A61P25/16—Anti-Parkinson drugs
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P25/00—Drugs for disorders of the nervous system
- A61P25/18—Antipsychotics, i.e. neuroleptics; Drugs for mania or schizophrenia
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P25/00—Drugs for disorders of the nervous system
- A61P25/28—Drugs for disorders of the nervous system for treating neurodegenerative disorders of the central nervous system, e.g. nootropic agents, cognition enhancers, drugs for treating Alzheimer's disease or other forms of dementia
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P25/00—Drugs for disorders of the nervous system
- A61P25/30—Drugs for disorders of the nervous system for treating abuse or dependence
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P27/00—Drugs for disorders of the senses
- A61P27/02—Ophthalmic agents
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P29/00—Non-central analgesic, antipyretic or antiinflammatory agents, e.g. antirheumatic agents; Non-steroidal antiinflammatory drugs [NSAID]
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P35/00—Antineoplastic agents
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P43/00—Drugs for specific purposes, not provided for in groups A61P1/00-A61P41/00
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61P—SPECIFIC THERAPEUTIC ACTIVITY OF CHEMICAL COMPOUNDS OR MEDICINAL PREPARATIONS
- A61P9/00—Drugs for disorders of the cardiovascular system
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N15/00—Mutation or genetic engineering; DNA or RNA concerning genetic engineering, vectors, e.g. plasmids, or their isolation, preparation or purification; Use of hosts therefor
- C12N15/09—Recombinant DNA-technology
- C12N15/63—Introduction of foreign genetic material using vectors; Vectors; Use of hosts therefor; Regulation of expression
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N15/00—Mutation or genetic engineering; DNA or RNA concerning genetic engineering, vectors, e.g. plasmids, or their isolation, preparation or purification; Use of hosts therefor
- C12N15/09—Recombinant DNA-technology
- C12N15/87—Introduction of foreign genetic material using processes not otherwise provided for, e.g. co-transformation
- C12N15/90—Stable introduction of foreign DNA into chromosome
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N15/00—Mutation or genetic engineering; DNA or RNA concerning genetic engineering, vectors, e.g. plasmids, or their isolation, preparation or purification; Use of hosts therefor
- C12N15/09—Recombinant DNA-technology
- C12N15/87—Introduction of foreign genetic material using processes not otherwise provided for, e.g. co-transformation
- C12N15/90—Stable introduction of foreign DNA into chromosome
- C12N15/902—Stable introduction of foreign DNA into chromosome using homologous recombination
- C12N15/907—Stable introduction of foreign DNA into chromosome using homologous recombination in mammalian cells
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N9/00—Enzymes; Proenzymes; Compositions thereof; Processes for preparing, activating, inhibiting, separating or purifying enzymes
- C12N9/14—Hydrolases (3)
- C12N9/16—Hydrolases (3) acting on ester bonds (3.1)
- C12N9/22—Ribonucleases [RNase]; Deoxyribonucleases [DNase]
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N2310/00—Structure or type of the nucleic acid
- C12N2310/10—Type of nucleic acid
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N2310/00—Structure or type of the nucleic acid
- C12N2310/10—Type of nucleic acid
- C12N2310/20—Type of nucleic acid involving clustered regularly interspaced short palindromic repeats [CRISPR]
-
- C—CHEMISTRY; METALLURGY
- C12—BIOCHEMISTRY; BEER; SPIRITS; WINE; VINEGAR; MICROBIOLOGY; ENZYMOLOGY; MUTATION OR GENETIC ENGINEERING
- C12N—MICROORGANISMS OR ENZYMES; COMPOSITIONS THEREOF; PROPAGATING, PRESERVING, OR MAINTAINING MICROORGANISMS; MUTATION OR GENETIC ENGINEERING; CULTURE MEDIA
- C12N2800/00—Nucleic acids vectors
- C12N2800/80—Vectors containing sites for inducing double-stranded breaks, e.g. meganuclease restriction sites
Definitions
- the invention relates to the field of genetic engineering.
- the present invention relates to novel eukaryotic genome editing systems and methods. More specifically, the present invention relates to a CRISPR-Cpf1 system capable of efficiently editing a genome of a eukaryotic cell and uses thereof.
- the CRISPR (Clustered regular interspaced short palindromic repeats) system is an immune system in which bacteria generated during evolution are used to protect against foreign gene invasion.
- the type II CRISPR-Cas9 system is a system for DNA cleavage of a Cas9 protein by two small RNAs (crRNA and tracrRNA) or a synthetic small RNA (sgRNA), and is the first three discovered (I, II, Type III)
- the simplest system in the CRISPR system Due to its simplicity and ease of operation, the system was successfully rebuilt in 2013 and successfully completed the editing of the genome of eukaryotes.
- the CRISPR/Cas9 system quickly became the hottest technology in the life sciences.
- the invention provides a genome editing system for site-directed modification of a target sequence in a cellular genome comprising at least one of the following i) to v):
- Ii an expression construct comprising a nucleotide sequence encoding a Cpf1 protein, and a guide RNA;
- Iii a Cpf1 protein, and an expression construct comprising a nucleotide sequence encoding a guide RNA
- the Cpf1 protein comprises an amino acid sequence of one of SEQ ID Nos: 1-12 or an amino acid sequence having at least 80% sequence identity to one of SEQ ID Nos: 1-12, the guide RNA capable of expressing the Cpf1 protein Targeting the target sequence in the genome of the cell.
- the invention provides a method of site-directed modification of a target sequence in a cellular genome, comprising introducing a genome editing system of the invention into said cell, whereby said guide RNA targets said Cpf1 protein A target sequence in the genome of the cell results in the substitution, deletion and/or addition of one or more nucleotides in the target sequence.
- the invention provides a method of treating a disease in a subject in need thereof, comprising delivering to the subject an effective amount of a genome editing system of the invention to modify a gene associated with the disease in the subject .
- the invention provides the use of a genome editing system of the invention in the preparation of a pharmaceutical composition for treating a disease in a subject in need thereof, wherein said genome editing system is for modifying said object Disease-related genes.
- the present invention provides a pharmaceutical composition for treating a disease in a subject in need thereof, comprising a genome editing system of the present invention and a pharmaceutically acceptable carrier, wherein the genome editing system is for modifying A gene associated with the disease in the subject.
- the invention provides a crRNA comprising a crRNA backbone sequence corresponding to any one of SEQ ID NOs: 25-33, or a coding sequence thereof comprising the sequence set forth in any one of SEQ ID NOs: 25-33.
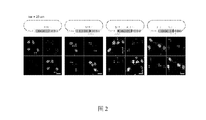
- FIG. 1 Immunofluorescence showing that the Cpfl protein is localized to the nucleus.
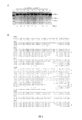
- Figure 3 Shows the ability of the Cpfl protein to edit human Dnmt1 site 3.
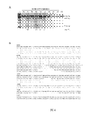
- Figure 4 Shows the ability of the Cpf1 protein to edit human Dnmt1 locus 1.
- Figure 5 Shows the editing ability of Cpf1 protein to human Dnmt1 site 2.
- A The T7EI assay showed that four Cpf1 proteins were clearly targeted to human Dnmt1 site 2.
- B. Sequencing results show representative indels in human Dnmt1 locus 2, of which 5 Cpf1 are capable of producing indel, although PsCpf1 has no significant bands in the enzyme digestion assay.
- FIG. 1 PAM sequence of BsCpfl in vitro assay.
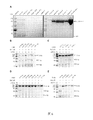
- A E. coli expression and purification of BsCpf1 protein.
- B-E Targeting BsCpf1 using 5'-TTN PAM.
- Figure 8. Shows the ability of HkCpf1 to edit 8 sites of the human AAVS1 gene.
- A T7EI measurement results.
- B Sequencing results showed that HkCpf1 was able to generate mutations at seven sites, and the PAM sequence was 5'-YYN, which was consistent with the results of Figure 7.
- FIGS 9, 10 and 11 show that four Cpf1 proteins edit the mouse genome in EpiSC cells.
- Figures 13-14 show the optimization of the crRNA backbone sequence.
- Figure 15. shows the various vector maps used.
- Cpf1 nuclease Cpf1 protein
- Cpf1 Cpf1
- Cpf1 protein Cpf1
- Cpf1 is a component of the CRISPR-Cpf1 genome editing system that targets and cleaves DNA target sequences to form DNA double-strand breaks (DSBs) under the guidance of a guide RNA (crRNA).
- DSB can activate the intrinsic repair mechanism in the cell, non-homologous end joining (NHEJ) and homologous recombination (HR) to repair DNA damage in cells. During the repair process, this specific The DNA sequence was subjected to fixed point editing.
- the guide RNA of the CRISPR-Cpf1 genome editing system is usually composed only of crRNA molecules, wherein the crRNA comprises sufficient identity with the target sequence to hybridize to the complement of the target sequence and direct the CRISPR complex (Cpf1+crRNA) to be specific to the target sequence. Sexually bound sequences.
- Genomic as used herein encompasses not only chromosomal DNA present in the nucleus but also organelle DNA present in subcellular components of the cell (eg, mitochondria, plastids).
- organism includes any organism, preferably a eukaryote, suitable for genome editing.
- organisms include, but are not limited to, mammals such as humans, mice, rats, monkeys, dogs, pigs, sheep, cows, cats; poultry such as chickens, ducks, geese; plants including monocots and dicots, For example, rice, corn, wheat, sorghum, barley, soybeans, peanuts, Arabidopsis, and the like.
- genetically modified organism or “genetically modified cell” is meant an organism or cell comprising an exogenous polynucleotide or modified gene or expression control sequence within its genome.
- an exogenous polynucleotide can be stably integrated into the genome of an organism or cell and inherits successive generations.
- the exogenous polynucleotide can be integrated into the genome either alone or as part of a recombinant DNA construct.
- the modified gene or expression control sequence is such that the sequence comprises single or multiple deoxynucleotide substitutions, deletions, and additions in the organism or cell genome.
- Exogenous with respect to a sequence means a sequence from a foreign species, or, if from the same species, a sequence that has undergone a significant change in composition and/or locus from its native form by deliberate human intervention.
- nucleic acid sequence is used interchangeably and are single- or double-stranded RNA or DNA polymers, optionally containing synthetic, non-natural Or altered nucleotide bases.
- Nucleotides are referred to by their single letter designation: "A” is adenosine or deoxyadenosine (corresponding to RNA or DNA, respectively), “C” means cytidine or deoxycytidine, and “G” means guanosine or Deoxyguanosine, “U” means uridine, “T” means deoxythymidine, “R” means ⁇ (A or G), “Y” means pyrimidine (C or T), “K” means G or T, “ H” represents A or C or T, “I” represents inosine, and “N” represents any nucleotide.
- Polypeptide “peptide”, and “protein” are used interchangeably herein and refer to a polymer of amino acid residues. The term applies to amino acid polymers in which one or more amino acid residues are artificial chemical analogs of the corresponding naturally occurring amino acid, as well as to naturally occurring amino acid polymers.
- polypeptide “peptide”, “amino acid sequence” and “protein” may also include modified forms including, but not limited to, glycosylation, lipid linking, sulfation, gamma carboxylation of glutamic acid residues, hydroxy And ADP-ribosylation.
- Sequence identity has art-recognized meaning, and the percentage of sequence identity between two nucleic acid or polypeptide molecules or regions can be calculated using the disclosed techniques. Sequence identity can be measured along the entire length of a polynucleotide or polypeptide or along a region of the molecule.
- identity is well known to the skilled person (Carrillo, H. & Lipman, D., SIAM J Applied Math 48: 1073 (1988). ).
- peptides or proteins suitable conservative amino acid substitutions are known to those skilled in the art, and one can be carried out without altering the biological activity of the resulting molecule.
- one skilled in the art recognizes that a single amino acid substitution in a non-essential region of a polypeptide does not substantially alter biological activity (see, for example, Watson et al., Molecular Biology of the Gene, 4th Edition, 1987, The Benjamin/Cummings Pub .co., p. 224).
- expression construct refers to a vector, such as a recombinant vector, suitable for expression of a nucleotide sequence of interest in an organism. "Expression” refers to the production of a functional product.
- expression of a nucleotide sequence can refer to transcription of a nucleotide sequence (eg, transcription to produce mRNA or functional RNA) and/or translation of RNA into a precursor or mature protein.
- An "expression construct" of the invention can be a linear nucleic acid fragment, a circular plasmid, a viral vector, or, in some embodiments, can be a translatable RNA (such as an mRNA).
- An "expression construct" of the invention may comprise regulatory sequences of different origin and nucleotide sequences of interest, or regulatory sequences of the same origin but arranged in a manner different from that normally found in nature, and nucleotide sequences of interest.
- regulatory sequences and “regulatory elements” are used interchangeably and refer to either upstream (5' non-coding sequences), intermediate or downstream (3' non-coding sequences) of a coding sequence, and affect transcription or RNA processing of related coding sequences or Stability or translated nucleotide sequence. Regulatory sequences can include, but are not limited to, promoters, translation leader sequences, introns, and polyadenylation recognition sequences.
- Promoter refers to a nucleic acid fragment that is capable of controlling the transcription of another nucleic acid fragment.
- a promoter is a promoter capable of controlling the transcription of a gene in a cell, whether or not it is derived from the cell.
- the promoter may be a constitutive promoter or a tissue-specific promoter or a developmentally regulated promoter or an inducible promoter.
- Constant promoter refers to a promoter that will cause expression of a gene in most cell types in most cases.
- tissue-specific promoter and “tissue-preferred promoter” are used interchangeably and mean primarily, but not necessarily exclusively, in a tissue or organ, and can also be expressed in a particular cell or cell type.
- Promoter “Development-regulated promoter” refers to a promoter whose activity is determined by developmental events.
- An “inducible promoter” selectively expresses a operably linked DNA sequence in response to an endogenous or exogenous stimulus (environment, hormone, chemical signal, etc.).
- operably linked refers to a regulatory element (such as, but not limited to, a promoter sequence, a transcription termination sequence, etc.) linked to a nucleic acid sequence (eg, a coding sequence or an open reading frame) such that the nucleotide Transcription of the sequence is controlled and regulated by the transcriptional regulatory elements.
- a regulatory element such as, but not limited to, a promoter sequence, a transcription termination sequence, etc.
- nucleic acid sequence eg, a coding sequence or an open reading frame
- Introducing" a nucleic acid molecule eg, a plasmid, a linear nucleic acid fragment, an RNA, etc.
- a protein into an organism means converting the organism cell with the nucleic acid or protein such that the nucleic acid or protein is capable of functioning in the cell.
- Transformation includes both stable and transient transformations.
- “Stable transformation” refers to the introduction of an exogenous nucleotide sequence into the genome, resulting in the stable inheritance of the foreign gene. Once stably transformed, the exogenous nucleic acid sequence is stably integrated into the genome of the organism and any of its successive generations.
- Transient transformation refers to the introduction of a nucleic acid molecule or protein into a cell to perform a function without the foreign gene being stably inherited. In transient transformation, the exogenous nucleic acid sequence is not integrated into the genome.
- the invention provides at least 80%, at least 85%, at least 90%, at least 95%, at least 96%, at least 97%, at least 98%, at least 99% comprising one of SEQ ID NOs: 1-12
- the invention provides a genome editing system for site-directed modification of a target sequence in a cellular genome, comprising at least one of the following i) to v):
- Ii an expression construct comprising a nucleotide sequence encoding a Cpf1 protein, and a guide RNA;
- Iii a Cpf1 protein, and an expression construct comprising a nucleotide sequence encoding a guide RNA
- the Cpf1 protein comprises the amino acid sequence of SEQ ID NOs: 1-12 or an amino acid sequence having at least 80% sequence identity to one of SEQ ID NOs: 1-12, the guide RNA capable of targeting the Cpf1 protein a target sequence in the genome of the cell.
- the guide RNA is a crRNA.
- the coding sequence of the crRNA comprises the crRNA backbone sequence set forth in any one of SEQ ID NOs: 25-33.
- the crRNA backbone sequence is SEQ ID NO:30.
- the coding sequence of the cRNA further comprises a sequence (i.e., a spacer sequence) at 3' of the cRNA backbone sequence that specifically hybridizes to the complement of the target sequence.
- the crRNA is encoded by a nucleotide sequence selected from the group consisting of:
- the sequence N x (spacer sequence) is capable of specifically hybridizing to the complement of the target sequence.
- the cell is a eukaryotic cell, preferably a mammalian cell.
- the Cpfl protein comprises at least 80%, at least 85%, at least 90%, at least 95%, at least 96%, at least 97% with one of SEQ ID NOs: 1-12 An amino acid sequence of at least 98%, at least 99%, or even 100% sequence identity.
- the Cpfl protein is capable of targeting and/or cleaving a target sequence in the genome of the cell by crRNA.
- the Cpfl protein comprises an amino acid sequence having one or more amino acid residue substitutions, deletions or additions relative to one of SEQ ID NOs: 1-12.
- the Cpf1 protein comprises 1, 2, 3, 4, 5, 6, 7, 8, 9, 10 amino acid residues relative to one of SEQ ID NOs: 1-12 Amino acid sequence substituted, deleted or added.
- the amino acid substitution is a conservative substitution.
- the Cpfl protein is capable of targeting and/or cleaving a target sequence in the genome of the cell by crRNA.
- the Cpf1 protein of the present invention may be derived from a species selected from the group consisting of Agathobacter rectalis, Lachnospira pectinoschiza, Sneathia amnii, Helcococcus kunzii, Arcobacter butzleri, Bacteroidetes oral, Oribacterium sp., Butyrivibrio sp., Proteocatella sphenisci, Candidatus Dojkabacteria, Pseudobutyrivibrio xylanivorans, Pseudobutyrivibrio ruminis .
- the Cpf1 protein is from Agathobacter rectalis (ArCpf1), Butyrivibrio sp. (BsCpf1), Helcococcus kunzii (HkCpf1), Lachnospira pectinoschiza (LpCpf1), Pseudobutyrivibrio ruminis (PrCpf1) or Pseudobutyrivibrio xylanivorans (PxCpf1) ).
- the Cpfl protein comprises a member selected from the group consisting of SEQ ID NO: 1, SEQ ID NO: 2, SEQ ID NO: 4, SEQ ID NO: 8, SEQ ID NO: 11, SEQ ID NO : 12 amino acid sequence.
- the Cpfl protein of the invention further comprises a nuclear localization sequence (NLS).
- NLS nuclear localization sequence
- one or more NLSs in the Cpfl protein should have sufficient strength to drive the Cpfl protein in the nucleus to accumulate an amount of its gene editing function.
- the strength of nuclear localization activity is determined by the number, location of the NLS in the Cpfl protein, one or more specific NLSs used, or a combination of these factors.
- the NLS of the Cpfl protein of the invention may be at the N-terminus and/or C-terminus.
- the Cpfl protein comprises about 1, 2, 3, 4, 5, 6, 7, 8, 9, 10 or more NLS.
- the Cpfl protein comprises about 1, 2, 3, 4, 5, 6, 7, 8, 9, 10 or more NLS at or near the N-terminus.
- the Cpfl protein comprises about 1, 2, 3, 4, 5, 6, 7, 8, 9, 10 or more NLS at or near the C-terminus.
- the Cpfl protein comprises a combination of these, such as one or more NLSs comprising an N-terminus and one or more NLSs at the C-terminus.
- the Cpfl protein comprises two NLSs, eg, the two NLSs are located at the N-terminus and the C-terminus, respectively.
- NLS consists of one or more short sequences of positively charged lysine or arginine exposed on the surface of the protein, but other types of NLS are also known.
- Non-limiting examples of NLS include: KKRKV (nucleotide sequence 5'-AAGAAGAGAAAGGTC-3'), PKKKRKV (nucleotide sequence 5'-CCCAAGAAGAAGAGGAAGGTG-3' or CCAAAGAAGAAGAGGAAGGTT), or SGGSPKKKRKV (nucleotide sequence 5'- TCGGGGGGGAGCCCAAAGAAGAAGCGGAAGGTG-3').
- the Cpfl protein of the invention may also include other localization sequences, such as cytoplasmic localization sequences, chloroplast localization sequences, mitochondrial localization sequences, and the like, depending on the location of the DNA to be edited.
- the nucleotide sequence encoding the Cpfl protein is codon optimized for the organism from which the cell to be genome edited is derived.
- Codon optimization refers to the replacement of at least one codon of a native sequence by a codon that is used more frequently or most frequently in the gene of the host cell (eg, about or more than about 1, 2, 3, 4, 5, 10) a method of simultaneously, 15, 20, 25, 50 or more codons maintaining the native amino acid sequence while modifying the nucleic acid sequence to enhance expression in a host cell of interest.
- a codon that is used more frequently or most frequently in the gene of the host cell eg, about or more than about 1, 2, 3, 4, 5, 10.
- Different species display certain codons for a particular amino acid Specific preferences. Codon preference (difference in codon usage between organisms) is often associated with the efficiency of translation of messenger RNA (mRNA), which is believed to be dependent on the nature of the translated codon and The availability of specific transport RNA (tRNA) molecules.
- mRNA messenger RNA
- tRNA transport RNA
- the organism from which the genome editable by the system of the present invention is derived is preferably a eukaryote, including, but not limited to, a mammal such as a human, a mouse, a rat, a monkey, a dog, a pig, a sheep, a cow, a cat; Poultry such as chickens, ducks, and geese; plants include monocots and dicots, such as rice, corn, wheat, sorghum, barley, soybeans, peanuts, Arabidopsis, and the like.
- a mammal such as a human, a mouse, a rat, a monkey, a dog, a pig, a sheep, a cow, a cat
- Poultry such as chickens, ducks, and geese
- plants include monocots and dicots, such as rice, corn, wheat, sorghum, barley, soybeans, peanuts, Arabidopsis, and the like.
- the nucleotide sequence encoding a Cpfl protein is codon optimized for humans. In some embodiments, the codon-optimized nucleotide sequence encoding a Cpfl protein is selected from the group consisting of SEQ ID NOs: 13-24.
- the nucleotide sequence encoding the Cpfl protein and/or the nucleotide sequence encoding the guide RNA is operably linked to an expression control element such as a promoter.
- promoters examples include, but are not limited to, the polymerase (pol) I, pol II or pol III promoters.
- pol I promoters include the chicken RNApol I promoter.
- pol II promoters include, but are not limited to, the cytomegalovirus immediate early (CMV) promoter, the Rous sarcoma virus long terminal repeat (RSV-LTR) promoter, and the simian virus 40 (SV40) immediate early promoter.
- pol III promoters include the U6 and H1 promoters.
- An inducible promoter such as a metallothionein promoter can be used.
- promoters include the T7 phage promoter, the T3 phage promoter, the beta-galactosidase promoter, and the Sp6 phage promoter.
- the promoter may be the cauliflower mosaic virus 35S promoter, the maize Ubi-1 promoter, the wheat U6 promoter, the rice U3 promoter, the maize U3 promoter, the rice actin promoter.
- the invention provides a crRNA comprising a crRNA backbone sequence corresponding to any one of SEQ ID NOs: 25-33.
- the coding sequence of the crRNA comprises the crRNA backbone sequence set forth in any one of SEQ ID NOs: 25-33.
- the crRNA backbone sequence is SEQ ID NO:30.
- the coding sequence of the cRNA further comprises a sequence (i.e., a spacer sequence) located 3' to which the complementary sequence of the target sequence specifically hybridizes to the cRNA backbone sequence.
- the crRNA is encoded by a nucleotide sequence selected from the group consisting of:
- the sequence N x (spacer sequence) is capable of specifically hybridizing to the complement of the target sequence.
- the crRNAs of the invention are particularly suitable for use in combination with the Cpfl protein of the invention for genome editing, particularly for genome editing in eukaryotes such as mammals.
- the invention provides a method of modifying a target sequence in a cellular genome, comprising introducing a genome editing system of the invention into the cell, whereby the guide RNA targets the Cpfl protein to the cellular genome
- the target sequence in the sequence results in the substitution, deletion and/or addition of one or more nucleotides in the target sequence.
- the invention also provides a method of producing a genetically modified cell comprising introducing a genome editing system of the invention into a cell, whereby the guide RNA targets the Cpfl protein to the cellular genome
- the target sequence results in the substitution, deletion and/or addition of one or more nucleotides in the target sequence.
- the invention also provides a genetically modified organism comprising genetically modified cells produced by the methods of the invention or a progeny cell thereof.
- target sequences or crRNA coding sequences that can be recognized and targeted by the Cpf1 protein and the guide RNA (i.e., crRNA) complex can be found, for example, in Zhang et al., Cell 163, 1-13, October 22, 2015.
- the 5' end of the target sequence targeted by the genome editing system of the present invention needs to include a protospacer adjacent motif (PAM) 5'-TTTN, 5'-TTN, 5'-CCN. , 5'-TCCN, 5'-TCN or 5'-CTN, where N represents A, G, C or T.
- PAM protospacer adjacent motif
- the target sequence has the structure: 5'-TYYN-N x -3' or 5'-YYN-Nx-3', wherein N is independently selected from A, G, C and T, Y are selected from C and T; X is an integer of 15 ⁇ X ⁇ 35; Nx represents X contiguous nucleotides.
- the coding sequence of the crRNA comprises the crRNA backbone sequence set forth in any one of SEQ ID NOs: 25-33. In some preferred embodiments, the crRNA backbone sequence is SEQ ID NO:30. In some embodiments, the coding sequence of the cRNA further comprises a sequence (i.e., a spacer sequence) located 3' to which the complementary sequence of the target sequence specifically hybridizes to the cRNA backbone sequence.
- the crRNA is encoded by a nucleotide sequence selected from the group consisting of:
- the sequence N x (spacer sequence) is capable of specifically hybridizing to the complement of the target sequence.
- the target sequence to be modified may be located at any position in the genome, for example, in a functional gene such as a protein-encoding gene, or may be, for example, located in a gene expression regulatory region such as a promoter region or an enhancer region, thereby Gene functional modification or modification of gene expression.
- Substitutions, deletions, and/or additions in the target sequences of the cells can be detected by T7EI, PCR/RE or sequencing methods.
- the genome editing system can be introduced into cells by a variety of methods well known to those skilled in the art.
- Methods that can be used to introduce a genome editing system of the invention into a cell include, but are not limited to, calcium phosphate transfection, protoplast fusion, electroporation, lipofection, microinjection, viral infection (eg, baculovirus, vaccinia virus, gland) Virus, adeno-associated virus, lentivirus and other viruses), gene gun method, PEG-mediated protoplast transformation, Agrobacterium-mediated transformation of soil.
- Cells that can be genome edited by the methods of the invention can be derived, for example, from mammals such as humans, mice, rats, monkeys, dogs, pigs, sheep, cattle, cats; poultry such as chickens, ducks, geese; plants, including lists Leaf plants and dicots, such as rice, corn, wheat, sorghum, barley, soybeans, peanuts, Arabidopsis, and the like.
- the methods of the invention are performed in vitro.
- the cell is an isolated cell.
- the cell is a CAR-T cell.
- the cell is an induced embryonic stem cell.
- the methods of the invention may also be performed in vivo.
- the cell is a cell in a living body, and the system of the present invention can be introduced into the cell in vivo by, for example, a virus-mediated method.
- the cell can be a tumor cell in a patient.
- the invention also encompasses the use of the genome editing system of the invention in the treatment of diseases.
- the target sequence in the present invention may be located in a protein coding region of a disease-related gene, or may be, for example, located in a gene expression regulatory region such as a promoter region or an enhancer region, thereby enabling functional modification of the disease-related gene or disease-related Modification of gene expression.
- a “disease-associated” gene refers to any gene that produces a transcriptional or translational product at an abnormal level or in an abnormal form in a cell derived from a disease-affected tissue as compared to a non-disease-controlled tissue or cell. Where altered expression is associated with the appearance and/or progression of a disease, it may be a gene that is expressed at an abnormally high level; it may be a gene that is expressed at an abnormally low level.
- a disease-associated gene also refers to a gene having one or more mutations or a genetic variation that is directly responsible for or incompatible with one or more genes responsible for the etiology of the disease. The transcribed or translated product may be known or unknown and may be at normal or abnormal levels.
- the invention also provides a method of treating a disease in a subject in need thereof, comprising delivering to the subject an effective amount of a genome editing system of the invention to modify a gene associated with the disease.
- the invention also provides the use of a genome editing system of the invention for the preparation of a pharmaceutical composition for treating a disease in a subject in need thereof, wherein the genome editing system is for modifying a gene associated with the disease.
- the invention also provides a pharmaceutical composition for treating a disease in a subject in need thereof, comprising a genome editing system of the invention and a pharmaceutically acceptable carrier, wherein the genome editing system is for modifying a gene associated with the disease .
- the subject is a mammal, such as a human.
- diseases include, but are not limited to, tumors, inflammation, Parkinson's disease, cardiovascular disease, Alzheimer's disease, autism, drug addiction, age-related macular degeneration, schizophrenia, hereditary diseases, and the like.
- kits for use in the methods of the invention comprising the genome editing system of the invention, and instructions for use.
- the kit generally includes a label indicating the intended use and/or method of use of the contents of the kit.
- the term label includes any written or recorded material provided on or with the kit or otherwise provided with the kit.
- HEK293T HeLa cells were cultured in DMEM medium (Gibco) supplemented with 10% FBS (Gibco) and 100 U/ml penicillin and 100 ug/ml streptomycin, and mouse EpiSC cells were cultured in N2B27 medium supplemented with bFGF.
- the plasmid was transferred into the cells, and replaced with serum-free opti-MEM medium (Gibco) before transfection. After transfection, it was replaced with serum-added DMED medium at 8-12 h after transfection. After transfection for 48 h, the flow was divided. GFP positive cells were selected for genotyping.
- GFP-positive cells were sorted by flow, lysed with Buffer L+1/100V Protease K (Biotool) at 55 ° C for 30 min, inactivated at 95 ° C for 5 min, and directly used for PCR detection.
- the heterodimer is formed by re-annealing according to the previously reported method (Li, w., et al., Simultaneous generation and germline transmission of multiple gene mutations in rat using CRISPR-Cas systems. Nat Biotechnol, 2013.31(8) :p.684-6).
- the reannealed product was added with 0.3 uL of T7EI endnucelease and 1/10 V NEBuffer 2 (NEB), and digested at 37 ° C for 1 h 30 min.
- Genotypic analysis was performed by 3% TAE-Gel electrophoresis. Indel calculates according to the method reported in the previous article (Cong, L., et al., Multiplex genome engineering using CRISPR/Cas systems. Science, 2013. 339 (6121): p. 819-23).
- the PCR product corresponding to the T7EI positive sample was ligated to the pEASY-T1 or pEASY-B (Transgen) vector. Transformation, plating, and incubation at 37 ° C overnight. Pick the right amount of monoclonal colonies for Sanger sequencing. Mutant genotypes were determined by alignment with wild-type genotypes.
- the Cpf1 eukaryotic expression vector was transfected into HeLa cells for 48 hours and then fixed with 4% PFA for 10 min at room temperature. Wash three times with PBST (PBS + 0.3% Triton X100). 2% BSA (+0.3% Triton X100) was incubated for 15 min at room temperature, incubated with primary anti-Rat anti-HA (Roche, 1:1000) overnight, and washed three times with PBST. The Cy3-labeled fluorescent secondary antibody (Jackson ImmunoResearch, 1:1000) was incubated for 2 h at room temperature, DAPI (Sigma, 1:1000) for 10 min, and washed three times with PBST. Mount with Aqueous Mounting Medium (Abeam) and fix. Zeiss LSM780 is used for observation.
- the Cpf1 encoding gene was cloned into the prokaryotic expression vector of BPK2103/2104.
- the fused C-terminal 10xHis tag was used to purify the protein.
- the expression vector was transformed into BL21(DE3) E. coli competent cells (Transgen). Clones in which IPTG induced high expression were selected and inoculated into 300 mL of CmR+LB medium. Incubate at 37 °C to OD600 ⁇ 0.4, add IPTG at a final concentration of 1 mM, and induce expression at 16 ° C for 16 h.
- the heterologous protein without the fused His10 tag was thoroughly washed away with 20 mL of NPI-20, 20 mL of NPI-40 and 10 mL of NPI-100, respectively, using gravity flow. Finally, the His10-tagged Cpf1 protein was eluted from the Ni column with 6 x 0.5 mL of NPI-500. The eluted protein of interest was dialyzed overnight in dialysate (50 mM Tris-HCl, 300 mM KCl, 1 mM DTT, 20% Glycerol). The protein solution after dialysis was concentrated with 100 kDa Amicon Ultra-4, PLHK Ultracel-PL ultrafiltration tube (Millipore). Protein Assay Kit (Thermo Scientific TM) Protein concentration was determined using Micro BCA TM.
- the target sequences with different 5'PAM sequences were synthesized and cloned into pUC19 or p11-LacY-wtx1 vector, amplified with primers and then purified by gel. 200 ng of purified PCR product was reacted with 400 ng of crRNA and 50 nM of Cpf1 protein in a NEBuffer 3 (NEB) reaction system for 1 h at 37 ° C, respectively. This was followed by electrophoresis on a 12% Urea-TBE-PAGE gel or 2.5% agarose gel.
- NNB NEBuffer 3
- CRISPR/Cpt1 (Clustered Regularly Interspaced Short Palindromic Repeats from Prevotella and Francisella 1) is an acquired immune mechanism found in Prevotella and Francisella and successfully engineered for DNA editing technology (Zetsche, B., et al., Cpf1is a Single RNA-guided endonuclease of a class 2 CRISPR-Cas system. Cell, 2015. 163(3): p.759-71.). Unlike CRISPR/Cas9, Cpf1 requires only one crRNA to guide, no tracrRNA is required, and the Cpf1 protein uses a T base-rich PAM sequence.
- the present inventors performed PSI-Blast search in the NCBI database using AsCpf1, LbCpf1 and FnCpt1 which have been reported, and selected 25 unreported Cpf1 proteins, of which 21 Cpf1 proteins possess a direct repeat (DR) sequence.
- DR direct repeat
- the coding sequence (BGI) of 12 selected proteins was codon-optimized for expression in human, cloned into eukaryotic expression vector (pCAG-2AeGFP-SV40 and pCAG-2AeGFP-SV40_v4) and prokaryotic expression vector (BPK2103- In ccdB and BPK2014-ccdB).
- 293T cells were co-transfected with crRNA targeting human Dnmt1 gene, and identified by PCR and T7EI digestion, 8 Cpf1 proteins (Ab, Ar, Bo, Bs, Hk, Lp, Ps, Sa) were found. Mutation was initiated at position 3 of the Dnmt1 gene in 293T cells (Fig. 3A). DNA sequencing further confirmed that the gene locus did produce a genetic mutation (Fig. 3B).
- the BsCpf1 protein was selected for detailed study.
- BsCpf1 was expressed in E. coli prokaryotic and protein purified by His tag (Fig. 6A).
- the purified BsCpf1 protein and the corresponding crRNA and dsDNA fragment (human Dnmt1 target site 2) were incubated at 37 ° C for 1 h, and then subjected to TBE denaturing PAGE gel electrophoresis, which proved that the PAM sequence of BsCpf1 was 5'(T)TTN- (Fig. 6B-E).
- the PAM sequence of the remaining Cpf1 protein was identified by a similar method, and the results are shown in FIG.
- the experimental results show that the selected Cpf1 proteins have in vitro enzymatic activity.
- the PAM sequence of 9 of the Cpf1 proteins is 5'(T)TTN-.
- the PAM sequences of C6Cpf1, HkCpf1 and PsCpf1 are 5'(T)YYN-.
- HkCpf1 was transfected into 293T cells with a targeted crRNA vector at 8 sites on the human AAVS1 gene, respectively.
- the experimental results show that (Fig. 8), HkCpf1 can edit 7 of the sites and generate mutations, and the PAM sequence is 5'(T)YYN- (underlined portion of Fig. 8B).
- This example optimizes the cRNA backbone of the newly identified Cpt1 protein that can be used for mammalian genome editing to improve the genome editing efficiency of each Cpt1 protein (Table 3).
- Figure 13A shows that cells transfected each Cpt1 protein and a different crRNA plasmid, and by PCR and T7EI analysis, demonstrated that different crRNA backbones affect the effective editing efficiency of the Cpt1 protein.
- the inventors then established a library of mutants of crRNA, transfected with BsCpt1 or PrCpt1, respectively. Through PCR and T7EI analysis, a crRNA mutant capable of enabling Cpt1 to efficiently edit the mammalian genome was screened.
- crRNA31 The editing efficiency of the crRNA31 mutant was significantly higher than that of the wild-type crRNA backbone (crRNA2) derived from the strain genome.
- the cells were transfected with Cpf1 and crRNA31, crRNA2 plasmids, and by PCR and T7EI analysis, it was confirmed that crRNA31 can increase the editing efficiency of 15 Cpt1 of ArCpf1, BsCpf1, HkCpf1, PrCpf1, and PxCpt at the MeCP2-4 site by about one time (Fig. 13B).
- Figures 14A and B show that analysis of different target sites by T7EI confirms that the screened cRNA backbone can improve the editing efficiency of BsCpt1 and PrCpf1.
- PrCpt1 in addition to the crRNA31 backbone, the editing efficiency of the crRNA77, crRNA129 and crRNA159 skeletons at the Nrl-1 locus was also significantly improved.
- Figure 14C shows flow cytometry analysis of intracellular GFP editing efficiency.
- the crRNA31 backbone can improve the editing efficiency of BsCpt1 and PrCpf1, and the crRNA77 and crRNA159 backbone can also significantly improve the editing efficiency of PrCpt1.
- cRNA skeleton name crRNA backbone sequence (5'-3') SEQ ID NO crRNA1 ATTTCTACtgttGTAGAT 25 crRNA2 ATTTCTACtattGTAGAT 26 crRNA3 ATTTCTACtactGTAGAT 27 crRNA4 ATTTCTACtttgGTAGAT 28 crRNA5 ATTTCTACtagttGTAGAT 29 crRNA31 ATTTCTACTATGGTAGAT 30 crRNA77 ATTTCTACTGTCGTAGAT 31 crRNA129 ATTTCTACTTGTGTAGAT 32 crRNA159 ATTTCTACTGTGGTAGAT 33
Landscapes
- Health & Medical Sciences (AREA)
- Life Sciences & Earth Sciences (AREA)
- Engineering & Computer Science (AREA)
- Genetics & Genomics (AREA)
- Chemical & Material Sciences (AREA)
- Bioinformatics & Cheminformatics (AREA)
- Organic Chemistry (AREA)
- Biomedical Technology (AREA)
- General Health & Medical Sciences (AREA)
- Wood Science & Technology (AREA)
- Zoology (AREA)
- Biotechnology (AREA)
- Molecular Biology (AREA)
- General Engineering & Computer Science (AREA)
- Medicinal Chemistry (AREA)
- Pharmacology & Pharmacy (AREA)
- Veterinary Medicine (AREA)
- Public Health (AREA)
- Animal Behavior & Ethology (AREA)
- Nuclear Medicine, Radiotherapy & Molecular Imaging (AREA)
- General Chemical & Material Sciences (AREA)
- Chemical Kinetics & Catalysis (AREA)
- Microbiology (AREA)
- Biochemistry (AREA)
- Plant Pathology (AREA)
- Biophysics (AREA)
- Physics & Mathematics (AREA)
- Neurosurgery (AREA)
- Neurology (AREA)
- Psychiatry (AREA)
- Mycology (AREA)
- Epidemiology (AREA)
- Ophthalmology & Optometry (AREA)
- Cardiology (AREA)
- Psychology (AREA)
- Crystallography & Structural Chemistry (AREA)
- Hospice & Palliative Care (AREA)
- Addiction (AREA)
- Heart & Thoracic Surgery (AREA)
- Pain & Pain Management (AREA)
Abstract
一种真核生物基因组编辑系统和方法,能够对真核动物细胞基因组进行高效编辑的CRISPR-Cpf1系统及其用途。
Description
本发明涉及基因工程领域。具体而言,本发明涉及新的真核生物基因组编辑系统和方法。更具体而言,本发明涉及能够对真核生物细胞基因组进行高效编辑的CRISPR-Cpf1系统及其用途。
CRISPR(Clustered regularly interspaced short palindromic repeats,成簇的规律间隔的短回文重复序列)系统是在进化过程中产生的细菌用于防御外来基因入侵的免疫系统。其中,II型CRISPR-Cas9系统是通过两个小RNA(crRNA和tracrRNA)或者一个人工合成小RNA(sgRNA)介导一个Cas9蛋白进行DNA切割的系统,也是最早发现的三种(I、II、III型)CRISPR系统中最简单的系统。由于该系统简单易操作,在2013年被改造并成功实现了真核生物基因组的编辑。CRISPR/Cas9系统迅速成为了生命科学领域最热门的技术。
2015年,Zhang et al.通过序列比对和系统分析的方法又发现了区别于CRISPR-Cas9系统之外的新的基因编辑系统,即CRISPR-Cpf1系统。该系统只需要一个小RNA(crRNA)的介导即可实现基因组的编辑。自然界中存在着成千上万种的CRISPR系统,但是,能够成功实现真核生物基因组编辑的CRISPR系统并不多。
本领域仍然需要能够实现高效真核生物基因组编辑的CRISPR-Cpf1系统。
发明简述
在一方面,本发明提供了一种用于对细胞基因组中的靶序列进行定点修饰的基因组编辑系统,其包含以下i)至v)中至少一项:
i)Cpf1蛋白,和向导RNA(crRNA);
ii)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和向导RNA;
iii)Cpf1蛋白,和包含编码向导RNA的核苷酸序列的表达构建体;
iv)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和包含编码向导RNA的核苷酸序列的表达构建体;
v)包含编码Cpf1蛋白的核苷酸序列和编码向导RNA的核苷酸序列的表达构建体;
其中所述Cpf1蛋白包含SEQ ID No:1-12之一的氨基酸序列或与SEQ ID No:1-12之一具有至少80%序列相同性的氨基酸序列,所述向导RNA能够将所述Cpf1蛋白靶向所述细胞基因组中的靶序列。
在第二方面,本发明提供了一种对细胞基因组中的靶序列进行定点修饰的方法,包括将本发明的基因组编辑系统导入所述细胞,由此所述向导RNA将所述Cpf1蛋白靶向所述细胞基因组中的靶序列,导致所述靶序列中的一或多个核苷酸的取代、缺失和/或添 加。
在第三方面,本发明提供了一种治疗有需要的对象中的疾病的方法,包括向所述对象递送有效量的本发明的基因组编辑系统以修饰所述对象中与所述疾病相关的基因。
在第四方面,本发明提供了本发明的基因组编辑系统在制备用于治疗有需要的对象中的疾病的药物组合物中的用途,其中所述基因组编辑系统用于修饰所述对象中与所述疾病相关的基因。
在第五方面,本发明提供了一种用于治疗有需要的对象中的疾病的药物组合物,其包含本发明的基因组编辑系统和药学可接受的载体,其中所述基因组编辑系统用于修饰所述对象中与所述疾病相关的基因。
在第六方面,本发明提供了一种crRNA,其包含对应于SEQ ID NO:25-33任一的crRNA骨架序列或其编码序列包含SEQ ID NO:25-33任一所示的序列。
附图描述
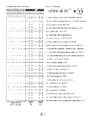
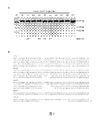
图1.来自25种新的Cpf1家族蛋白的直接重复序列(DR)的比对。其中具有DR序列的21种成熟crRNA的茎重复(stem duplex)极度保守。
图2.免疫荧光显示Cpf1蛋白定位于细胞核。
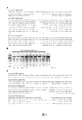
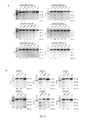
图3.示出Cpf1蛋白对人Dnmt1位点3的编辑能力。A:T7EI测定显示9种选定的Cpf1蛋白中的8种能够在293T细胞中对人Dnmt1位点3实现插入/缺失(indel);B:测序显示人Dnmt1位点3中的代表性indel。
图4.示出Cpf1蛋白对人Dnmt1位点1的编辑能力。A:T7EI测定显示4种Cpf1蛋白明显靶向人Dnmt1位点1。B:测序结果显示人Dnmt1位点1中的代表性indel,其中6种Cpf1蛋白能够产生indel,尽管PsCpf1和SaCpf1在酶切测定中无明显条带。
图5.示出Cpf1蛋白对人Dnmt1位点2的编辑能力。A:T7EI测定显示4种Cpf1蛋白明显靶向人Dnmt1位点2。B.:测序结果显示人Dnmt1位点2中的代表性indel,其中5种Cpf1能够产生indel,尽管PsCpf1在酶切测定中无明显条带。
图6.体外测定BsCpf1的PAM序列。A:BsCpf1蛋白的大肠杆菌表达和纯化。B-E:BsCpf1的靶向采用5’-TTN PAM。
图7.体外测定各Cpf1的PAM序列。“+”表示有体外酶切活性。
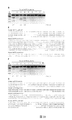
图8.示出HkCpf1对人AAVS1基因8个位点的编辑能力。A:T7EI测定结果。B:测序结果显示HkCpf1能够在7个位点产生突变,且PAM序列是5’-YYN,与图7结果吻合。
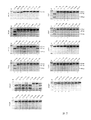
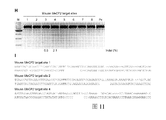
图9、图10和图11示出4种Cpf1蛋白在EpiSC细胞中编辑小鼠基因组。
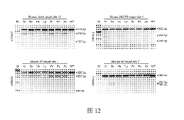
图12.进一步验证ArCpf1、BsCpf1、HkCpf1、LpCpf1、PrCpf1和PxCpf1对小鼠不同靶点的编辑能力。
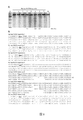
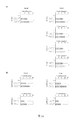
图13-图14示出对crRNA骨架序列的优化。
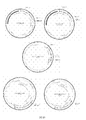
图15.示出所使用的各种载体图谱。
发明详述
一、定义
在本发明中,除非另有说明,否则本文中使用的科学和技术名词具有本领域技术人员所通常理解的含义。并且,本文中所用的蛋白质和核酸化学、分子生物学、细胞和组织培养、微生物学、免疫学相关术语和实验室操作步骤均为相应领域内广泛使用的术语和常规步骤。例如,本发明中使用的标准重组DNA和分子克隆技术为本领域技术人员熟知,并且在如下文献中有更全面的描述:Sambrook,J.,Fritsch,E.F.和Maniatis,T.,Molecular Cloning:A Laboratory Manual;Cold Spring Harbor Laboratory Press:Cold Spring Harbor,1989(下文称为“Sambrook”)。同时,为了更好地理解本发明,下面提供相关术语的定义和解释。
“Cpf1核酸酶”、“Cpf1蛋白”和“Cpf1”在本文中可互换使用,指的是包括Cpf1蛋白或其片段的RNA指导的核酸酶。Cpf1是CRISPR-Cpf1基因组编辑系统的组分,能在向导RNA(crRNA)的指导下靶向并切割DNA靶序列形成DNA双链断裂(DSB)。DSB能够激活细胞内固有的修复机制非同源末端连接(Non-homologous end joining,NHEJ)和同源重组(Homologous recombination,HR)对细胞中的DNA损伤进行修复,在修复过程中,对该特定的DNA序列进行定点编辑。
“向导RNA”和“gRNA”在本文中可互换使用。CRISPR-Cpf1基因组编辑系统的向导RNA通常仅由crRNA分子构成,其中crRNA包含与靶序列具有足够相同性以便与靶序列的互补序列杂交并且指导CRISPR复合物(Cpf1+crRNA)与该靶序列序列特异性结合的序列。
“基因组”如本文所用不仅涵盖存在于细胞核中的染色体DNA,而且还包括存在于细胞的亚细胞组分(如线粒体、质体)中的细胞器DNA。
如本文所用,“生物体”包括适于基因组编辑的任何生物体,优选真核生物。生物体的实例包括但不限于,哺乳动物如人、小鼠、大鼠、猴、犬、猪、羊、牛、猫;家禽如鸡、鸭、鹅;植物包括单子叶植物和双子叶植物,例如水稻、玉米、小麦、高粱、大麦、大豆、花生、拟南芥等。
“经遗传修饰的生物体”或“经遗传修饰的细胞”意指在其基因组内包含外源多核苷酸或修饰的基因或表达调控序列的生物体或细胞。例如外源多核苷酸能够稳定地整合进生物体或细胞的基因组中,并遗传连续的世代。外源多核苷酸可单独地或作为重组DNA构建体的部分整合进基因组中。修饰的基因或表达调控序列为在生物体或细胞基因组中所述序列包含单个或多个脱氧核苷酸取代、缺失和添加。
针对序列而言的“外源”意指来自外来物种的序列,或者如果来自相同物种,则指通过蓄意的人为干预而从其天然形式发生了组成和/或基因座的显著改变的序列。
“多核苷酸”、“核酸序列”、“核苷酸序列”或“核酸片段”可互换使用并且是单链或双链RNA或DNA聚合物,任选地可含有合成的、非天然的或改变的核苷酸碱基。核苷酸通过如下它们的单个字母名称来指代:“A”为腺苷或脱氧腺苷(分别对应RNA或 DNA),“C”表示胞苷或脱氧胞苷,“G”表示鸟苷或脱氧鸟苷,“U”表示尿苷,“T”表示脱氧胸苷,“R”表示嘌呤(A或G),“Y”表示嘧啶(C或T),“K”表示G或T,“H”表示A或C或T,“I”表示肌苷,并且“N”表示任何核苷酸。
“多肽”、“肽”、和“蛋白质”在本发明中可互换使用,指氨基酸残基的聚合物。该术语适用于其中一个或多个氨基酸残基是相应的天然存在的氨基酸的人工化学类似物的氨基酸聚合物,以及适用于天然存在的氨基酸聚合物。术语“多肽”、“肽”、“氨基酸序列”和“蛋白质”还可包括修饰形式,包括但不限于糖基化、脂质连接、硫酸盐化、谷氨酸残基的γ羧化、羟化和ADP-核糖基化。
序列“相同性”具有本领域公认的含义,并且可以利用公开的技术计算两个核酸或多肽分子或区域之间序列相同性的百分比。可以沿着多核苷酸或多肽的全长或者沿着该分子的区域测量序列相同性。(参见,例如:Computational Molecular Biology,Lesk,A.M.,ed.,Oxford University Press,New York,1988;Biocomputing:Informatics and Genome Projects,Smith,D.w.,ed.,Academic Press,New York,1993;Computer Analysis of Sequence Data,Part I,Griffin,A.M.,and Griffin,H.G.,eds.,Humana Press,New Jersey,1994;Sequence Analysis in Molecular Biology,von Heinje,G.,Academic Press,1987;and Sequence Analysis Primer,Gribskov,M.and Devereux,J.,eds.,M Stockton Press,New York,1991)。虽然存在许多测量两个多核苷酸或多肽之间的相同性的方法,但是术语“相同性”是技术人员公知的(Carrillo,H.&Lipman,D.,SIAM J Applied Math 48:1073(1988))。
在肽或蛋白中,合适的保守型氨基酸取代是本领域技术人员已知的,并且一股可以进行而不改变所得分子的生物活性。通常,本领域技术人员认识到多肽的非必需区中的单个氨基酸取代基本上不改变生物活性(参见,例如,Watson et al.,Molecular Biology of the Gene,4th Edition,1987,The Benjamin/Cummings Pub.co.,p.224)。
如本发明所用,“表达构建体”是指适于感兴趣的核苷酸序列在生物体中表达的载体如重组载体。“表达”指功能产物的产生。例如,核苷酸序列的表达可指核苷酸序列的转录(如转录生成mRNA或功能RNA)和/或RNA翻译成前体或成熟蛋白质。
本发明的“表达构建体”可以是线性的核酸片段、环状质粒、病毒载体,或者,在一些实施方式中,可以是能够翻译的RNA(如mRNA)。
本发明的“表达构建体”可包含不同来源的调控序列和感兴趣的核苷酸序列,或相同来源但以不同于通常天然存在的方式排列的调控序列和感兴趣的核苷酸序列。
“调控序列”和“调控元件”可互换使用,指位于编码序列的上游(5′非编码序列)、中间或下游(3′非编码序列),并且影响相关编码序列的转录、RNA加工或稳定性或者翻译的核苷酸序列。调控序列可包括但不限于启动子、翻译前导序列、内含子和多腺苷酸化识别序列。
“启动子”指能够控制另一核酸片段转录的核酸片段。在本发明的一些实施方案中,启动子是能够控制细胞中基因转录的启动子,无论其是否来源于所述细胞。启动子可以是组成型启动子或组织特异性启动子或发育调控启动子或诱导型启动子。
“组成型启动子”指一股将引起基因在多数细胞类型中在多数情况下表达的启动子。“组织特异性启动子”和“组织优选启动子”可互换使用,并且指主要但非必须专一地在一种组织或器官中表达,而且也可在一种特定细胞或细胞型中表达的启动子。“发育调控启动子”指其活性由发育事件决定的启动子。“诱导型启动子”响应内源性或外源性刺激(环境、激素、化学信号等)而选择性表达可操纵连接的DNA序列。
如本文中所用,术语“可操作地连接”指调控元件(例如但不限于,启动子序列、转录终止序列等)与核酸序列(例如,编码序列或开放读码框)连接,使得核苷酸序列的转录被所述转录调控元件控制和调节。用于将调控元件区域可操作地连接于核酸分子的技术为本领域已知的。
将核酸分子(例如质粒、线性核酸片段、RNA等)或蛋白质“导入”生物体是指用所述核酸或蛋白质转化生物体细胞,使得所述核酸或蛋白质在细胞中能够发挥功能。本发明所用的“转化”包括稳定转化和瞬时转化。
“稳定转化”指将外源核苷酸序列导入基因组中,导致外源基因稳定遗传。一旦稳定转化,外源核酸序列稳定地整合进所述生物体和其任何连续世代的基因组中。
“瞬时转化”指将核酸分子或蛋白质导入细胞中,执行功能而没有外源基因稳定遗传。瞬时转化中,外源核酸序列不整合进基因组中。
二、高效基因组编辑系统
在一方面,本发明提供包含与SEQ ID NO:1-12之一具有至少80%、至少85%、至少90%、至少95%、至少96%、至少97%、至少98%、至少99%、甚至100%序列相同性的氨基酸序列的Cpf1蛋白在真核细胞基因组编辑中的用途。
在另一方面,本发明提供了一种用于对细胞基因组中的靶序列进行定点修饰的基因组编辑系统,其包含以下i)至v)中至少一项:
i)Cpf1蛋白,和向导RNA;
ii)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和向导RNA;
iii)Cpf1蛋白,和包含编码向导RNA的核苷酸序列的表达构建体;
iv)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和包含编码向导RNA的核苷酸序列的表达构建体;
v)包含编码Cpf1蛋白的核苷酸序列和编码向导RNA的核苷酸序列的表达构建体;
其中所述Cpf1蛋白包含SEQ ID NO:1-12的氨基酸序列或与SEQ ID NO:1-12之一具有至少80%序列相同性的氨基酸序列,所述向导RNA能够将所述Cpf1蛋白靶向所述细胞基因组中的靶序列。
在本发明的方法的一些实施方式中,所述向导RNA是crRNA。在一些实施方式中,所述crRNA的编码序列包含SEQ ID NO:25-33任一所示的crRNA骨架序列。在一些优选实施方式中,所述crRNA骨架序列为SEQ ID NO:30。在一些实施方式中,所述cRNA的编码序列还包括位于所述cRNA骨架序列的3’的与靶序列的互补序列特异性杂交的序 列(即spacer序列)。
在一些实施方案中,所述crRNA由选自以下的核苷酸序列编码:
i)5’-ATTTCTACtgttGTAGAT(SEQ ID NO:25)-N
x-3’;
ii)5’-ATTTCTACtattGTAGAT(SEQ ID NO:26)-N
x-3’;
iii)5’-ATTTCTACtactGTAGAT(SEQ ID NO:27)-N
x-3’;
iv)5’-ATTTCTACtttgGTAGAT(SEQ ID NO:28)-N
x-3’;
v)5’-ATTTCTACtagttGTAGAT(SEQ ID NO:29)-N
x-3’;
vi)5’-ATTTCTACTATGGTAGAT(SEQ ID NO:30)-N
x-3’;
vii)5’-ATTTCTACTGTCGTAGAT(SEQ ID NO:31)-N
x-3’;
viii)5’-ATTTCTACTTGTGTAGAT(SEQ ID NO:32)-N
x-3’;和
ix)5’-ATTTCTACTGTGGTAGAT(SEQ ID NO:33)-N
x-3’,
其中N
x表示X个连续的核苷酸组成的核苷酸序列,N各自独立地选自A、G、C和T;X为18≤X≤35的整数,优选地,X=23。在一些实施方案中,序列N
x(spacer序列)能够与靶序列的互补序列特异性杂交。
在本发明的方法的一些实施方式中,所述细胞是真核生物细胞,优选哺乳动物细胞。
在本发明的方法的一些实施方式中,所述Cpf1蛋白包含与SEQ ID NO:1-12之一具有至少80%、至少85%、至少90%、至少95%、至少96%、至少97%、至少98%、至少99%、甚至100%序列相同性的氨基酸序列。所述Cpf1蛋白能够通过crRNA靶向和/或切割所述细胞基因组中的靶序列。
在本发明的方法的一些实施方式中,所述Cpf1蛋白包含相对于SEQ ID NO:1-12之一具有一或多个氨基酸残基取代、缺失或添加的氨基酸序列。例如,所述Cpf1蛋白包含相对于SEQ ID NO:1-12之一具有1个、2个、3个、4个、5个、6个、7个、8个、9个、10个氨基酸残基取代、缺失或添加的氨基酸序列。在一些实施方案中,所述氨基酸取代是保守型取代。所述Cpf1蛋白能够通过crRNA靶向和/或切割所述细胞基因组中的靶序列。
本发明的Cpf1蛋白可以来自选自以下的物种:Agathobacter rectalis、Lachnospira pectinoschiza、Sneathia amnii、Helcococcus kunzii、Arcobacter butzleri、Bacteroidetes oral、Oribacterium sp.、Butyrivibrio sp.、Proteocatella sphenisci、Candidatus Dojkabacteria、Pseudobutyrivibrio xylanivorans、Pseudobutyrivibrio ruminis。
在本发明的一些优选实施方案中,所述Cpf1蛋白来自Agathobacter rectalis(ArCpf1)、Butyrivibrio sp.(BsCpf1)、Helcococcus kunzii(HkCpf1)、Lachnospira pectinoschiza(LpCpf1)、Pseudobutyrivibrio ruminis(PrCpf1)或Pseudobutyrivibrio xylanivorans(PxCpf1)。在本发明的一些优选实施方案中,所述Cpf1蛋白包含选自SEQ ID NO:1、SEQ ID NO:2、SEQ ID NO:4、SEQ ID NO:8、SEQ ID NO:11、SEQ ID NO:12的氨基酸序列。
在本发明的一些实施方案中,本发明的Cpf1蛋白还包含核定位序列(NLS)。一股而 言,所述Cpf1蛋白中的一个或多个NLS应具有足够的强度,以便在细胞核中驱动所述Cpf1蛋白以可实现其基因编辑功能的量积聚。一股而言,核定位活性的强度由所述Cpf1蛋白中NLS的数目、位置、所使用的一个或多个特定的NLS、或这些因素的组合决定。
在本发明的一些实施方案中,本发明的Cpf1蛋白的NLS可以位于N端和/或C端。在一些实施方案中,所述Cpf1蛋白包含约1、2、3、4、5、6、7、8、9、10个或更多个NLS。在一些实施方案中,所述Cpf1蛋白包含在或接近于N端的约1、2、3、4、5、6、7、8、9、10个或更多个NLS。在一些实施方案中,所述Cpf1蛋白包含在或接近于C端约1、2、3、4、5、6、7、8、9、10个或更多个NLS。在一些实施方案中,所述Cpf1蛋白包含这些的组合,如包含在N端的一个或多个NLS以及在C端的一个或多个NLS。当存在多于一个NLS时,每一个可以被选择为不依赖于其他NLS。在本发明的一些实施方式中,所述Cpf1蛋白包含2个NLS,例如所述2个NLS分别位于N端和C端。
一股而言,NLS由暴露于蛋白表面上的带正电的赖氨酸或精氨酸的一个或多个短序列组成,但其他类型的NLS也是已知的。NLS的非限制性实例包括:KKRKV(核苷酸序列5’-AAGAAGAGAAAGGTC-3’)、PKKKRKV(核苷酸序列5’-CCCAAGAAGAAGAGGAAGGTG-3’或CCAAAGAAGAAGAGGAAGGTT),或SGGSPKKKRKV(核苷酸序列5’-TCGGGGGGGAGCCCAAAGAAGAAGCGGAAGGTG-3’)。
此外,根据所需要编辑的DNA位置,本发明的Cpf1蛋白还可以包括其他的定位序列,例如细胞质定位序列、叶绿体定位序列、线粒体定位序列等。
为了在靶细胞中获得有效表达,在本发明的一些实施方式中,所述编码Cpf1蛋白的核苷酸序列针对待进行基因组编辑的细胞所来自的生物体进行密码子优化。
密码子优化是指通过用在宿主细胞的基因中更频繁地或者最频繁地使用的密码子代替天然序列的至少一个密码子(例如约或多于约1、2、3、4、5、10、15、20、25、50个或更多个密码子同时维持该天然氨基酸序列而修饰核酸序列以便增强在感兴趣宿主细胞中的表达的方法。不同的物种对于特定氨基酸的某些密码子展示出特定的偏好。密码子偏好性(在生物之间的密码子使用的差异)经常与信使RNA(mRNA)的翻译效率相关,而该翻译效率则被认为依赖于被翻译的密码子的性质和特定的转运RNA(tRNA)分子的可用性。细胞内选定的tRNA的优势一股反映了最频繁用于肽合成的密码子。因此,可以将基因定制为基于密码子优化在给定生物中的最佳基因表达。密码子利用率表可以容易地获得,例如在
www.kazusa.orjp/codon/上可获得的密码子使用数据库(“Codon Usage Database”)中,并且这些表可以通过不同的方式调整适用。参见,Nakamura Y.等,“Codon usage tabulated from the international DNA sequence databases:status for the year2000.Nucl.Acids Res.,28:292(2000)。
可通过本发明的系统进行基因组编辑的细胞所来自的生物体优选是真核生物,包括但不限于,哺乳动物如人、小鼠、大鼠、猴、犬、猪、羊、牛、猫;家禽如鸡、鸭、鹅; 植物包括单子叶植物和双子叶植物,例如水稻、玉米、小麦、高粱、大麦、大豆、花生、拟南芥等。
在本发明的一些具体实施方式中,所述编码Cpf1蛋白的核苷酸序列针对人进行密码子优化。在一些具体实施方式中,所述密码子优化的编码Cpf1蛋白的核苷酸序列选自SEQ ID NO:13-24。
在本发明一些实施方式中,所述编码Cpf1蛋白的核苷酸序列和/或所述编码向导RNA的核苷酸序列与表达调控元件如启动子可操作地连接。
本发明可使用的启动子的实例包括但不限于聚合酶(pol)I、pol II或pol III启动子。pol I启动子的实例包括鸡RNApol I启动子。pol II启动子的实例包括但不限于巨细胞病毒立即早期(CMV)启动子、劳斯肉瘤病毒长末端重复(RSV-LTR)启动子和猿猴病毒40(SV40)立即早期启动子。pol III启动子的实例包括U6和H1启动子。可以使用诱导型启动子如金属硫蛋白启动子。启动子的其他实例包括T7噬菌体启动子、T3噬菌体启动子、β-半乳糖苷酶启动子和Sp6噬菌体启动子。当用于植物时,启动子可以是花椰菜花叶病毒35S启动子、玉米Ubi-1启动子、小麦U6启动子、水稻U3启动子、玉米U3启动子、水稻肌动蛋白启动子。
在另一方面,本发明还提供一种crRNA,其包含对应于SEQ ID NO:25-33任一的crRNA骨架序列。在一些实施方式中,所述crRNA的编码序列包含SEQ ID NO:25-33任一所示的crRNA骨架序列。在一些优选实施方式中,所述crRNA骨架序列为SEQ ID NO:30。在一些实施方式中,所述cRNA的编码序列还包括位于所述cRNA骨架序列的3’的与靶序列的互补序列特异性杂交的序列(即spacer序列)。
在一些实施方案中,所述crRNA由选自以下的核苷酸序列编码:
i)5’-ATTTCTACtgttGTAGAT(SEQ ID NO:25)-N
x-3’;
ii)5’-ATTTCTACtattGTAGAT(SEQ ID NO:26)-N
x-3’;
iii)5’-ATTTCTACtactGTAGAT(SEQ ID NO:27)-N
x-3’;
iv)5’-ATTTCTACtttgGTAGAT(SEQ ID NO:28)-N
x-3’;
v)5’-ATTTCTACtagttGTAGAT(SEQ ID NO:29)-N
x-3’;
vi)5’-ATTTCTACTATGGTAGAT(SEQ ID NO:30)-N
x-3’;
vii)5’-ATTTCTACTGTCGTAGAT(SEQ ID NO:31)-N
x-3’;
viii)5’-ATTTCTACTTGTGTAGAT(SEQ ID NO:32)-N
x-3’;和
ix)5’-ATTTCTACTGTGGTAGAT(SEQ ID NO:33)-N
x-3’,
其中N
x表示X个连续的核苷酸组成的核苷酸序列,N各自独立地选自A、G、C和T;X为18≤X≤35的整数,优选地,X=23。在一些实施方案中,序列N
x(spacer序列)能够与靶序列的互补序列特异性杂交。
在一些实施方式中,本发明的crRNA特别适合于与本发明的Cpf1蛋白组合用于基因组编辑,特别是真核生物如哺乳动物的基因组编辑。
三、修饰细胞基因组中靶序列的方法
在另一方面,本发明提供了一种修饰细胞基因组中靶序列的方法,包括将本发明的基因组编辑系统导入所述细胞,由此所述向导RNA将所述Cpf1蛋白靶向所述细胞基因组中的靶序列,导致所述靶序列中的一或多个核苷酸的取代、缺失和/或添加。
在另一方面,本发明还提供一种产生经遗传修饰的细胞的方法,包括将本发明的基因组编辑系统导入细胞中,由此所述向导RNA将所述Cpf1蛋白靶向所述细胞基因组中的靶序列,导致所述靶序列中的一或多个核苷酸取代、缺失和/或添加。
在另一方面,本发明还提供经遗传修饰的生物体,其包含通过本发明的方法产生的经遗传修饰的细胞或其后代细胞。
可以被Cpf1蛋白和向导RNA(即crRNA)复合物识别并靶向的靶序列或crRNA编码序列的设计可以参照例如Zhang et al.,Cell 163,1-13,October 22,2015。一股而言,本发明的基因组编辑系统靶向的靶序列5’末端需包含前间区序列邻近基序(protospacer adjacent motif)(PAM)5’-TTTN、5’-TTN、5’-CCN、5’-TCCN、5’-TCN或5’-CTN,其中N表示A、G、C或T。
例如,在本发明的一些实施方案中,所述靶序列具有以下结构:5’-TYYN-N
x-3’或5’-YYN-Nx-3’,其中N独立地选自A、G、C和T,Y选自C和T;X为15≤X≤35的整数;Nx表示X个连续的核苷酸。
在一些实施方式中,所述crRNA的编码序列包含SEQ ID NO:25-33任一所示的crRNA骨架序列。在一些优选实施方式中,所述crRNA骨架序列为SEQ ID NO:30。在一些实施方式中,所述cRNA的编码序列还包括位于所述cRNA骨架序列的3’的与靶序列的互补序列特异性杂交的序列(即spacer序列)。
在一些实施方案中,所述crRNA由选自以下的核苷酸序列编码:
i)5’-ATTTCTACtgttGTAGAT-N
x-3’;
ii)5’-ATTTCTACtattGTAGAT-N
x-3’;
iii)5’-ATTTCTACtactGTAGAT-N
x-3’;
iv)5’-ATTTCTACtttgGTAGAT-N
x-3’;
v)5’-ATTTCTACtagttGTAGAT-N
x-3’;
vi)5’-ATTTCTACTATGGTAGAT-N
x-3’;
vii)5’-ATTTCTACTGTCGTAGAT-N
x-3’;
viii)5’-ATTTCTACTTGTGTAGAT-N
x-3’;和
ix)5’-ATTTCTACTGTGGTAGAT-N
x-3’,
其中N
x表示X个连续的核苷酸组成的核苷酸序列,N各自独立地选自A、G、C和T;X为18≤X≤35的整数,优选地,X=23。在一些实施方案中,序列N
x(spacer序列)能够与靶序列的互补序列特异性杂交。
在本发明中,待进行修饰的靶序列可以位于基因组的任何位置,例如位于功能基因如蛋白编码基因内,或者例如可以位于基因表达调控区如启动子区或增强子区,从而实 现对所述基因功能修饰或对基因表达的修饰。
可以通过T7EI、PCR/RE或测序方法检测所述细胞靶序列中的取代、缺失和/或添加。
在本发明的方法中,所述基因组编辑系统可以通过本领域技术人员熟知的各种方法导入细胞。
可用于将本发明的基因组编辑系统导入细胞的方法包括但不限于:磷酸钙转染、原生质融合、电穿孔、脂质体转染、微注射、病毒感染(如杆状病毒、痘苗病毒、腺病毒、腺相关病毒、慢病毒和其他病毒)、基因枪法、PEG介导的原生质体转化、土壤农杆菌介导的转化。
可以通过本发明的方法进行基因组编辑的细胞可以来自例如,哺乳动物如人、小鼠、大鼠、猴、犬、猪、羊、牛、猫;家禽如鸡、鸭、鹅;植物,包括单子叶植物和双子叶植物,例如水稻、玉米、小麦、高粱、大麦、大豆、花生、拟南芥等。
在一些实施方式中,本发明的方法在体外进行。例如,所述细胞是分离的细胞。在一些实施方式中,所述细胞是CAR-T细胞。在一些实施方式中,所述细胞是诱导的胚胎干细胞。
在另一些实施方式中,本发明的方法还可以在体内进行。例如,所述细胞是生物体内的细胞,可以通过例如病毒介导的方法将本发明的系统体内导入所述细胞。例如,所述细胞可以是患者体内的肿瘤细胞。
四、治疗应用
本发明还涵盖本发明的基因组编辑系统在疾病治疗中的应用。
通过本发明的基因组编辑系统对疾病相关基因进行修饰,可以实现疾病相关基因的上调、下调、失活、激活或者突变纠正等,从而实现疾病的预防和/或治疗。例如,本发明中靶序列可以位于疾病相关基因的蛋白编码区内,或者例如可以位于基因表达调控区如启动子区或增强子区,从而可以实现对所述疾病相关基因功能修饰或对疾病相关基因表达的修饰。
“疾病相关”基因是指与非疾病对照的组织或细胞相比,在来源于疾病影响的组织的细胞中以异常水平或以异常形式产生转录或翻译产物的任何基因。在改变的表达与疾病的出现和/或进展相关的情况下,它可以是以异常高的水平被表达的基因;它可以是以异常低的水平被表达的基因。疾病相关基因还指具有一个或多个突变或直接负责或与一个或多个负责疾病的病因学的基因连锁不平衡的遗传变异的基因。转录的或翻译的产物可以是已知的或未知的,并且可以处于正常或异常水平。
因此,本发明还提供治疗有需要的对象中的疾病的方法,包括向所述对象递送有效量的本发明的基因组编辑系统以修饰与所述疾病相关的基因。
本发明还提供本发明的基因组编辑系统在制备用于治疗有需要的对象中的疾病的药物组合物中的用途,其中所述基因组编辑系统用于修饰与所述疾病相关的基因。
本发明还提供用于治疗有需要的对象中的疾病的药物组合物,其包含本发明的基因 组编辑系统和药学可接受的载体,其中所述基因组编辑系统用于修饰与所述疾病相关的基因。
在一些实施方式中,所述对象是哺乳动物,例如人。
所述疾病的实例包括但不限于肿瘤、炎症、帕金森病、心血管疾病、阿尔茨海默病、自闭症、药物成瘾、年龄相关性黄斑变性、精神分裂症、遗传性疾病等。
本发明所述的疾病和相应的疾病相关基因的更多实例例如可以从中国专利申请CN201480045703.4中找到。
五、试剂盒
本发明的范围内还包括用于本发明的方法的试剂盒,该试剂盒包括本发明的基因组编辑系统,以及使用说明。试剂盒一股包括表明试剂盒内容物的预期用途和/或使用方法的标签。术语标签包括在试剂盒上或与试剂盒一起提供的或以其他方式随试剂盒提供的任何书面的或记录的材料。
材料与方法
细胞培养和转染
HEK293T,HeLa细胞培养在添加10%FBS(Gibco)和100U/ml青霉素和100ug/ml链霉素的DMEM培养液(Gibco)中,小鼠EpiSC细胞培养在添加bFGF的N2B27培养液中。转染前12h将细胞的密度以每孔500,000接种于12孔板中,12h后细胞的密度在60%-70%左右,然后使用Lipofectamine LTX and PLUS reagents(Invitrogen)将1.5ug(Cpf1∶crRNA=2∶1)质粒转入细胞中,在转染前换成无血清的opti-MEM培养液(Gibco),转染后8-12h换成添加血清的DMED培养液,转染48h后流式分选GFP阳性的细胞用于基因型鉴定。
基因型分析:T7EI分析和DNA测序
流式分选GFP阳性细胞,用Buffer L+1/100V Protease K(Biotool)55℃裂解30min,95℃失活5min,直接用于PCR检测。在Cpf1打靶位点附近设计合适的引物,扩增产物用DNA Clean&Concentrator
TM-5试剂盒纯化(ZYMO Research),200ng纯化后PCR产物加入1uL NEBuffer2(NEB)并用ddH
2O稀释到10uL。然后按照之前报道的方法用于再退火形成异源二聚体(Li,w.,et al.,Simultaneous generation and germline transmission of multiple gene mutations in rat using CRISPR-Cas systems.Nat Biotechnol,2013.31(8):p.684-6)。再退火产物加入0.3uL T7EI endnucelease和1/10V NEBuffer2(NEB),37℃酶切1h30min。3%TAE-Gel电泳分析基因型。Indel按照之前文章中报道的方法进行计算(Cong,L.,et al.,Multiplex genome engineering using CRISPR/Cas systems.Science,2013.339(6121):p.819-23)。
T7EI分析阳性的样品对应的PCR产物连接到pEASY-T1或pEASY-B(Transgen)载体上。转化、涂板,37℃培养过夜。挑取适量的单克隆菌落用于Sanger测序。通过与野生型基因型比对,确定突变基因型。
免疫荧光染色
Cpf1真核表达载体转染HeLa细胞48h后用4%PFA室温固定10min。PBST(PBS+0.3%Triton X100)清洗三遍。2%BSA(+0.3%Triton X100)室温封闭通透15min,一抗Rat anti-HA(Roche,1∶1000)孵育过夜,PBST清洗三遍。Cy3标记荧光二抗(Jackson ImmunoResearch,1∶1000)室温孵育2h,DAPI(Sigma,1∶1000)染核10min,PBST清洗三遍。用Aqueous Mounting Medium(Abcam)封片,固定。Zeiss LSM780用于观察。
Cfp1蛋白原核表达纯化
Cpf1编码基因克隆到BPK2103/2104原核表达载体上。融合的C端10xHis标签用于纯化蛋白。表达载体转化到BL21(DE3)E.coli感受态细胞(Transgen)中。挑选IPTG诱导高表达的克隆接种到300mL CmR+LB培养基中。37℃摇菌培养至OD600~0.4,加入终浓度1mM的IPTG,16℃诱导表达16h。8000rpm 4℃离心10min,收集菌体沉淀,40mL NPI-10(+1x EDTA-free Protease Inhibitor Cocktail,Roche;+5%甘油)裂解菌体,冰浴,超声破碎:总时间15min,超声2s,暂停5s,功率100W。破碎后,8000rpm 4℃离心10min,收集上清液。上清液中加入2mL His60Ni Superflow Resin(Takara),4℃摇匀1h,摇匀后经过Polypropylene Colums(Qiagen)纯化。利用重力流,分别用20mL NPI-20,20mL NPI-40和10mL NPI-100充分洗掉没有融合His10标签的杂蛋白。最后用6x0.5mL NPI-500将融合His10标签的Cpf1蛋白从Ni柱中洗脱下来。洗脱后的目的蛋白在透析液(50mM Tris-HCl,300mM KCl,1mM DTT,20%Glycerol)中透析过夜。透析后的蛋白溶液用100kDa Amicon Ultra-4,PLHK Ultracel-PL超滤管(Millipore)浓缩蛋白。用Micro BCA
TM Protein Assay Kit(Thermo Scientific
TM)测定蛋白浓度。
RNA体外转录
合成带有T7启动子的体外转录crRNA模板(BGI),按照操作手册用HiScribe
TM T7Quick High Yield RNA Synthesis Kit(NEB)体外转录crRNA。转录完成后用Oligo Clean&Concentrator
TM(ZYMO Research)纯化,用NanoDrop(Thermo Scientific
TM)测定浓度,-80℃保存。
体外酶切分析
带有不同5’PAM序列的靶序列合成后克隆到pUC19或p11-LacY-wtx1载体上,用引物扩增后切胶纯化。200ng纯化PCR产物分别与400ng crRNA以及50nM Cpf1蛋白在NEBuffer3(NEB)反应体系中37℃反应1h。随后在12%Urea-TBE-PAGE胶或2.5%琼脂 糖胶电泳分析。
靶序列
实验中所用靶序列如下表1所示:
表1
| 靶名称 | 序列(5′-3′) | 5′PAM(5′-3′) |
| 人Dnmt1靶位点1 | CCTCACTCCTGCTCGGTGAATTT | TTTC |
| 人Dnmt1靶位点2 | AGGAGTGTTCAGTCTCCGTGAAC | TTTG |
| 人Dnmt1靶位点3 | CTGATGGTCCATGTCTGTTACTC | TTTC |
| 小鼠MeCP2靶位点1 | CCTGCCTCTGCTGGCTCTGCAGA | TTTG |
| 小鼠MeCP2靶位点2 | TGATGTTTCTGCTTTGCCTGCCT | TTTC |
| 小鼠MeCP2靶位点3 | GGGGAAGCCGAGGCTTCTGGCAC | TTTG |
| 小鼠MeCP2靶位点4 | GTGTCCAACCTTCAGGCAAGGTG | TTTC |
| 小鼠MeCP2靶位点5 | GCCTGCCTCTGCTGGCTCTGCAG | TTT |
| 小鼠MeCP2靶位点6 | CTGATGTTTCTGCTTTGCCTGCC | TTT |
| 小鼠MeCP2靶位点7 | GGGGGAAGCCGAGGCTTCTGGCA | TTT |
| 小鼠MeCP2靶位点8 | CGTGTCCAACCTTCAGGCAAGGT | TTT |
| 小鼠Tet1靶位点1 | TCGGGTCAGCATCACTGGCTCAG | TTTC |
| 小鼠Tet1靶位点2 | CTGGGAGCAGCCTGAGAACCCTG | TTTG |
| 小鼠Tet1靶位点3 | ACATCAGCTGAGCCAGTGATGCT | TTTG |
| 小鼠Tet1靶位点4 | GATTCTTGCAGTAGGTGCACTCC | TTTC |
| 小鼠Tet1靶位点5 | CTCTTCTTACAGATCTGGTGGCT | TTTC |
| 小鼠Tet1靶位点6 | CTCGGGTCAGCATCACTGGCTCA | TTT |
| 小鼠Tet1靶位点7 | CACAGGCCAGTACCTCTTCTCCC | TTA |
| 小鼠Tet1靶位点8 | CGATTCTTGCAGTAGGTGCACTC | TTT |
| 人AAVS1靶位点1 | TGAGAATGGTGCGTCCTAGGTGT | TTTG |
| 人AAVS1靶位点2 | GTGAGAATGGTGCGTCCTAGGTG | TTT |
| 人AAVS1靶位点3 | ACCAGGTCGTGGCCGCCTCTACT | TTC |
| 人AAVS1靶位点4 | TGTGGAAAACTCCCTTTGTGAGA | CCG |
| 人AAVS1靶位点5 | CTACTCCCTTTCTCTTTCTCCAT | CCT |
| 人AAVS1靶位点6 | TGTCCCCCTTCCTCGTCCACCAT | CCC |
| 人AAVS1靶位点7 | CCTTTGTGAGAATGGTGCGTCCT | CTC |
| 人AAVS1靶位点8 | CTACAGGGGTTCCTGGCTCTGCT | TCC |
| 小鼠Apob靶位点12 | GTGGGCCCATGGCGGATGGATGG | TTTC |
| 小鼠Nrl靶位点1 | CCTCCCAGTCCCTTGGCTATGGA | TTTC |
| 小鼠Nrl靶位点7 | GGCTCCACACCATACAGCTCGGT | TTG |
实施例1.鉴定新的Cpf1蛋白
CRISPR/Cpt1(Clustered Regularly Interspaced Short Palindromic Repeats from Prevotella and Francisella 1)是在Prevotella和Francisella中发现的获得性免疫机制,并且被成功改造用于DNA编辑技术(Zetsche,B.,et al.,Cpf1is a single RNA-guided endonuclease of a class 2CRISPR-Cas system.Cell,2015.163(3):p.759-71.)。与CRISPR/Cas9不同,Cpf1只需要1条crRNA来引导,不需要tracrRNA,并且Cpf1蛋白使用富含T碱基的PAM序列。
本发明人利用已经报道的AsCpf1、LbCpf1和FnCpt1在NCBI数据库中进行 PSI-Blast搜索,从中挑选出25个未详细报道的Cpf1蛋白,其中有21个Cpf1蛋白拥有direct repeat(DR)序列。
通过序列比对发现,21条来自不同Cpf1蛋白的DR序列和RNA的二级结构相当保守(图1)。基于除了crRNA的保守外,所有Cpf1蛋白的PAM序列也很保守(即都是使用富含T碱基的PAM序列)的假设,从25个Cpf1蛋白中挑选了12个作为候选。所选12个候选Cpf1蛋白具体信息的如下表2所示:
表2.候选Cpf1蛋白

实施例2.验证Cpf1蛋白编辑人基因组的能力
针对在人中的表达进行密码子优化并合成12个选定蛋白的编码序列(BGI),克隆到真核表达载体(pCAG-2AeGFP-SV40和pCAG-2AeGFP-SV40_v4)和原核表达载体(BPK2103-ccdB和BPK2014-ccdB)中。
通过HeLa细胞转染实验,我们可以发现,所选定的Cpf1蛋白可以明显地在细胞核中表达(图2)。
接下来,通过与靶向人Dnmt1基因的crRNA共同转染293T细胞,经PCR和T7EI酶切鉴定,发现有8种Cpf1蛋白(Ab、Ar、Bo、Bs、Hk、Lp、Ps、Sa)可以在293T细胞中的Dnmt1基因的3号位点引发突变(图3A)。而DNA测序也进一步证明该基因位点确实产生了基因突变(图3B)。
为了进一步证明所鉴定的Cpf1蛋白可以在哺乳动物基因组上引发突变,选取了Dnmt1基因的1号和2号位点重复上述实验。T7EI酶切结果证明,ArCpf1、BsCpf1、HkCpf1和LpCpf1四个蛋白可以在两个基因位点产生明显的indel(图4A和5A)。而DNA测序结果证明除了上述4个蛋白,PsCpf1和SaCpf1蛋白也能引发基因的突变(图4B和 5B)。
实施例3.鉴定PAM序列
为了确定所鉴定Cpf1蛋白的PAM序列,首先,选择了BsCpf1蛋白进行详细的研究。
利用大肠杆菌原核表达BsCpf1,通过His标签进行蛋白纯化(图6A)。通过将纯化的BsCpf1蛋白和对应的crRNA以及dsDNA片段(人Dnmt1靶位点2)在37℃孵育1h,然后进行TBE变性PAGE胶电泳,证明BsCpf1的PAM序列为5’(T)TTN-(图6B-E)。
然后,利用类似方法,鉴别其余Cpf1蛋白的PAM序列,结果如图7所示。实验结果表明,所选的Cpf1蛋白均具有体外酶切活性。其中9种Cpf1蛋白的PAM序列是5’(T)TTN-。而C6Cpf1、HkCpf1和PsCpf1的PAM序列是5’(T)YYN-。
为了确认HkCpf1体内编辑的PAM序列是5’(T)YYN-,将HkCpf1载体与人AAVS1基因上8个位点的靶向crRNA载体分别转染293T细胞。实验结果表明(图8),HkCpf1可以对其中的7个位点进行编辑并产生突变,其PAM序列是5’(T)YYN-(图8B下划线部分)。
实施例4.小鼠基因组编辑
为了拓展这些Cpf1蛋白的适用性,在小鼠的EpiSC细胞系中进行了一些列的转染实验。
首先,我们将BsCpf1载体与小鼠Tet1基因上8个位点的靶向crRNA载体(pUC19-crRNA)分别转染EpiSC细胞。通过T7EI酶切和DNA测序证明,BsCpf1在2号,3号和7号位点引发基因突变(图9A)。其中,7号位点的PAM序列为5’TTA-,该结果与实施例3的结论吻合。说明BsCpf1蛋白使用5’TTN-PAM序列。
接下来,重复验证了ArCpf1、BsCpf1、HkCpf1和PxCpf1的DNA编辑能力。通过与小鼠MeCP2基因8个位点的靶向crRNA载体分别共转染。利用T7EI酶切和DNA测序,证明ArCpf1(图10D、E)、BsCpf1(图9B、C)、HkCpf1(图10F、G)和PxCpf1(图11H、I)四种蛋白可以靶向编辑小鼠的基因组。
此外,进一步用小鼠Apob靶位点12、小鼠MeCP2靶位点4、小鼠Nrl靶位点1和小鼠Nrl靶位点7验证ArCpf1、BsCpf1、HkCpf1、LpCpf1、PrCpf1和PxCpf1的编辑能力。结果如图12所示,这六种蛋白都能实现基因组编辑。其中,Nrl-7位点的PAM序列为5’TTG,说明BsCpf1和PrCpf1的PAM序列为5’TTN-。
以上实验结果证明,本发明发现的12个Cpf1蛋白都具有DNA编辑的能力,其中ArCpf1(SEQ ID NO:1)、BsCpf1(SEQ ID NO:8)、HkCpf1(SEQ ID NO:4)、PxCpf1(SEQ ID NO:11)、LpCpf1(SEQ ID NO:2)和PrCpf1(SEQ ID NO:12)能够实现高效的哺乳动物基因组编辑。
实施例5优化crRNA骨架以改进编辑效率
本实施例对新鉴定的可以用于哺乳动物基因组编辑的Cpt1蛋白的cRNA骨架进行了优化以提高各Cpt1蛋白的基因组编辑效率(表3)。
实验结果示于图13。图13A显示细胞转染各Cpt1蛋白和不同的crRNA质粒,通过PCR和T7EI分析,证明不同的crRNA骨架影响Cpt1蛋白的有效编辑效率。
然后,发明人建立了crRNA的突变体库,分别与BsCpt1或PrCpt1转染细胞。通过PCR和T7EI分析,从中筛选出能够使Cpt1有效编辑哺乳动物基因组的crRNA突变体。
crRNA31突变体的编辑效率明显高于来源于菌株基因组的野生型crRNA骨架(crRNA2)。细胞转染Cpf1和crRNA31、crRNA2质粒,通过PCR和T7EI分析,证明crRNA31可以使ArCpf1、BsCpf1、HkCpf1、PrCpf1、PxCpt15种Cpt1在MeCP2-4位点的编辑效率提高一倍左右(图13B)。
图14A和B显示通过T7EI分析不同的靶位点,验证筛选到的cRNA骨架可以提高BsCpt1和PrCpf1的编辑效率。其中对于PrCpt1而言,除了crRNA31骨架,crRNA77、crRNA129和crRNA159骨架在Nrl-1位点的编辑效率也有明显提高。
图14C显示流式细胞术分析细胞内GFP编辑效率。其中,crRNA31骨架可以提高BsCpt1和PrCpf1的编辑效率,crRNA77和crRNA159骨架也可以明显提高PrCpt1的编辑效率。
表3.鉴定的cRNA骨架
| cRNA骨架名称 | crRNA骨架序列(5′-3′) | SEQ ID NO |
| crRNA1 | ATTTCTACtgttGTAGAT | 25 |
| crRNA2 | ATTTCTACtattGTAGAT | 26 |
| crRNA3 | ATTTCTACtactGTAGAT | 27 |
| crRNA4 | ATTTCTACtttgGTAGAT | 28 |
| crRNA5 | ATTTCTACtagttGTAGAT | 29 |
| crRNA31 | ATTTCTACTATGGTAGAT | 30 |
| crRNA77 | ATTTCTACTGTCGTAGAT | 31 |
| crRNA129 | ATTTCTACTTGTGTAGAT | 32 |
| crRNA159 | ATTTCTACTGTGGTAGAT | 33 |
序列信息
>SEQ ID NO:1 ArCpf1


>SEQ ID NO:2 LpCpf1

>SEQ ID NO:3 SaCpf1

>SEQ ID NO:4 HkCpf1


>SEQ ID NO:5 AbCpf1

>SEQ ID NO:6 BoCpf1

>SEQ ID NO:7 OsCpf1


>SEQ ID NO:8 BsCpf1

>SEQ ID NO:9 PsCpf1

>SEQ ID NO:10 C6Cpf1


>SEQ ID NO:11 PxCpf1

>SEQ ID NO:12 PrCpf1

>SEQ ID NO:13 ArCpf1核苷酸序列


>SEQ ID NO:14 LpCpf1核苷酸序列


>SEQ ID NO:15 SaCpf1核苷酸序列


>SEQ ID NO:16 HkCpf1核苷酸序列


>SEQ ID NO:17 AbCpf1核苷酸序列


>SEQ ID NO:18 BoCpf1核苷酸序列


>SEQ ID NO:19 OsCpf1核苷酸序列


>SEQ ID NO:20 BsCpf1核苷酸序列


>SEQ ID NO:21 PsCpf1核苷酸序列


>SEQ ID NO:22 C6Cpf1核苷酸序列


>SEQ ID NO:23 PxCpf1核苷酸序列


>SEQ ID NO:24 PrCpf1核苷酸序列


>SEQ ID NO:25 crRNA1骨架序列

>SEQ ID NO:26 crRNA2骨架序列

>SEQ ID NO:27 crRNA3骨架序列

>SEQ ID NO:28 crRNA4骨架序列

>SEQ ID NO:29 crRNA5骨架序列

>SEQ ID NO:30 crRNA31骨架序列

>SEQ ID NO:31 crRNA77骨架序列

>SEQ ID NO:32 crRNA129骨架序列

>SEQ ID NO:33 crRNA159骨架序列

Claims (20)
- 一种用于对细胞基因组中的靶序列进行定点修饰的基因组编辑系统,其包含以下i)至v)中至少一项:i)Cpf1蛋白,和向导RNA;ii)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和向导RNA;iii)Cpf1蛋白,和包含编码向导RNA的核苷酸序列的表达构建体;iv)包含编码Cpf1蛋白的核苷酸序列的表达构建体,和包含编码向导RNA的核苷酸序列的表达构建体;v)包含编码Cpf1蛋白的核苷酸序列和编码向导RNA的核苷酸序列的表达构建体;其中所述Cpf1蛋白包含SEQ ID NO:1-12的氨基酸序列或与SEQ ID NO:1-12之一具有至少80%序列相同性的氨基酸序列,所述向导RNA能够将所述Cpf1蛋白靶向所述细胞基因组中的靶序列。
- 权利要求1的系统,其中所述Cpf1蛋白包含与SEQ ID NO:1-12之一具有至少85%、至少90%、至少95%、至少96%、至少97%、至少98%、至少99%、或100%序列相同性的氨基酸序列。
- 权利要求1的系统,其中所述Cpf1蛋白包含相对于SEQ ID NO:1-12之一具有一或多个氨基酸残基取代、缺失或添加的氨基酸序列,例如,所述Cpf1蛋白包含相对于SEQ ID NO:1-12之一具有1个、2个、3个、4个、5个、6个、7个、8个、9个、10个氨基酸残基取代、缺失或添加的氨基酸序列。
- 权利要求1的系统,其中所述Cpf1蛋白来自选自以下的物种:Agathobacter rectalis、Lachnospira pectinoschiza、Sneathia amnii、Helcococcus kunzii、Arcobacter butzleri、Bacteroidetes oral、Oribacterium sp.、Butyrivibrio sp.、Proteocatella sphenisci、Candidatus Dojkabacteria、Pseudobutyrivibrio xylanivorans和Pseudobutyrivibrio ruminis。
- 权利要求1的系统,所述Cpf1蛋白包含选自SEQ ID NO:1、SEQ ID NO:2、SEQ ID NO:4、SEQ ID NO:8、SEQ ID NO:11和SEQ ID NO:12所示的氨基酸序列。
- 权利要求1的系统,其中所述编码Cpf1蛋白的核苷酸序列针对待进行定点修饰的细胞所来自的生物体进行密码子优化。
- 权利要求1的系统,其中所述编码Cpf1蛋白的核苷酸序列选自SEQ ID NO:13-24。
- 权利要求1的系统,其中所述向导RNA是crRNA。
- 权利要求8的系统,其中所述crRNA的编码序列包含SEQ ID NO:25-33任一所示的crRNA骨架序列,优选包含SEQ ID NO:30所示的crRNA骨架序列。
- 权利要求1的系统,所述靶序列具有以下结构:5’-TYYN-N X-3’或5’-YYN-N X-3’,其中N独立地选自A、G、C和T;Y选自C和T;X为15≤X≤35的整数;Nx表示x个连续的核苷酸。
- 一种对细胞基因组中的靶序列进行定点修饰的方法,包括将权利要求1-10中任一项的系统导入细胞中,由此所述向导RNA将所述Cpf1蛋白靶向所述细胞基因组中的靶序列,导致所述靶序列中的一或多个核苷酸取代、缺失和/或添加。
- 权利要求11的方法,其中所述细胞来自哺乳动物如人、小鼠、大鼠、猴、犬、猪、羊、牛、猫;家禽如鸡、鸭、鹅;植物,包括单子叶植物和双子叶植物,例如水稻、玉米、小麦、高粱、大麦、大豆、花生、拟南芥等。
- 权利要求11-12中任一项的方法,其中所述系统通过选自以下的方法导入所述细胞:磷酸钙转染、原生质融合、电穿孔、脂质体转染、微注射、病毒感染(如杆状病毒、痘苗病毒、腺病毒、腺相关病毒、慢病毒和其他病毒)、基因枪法、PEG介导的原生质体转化、土壤农杆菌介导的转化。
- 一种治疗有需要的对象中的疾病的方法,包括向所述对象递送有效量的权利要求1-10中任一项的基因组编辑系统以修饰所述对象中与所述疾病相关的基因。
- 权利要求1-10中任一项的基因组编辑系统在制备用于治疗有需要的对象中的疾病的药物组合物中的用途,其中所述基因组编辑系统用于修饰所述对象中与所述疾病相关的基因。
- 一种用于治疗有需要的对象中的疾病的药物组合物,其包含权利要求1-10中任一项的基因组编辑系统和药学可接受的载体,其中所述基因组编辑系统用于修饰所述对象中与所述疾病相关的基因。
- 权利要求14-16的方法、用途或药物组合物,其中所述对象是哺乳动物例如人。
- 权利要求17的方法、用途或药物组合物,其中所述疾病选自肿瘤、炎症、帕金森病、心血管疾病、阿尔茨海默病、自闭症、药物成瘾、年龄相关性黄斑变性、精神分裂症和遗传性疾病。
- 一种crRNA,其包含对应于SEQ ID NO:25-33任一的crRNA骨架序列或其编码序列包含SEQ ID NO:25-33任一所示的序列。
- 权利要求19的crRNA,所述crRNA由选自以下的核苷酸序列编码:i)5’-ATTTCTACtgttGTAGAT(SEQ ID NO:25)-N x-3’;ii)5’-ATTTCTACtattGTAGAT(SEQ ID NO:26)-N x-3’;iii)5’-ATTTCTACtactGTAGAT(SEQ ID NO:27)-N x-3’;iv)5’-ATTTCTACtttgGTAGAT(SEQ ID NO:28)-N x-3’;v)5’-ATTTCTACtagttGTAGAT(SEQ ID NO:29)-N x-3’;vi)5’-ATTTCTACTATGGTAGAT(SEQ ID NO:30)-N x-3’;vii)5’-ATTTCTACTGTCGTAGAT(SEQ ID NO:31)-N x-3’;viii)5’-ATTTCTACTTGTGTAGAT(SEQ ID NO:32)-N x-3’;和ix)5’-ATTTCTACTGTGGTAGAT(SEQ ID NO:33)-N x-3’,其中N x表示X个连续的核苷酸组成的靶核苷酸序列,N各自独立地选自A、G、C和T;X为18≤X≤35的整数,优选地,X=23。
Priority Applications (4)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| EP18783675.4A EP3611258B1 (en) | 2017-04-10 | 2018-04-10 | System and method for genome editing |
| JP2019555026A JP7100057B2 (ja) | 2017-04-10 | 2018-04-10 | ゲノム編集のためのシステム及び方法 |
| US16/603,975 US11702643B2 (en) | 2017-04-10 | 2018-04-10 | System and method for genome editing |
| JP2022064162A JP7700079B2 (ja) | 2017-04-10 | 2022-04-07 | ゲノム編集のためのシステム及び方法 |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN201710228595.X | 2017-04-10 | ||
| CN201710228595.XA CN108690845B (zh) | 2017-04-10 | 2017-04-10 | 基因组编辑系统和方法 |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2018188571A1 true WO2018188571A1 (zh) | 2018-10-18 |
Family
ID=63793114
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/CN2018/082446 Ceased WO2018188571A1 (zh) | 2017-04-10 | 2018-04-10 | 基因组编辑系统和方法 |
Country Status (5)
| Country | Link |
|---|---|
| US (1) | US11702643B2 (zh) |
| EP (1) | EP3611258B1 (zh) |
| JP (2) | JP7100057B2 (zh) |
| CN (1) | CN108690845B (zh) |
| WO (1) | WO2018188571A1 (zh) |
Cited By (15)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US11098297B2 (en) | 2017-06-09 | 2021-08-24 | Editas Medicine, Inc. | Engineered Cas9 nucleases |
| US11236313B2 (en) | 2016-04-13 | 2022-02-01 | Editas Medicine, Inc. | Cas9 fusion molecules, gene editing systems, and methods of use thereof |
| WO2022120520A1 (en) * | 2020-12-07 | 2022-06-16 | Institute Of Zoology, Chinese Academy Of Sciences | Engineered cas effector proteins and methods of use thereof |
| US11390884B2 (en) | 2015-05-11 | 2022-07-19 | Editas Medicine, Inc. | Optimized CRISPR/cas9 systems and methods for gene editing in stem cells |
| US11499151B2 (en) | 2017-04-28 | 2022-11-15 | Editas Medicine, Inc. | Methods and systems for analyzing guide RNA molecules |
| US11597924B2 (en) | 2016-03-25 | 2023-03-07 | Editas Medicine, Inc. | Genome editing systems comprising repair-modulating enzyme molecules and methods of their use |
| US11667911B2 (en) | 2015-09-24 | 2023-06-06 | Editas Medicine, Inc. | Use of exonucleases to improve CRISPR/CAS-mediated genome editing |
| US11680268B2 (en) | 2014-11-07 | 2023-06-20 | Editas Medicine, Inc. | Methods for improving CRISPR/Cas-mediated genome-editing |
| US11866726B2 (en) | 2017-07-14 | 2024-01-09 | Editas Medicine, Inc. | Systems and methods for targeted integration and genome editing and detection thereof using integrated priming sites |
| US11911415B2 (en) | 2015-06-09 | 2024-02-27 | Editas Medicine, Inc. | CRISPR/Cas-related methods and compositions for improving transplantation |
| US12110545B2 (en) | 2017-01-06 | 2024-10-08 | Editas Medicine, Inc. | Methods of assessing nuclease cleavage |
| WO2024229938A1 (zh) * | 2023-05-08 | 2024-11-14 | 珠海舒桐医疗科技有限公司 | 一种Cpf1蛋白、V型基因编辑系统及应用 |
| US12201699B2 (en) | 2014-10-10 | 2025-01-21 | Editas Medicine, Inc. | Compositions and methods for promoting homology directed repair |
| US12286727B2 (en) | 2016-12-19 | 2025-04-29 | Editas Medicine, Inc. | Assessing nuclease cleavage |
| US12338436B2 (en) | 2018-06-29 | 2025-06-24 | Editas Medicine, Inc. | Synthetic guide molecules, compositions and methods relating thereto |
Families Citing this family (7)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| KR102677877B1 (ko) * | 2016-12-22 | 2024-06-25 | 키진 엔.브이. | 이중나선 dna의 표적화된 변형 방법 |
| CN108690845B (zh) * | 2017-04-10 | 2021-04-27 | 中国科学院动物研究所 | 基因组编辑系统和方法 |
| CN116694603B (zh) * | 2019-05-14 | 2026-07-14 | 深圳华大生命科学研究院 | 新型的Cas蛋白、Crispr-Cas系统及其在基因编辑领域中的用途 |
| CN111235130B (zh) * | 2019-11-15 | 2022-11-25 | 武汉大学 | II类V型CRISPR蛋白CeCas12a及其在基因编辑的应用 |
| CA3193089A1 (en) * | 2020-09-18 | 2022-03-24 | Jamie KERSHNER | Constructs and uses thereof for efficient and specific genome editing |
| CN117897481A (zh) * | 2021-09-03 | 2024-04-16 | 中国科学院动物研究所 | 一种外源基因定点整合的系统及方法 |
| CN119264278B (zh) * | 2024-12-09 | 2025-04-11 | 中国水产科学研究院南海水产研究所 | 一种用于斑节对虾基因编辑的融合蛋白PmMAD7-NLS及其应用 |
Citations (2)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN105907785A (zh) * | 2016-05-05 | 2016-08-31 | 苏州吉玛基因股份有限公司 | 化学合成的crRNA用于CRISPR/Cpf1系统在基因编辑中的应用 |
| WO2016186946A1 (en) * | 2015-05-15 | 2016-11-24 | Pioneer Hi-Bred International, Inc. | Rapid characterization of cas endonuclease systems, pam sequences and guide rna elements |
Family Cites Families (6)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US9790490B2 (en) | 2015-06-18 | 2017-10-17 | The Broad Institute Inc. | CRISPR enzymes and systems |
| JP2018519811A (ja) | 2015-06-29 | 2018-07-26 | アイオーニス ファーマシューティカルズ, インコーポレーテッドIonis Pharmaceuticals,Inc. | 修飾crispr rna及び修飾単一crispr rnaならびにその使用 |
| WO2017015015A1 (en) | 2015-07-17 | 2017-01-26 | Emory University | Crispr-associated protein from francisella and uses related thereto |
| US20180237800A1 (en) | 2015-09-21 | 2018-08-23 | The Regents Of The University Of California | Compositions and methods for target nucleic acid modification |
| MX2018010484A (es) | 2016-03-04 | 2019-01-10 | Editas Medicine Inc | Métodos, composiciones y componentes relacionados con crispr-cpf1 para la inmunoterapia contra el cáncer. |
| CN108690845B (zh) | 2017-04-10 | 2021-04-27 | 中国科学院动物研究所 | 基因组编辑系统和方法 |
-
2017
- 2017-04-10 CN CN201710228595.XA patent/CN108690845B/zh active Active
-
2018
- 2018-04-10 JP JP2019555026A patent/JP7100057B2/ja active Active
- 2018-04-10 EP EP18783675.4A patent/EP3611258B1/en active Active
- 2018-04-10 US US16/603,975 patent/US11702643B2/en active Active
- 2018-04-10 WO PCT/CN2018/082446 patent/WO2018188571A1/zh not_active Ceased
-
2022
- 2022-04-07 JP JP2022064162A patent/JP7700079B2/ja active Active
Patent Citations (2)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| WO2016186946A1 (en) * | 2015-05-15 | 2016-11-24 | Pioneer Hi-Bred International, Inc. | Rapid characterization of cas endonuclease systems, pam sequences and guide rna elements |
| CN105907785A (zh) * | 2016-05-05 | 2016-08-31 | 苏州吉玛基因股份有限公司 | 化学合成的crRNA用于CRISPR/Cpf1系统在基因编辑中的应用 |
Non-Patent Citations (23)
| Title |
|---|
| "Biocomputing: Informatics and Genome Projects", 1993, ACADEMIC PRESS |
| "Computer Analysis of Sequence Data", 1994, HUMANA PRESS |
| "Sequence Analysis Primer", 1991, M STOCKTON PRESS |
| CARRILLO, H.LIPMAN, D., SIAM J APPLIED MATH, vol. 48, 1988, pages 1073 |
| CONG, L. ET AL.: "Multiplex genome engineering using CRISPR/Cas systems", SCIENCE, vol. 339, no. 6121, 2013, pages 819 - 23, XP055458249, DOI: 10.1126/science.1231143 |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Arcobacter butzleri", XP055613739, retrieved from NCBI Database accession no. WP_052943011. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Bacteroidetes oral taxon 274", XP055613818, retrieved from NCBI Database accession no. WP_009217842. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Butyrivibrio sp. NC3005", XP055613822, retrieved from NCBI Database accession no. WP_035798880. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Helcococcus kunzii", XP055613813, retrieved from NCBI Database accession no. WP_005398606. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Oribacterium sp. NK2B42", XP055613820, retrieved from NCBI Database accession no. WP_049895985. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Proteocatella sphenisci", retrieved from NCBI Database accession no. WP_028830240. 1 * |
| DATABASE Protein 1 October 2015 (2015-10-01), "type V CRISPR-associated protein Cpfl [Pseudobutyrivibrio ruminis", XP055613837, retrieved from NCBI Database accession no. WP_028248456. 1 * |
| DATABASE Protein 13 November 2015 (2015-11-13), HARWICH, M. D. JR.: "hypothetical protein VC03_02970 [Sneathia amnii", XP055613810, retrieved from NCBI Database accession no. AKC95493. 1 * |
| DATABASE Protein 17 October 2016 (2016-10-17), VARGHESE, N.: "CRISPR-associated protein Cpfl, subtype PREFRAN [Pseudobu- tyrivibrio xylanivorans", XP055613833, retrieved from NCBI Database accession no. SCZ76797. 1 * |
| DATABASE Protein 7 May 2015 (2015-05-07), BROWN, C. T.: "hypothetical protein US 52_C0007G0008 [candidate division WS6 bacterium GW2011_GWA2_37_6", XP055613829, retrieved from NCBI Database accession no. KKQ36153. 1 * |
| DATABASE Protein 9 February 2016 (2016-02-09), "type V CRISPR-associated protein Cpfl [[Eubacterium] rectale", XP055613736, retrieved from NCBI Database accession no. WP_055272206 * |
| GAO P.: "Type V CRISPR-Cas Cpfl endonuclease employs a unique mechanism for crRNA-mediated target DNA recognition", CELL RESEARCH, vol. 26, no. 8, 22 July 2016 (2016-07-22), pages 901 - 913, XP055366082 * |
| LI, W. ET AL.: "Simultaneous generation and germline transmission of multiple gene mutations in rat using CRISPR-Cas systems", NAT BIOTECHNOL, vol. 31, no. 8, 2013, pages 684 - 6, XP055324100, DOI: 10.1038/nbt.2652 |
| NAKAMURA Y.: "Codon usage tabulated from the international DNA sequence databases: status for the year 2000", NUCL.ACIDS RES, vol. 28, 2000, pages 292, XP002941557, DOI: 10.1093/nar/28.1.292 |
| SAMBROOK, J.FRITSCH, E.F.MANIATIS, T.: "Molecular Cloning: A Laboratory Manual", 1989, COLD SPRING HARBOR LABORATORY PRESS |
| WATSON ET AL.: "Sequence Analysis in Molecular Biology", 1987, THE BENJAMIN/CUMMINGS PUB. CO., pages: 224 |
| ZETSCHE, B. ET AL.: "Cpfl is a single RNA-guided endonuclease of a class 2 CRISPR-Cas system", CELL, vol. 163, no. 3, 2015, pages 759 - 71 |
| ZHANG ET AL., CELL, vol. 163, 22 October 2015 (2015-10-22), pages 1 - 13 |
Cited By (17)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US12201699B2 (en) | 2014-10-10 | 2025-01-21 | Editas Medicine, Inc. | Compositions and methods for promoting homology directed repair |
| US11680268B2 (en) | 2014-11-07 | 2023-06-20 | Editas Medicine, Inc. | Methods for improving CRISPR/Cas-mediated genome-editing |
| US11390884B2 (en) | 2015-05-11 | 2022-07-19 | Editas Medicine, Inc. | Optimized CRISPR/cas9 systems and methods for gene editing in stem cells |
| US11911415B2 (en) | 2015-06-09 | 2024-02-27 | Editas Medicine, Inc. | CRISPR/Cas-related methods and compositions for improving transplantation |
| US11667911B2 (en) | 2015-09-24 | 2023-06-06 | Editas Medicine, Inc. | Use of exonucleases to improve CRISPR/CAS-mediated genome editing |
| US11597924B2 (en) | 2016-03-25 | 2023-03-07 | Editas Medicine, Inc. | Genome editing systems comprising repair-modulating enzyme molecules and methods of their use |
| US11236313B2 (en) | 2016-04-13 | 2022-02-01 | Editas Medicine, Inc. | Cas9 fusion molecules, gene editing systems, and methods of use thereof |
| US12049651B2 (en) | 2016-04-13 | 2024-07-30 | Editas Medicine, Inc. | Cas9 fusion molecules, gene editing systems, and methods of use thereof |
| US12286727B2 (en) | 2016-12-19 | 2025-04-29 | Editas Medicine, Inc. | Assessing nuclease cleavage |
| US12110545B2 (en) | 2017-01-06 | 2024-10-08 | Editas Medicine, Inc. | Methods of assessing nuclease cleavage |
| US11499151B2 (en) | 2017-04-28 | 2022-11-15 | Editas Medicine, Inc. | Methods and systems for analyzing guide RNA molecules |
| US12297466B2 (en) | 2017-06-09 | 2025-05-13 | Editas Medicine, Inc. | Engineered Cas9 nucleases |
| US11098297B2 (en) | 2017-06-09 | 2021-08-24 | Editas Medicine, Inc. | Engineered Cas9 nucleases |
| US11866726B2 (en) | 2017-07-14 | 2024-01-09 | Editas Medicine, Inc. | Systems and methods for targeted integration and genome editing and detection thereof using integrated priming sites |
| US12338436B2 (en) | 2018-06-29 | 2025-06-24 | Editas Medicine, Inc. | Synthetic guide molecules, compositions and methods relating thereto |
| WO2022120520A1 (en) * | 2020-12-07 | 2022-06-16 | Institute Of Zoology, Chinese Academy Of Sciences | Engineered cas effector proteins and methods of use thereof |
| WO2024229938A1 (zh) * | 2023-05-08 | 2024-11-14 | 珠海舒桐医疗科技有限公司 | 一种Cpf1蛋白、V型基因编辑系统及应用 |
Also Published As
| Publication number | Publication date |
|---|---|
| JP2022105015A (ja) | 2022-07-12 |
| CN108690845A (zh) | 2018-10-23 |
| JP7700079B2 (ja) | 2025-06-30 |
| JP2020516255A (ja) | 2020-06-11 |
| CN108690845B (zh) | 2021-04-27 |
| US11702643B2 (en) | 2023-07-18 |
| JP7100057B2 (ja) | 2022-07-12 |
| EP3611258A4 (en) | 2020-05-06 |
| EP3611258A1 (en) | 2020-02-19 |
| EP3611258B1 (en) | 2024-12-11 |
| US20200149021A1 (en) | 2020-05-14 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| JP7700079B2 (ja) | ゲノム編集のためのシステム及び方法 | |
| US10781432B1 (en) | Engineered cascade components and cascade complexes | |
| US20220025347A1 (en) | Variants of CRISPR from Prevotella and Francisella 1 (Cpf1) | |
| JP7138712B2 (ja) | ゲノム編集のためのシステム及び方法 | |
| JP2023002712A (ja) | S.ピオゲネスcas9変異遺伝子及びこれによってコードされるポリペプチド | |
| US20200224221A1 (en) | Genome editing method | |
| KR20190005801A (ko) | 표적 특이적 crispr 변이체 | |
| KR102626503B1 (ko) | 뉴클레오타이드 표적 인식을 이용한 표적 서열 특이적 개변 기술 | |
| CN110300802A (zh) | 用于动物胚胎碱基编辑的组合物和碱基编辑方法 | |
| WO2023169454A1 (zh) | 腺嘌呤脱氨酶及其在碱基编辑中的用途 | |
| JP7361109B2 (ja) | C2c1ヌクレアーゼに基づくゲノム編集のためのシステムおよび方法 | |
| WO2020224611A1 (en) | Improved gene editing system | |
| WO2019120193A1 (zh) | 拆分型单碱基基因编辑系统及其应用 | |
| JP2024501892A (ja) | 新規の核酸誘導型ヌクレアーゼ | |
| WO2021004456A1 (zh) | 改进的基因组编辑系统及其应用 | |
| CN115109798A (zh) | 改进的cg碱基编辑系统 | |
| HK1261024B (zh) | 基因组编辑系统和方法 | |
| HK1261024A1 (zh) | 基因组编辑系统和方法 | |
| WO2025087411A1 (zh) | 一种脱氨酶、包含其的碱基编辑器及其应用 | |
| WO2021098709A1 (zh) | 衍生自黄杆菌的基因编辑系统 |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 18783675 Country of ref document: EP Kind code of ref document: A1 |
|
| ENP | Entry into the national phase |
Ref document number: 2019555026 Country of ref document: JP Kind code of ref document: A |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| ENP | Entry into the national phase |
Ref document number: 2018783675 Country of ref document: EP Effective date: 20191111 |