WO2019091318A1 - 图像分类和转换方法、装置、图像处理器及其训练方法和介质 - Google Patents
图像分类和转换方法、装置、图像处理器及其训练方法和介质 Download PDFInfo
- Publication number
- WO2019091318A1 WO2019091318A1 PCT/CN2018/113115 CN2018113115W WO2019091318A1 WO 2019091318 A1 WO2019091318 A1 WO 2019091318A1 CN 2018113115 W CN2018113115 W CN 2018113115W WO 2019091318 A1 WO2019091318 A1 WO 2019091318A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- image
- output
- input
- component
- feature
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Images




Classifications
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06T—IMAGE DATA PROCESSING OR GENERATION, IN GENERAL
- G06T9/00—Image coding
- G06T9/002—Image coding using neural networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F18/00—Pattern recognition
- G06F18/20—Analysing
- G06F18/21—Design or setup of recognition systems or techniques; Extraction of features in feature space; Blind source separation
- G06F18/217—Validation; Performance evaluation; Active pattern learning techniques
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F18/00—Pattern recognition
- G06F18/20—Analysing
- G06F18/24—Classification techniques
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
- G06N3/0455—Auto-encoder networks; Encoder-decoder networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/0464—Convolutional networks [CNN, ConvNet]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/06—Physical realisation, i.e. hardware implementation of neural networks, neurons or parts of neurons
- G06N3/063—Physical realisation, i.e. hardware implementation of neural networks, neurons or parts of neurons using electronic means
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/09—Supervised learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V10/00—Arrangements for image or video recognition or understanding
- G06V10/70—Arrangements for image or video recognition or understanding using pattern recognition or machine learning
- G06V10/764—Arrangements for image or video recognition or understanding using pattern recognition or machine learning using classification, e.g. of video objects
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V10/00—Arrangements for image or video recognition or understanding
- G06V10/70—Arrangements for image or video recognition or understanding using pattern recognition or machine learning
- G06V10/82—Arrangements for image or video recognition or understanding using pattern recognition or machine learning using neural networks
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N19/00—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals
- H04N19/10—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using adaptive coding
- H04N19/169—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using adaptive coding characterised by the coding unit, i.e. the structural portion or semantic portion of the video signal being the object or the subject of the adaptive coding
- H04N19/182—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using adaptive coding characterised by the coding unit, i.e. the structural portion or semantic portion of the video signal being the object or the subject of the adaptive coding the unit being a pixel
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N19/00—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals
- H04N19/20—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using video object coding
- H04N19/29—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using video object coding involving scalability at the object level, e.g. video object layer [VOL]
Definitions
- the present disclosure relates to the field of image processing, and in particular, to an image classification method, an image classification device, an image conversion method, an image processor including an image classification device and an image restoration device, a training method thereof, and a medium.
- the input image can be analyzed and a label for the input image is output, the label representing the image category of the input image.
- a label for the input image is output, the label representing the image category of the input image.
- information of an image category can be obtained, but image pixel information corresponding to its category in the input image cannot be obtained.
- the present disclosure provides a new method, apparatus, image processor, training method and medium thereof for image classification and conversion.
- an image classification method comprising: receiving an input image; image encoding the input image by using a cascaded n-level coding unit to generate an output image, n being an integer greater than 1, for 1 ⁇ i ⁇ n, the input of the i-th coding unit is the i-th coded input image and includes m i-1 image components, and the output of the i-th coding unit is the i-th coded output image and includes m i images
- the component, and the output of the i-th coding unit is an input of the i+1th coding unit, where m is an integer greater than one; outputting the output image, the output image comprising m n output sub-images, the m each of the n sub-output image corresponding to an image category; n obtaining output image sub-pixel values m of each of the image output, and determining the pixel values m n output sub-images least One is a category sub-image of the
- an image classification apparatus comprising: an input configured to receive an input image; a cascaded n-level encoding unit configured to image encode the input image to generate an output image, n is an integer greater than 1, and for 1 ⁇ i ⁇ n, the input of the i-th coding unit is the i-th coded input image and includes m i-1 image components, and the output of the i-th coding unit is the i-th coding Outputting an image and including m i image components, and an output of the i-th coding unit is an input of an i+1th coding unit, where m is an integer greater than 1; an output configured to output the output image, The output image includes m n output sub-images, each of the m n output sub-images corresponding to one image category; a classification unit configured to acquire pixels of each of the m n output sub-images in the output image And determining, according to the pixel value, at least one of
- an image processor comprising: an image encoding device, the image encoding device comprising: an encoding input configured to receive an input image; a cascaded n-level encoding unit configured to be paired The input image is image-encoded to generate an output image, n is an integer greater than 1, and for 1 ⁇ i ⁇ n, the input of the ith-level coding unit is an ith-level encoded input image and includes mi-1 image components, The output of the i-th coding unit is an i-th coded output image and includes m i image components, and the output of the i-th coding unit is an input of an i+1th coding unit, where m is an integer greater than one; The output end is configured to output the output image, the output image includes m n output sub-images, each of the m n output sub-images corresponding to one image category; image decoding device, the image decoding device comprising: decoding an input terminal configured
- a training method for an image processor comprising: inputting a training image to the image processor, adjusting the n-level coding unit and the n-level
- the weights of the convolutional networks in each convolutional layer in the decoding unit are run a finite number of iterations to optimize the objective function.
- a computer readable medium having stored thereon instructions, when executed by a processor, causes a computer to perform the steps of: receiving an input image; utilizing a cascade of n-level coding unit pairs
- the input image is image-encoded to generate an output image, n is an integer greater than 1, and for 1 ⁇ i ⁇ n, the input of the ith-level coding unit is an ith-level encoded input image and includes mi-1 image components,
- the output of the i-th coding unit is an i-th coded output image and includes m i image components, and the output of the i-th coding unit is an input of the i+1th coding unit, where m is an integer greater than one;
- the output image, the output image comprising output m n sub-images, the m n output sub-images each corresponding to an image category; obtaining m n outputs each of said sub-images output image pixel value and the pixel value determining at least one
- an image conversion method comprising: receiving a first input image and a second input image; image encoding the first input image by using a cascaded n-level encoding unit to generate a first An output image, n is an integer greater than 1, for 1 ⁇ i ⁇ n, the input of the i-th coding unit is an ith-level coded input image and includes m i-1 image components, and the output of the i-th coding unit is The i-th level encodes the output image and includes m i image components, and the output of the i-th coding unit is an input of the i+1th-order coding unit, where m is an integer greater than 1; and outputs a first output image, the An output image includes m n output sub-images; acquiring pixel values of each of the m n output sub-images in the first output image, and determining, according to the pixel values, at least one of the m n output sub-
- the image classifying apparatus can classify an input image with the advantages of development and performance of the latest depth learning, and extract pixel information of a corresponding category in the input image. Further, image category conversion can be performed on other images using pixel information corresponding to the category.
- 1 is a schematic diagram illustrating a convolutional neural network for image processing
- FIG. 2 is a schematic diagram illustrating a convolutional neural network for image processing
- FIG. 3 is a schematic diagram illustrating a wavelet transform for multi-resolution image transformation
- FIG. 4 is a schematic structural diagram of an image processor that implements wavelet transform using a convolutional neural network
- FIG. 5 shows a schematic diagram of an image classification device according to an embodiment of the present disclosure
- FIG. 6 illustrates a schematic diagram of a splitting unit in accordance with an embodiment of the present disclosure
- FIG. 7 illustrates a schematic diagram of a transform unit in accordance with an embodiment of the present disclosure
- FIG. 8 shows a schematic diagram of an image restoration apparatus according to an embodiment of the present disclosure
- FIG. 9 shows a schematic diagram of an inverse transform unit in accordance with an embodiment of the present disclosure.
- FIG. 10 shows a schematic diagram of a composite unit in accordance with an embodiment of the present disclosure
- Figure 11 schematically illustrates a process of transform coding and transform decoding an image
- FIG. 12 shows a flowchart of an image classification method according to an embodiment of the present disclosure
- FIG. 13 shows a flowchart of an image encoding process according to an embodiment of the present disclosure
- FIG. 14 illustrates a flowchart of an image transformation process in an i-th stage transform coding unit, according to an embodiment of the present disclosure
- 15A shows a flowchart of an image transformation process in an i-th stage transform coding unit, according to an embodiment of the present disclosure
- 15B shows a flowchart of an image transformation process in an i-th stage transform coding unit, according to an embodiment of the present disclosure
- FIG. 16 shows a flowchart of a wavelet transform based on an updated image, in accordance with an embodiment of the present disclosure
- FIG. 17 shows a flowchart of a differential image based wavelet transform, in accordance with an embodiment of the present disclosure
- FIG. 18 shows a flowchart of an image restoration method according to an embodiment of the present disclosure
- FIG. 19 illustrates a flowchart of an image decoding method of an i-th stage transform decoding unit according to an embodiment of the present disclosure
- FIG. 20 illustrates a flowchart of an image inverse transform method according to an embodiment of the present disclosure
- 21A shows a flowchart of an image decoding method of an i-th stage transform decoding unit, according to an embodiment of the present disclosure
- 21B shows a flowchart of an image decoding method of an i-th stage transform decoding unit, according to an embodiment of the present disclosure
- FIG. 22 shows a flow chart of an inverse wavelet transform method based on a first decoded input component and a second decoded input component
- FIG. 23 A flowchart of an inverse wavelet transform method based on a third decoded input component and a fourth decoded input component is shown in FIG. 23;
- FIG. 24 shows a schematic diagram of an image processor in accordance with an embodiment of the present disclosure.
- a commonly used network structure in deep learning is a convolutional neural network.
- Convolutional neural networks are neural network structures that often use images as input and use convolution kernels to replace weights.
- FIG. Figure 1 shows a simplified schematic of a convolutional neural network.
- the convolutional neural network is used, for example, for image processing, using images as inputs and outputs, such as convolution kernels instead of weights.
- a convolutional neural network of a simple structure is shown in FIG. As shown in FIG. 1, the structure acquires 4 input images at the four input terminals on the left side, has 3 units (output image) in the hidden layer 102 at the center, and has 2 units in the output layer 103, resulting in 2 Output images.
- Each of the boxes corresponds to a convolution kernel (e.g., a 3x3 or 5x5 core), where k is a label indicating the input layer number, and i and j are labels indicating the input and output units, respectively.
- Bias Is the scalar added to the output of the convolution.
- the activation function usually corresponds to a rectifying linear unit (ReLU) or a sigmoid function or a hyperbolic tangent (Sigmoid) function. .
- the weights and offsets of the convolution kernel are fixed during operation of the system, obtained through a training process using a set of input/output sample images, and adjusted to suit some optimization criteria depending on the application.
- a typical configuration involves tens or hundreds of convolution kernels in each layer.
- FIG. 2 An example diagram equivalent to the activation result of the activation function in the convolutional neural network shown in Fig. 1 is shown in Fig. 2.
- a particular input which is only the second ReLU in the first layer (corresponding to the offset in Figure 2) The node pointed to) and the first ReLU in the second layer (corresponding to the offset in Figure 2) The output of the pointed node) is greater than zero.
- the input to the other ReLU is 0, so it can be omitted in Figure 2.
- the present disclosure describes a method for using a deep learning network for image classification, where image classification is reversible. For example, images including handwritten digits can be classified into 10 categories: 0, 1, ... 9.
- the system provided by the present disclosure can output multiple (eg, 10) small resolution images called "latent space", in which only one image will display a number that is correct corresponding to the input image. The number.
- the image of the potential space may be an image with a lower resolution relative to the input image.
- these low resolution outputs can be utilized and decoded to recover the original input image.
- One application is to combine potential spatial information to convert an image corresponding to one category to another. For example, one can convert a digital image to another number, or convert a man's image into a woman's image, or convert the dog to a cat while retaining all other features that are not related to the category.
- FIG. 3 is a schematic diagram illustrating a wavelet transform for multi-resolution image transformation.
- Wavelet transform is a multi-resolution image transform for image codec processing, and its applications include transform coding in the JPEG 2000 standard.
- image encoding processing wavelet transform is used to represent an original high resolution image with a smaller low resolution image (eg, a portion of the original image).
- the inverse wavelet transform is used to recover the original image using the low resolution image and the difference features required to restore the original image.
- Fig. 3 schematically shows a 3-level wavelet transform and an inverse transform.
- one of the smaller low resolution images is the reduced version A of the original image, while the other low resolution images represent the details (Dh, Dv, and Dd) needed to restore the original image.
- FIG. 4 is a schematic diagram showing the structure of an image processor that implements wavelet transform using a convolutional neural network.
- the Lifting Scheme is an effective implementation of wavelet transform and a flexible tool for constructing wavelets.
- Figure 4 schematically shows a standard structure for one-dimensional (1D) data.
- the left side of Fig. 4 is the encoder 41.
- the splitting unit 402 in the encoder 41 converts the input original image 401 into a low resolution image A and a detail D. More specifically, the encoder 41 uses the prediction filter p and the update filter u. For compression applications, it is desirable for detail D to be approximately zero, such that most of the information is contained in image A.
- the right side of FIG. 4 is the decoder 42.
- the parameters of the decoder 42 may be identical to the filters p and u from the encoder 41, but only the filters p and u are arranged oppositely. Due to the strict correspondence of the encoder 41 and the decoder 42, this configuration ensures that the decoded image 404 stitched out via the tiling unit 403 of the decoder 42 is identical to the original image 401. Further, the configuration shown in FIG. 4 is also not restrictive, and may alternatively be configured in the order in which the encoder and the decoder exchange the update filter u and the prediction filter p. In the present disclosure, the update filter u and the prediction filter p can be implemented using a convolutional neural network as shown in FIG.
- an image classification device an image restoration device, an image processor including an image classification device, an image restoration device, a corresponding image classification method, an image restoration method, and the like for configuring the above according to an embodiment of the present disclosure will be described in further detail with reference to the accompanying drawings.
- the training method of the image processor The training method of the image processor.
- FIG. 5 shows a schematic diagram of an image classification device in accordance with an embodiment of the present disclosure.
- the image classification device 500 includes a transform coding unit 510.
- the transform coding unit 510 may include an input terminal for receiving an encoded input image, and the input image may be an image including only a single channel (such as R, G, B, or grayscale, etc.), or may include any number of channels (such as R). , G, B, grayscale, etc.).
- the transform coding unit 510 may further include cascaded n-level coding units 510-1, 510-2, ... 510-n, n being an integer greater than or equal to 1, for 1 ⁇ i ⁇ n, input of the i-th coding unit Inputting an image for the i-th stage, which includes m i-1 image components, the output of the i-th coding unit is an i-th coded output image and includes m i image components, and the output of the i-th coding unit is The input of the i+1 level coding unit, where m is an integer greater than one.
- each of the cascaded n-level coding units can include a split unit 512 and a transform unit 514. That is, the i-th coding unit 510-i includes a split unit 512-i and a transform unit 514-i.
- the splitting unit 512-i is configured to perform a split operation on each of the mi-1 image components received by the i- th encoding unit, and split each image component in the i-th encoded input image into m
- the image component that is, the m i-1 image components in the i- th coded input image is split into m i image components.
- the transform unit 514-i is configured to transform the m i image components obtained by the i-th coding unit.
- the transform coding unit 510 may further include an output for outputting the encoded output image, wherein the encoded output image includes m n output image components corresponding to the encoded input image, ie, m n output sub-images, and m n output sub-images Each of them corresponds to an image category.
- the image classification device 500 may further include a classification unit 520 configured to acquire pixel values of each of the m n output sub-images in the encoded output image, and determine, according to the pixel values, at least one of the m n output sub-images is an input image
- the category sub-image, and the category determining the input image are image categories corresponding to the category sub-image.
- the pixel value referred to herein may be the sum of the pixel values of all the pixels in the image.
- the sum of the pixel values in the image may also be simply referred to as the pixel value of the image.
- the classification unit 520 may be configured to compare the pixel values of each of the m n output sub-images with a first threshold, determine an output sub-image having a pixel value greater than the first threshold as a category sub-image, and output a corresponding A category label for a category sub-image, wherein the category sub-image includes pixel information corresponding to the category label in the input image.
- the above-described transform coding unit is capable of splitting an input image and image transform, and extracts a plurality of image components in the image as an output.
- Each image component output corresponds to a category of image classification.
- the category of the input image can be determined based on the pixel values of the plurality of image components output by the image classification device.
- at least one of the plurality of output sub-images in the output image has a pixel value that is not zero, and the pixel values of the other output sub-images are close to zero. Then, the output sub-image in which the above pixel value is not zero can be considered to represent the category of the input image.
- the output image includes 4 output sub-images C 0 (REF), C 1 , C 2 , C 3 , if the pixel value of C 1 is not zero, and the pixel values of C 0 , C 2 , C 3 are close to zero, then the input image is determined as the category type C 1.
- the image features represented by the specific class C 1 are determined by the configuration of the image classifying device.
- the output sub-image output after the encoding transformation represents the category information of the input image and the pixel information corresponding to the category information.
- C 0 , C 1 , C 2 , C 3 may represent the numbers 0 , 1 , 2 , and 3 , respectively.
- the pixel value of C 0 in the four output sub-images outputted therefrom is not zero, and the pixel values of C 1 , C 2 , and C 3 are close to zero.
- the pixel information of C 0 may represent pixel information of the number 0 in the input image, such as the shape, size, position, and the like of the image of the numeral 0.
- the pixel information of C 0 may represent pixel information of the number 0 in the input image, such as the shape, size, position, and the like of the image of the numeral 0.
- the pixel information of C 2 may represent pixel information of the number 0 in the input image, such as the shape, size, position, etc. of the image of the number 2. For example, if there is an image of the number 0 in the upper left corner of the input image of the image classifying device and an image of the number 2 in the lower right corner, there is a number 0 corresponding to the input image included in the upper left corner of the output sub-image C 0 of the output image.
- the pixel information has pixel information corresponding to the number 0 included in the input image in the lower right corner of the output sub-image C 2 that is output.
- C 0 , C 1 , C 2 , and C 3 can represent men, women, cats, and dogs, respectively. Then, similarly, when a man and a dog are included in the input image, the pixel values of C 0 and C 3 in the outputted four output sub-images are not zero, and the pixel values of C 1 and C 2 are close to zero. Also, the pixel information of C 0 may represent pixel information of a man in the input image, and the pixel information of C 2 may represent pixel information of a dog in the input image.
- the trained image classification device can classify the input image and extract corresponding category information.
- the image classifying means outputs a plurality of output sub-images of the corresponding categories, and the output sub-images include pixel information corresponding to the category in the input image.
- the pixel information corresponding to the image category extracted through the above classification process can be further used for image conversion.
- the process of image conversion will be further described below with reference to FIGS. 8-10.
- a splitting unit 512 capable of splitting an image into four smaller images with lower resolution is exemplarily shown in FIG.
- the splitting unit T-MUXOUT may divide the original image into units of a 2 ⁇ 2 basic pixel matrix, wherein each basic pixel matrix includes 4 original pixels.
- the splitting unit 512 further extracts pixels of a specific position in all of the divided 2 ⁇ 2 basic pixel matrices, and determines the split image based on pixels of a specific position in each of the basic pixel matrices. For example, as shown in FIG.
- the input image of the splitting unit 512 includes 16 original pixels, and the splitting unit 512 divides the input image into basic pixel matrices A 11 , A 12 , A 21 , A 22 , where the basic pixels
- the matrix A 11 includes pixels a 11 , b 11 , c 11 , d 11
- the basic pixel matrix A 12 includes pixels a 12 , b 12 , c 12 , d 12
- the basic pixel matrix A 21 includes pixels a 21 , b . 21 , c 21 , d 21
- the basic pixel matrix A 22 includes pixels a 22 , b 22 , c 22 , d 22 .
- the splitting unit 512 can extract the original pixels in the upper left corner (ie, at the [1, 1] position) of all the basic pixel matrices, as shown in FIG. 5, the pixels a 11 , a 12 , a 21 , a 22 , and The extracted pixels are arranged in the order in which the pixels are arranged in the image before the splitting to generate the first split low resolution image. Further, the splitting unit 512 may extract the original pixels at the [1, 2] position in all the basic pixel matrices, such as the pixels b 11 , b 12 , b 21 , b 22 shown in FIG. 5 , and extract the extracted pixels. The pixels are arranged in the order in which the pixels are arranged in the image before the splitting to generate a second split low resolution image. Similarly, the split unit can generate the remaining split low resolution small images.
- the splitting unit shown in FIG. 6 can split an image of any size into four smaller images with lower resolution.
- the plurality of split low resolution images are equal in size.
- the splitting unit 512 as shown in Fig. 6 can split an image having an original size of 128 x 128 into four low resolution images each having a size of 64 x 64.
- the split unit as shown in Figure 6 is but one example of a split unit in accordance with the principles of the present disclosure.
- the image can be split into smaller images with lower resolution by adjusting the size and shape of the divided basic pixel matrix.
- split unit 512 can split an image into any number of reduced images of lower resolution.
- FIG. 6 shows a schematic diagram of splitting two-dimensional image data by using a splitting unit.
- the splitting unit 512 can also split image data of other arbitrary dimensions (such as one-dimensional, three-dimensional, etc.).
- the splitting unit shown in FIG. 6 will be described below as an example, and the split four low-resolution images are referred to as upper left (UL), upper right (UR), and lower left (BL), respectively. ) and the bottom right (BR). That is to say, for the i-th coding unit, the input image includes 4 i-1 image components, and after the split unit 512-i in the i-th coding unit, the i-th encoded input image is split into 4 i image components.
- FIG. 7 illustrates a schematic diagram of a transform unit 514 in accordance with an embodiment of the present disclosure.
- the split unit can split the original image into four low resolution images UL, UR, BL and BR.
- the transform unit 514 can perform image transformation on the above four low-resolution images UL, UR, BL, and BR, thereby extracting image components in the input image.
- the transform unit 514 may include a first prediction unit 710 configured to generate a predicted image for the UR image and the BL image based on the UL image and the BR image and acquire a difference image between the UR image and the BL image and the predicted image; the first update The unit 720 is configured to generate an updated image for the UL image and the BR image based on the difference image between the UR image and the BL image and the predicted image; the first wavelet transform unit 730 is configured to perform based on the image for the UL image and the BR image Updating a wavelet transform of the image, and generating a first encoded output component and a second encoded output component based on a result of the wavelet transform; the second wavelet transform unit 740 configured to perform a difference image between the UR image and the BL image and the predicted image The wavelet transform generates a third encoded output component and a fourth encoded output component based on the result of the wavelet transform.
- the first prediction unit 710 may further comprise a first convolutional network prediction to P 1 and a first superimposing unit 712.
- the first prediction unit P 1 is configured to receive the UL image and the BR image as inputs, and generate first prediction features and second prediction features for the UR image and the BL image.
- the first predicted feature and the second predicted feature may be the same or different.
- the first de-overlay unit 712 is configured to perform a de-overlay operation on the UR image and the first prediction feature to obtain a first difference feature, and perform a de-overlay operation on the BL image and the second prediction feature to obtain a second difference feature.
- the first update unit 720 can further include a first update convolutional network U 1 and a first superimposition unit 722.
- a first convolutional network update U 1 is configured to receive the first and second difference difference characteristic features as input, and generates a first image and a UL BR updating feature image and a second update feature.
- the first update feature and the second update feature may be the same or different.
- the first superimposing unit 722 is configured to perform a superimposing operation on the UL image and the first updated feature to obtain a first superimposed feature, and perform a superimposing operation on the BR image and the second updated feature to obtain a second superimposed feature.
- the first wavelet transform unit 730 can further include a second predictive convolutional network P 21 configured to receive the first superimposed feature as an input and generate a third predictive feature for the second superimposed feature; to superimposing unit 732, configured to overlay a second characteristic feature of the third prediction to perform superimposition operation to obtain a second encoded output component; the second convolutional network update U 21, configured to receive a second encoded output component as an input, and Generating a third update feature for the first encoded output component; the second overlay unit 734 is configured to perform a superimposition operation on the first overlay feature and the third update feature to obtain a first encoded output component.
- a second predictive convolutional network P 21 configured to receive the first superimposed feature as an input and generate a third predictive feature for the second superimposed feature
- to superimposing unit 732 configured to overlay a second characteristic feature of the third prediction to perform superimposition operation to obtain a second encoded output component
- the second convolutional network update U 21, configured to receive a second encoded output component as an input, and
- the second wavelet transform unit 740 can further include a third predictive convolutional network P 22 configured to receive the first differential feature as an input and generate a fourth predicted feature for the second differential feature; to superimposing unit 742, configured to predict the second and the fourth characteristic feature difference to perform superimposition operation component to obtain a fourth coded output; third update convolutional network U 22, configured to receive a fourth input component as the encoded output, and Generating a fourth update feature for the first difference feature; a third overlay unit 644 configured to perform a superposition operation on the first difference feature and the fourth update feature to obtain a third coded output component.
- a third predictive convolutional network P 22 configured to receive the first differential feature as an input and generate a fourth predicted feature for the second differential feature
- to superimposing unit 742 configured to predict the second and the fourth characteristic feature difference to perform superimposition operation component to obtain a fourth coded output
- third update convolutional network U 22, configured to receive a fourth input component as the encoded output, and Generating a fourth update feature for the first
- the structure shown in Fig. 7 is not limitative.
- the structure of the first prediction unit 710 and the first update unit 720 can be swapped in the transform unit 514.
- the image processing apparatus shown in FIG. 7 can perform image conversion on the split low resolution image and extract image components in the input image.
- the image information is not lost in the image transformation, and the image information can be restored without loss by the corresponding inverse transformation.
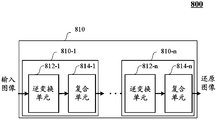
- FIG. 8 shows a schematic diagram of an image restoration apparatus according to an embodiment of the present disclosure.
- the image restoration device 800 may include a transform decoding unit 810.
- the transform decoding unit 810 illustrated in FIG. 8 corresponds to the transform coding unit illustrated in FIG. 5, and is capable of losslessly restoring image data transformed by the transform coding unit 510 into original data.
- Transform decoding unit 810 may include an input for receiving an input image is decoded, the decoded input image includes image components n-m, where m is an integer greater than 1, n is an integer greater than or equal to 1.
- Each of the m n image components may include a plurality of channels (eg, three channels of RGB).
- the transform decoding unit 810 may further include cascaded n-level decoding units 810-1, 810-2, ... 810-n, for 1 ⁇ i ⁇ n, the input of the ith-th decoding unit is the ith-level decoded input image and includes m i image components, the output of the i-th decoding unit is the i-th decoding output image and includes m i-1 image components, and the output of the i-th decoding unit is an input of the i+1th-level decoding unit.
- each of the cascaded n-level decoding units can include an inverse transform unit 812 and a composite unit 814. That is, the i-th stage decoding unit 810-i includes an inverse transform unit 812-i and a composite unit 814-i.
- the inverse transform unit is configured to perform inverse transform on the m i image components of the input of the i-th decoding unit, thereby losslessly restoring the restored image corresponding to the m i image components included in the decoded input image.
- the combining unit 814 is configured to perform a combining operation on the m i inverse transformed transform output components, thereby combining the m i image components into m i-1 image components.
- the transform decoding unit 810 may further include an output configured to output a restored image corresponding to the m n image components in the decoded input image.
- FIG. 9 shows a schematic diagram of an inverse transform unit 812 in accordance with an embodiment of the present disclosure.
- the i-th decoding input image includes a first decoding input component, a second decoding input component, a third decoding input component, and a fourth decoding input component, wherein each decoding input component includes 4 i-1 images ingredient.
- the inverse transform unit 812 may include a first inverse wavelet transform unit 930 configured to perform an inverse wavelet transform based on the first decoded input component and the second decoded input component, and obtain a first differential feature and a first overlay based on a result of the inverse wavelet transform a second inverse wavelet transform unit 940 configured to perform an inverse wavelet transform based on the third decoded input component and the fourth decoded input component, and obtain a second differential feature and a second overlay feature based on a result of the inverse wavelet transform;
- the updating unit 920 is configured to generate an update image based on the second difference feature and the second overlay feature, and generate a first decoded output component and a second decoded output component based on the updated image, the first differential feature, and the first overlay feature;
- the prediction unit 910 is configured to generate a predicted image based on the first decoded output component and the second decoded output component, and generate a third decoded output component and a fourth decoded
- the second updating unit 920 further comprises a first updating convolutional network U '1 and to a first superimposing unit 922.
- a first convolutional network update U '1 configured to receive the second difference and the second superposition characteristic features as input, and generates a first update feature and the second feature on the second difference and the second superposition characteristic feature updates.
- the first update feature and the second update feature may be the same or different.
- the first de-overlay unit 922 is configured to perform a de-overlay operation on the first difference feature and the first update feature to obtain a first decoded output component, and perform a de-overlay operation on the first overlay feature and the second update feature to obtain a second decoding Output component.
- the second prediction unit 910 further includes a first predicted convolutional network P' 1 and a first superimposed unit 912.
- the first predictive convolutional network P' 1 is configured to receive the first decoded output component and the second decoded output component as inputs, and to generate first and second predicted features for the first decoded output component and the second decoded output component .
- the first predicted feature and the second predicted feature may be the same or different.
- the first superimposing unit 912 is configured to perform a superimposing operation on the second difference feature and the first prediction feature to obtain a third decoded output component, and perform a superimposition operation on the second superimposed feature and the second predicted feature to obtain a fourth decoded output component.
- the first inverse wavelet transform unit 930 can further include a second update convolutional network U' 21 configured to receive the second decoded input component as an input and generate a third update feature with respect to the second decoded input component a second de-overlapping unit 934 configured to perform a de-superimposing operation on the first decoding input component and the third update feature to obtain a first difference feature; the second predictive convolution network P' 21 configured to receive the first difference feature as Inputting and generating a third prediction feature with respect to the first difference feature; a second superimposing unit 932 configured to perform a superposition operation on the second decoded input component and the third predicted feature to obtain the first superimposed feature.
- a second update convolutional network U' 21 configured to receive the second decoded input component as an input and generate a third update feature with respect to the second decoded input component
- a second de-overlapping unit 934 configured to perform a de-superimposing operation on the first decoding input component and the third update feature to obtain a first difference feature
- the second inverse wavelet transform 940 may further include a third update convolutional network U '22, configured to receive a fourth input component decoder as an input, and generates a fourth image decoding update feature on the fourth input; a third de-superimposing unit 942 configured to perform a de-superimposing operation on the third decoding input component and the fourth update feature to obtain a second difference feature; the third predictive convolution network P' 22 configured to receive the second difference feature as an input And generating a fourth prediction feature regarding the second difference feature; the third superimposing unit 944 is configured to perform a superposition operation on the fourth decoding input component and the fourth prediction feature to obtain the second superimposed feature.
- a third update convolutional network U '22 configured to receive a fourth input component decoder as an input, and generates a fourth image decoding update feature on the fourth input
- a third de-superimposing unit 942 configured to perform a de-superimposing operation on the third decoding input component and the fourth update feature to obtain a second difference feature
- the convolutional network in the inverse transform unit 812 corresponds exactly to the convolutional network in the transform unit 514. That is, the first predictive convolutional network P' 1 , the first updated convolutional network U' 1 , the second updated convolutional network U' 21 , and the second predicted convolutional network P' 21 in the inverse transform unit 812, third update convolutional network U '22, the third prediction convolutional network P' 22 and the conversion unit 514 in the first predicted convolutional network P 1, a first update convolutional network U 1, U second update convolutional network 21.
- the second predictive convolutional network P 21 , the third updated convolutional network U 22 , and the third predictive convolutional network P 22 have the same structure and configuration parameters.
- the structure shown in Figure 9 is non-limiting.
- the structure of the second prediction unit 910 and the second update unit 920 may be swapped in the inverse transform unit 812.
- FIG. 10 shows a schematic diagram of a composite unit in accordance with an embodiment of the present disclosure.
- the composite unit can combine multiple small images of low resolution into a composite image with higher resolution.
- the composite unit is configured to perform an inverse transformation of the split unit as previously described to restore the split low resolution small image to a high resolution original image.
- the image restoration device outputs the restored input image.
- the input image is processed by the image classification device to obtain output sub-images C 0 (REF), C 1 , C 2 , C 3 , if the output sub-images C 0 (REF), C 1 , C 2 , C 3 are corresponding.
- the input unit of the inverse transform unit is input, and the composite unit MUXOUT extracts the corresponding pixel points in the output sub-image, and sequentially arranges the extracted pixels to generate a restored image.
- the image restoration device outputs the same restored image as the input image.
- the image restoration means if the output sub-image output by the image classifying means is changed and the changed plurality of output sub-images are input to the image restoration means, the image restoration means outputs a restoration means different from the input image.
- C 0 , C 2 in the output sub-image obtained by the processing of the image classification device will include the number 0 in the upper left corner and the number in the lower right corner. 2 pixel information.
- the image restoration device outputs an image obtained by swapping the numbers 0 and 2 in the input image.
- the restored image outputted by the image restoration device is an image in which the number 0 in the original input image is replaced with the number 5.
- Fig. 11 schematically shows a process of transform coding and transform decoding an image.
- An input image is received at an input of the transform coding unit.
- the input image may include any number of channels, for example, RGB three channels.
- the input image is split into four sub-images having lower resolution via the splitting unit.
- the input image can be split into any number of sub-images.
- the split sub-image is subjected to image transformation by a transform unit to obtain an image component.
- each arrow of the first-stage transform coding unit shown in FIG. 11 can process data of a plurality of channels.
- each arrow in the level 1 transform coding unit indicates that there are 3 channels of data in the input or output.
- each channel of the input image is transformed into four image components.
- the image can be processed using a multi-level transform coding unit.
- n image components can be obtained, wherein one or more image components contain category information of the input image, and the rest are images containing other detail information. ingredient.
- the pixel information of the remaining image components is close to zero compared to the category information. That is to say, through the image transformation method provided by the embodiment of the present disclosure, the pixel information of the image component obtained by the transformation can determine the category of the input image and the pixel information in the input image corresponding to the category.
- each stage of the transform coding unit can have more channels than the previous-stage transform coding unit.
- each arrow in the first-stage transform coding unit indicates that the input/output includes data of 3 channels
- each arrow in the second-stage transform coding unit indicates input/output.
- the data including 12 channels, and so on, each arrow in the nth-stage transform coding unit indicates that the input/output includes data of 3*4 n-1 channels.
- the image transform encoding process as described above is reversible, and corresponding to the n-th transform coding unit, the n-level transform decoding unit using the same configuration can restore the input image without losing image information.
- Each level of transform decoding unit is configured to inverse transform the input plurality of image components, and perform a composite operation on the transformed image components to restore the image components to higher resolution image components.
- a plurality of image components can be restored to the original input image. I will not repeat them here.
- FIG. 12 shows a flow chart of an image classification method in accordance with an embodiment of the present disclosure.
- the image classification method 1200 can be performed using the image classification device as shown in FIG.
- step S1202 an input image is received.
- step S1204 the input image is image-encoded by using the cascaded n-level coding unit to generate an output image, where n is an integer greater than or equal to 1, and for 1 ⁇ i ⁇ n, the input of the i-th coding unit is The i-level encodes the input image and includes m i-1 image components, the output of the i-th coding unit is the i-th coded output image and includes m i image components, and the output of the i-th coding unit is the i+1th The input of the level coding unit, where m is an integer greater than one.
- step S1206 the output of the output image, the output image comprises sub-images output n m, n m output of the sub-picture respectively correspond to m n n-th stage output of the image coding section, and the Each of the m n output sub-images corresponds to one image category.
- step S1208 the acquired n output values of the output image in the sub-pixel image of each of m, n m is determined according to the pixel values of the sub-output image is a sub-category of the input image.
- step S1208 includes comparing pixel values of each of the m n output sub-images with a first threshold, determining an output sub-image having a pixel value greater than a first threshold as a category sub-image, and outputting corresponding to a category tag of the category sub-image, wherein the category sub-image includes pixel information in the input image corresponding to the category tag.
- step S1210 it is determined that the category of the input image is an image category corresponding to the category sub-image.
- the image classification method described above is capable of classifying an input image, determining a category of the input image, and simultaneously outputting pixel information corresponding to an image category of the input image.
- FIG. 13 shows a flowchart of an image encoding process of an i-th transform coding unit according to an embodiment of the present disclosure.
- the image encoding process 1300 can be performed using the transform encoding unit 510-i as shown in FIG.
- the i-th encoded input image is received.
- the image component is split into m coded input components.
- m coded input components split from the image component are subjected to image conversion to generate m coded output components corresponding to the image component.
- mi coding output components corresponding to the m i-1 image components of the i- th code input are output as the i-th code output image.
- the image transformation process 1400 can be performed using the transform unit 514 as shown in FIG. 5 or 7.
- each image component in the i-th encoded input image is split into a first encoded input component, a second encoded input component, a third encoded input component, and a fourth encoded input component. Therefore, in step S1402, the transform unit 514 receives the first encoded input component, the second encoded input component, the third encoded input component, and the fourth encoded input component. In step S1404, a predicted image is generated based on the first encoded input component and the second encoded input component and a difference image of the third encoded input component and the fourth encoded input component and the predicted image is acquired.
- step S1404 may further comprise: in step S1502, by using the first component and the second encoded input encoding a first component as the input prediction input P 1 of a convolutional network generating a first prediction Features and second predictive features.
- the first predicted feature and the second predicted feature may be the same or different.
- step S1504 a de-superimposing operation is performed on the third encoded input component and the first predicted feature to obtain a first differential feature.
- step S1506 a de-superimposing operation is performed on the fourth encoded input component and the second predicted feature to obtain a second differential feature.
- step S1406 an updated image of the first encoded input component and the second encoded input component is generated based on the difference image, the first encoded input component, and the second encoded input component.
- step S1404 may further comprise: in step S1508, the first and second difference difference characteristic feature use as input to the first convolution of the network updated U 1 and generates a first update feature Second update feature.
- the first update feature and the second update feature may be the same or different.
- step S1510 a superimposition operation is performed on the first encoded input component and the first updated feature to obtain a first superimposed feature.
- step S1512 a superimposition operation is performed on the second encoded input component and the second updated feature to obtain a second superimposed feature.
- step S1408 wavelet transform based on the updated image is performed, and a first encoded output component and a second encoded output component are generated based on the result of the wavelet transform.
- step S1410 a differential image based wavelet transform is performed, and a third encoded output component and a fourth encoded output component are generated based on the result of the wavelet transform.
- FIG. 16 illustrates a flow chart of an image-based wavelet transform, in accordance with an embodiment of the present disclosure.
- the image-based wavelet transform 1600 can be implemented using the first wavelet transform unit 730 shown in FIG.
- a third predicted feature with respect to the first superimposed feature is generated using the second predictive convolutional network P 21 having the first superimposed feature as an input.
- a de-superimposing operation is performed on the second superimposed feature and the third predicted feature to obtain a second encoded output component.
- the output coded using the second component as a second input to update convolutional network update U 21 wherein generating a third coded output on a second component.
- a superimposing operation is performed on the first superimposed feature and the third updated feature to obtain a first encoded output component.
- FIG. 17 shows a flowchart of a differential image based wavelet transform, in accordance with an embodiment of the present disclosure.
- the difference image based wavelet transform 1700 can be implemented using the second wavelet transform unit 740 shown in FIG.
- a fourth predicted feature is generated using a third predictive convolutional network P 22 having the first differential feature as an input.
- a de-superimposing operation is performed on the second difference feature and the fourth prediction feature to obtain a fourth coded output component.
- a fourth update feature is generated using the third update convolutional network U 22 having the fourth encoded output component as an input.
- a superimposition operation is performed on the first difference feature and the fourth update feature to obtain a third coded output component.
- a plurality of image components in the input image may be extracted, and a category of the input image is determined based on the pixel values of the extracted plurality of image components.
- FIG. 18 shows a flow chart of an image restoration method according to an embodiment of the present disclosure.
- the image restoration method 1800 can be performed using the image restoration device as shown in FIG.
- an input image is received, the input image including m n image components.
- the input image is image decoded by the cascaded n-level decoding unit to generate a restored image.
- the input of the i-th decoding unit is the i-th decoding input image and includes m i
- the image component, the output of the i-th decoding unit is the i-th decoding output image and includes m i-1 image components, and the output of the i-th decoding unit is an input of the i+1th-level decoding unit.
- a restored image corresponding to the input image is output.
- the image restoration method 1800 corresponds to the image classification method 1200. That is to say, for example, when the image classification method 1200 includes n-level coding units, the image restoration method 1800 also includes n-level decoding units accordingly.
- FIG. 19 illustrates a flowchart of an image decoding method of an i-th stage transform decoding unit, according to an embodiment of the present disclosure.
- the image decoding method 1900 can be performed using the transform decoding unit 810 as shown in FIG.
- step S1902 an i-th stage decoded input image is received, wherein the i-th stage input image includes m i input sub-images.
- step S1904 the m i image components are inversely transformed, and m i decoded output components corresponding to the i-th decoded input image are generated.
- the m i decoded output components are combined into m i-1 decoded output sub-images.
- step S1908 m i-1 decoded output sub-images corresponding to the m i image components of the i- th stage decoded input image are output as the i-th decoded output image.
- the image inverse transform method 2000 can be performed using the inverse transform unit 812 as shown in FIG. 8 or 9.
- the inverse transform unit 812 receives the first decoded input component, the second decoded input component, the third decoded input component, and the fourth decoded input component.
- step S2004 an inverse wavelet transform based on the first decoded input component and the second decoded input component is performed, and the first differential feature and the first superimposed feature are obtained based on the result of the inverse wavelet transform.
- an inverse wavelet transform based on the third decoded input component and the fourth decoded input component is performed, and the second differential feature and the second superimposed feature are obtained based on the result of the inverse wavelet transform.
- step S2008 an update image is generated based on the second difference feature and the second overlay feature, and the first decoded output component and the second decoded output component are generated based on the updated image, the first difference feature, and the first overlay feature.
- step S2008 shown in FIG. 21A may further comprise: in step S2102, the second difference using the features as inputs and a second overlay network convolutional first update U '1 to generate a first feature and the second update Update features.
- the first update feature and the second update feature may be the same or different.
- step S2104 a de-overlay operation is performed on the first difference feature and the first update feature to obtain a first decoded output component.
- step S2106 a de-superimposing operation is performed on the first superimposed feature and the second updated feature to obtain a second decoded output component.
- step S2010 a predicted image is generated based on the first decoded output component and the second decoded output component, and a third decoded output component and a fourth decoded output component are generated based on the predicted image, the second differential feature, and the second superimposed feature.
- step S2010 shown in FIG. 21B may further comprise: in step S2108, a first decoded output and the second decoded output component as a first component using a convolutional network input prediction P '1 generates a first prediction feature And a second predictive feature.
- the first predicted feature and the second predicted feature may be the same or different.
- step S2110 a superposition operation is performed on the second difference feature and the first prediction feature to obtain a third decoded output component.
- step S2106 a superimposing operation is performed on the second superimposed feature and the second predicted feature to obtain a fourth decoded output component.
- FIG. 22 shows a flow chart of an inverse wavelet transform method based on a first decoded input component and a second decoded input component.
- the inverse wavelet transform method 2200 can be performed using the inverse wavelet transform unit 930 as shown in FIG.
- step S2202 using a second decoder input component as a second input to update convolutional network U '21 generates a third update feature.
- step S2204 a de-overlay operation is performed on the first decoded input component and the third updated feature to obtain a first differential feature.
- step S2206 using a feature as an input the first difference a second convolutional network prediction P '21 generates a third prediction feature.
- a superimposition operation is performed on the second decoded input component and the third predicted feature to obtain a first superimposed feature.
- a flowchart of an inverse wavelet transform method based on the third decoded input component and the fourth decoded input component is shown in FIG.
- the inverse wavelet transform method 2300 can be performed using the inverse wavelet transform unit 940 as shown in FIG.
- step S2302 using a fourth input component decoder as the input of the third update convolutional network U '22 generate a fourth update feature.
- step S2304 a de-overlay operation is performed on the third decoded input component and the fourth updated feature to obtain a second differential feature.
- the second difference using the third prediction characterized as a convolution of the input network P '22 generate a fourth prediction feature.
- a superimposition operation is performed on the fourth decoding input component and the fourth prediction feature to obtain a second superimposed feature.
- FIG. 24 shows a schematic diagram of an image processor in accordance with an embodiment of the present disclosure.
- the first half of the image processor 2400 may be a transform coding unit in the image classification device as shown in FIG. 5 for extracting a plurality of image components from the input image.
- the second half of the image processor 2400 may be an image restoration device as shown in FIG. 8 for restoring image components.
- the image processor 2400 can be used to implement the classification and restoration process of the image.
- the specific structure of the image classification device and the restoration device has been described in detail above, and will not be described herein.
- the configuration of the parameters of the respective convolutional networks in the image processor 2400 can be implemented using the deep learning method.
- the training image is input to the image processor, and the weights of the convolutional networks in the convolutional layers in the n-level coding unit and the n-level decoding unit are adjusted, and a finite number of iterations are run to optimize the objective function.
- a training image is input for each level of coding unit and decoding unit.
- an original high resolution image HR image is input at the input of the image processor.
- the objective function may include a sum of one or any of encoding loss, decoding loss, style loss, and weight regularization coefficients in the image processor. The calculation method of the above loss function will be described below.
- the coding loss between the reference image REF 1 output by the first-stage coding unit and the training image LR 1 of the first-stage coding unit is calculated.
- the above coding loss can be calculated by the coding loss function L ENCk shown in equation (1):
- REF k is the first image component of the kth order coding unit
- LR k is the training image of the kth coding unit, where LR k is the downsampled image of the training image of the image processor and has REF k The same size
- C 0 is the number of the training images
- C ki is the image component output by the k-th coding unit, where 1 ⁇ i ⁇ m k -1.
- the IQ function evaluates the difference between REF k and LR k .
- the IQ function can be an MSE function:
- MSE(X,Y)
- the IQ function can be a SSIM function:
- X and Y represent image data of REF k and LR k , respectively.
- the style loss function of this level can be calculated from the output of the i-th coding unit and the input of the decoding unit of the corresponding stage.
- the style loss function of the first stage can be calculated from the output of the first level coding unit and the input of the nth stage decoding unit.
- the second-order style loss function can be calculated based on the output of the second-stage coding unit and the input of the n-1th, that is, the decoding unit.
- the style loss function can be defined by equation (3):
- G X and G Y are the feature quantities of the Gram matrix of the X image and the Y image, respectively, X is the output image of the kth coding unit, and Y is the output image of the i+1th kth coding unit, where 1 ⁇ k ⁇ n.
- system's weight regularization coefficient can be defined by equation (4):
- W is the weighting parameter for all convolutional networks in the image processor and b is the offset of all convolutional networks in the image processor.
- the total loss function of the image processor can be calculated based on one or more of the above loss functions.
- the total loss function of the image processor can be applied to any deep learning optimization strategy, such as stochastic gradient descent SGD or variants thereof (such as momentum SGD, Adam, RMSProp, etc.).
- the convolutional neural network in the image processor can be parameter configured by using a deep learning strategy.
- the parameters of the convolutional neural network in the image processor are adjusted to optimize the objective function, thereby achieving better image classification.
Landscapes
- Engineering & Computer Science (AREA)
- Theoretical Computer Science (AREA)
- Physics & Mathematics (AREA)
- Evolutionary Computation (AREA)
- Artificial Intelligence (AREA)
- General Physics & Mathematics (AREA)
- Data Mining & Analysis (AREA)
- Health & Medical Sciences (AREA)
- Multimedia (AREA)
- Computing Systems (AREA)
- General Health & Medical Sciences (AREA)
- Software Systems (AREA)
- Life Sciences & Earth Sciences (AREA)
- General Engineering & Computer Science (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Biophysics (AREA)
- Biomedical Technology (AREA)
- Molecular Biology (AREA)
- Computational Linguistics (AREA)
- Mathematical Physics (AREA)
- Medical Informatics (AREA)
- Databases & Information Systems (AREA)
- Signal Processing (AREA)
- Evolutionary Biology (AREA)
- Bioinformatics & Computational Biology (AREA)
- Bioinformatics & Cheminformatics (AREA)
- Neurology (AREA)
- Compression Or Coding Systems Of Tv Signals (AREA)
Abstract
公开了一种图像分类和转换方法、装置、图像处理器及其训练方法和介质。所述图像分类方法包括:接收输入图像;利用级联的n级编码单元对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括mi-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括mi个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出所述输出图像,所述输出图像包括mn个输出子图像,所述mn个输出子图像分别对应于第n级编码单元的mn个输出图像成分,并且所述mn个输出子图像的每一个对应于一种图像类别。
Description
相关申请的交叉引用
本申请要求于2017年11月09日递交的中国专利申请第201711100238.1号的优先权,在此以引用的方式并入上述中国专利申请公开的内容以作为本公开的一部分。
本公开涉及图像处理领域,具体涉及一种图像分类方法、图像分类装置、图像转换方法、包括图像分类装置和图像还原装置的图像处理器及其训练方法和介质。
基于现有的图像分类方法,可以对输入图像进行分析并输出用于该输入图像的标签,该标签代表了输入图像的图像类别。然而,根据现有的图像分类方法可以得到图像类别的信息,但不能获得输入图像中对应于其类别的图像像素信息。
发明内容
针对以上问题,本公开提供一种新的用于图像分类和转换的方法、装置、图像处理器及其训练方法和介质。
根据本公开的一方面,提出了一种图像分类方法,包括:接收输入图像;利用级联的n级编码单元对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出所述输出图像,所述输出图像包括m
n个输出子图像,所述m
n个输出子图像的每一个对应于一种图像类别;获取所述输出图像中m
n个输出子图像的每一个的像素值,并根据像素值确定所述m
n个输出 子图像中的至少一个是所述输入图像的类别子图像,以及确定所述输入图像的类别为对应于所述类别子图像的图像类别。
根据本公开的另一方面,提出了一种图像分类装置,包括:输入端,配置成接收输入图像;级联的n级编码单元,配置成对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出端,配置成输出所述输出图像,所述输出图像包括m
n个输出子图像,所述m
n个输出子图像的每一个对应于一种图像类别;分类单元,配置成获取所述输出图像中m
n个输出子图像的每一个的像素值,并根据像素值确定所述m
n个输出子图像中的至少一个是所述输入图像的类别子图像,并确定所述输入图像的类别为对应于所述类别子图像的图像类别。
根据本公开的另一方面,提出了一种图像处理器,包括:图像编码装置,所述图像编码装置包括:编码输入端,配置成接收输入图像;级联的n级编码单元,配置成对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;编码输出端,配置成输出所述输出图像,所述输出图像包括m
n个输出子图像,所述m
n个输出子图像的每一个对应于一种图像类别;图像解码装置,所述图像解码装置包括:解码输入端,配置成所述输入图像的图像成分,所述输入图像的图像成分包括m
n个图像成分,其中m是大于1的整数,n是大于1的整数;级联的n级解码单元,配置成对所述解码输入图像进行图像解码以产生还原图像,n为大于1的整数,对于1≤i<n,第i级解码单元的输入为第i级解码输入图像并包括m
i个图像成分,第i级解码单元的输出为第i级解码输出图像并包括m
i-1个图像成分,以及第i级解码单元的输出是第i+1级解码单元的输入;解码输出端,配置成输出对应于所述解码输入图像的还原图像。
根据本公开的另一方面,提出了一种用于如前所述的图像处理器的训练方法,包括:将训练图像输入所述图像处理器,调整所述n级编码单元和所述n级解码单元中各卷积层中各卷积网络的权值,运行有限次迭代以使目标函数最优化。
根据本公开的另一方面,提出了一种计算机可读介质,其上存储有指令,当处理器执行所述指令时使得计算机执行以下步骤:接收输入图像;利用级联的n级编码单元对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出所述输出图像,所述输出图像包括m
n个输出子图像,所述m
n个输出子图像的每一个对应于一种图像类别;获取所述输出图像中m
n个输出子图像的每一个的像素值,并根据像素值确定所述m
n个输出子图像中的至少一个是所述输入图像的类别子图像,以及确定所述输入图像的类别为对应于所述类别子图像的图像类别。
根据本公开的另一方面,提出了一种图像转换方法,包括:接收第一输入图像和第二输入图像;利用级联的n级编码单元对所述第一输入图像进行图像编码以产生第一输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出第一输出图像,所述第一输出图像包括m
n个输出子图像;获取所述第一输出图像中m
n个输出子图像的每一个的像素值,并根据像素值确定所述m
n个输出子图像中的至少一个是所述第一输入图像的类别子图像;确定所述第一输入图像的类别为对应于所述类别子图像的图像类别;获取所述类别子图像的像素信息;基于所述类别子图像的像素信息对所述第二输入图像进行图像变换,将所述第二输入图像变换为对应于所述第一输入图像的图像类别的第三图像。
本公开实施例中公开了使用卷积网络进行图像分类并获得图像中对应于该类别的像素信息的图像分类装置和图像分类方法的几种配置。根据本公开 的实施例的图像分类装置可以利用最新的深度学习的发展和表现的优点对输入图像进行分类,并提取输入图像中对应该类别的像素信息。更进一步地,可以使用对应该类别的像素信息对其他图像进行图像类别转换。
为了更清楚地说明本公开实施例的技术方案,下面将对实施例描述中所需要使用的附图作简单地介绍,显而易见地,下面描述中的附图仅仅是本公开的一些实施例,对于本领域普通技术人员而言,在没有做出创造性劳动的前提下,还可以根据这些附图获得其他的附图。以下附图并未刻意按实际尺寸等比例缩放绘制,重点在于示出本公开的主旨。
图1是图示用于图像处理的卷积神经网络的示意图;
图2是图示用于图像处理的卷积神经网络的示意图;
图3是图示用于多分辨率图像变换的小波变换的示意图;
图4是利用卷积神经网络实现小波变换的图像处理器的结构示意图;
图5示出了根据本公开的实施例的一种图像分类装置的示意图;
图6图示了根据本公开的实施例的一种拆分单元的示意图;
图7图示了根据本公开的实施例的一种变换单元的示意图;
图8示出了根据本公开实施例的一种图像还原装置的示意图;
图9示出了根据本公开的实施例的一种逆变换单元的示意图;
图10示出了根据本公开的实施例的一种复合单元的示意图;
图11示意性地示出了对图像进行变换编码和变换解码的过程;
图12示出了根据本公开的实施例的一种图像分类方法的流程图;
图13示出了根据本公开的实施例的图像编码过程的流程图;
图14示出了根据本公开的实施例的第i级变换编码单元中的图像变换过程的流程图;
图15A示出了根据本公开的实施例的第i级变换编码单元中的图像变换过程的流程图;
图15B示出了根据本公开的实施例的第i级变换编码单元中的图像变换过程的流程图;
图16示出了根据本公开的实施例的基于更新图像的小波变换的流程图;
图17示出了根据本公开的实施例的基于差别图像的小波变换的流程图;
图18示出了根据本公开的实施例的一种图像还原方法的流程图;
图19示出了根据本公开的实施例的第i级变换解码单元的图像解码方法的流程图;
图20示出了根据本公开的实施例的图像逆变换方法的流程图;
图21A示出了根据本公开的实施例的第i级变换解码单元的图像解码方法的流程图;
图21B示出了根据本公开的实施例的第i级变换解码单元的图像解码方法的流程图;
图22示出了基于第一解码输入成分和第二解码输入成分的逆小波变换方法的流程图;
图23中示出了基于第三解码输入成分和第四解码输入成分的逆小波变换方法的流程图;以及
图24示出了根据本公开的实施例的一种图像处理器的示意图。
为使本公开实施例的目的、技术方案和优点更加清楚,下面将结合本公开实施例的附图,对本公开实施例的技术方案进行清楚、完整地描述。显然,所描述的实施例是本公开的一部分实施例,而不是全部的实施例。基于所描述的本公开的实施例,本领域普通技术人员在无需创造性劳动的前提下所获得的所有其他实施例,都属于本公开保护的范围。
除非另外定义,本公开使用的技术术语或者科学术语应当为本公开所属领域内具有一般技能的人士所理解的通常意义。本公开中使用的“第一”、“第二”以及类似的词语并不表示任何顺序、数量或者重要性,而只是用来 区分不同的组成部分。同样,“包括”或者“包含”等类似的词语意指出现该词前面的元件或者物件涵盖出现在该词后面列举的元件或者物件及其等同,而不排除其他元件或者物件。“连接”或者“相连”等类似的词语并非限定于物理的或者机械的连接,而是可以包括电性连接或信号连接,不管是直接的还是间接的。
深度学习中一种常用的网络结构是卷积神经网络。卷积神经网络是经常使用图像作为输入并且使用卷积核来替换权重的神经网络结构。作为示例,一个简单的神经网络结构在图1中示出。图1示出了一种卷积神经网络的简单示意图。该卷积神经网络例如用于图像处理,使用图像作为输入和输出,例如卷积核替代权重。图1中示出了简单结构的卷积神经网络。如图1所示,该结构在左侧的四个输入端子处获取4个输入图像,在中心的隐藏层102具有3个单元(输出图像),并且在输出层103具有2个单元,产生2个输出图像。具有权重
 的每个框对应于卷积核(例如,3×3或5×5内核),其中k是指示输入层编号的标签,i和j分别是指示输入和输出单元的标签。偏置(bias)
 是添加到卷积的输出的标量。加入几个卷积和偏置的结果然后通过激活层的激活函数(Activation Function),激活函数通常对应于整流线性单元(rectifying linear unit,ReLU)或S形函数或双曲正切(Sigmoid)函数等。卷积核的权重和偏置在系统的操作期间是固定的,通过使用一组输入/输出示例图像的训练过程获得,并且被调整以适合取决于应用的一些优化准则。典型的配置涉及每层中的数十或数百个卷积核。
图2中示出了由于图1所示的卷积神经网络中的激活函数的激活结果而等效的示例图。其中假设某个特定的输入,其仅在第一层中的第二ReLU(对应于图2中偏置
 所指向的节点)和第二层中的第一ReLU(对应于图2中偏置
 所指向的节点)的输出大于0。对于该特定输入,到其他ReLU的输入是0,因此可以在图2中省略。
本公开介绍了一种将深度学习网络用于图像分类的方法,这里的图像分类是可逆的。例如,可以将包括手写数字的图像分类为10类:0、1……9。本公开提供的系统可以输出多个(例如10个)被称为“潜在空间”(latent space)的小分辨率的图像,在其中只有一个图像将显示数字,该数字是对应于输入图像的正确的数字。潜在空间的图像可以是相对于输入图像更低分辨率的图像。存在许多用于解决分类问题的系统,但是在本公开中,可以利用这些低分辨率的输出并对其进行解码以恢复原始的输入图像。在这种场景中人们可以操作分类的输出用于不同的目的。一种应用是组合潜在空间信息以将对应于一个类别的图像转换为另一个类别。例如,人们可以将一个数字的图像转换为另一个数字,或将一个男人的图像转换为一个女人的图像,或将狗转换为猫,同时保留与类别无关的其他所有特征。
图3是图示用于多分辨率图像变换的小波变换的示意图。小波变换是一种用于图像编解码处理的多分辨率图像变换,其应用包括JPEG 2000标准中的变换编码。在图像编码处理中,小波变换用于以更小的低分辨率图像(例如,原始图像的一部分图像)代表原始的高分辨率图像。在图像解码处理中,逆小波变换用于利用低分辨率图像以及恢复原始图像所需的差异特征,恢复得到原始图像。
图3示意性地示出了3级小波变换和逆变换。如图3所示,更小的低分辨率图像之一是原始图像的缩小版本A,而其他的低分辨率图像代表恢复原始图像所需的细节(Dh、Dv和Dd)。
图4是利用卷积神经网络实现小波变换的图像处理器的结构示意图。提升算法(Lifting Scheme)是小波变换的一种有效实施方式,并且是构造小波时的一种灵活的工具。图4示意性地示出了用于一维(1D)数据的标准结构。图4的左侧为编码器41。编码器41中的拆分单元402将输入的原始图像401变换为低分辨率图像A和细节D。更具体地,编码器41使用预测滤波器p和更新滤波器u。对于压缩应用,希望细节D约为0,使得大部分的信息包含在图像A中。图4的右侧为解码器42。解码器42的参数可以与来自编码器41的滤波器p和u完全相同,而仅仅是滤波器p和u相反地布置。由于编码器41和解码器42的严格对应,该配置确保了经由解码器42的拼接单元403拼接得到的解码图像404与原始图像401完全相同。此外,图4所示的结构也不是限制性的,可以替代地在编码器和解码器按照交换更新滤波器u和预测滤波器p的顺序进行配置。在本公开中,更新滤波器u和预测滤波器p可以使用如图1所示的卷积神经网络实现。
以下,将参照附图进一步详细描述根据本公开实施例的图像分类装置、图像还原装置、包括图像分类装置、图像还原装置的图像处理器、相应的图像分类方法、图像还原方法以及用于配置上述图像处理器的训练方法。
图5示出了根据本公开实施例的一种图像分类装置的示意图。图像分类装置500包括变换编码单元510。
变换编码单元510可以包括用于接收编码输入图像的输入端,输入图像可以是仅包括单通道(如R、G、B或灰度等)的图像,也可以是包括任意多个通道(如R、G、B和灰度等)的图像。
变换编码单元510还可以包括级联的n级编码单元510-1、510-2、……510-n,n为大于等于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像,其包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数。
在一些实施例中,级联的n级编码单元中的每一个可以包括拆分单元512和变换单元514。也就是说,第i级编码单元510-i中包括拆分单元512-i、变换单元514-i。拆分单元512-i用于对第i级编码单元接收的m
i-1个图像成分中的每一个执行拆分操作,将第i级编码输入图像中的每个图像成分拆分为m个图像成分,即将第i级编码输入图像中的m
i-1个图像成分拆分为m
i个图像成分。变换单元514-i用于对由第i级编码单元拆分得到的m
i个图像成分进行变换。
变换编码单元510还可以包括用于输出编码输出图像的输出端,其中编码输出图像包括对应于编码输入图像的m
n个输出图像成分,即m
n个输出子图像,并且m
n个输出子图像的每一个对应于一种图像类别。
图像分类装置500还可以包括分类单元520,配置成获取编码输出图像中m
n个输出子图像的每一个的像素值,并根据像素值确定m
n个输出子图像中的至少一个是输入图像的类别子图像,以及确定输入图像的类别为对应于所述类别子图像的图像类别。这里所说的像素值可以是图像中所有像素的像素值的和,在下文中,图像中各像素值的和也可以被简称为该图像的像素值。在一些实施例中,分类单元520可以配置成比较m
n个输出子图像中每一个的像素值与第一阈值,将像素值大于第一阈值的输出子图像确定为类别子图 像,并输出对应于类别子图像的类别标签,其中类别子图像包括输入图像中对应于类别标签的像素信息。
上述变换编码单元能够对输入图像拆分以及图像变换,并提取图像中的多个图像成分作为输出。输出的每一个图像成分对应于一种图像分类的类别。根据图像分类装置输出的多个图像成分的像素值可以确定输入图像的类别。在一些实施例中,经过上述图像分类装置的处理后,输出图像中的多个输出子图像中有至少一个输出子图像的像素值不为零,而其他输出子图像的像素值都接近于零,那么可以认为上述像素值不为零的输出子图像代表了输入图像的类别。例如,如果输出图像包括4个输出子图像C
0(REF)、C
1、C
2、C
3,如果其中C
1的像素值不为零,而C
0、C
2、C
3的像素值都接近于零,则将输入图像的类别确定为C
1类。具体C
1类代表的图像特征由图像分类装置的配置所决定。经过下文中将介绍的训练方法的配置后,经过编码变换后输出的输出子图像代表了输入图像的类别信息以及对应于类别信息的像素信息。
例如,C
0、C
1、C
2、C
3可以分别代表数字0、1、2、3。当图像分类装置的输入图像中包括数字0的图像时,其输出的4个输出子图像中C
0的像素值不为零,而C
1、C
2、C
3的像素值接近于零。并且,C
0的像素信息可以表示数字0在输入图像中的像素信息,如数字0的图像的形状、大小、位置等。例如,如果在输入图像的左上角存在数字0的图像,那么,在输出的输出子图像C
0的左上角存在对应于输入图像中包括的数字0的像素信息。当图像分类装置的输入图像中同时包括数字0和数字2的图像时,输出的4个输出子图像中C
0、C
2的像素值不为零,而C
1、C
3的像素值接近于零。并且,C
0的像素信息可以表示数字0在输入图像中的像素信息,如数字0的图像的形状、大小、位置等。C
2的像素信息可以表示数字0在输入图像中的像素信息,如数字2的图像的形状、大小、位置等。例如,如果在图像分类装置的输入图像的左上角存在数字0的图像,右下角存在数字2的图像,那么在输出的输出子图像C
0的左上角存在对应于输入图像中包括的数字0的像素信息,在输出的输出子图像C
2的右下角存在对应于输入图像中包括的数字0的像素信息。
又例如,C
0、C
1、C
2、C
3可以分别代表男人、女人、猫、狗。那么,类 似地,当输入图像中包括男人和狗时,输出的4个输出子图像中C
0、C
3的像素值不为零,而C
1、C
2的像素值接近于零。并且,C
0的像素信息可以表示输入图像中的男人的像素信息,C
2的像素信息可以表示输入图像中的狗的像素信息。
也就是说,经过训练的图像分类装置能够对输入图像进行分类并提取相应的类别信息。当输入图像中包含符合多个类别的图像信息时,图像分类装置将输出多个对应类别的输出子图像,输出子图像中包括对应于输入图像中该类别的像素信息。
经过上述分类过程提取的对应于图像类别的像素信息能够进一步用于图像转换。在下文中将参考图8-图10对图像转换的过程进行进一步的说明。
图6中示例性的示出了一种能够将一张图像拆分为4个分辨率更低的小图像的拆分单元512。如图6所示,拆分单元T-MUXOUT可以将原始图像以2×2的基本像素矩阵为单位进行划分,其中每个基本像素矩阵包括4个原始像素。拆分单元512进一步提取所有划分好的2×2的基本像素矩阵中的特定位置的像素,并根据每个基本像素矩阵中特定位置的像素确定拆分后的图像。例如,如图6中示出的,拆分单元512的输入图像包括16个原始像素,拆分单元512将输入图像划分为基本像素矩阵A
11、A
12、A
21、A
22,其中基本像素矩阵A
11中包括像素a
11、b
11、c
11、d
11,基本像素矩阵A
12中包括像素a
12、b
12、c
12、d
12,基本像素矩阵A
21中包括像素a
21、b
21、c
21、d
21,基本像素矩阵A
22中包括像素a
22、b
22、c
22、d
22。拆分单元512可以通过提取所有基本像素矩阵中左上角(即[1,1]位置处)的原始像素,如图5中示出的像素a
11、a
12、a
21、a
22,并将提取的像素按照拆分前各像素在图像中排列的顺序进行排列,以生成第一张拆分后的低分辨率图像。进一步地,拆分单元512可以通过提取所有基本像素矩阵中[1,2]位置处的原始像素,如图5中示出的像素b
11、b
12、b
21、b
22,并将提取的像素按照拆分前各像素在图像中排列的顺序进行排列,以生成第二张拆分后的低分辨率图像。类似地,拆分单元可以生成其余的拆分后的低分辨率小图像。
可以理解,如图6所示的拆分单元可以将任意大小的图像拆分为4个分辨率更低的小图像。在一些实施例中,拆分后的多个低分辨率图像尺寸相等。例如,如图6所示的拆分单元512可以将原始尺寸为128×128的图像拆分 成4个尺寸均为64×64的低分辨率图像。
也可以理解,如图6所示的拆分单元只是根据本公开的原理的拆分单元的一个示例。事实上,可以通过调整划分的基本像素矩阵的大小和形状将图像拆分为多个分辨率更低的小图像。例如,当基本像素矩阵的大小为3×3时,拆分单元可以将输入图像拆分为3×3=9个分辨率更低的小图像。又例如,当基本像素矩阵的大小是3×4时,拆分单元可以将输入图像拆分为3×4=12个分辨率更低的小图像。也就是说,当基本像素矩阵的大小是a×b时,拆分单元可以将输入图像拆分为a×b=c个分辨率更低的小图像。本领域技术人员可以了解,根据本公开的原理,拆分单元512可以将一张图像拆分为任意多个分辨率更低的缩小的图像。
也可以理解,图6示出的是利用拆分单元对二维的图像数据进行拆分的示意图。根据本公开的原理,拆分单元512也可以对其他任意维度(如一维、三维等)的图像数据进行拆分。
为了描述方便,在下文中将以图6示出的拆分单元为例进行描述,并将拆分后的四个低分辨率的图像分别称为左上(UL)、右上(UR)、左下(BL)和右下(BR)。也就是说,对于第i级编码单元来说,输入图像包括4
i-1个图像成分,经过第i级编码单元中的拆分单元512-i,第i级编码输入图像被拆分为4
i个图像成分。
图7图示了根据本公开的实施例的一种变换单元514的示意图。如前所述,拆分单元可以将原始图像拆分为4个低分辨率图像UL、UR、BL和BR。变换单元514可以对上述四个低分辨率图像UL、UR、BL和BR进行图像变换,从而提取出输入图像中的图像成分。
变换单元514可以包括第一预测单元710,配置成基于UL图像和BR图像生成用于UR图像和BL图像的预测图像并获取UR图像和BL图像和该预测图像之间的差别图像;第一更新单元720,配置成基于UR图像和BL图像和预测图像之间的差别图像生成用于UL图像和BR图像的更新图像;第一小波变换单元730,配置成执行基于用于UL图像和BR图像的更新图像的小波变换,并基于小波变换的结果生成第一编码输出成分和第二编码输出成分;第二小波变换单元740,配置成执行基于UR图像和BL图像和上述预测图像之间的差别图像的小波变换,并基于小波变换的结果生成第三编码输出成分 和第四编码输出成分。
在一些实施例中,如图7所示,第一预测单元710可以进一步包括第一预测卷积网络P
1和第一去叠加单元712。第一预测单元P
1配置成接收UL图像和BR图像作为输入,并生成用于UR图像和BL图像的第一预测特征和第二预测特征。第一预测特征和第二预测特征可以是相同的,也可以是不同的。第一去叠加单元712配置成对UR图像和第一预测特征执行去叠加操作以获得第一差别特征,以及对BL图像和第二预测特征执行去叠加操作以获得第二差别特征。
在一些实施例中,第一更新单元720可以进一步包括第一更新卷积网络U
1和第一叠加单元722。第一更新卷积网络U
1配置成接收第一差别特征和第二差别特征作为输入,并生成用于UL图像和BR图像的第一更新特征和第二更新特征。第一更新特征和第二更新特征可以是相同的,也可以是不同的。第一叠加单元722配置成对UL图像与第一更新特征执行叠加操作以获得第一叠加特征,以及对BR图像与第二更新特征执行叠加操作以获得第二叠加特征。
在一些实施例中,第一小波变换单元730可以进一步包括第二预测卷积网络P
21,配置成接收第一叠加特征作为输入,并生成用于第二叠加特征的第三预测特征;第二去叠加单元732,配置成对第二叠加特征与第三预测特征执行去叠加操作以获得第二编码输出成分;第二更新卷积网络U
21,配置成接收第二编码输出成分作为输入,并生成用于第一编码输出成分的第三更新特征;第二叠加单元734,配置成对第一叠加特征与第三更新特征执行叠加操作以获得第一编码输出成分。
在一些实施例中,第二小波变换单元740可以进一步包括第三预测卷积网络P
22,配置成接收第一差别特征作为输入,并生成用于第二差别特征的第四预测特征;第三去叠加单元742,配置成对第二差别特征与第四预测特征执行去叠加操作以获得第四编码输出成分;第三更新卷积网络U
22,配置成接收第四编码输出成分作为输入,并生成用于第一差别特征的第四更新特征;第三叠加单元644,配置成对第一差别特征与第四更新特征执行叠加操作以获得第三编码输出成分。
图7中示出的结构不是限制性的。例如,可以在变换单元514中对换第 一预测单元710和第一更新单元720的结构。
利用图7示出的图像处理装置可以对拆分后的低分辨率图像进行图像变换并提取输入图像中的图像成分。这里的图像变换中不损失图像信息,经过相应的逆变换可以无损的还原图像信息。
图8示出了根据本公开实施例的一种图像还原装置的示意图。图像还原装置800可以包括变换解码单元810。
图8示出的变换解码单元810对应于图5中示出的变换编码单元,能够将经过变换编码单元510变换的图像数据无损地还原为原始数据。
变换解码单元810可以包括用于接收解码输入图像的输入端,解码输入图像包括m
n个图像成分,其中m是大于1的整数,n是大于等于1的整数。其中m
n个图像成分中的每个图像成分可以包括多个通道(如RGB三个通道)。
变换解码单元810还可以包括级联的n级解码单元810-1、810-2……810-n,对于1≤i<n,第i级解码单元的输入为第i级解码输入图像并包括m
i个图像成分,第i级解码单元的输出为第i级解码输出图像并包括m
i-1个图像成分,以及第i级解码单元的输出是第i+1级解码单元的输入。
在一些实施例中,级联的n级解码单元中的每一个可以包括逆变换单元812和复合单元814。也就是说,第i级解码单元810-i中包括逆变换单元812-i和复合单元814-i。逆变换单元用于对第i级解码单元的输入的m
i个图像成分执行逆变换,从而无损地还原解码输入图像包括的m
i个图像成分对应的还原图像。复合单元814用于对m
i个经过逆变换的解码输出成分执行复合操作,从而将m
i个图像成分复合为m
i-1个图像成分。
变换解码单元810还可以包括输出端,配置成输出对应于解码输入图像中m
n个图像成分的还原图像。
图9示出了根据本公开的实施例的一种逆变换单元812的示意图。当m=4时,第i级解码输入图像包括第一解码输入成分、第二解码输入成分、第三解码输入成分和第四解码输入成分,其中每个解码输入成分包括4
i-1个图像成分。
逆变换单元812可以包括第一逆小波变换单元930,配置成执行基于第一解码输入成分和第二解码输入成分的逆小波变换,并基于逆小波变换的结 果获得第一差别特征和第一叠加特征;第二逆小波变换单元940,配置成执行基于第三解码输入成分和第四解码输入成分的逆小波变换,并基于逆小波变换的结果获得第二差别特征和第二叠加特征;第二更新单元920,配置成基于第二差别特征和第二叠加特征生成更新图像,并基于该更新图像、第一差别特征和第一叠加特征生成第一解码输出成分和第二解码输出成分;第二预测单元910,配置成基于第一解码输出成分和第二解码输出成分生成预测图像,并基于预测图像、第二差别特征和第二叠加特征生成第三解码输出成分和第四解码输出成分。
在一些实施例中,第二更新单元920进一步包括第一更新卷积网络U’
1和第一去叠加单元922。第一更新卷积网络U’
1配置成接收第二差别特征和第二叠加特征作为输入,并生成关于第二差别特征和第二叠加特征的第一更新特征和第二更新特征。第一更新特征和第二更新特征可以是相同的,也可以是不同的。第一去叠加单元922配置成对第一差别特征和第一更新特征执行去叠加操作以获得第一解码输出成分,以及对第一叠加特征和第二更新特征执行去叠加操作以获得第二解码输出成分。
在一些实施例中,第二预测单元910进一步包括第一预测卷积网络P’
1和第一叠加单元912。第一预测卷积网络P’
1配置成接收第一解码输出成分和第二解码输出成分作为输入,并生成关于第一解码输出成分和第二解码输出成分的第一预测特征和第二预测特征。第一预测特征和第二预测特征可以是相同的,也可以是不同的。第一叠加单元912配置成对第二差别特征和第一预测特征执行叠加操作以获得第三解码输出成分,以及对第二叠加特征和第二预测特征执行叠加操作以获得第四解码输出成分。
在一些实施例中,第一逆小波变换单元930可以进一步包括第二更新卷积网络U’
21,配置成接收第二解码输入成分作为输入,并生成关于第二解码输入成分的第三更新特征;第二去叠加单元934,配置成对第一解码输入成分和第三更新特征执行去叠加操作以获得第一差别特征;第二预测卷积网络P’
21,配置成接收第一差别特征作为输入,并生成关于第一差别特征的第三预测特征;第二叠加单元932,配置成对第二解码输入成分和第三预测特征执行叠加操作以获得第一叠加特征。
在一些实施例中,第二逆小波变换940可以进一步包括第三更新卷积网 络U’
22,配置成接收第四解码输入成分作为输入,并生成关于第四图像解码输入的第四更新特征;第三去叠加单元942,配置成对第三解码输入成分和第四更新特征执行去叠加操作以获得第二差别特征;第三预测卷积网络P’
22,配置成接收第二差别特征作为输入,并生成关于第二差别特征的第四预测特征;第三叠加单元944,配置成对第四解码输入成分和第四预测特征执行叠加操作以获得第二叠加特征。
由于逆变换单元812可以用于恢复经过变换单元514的处理的图像,因此,在一些实施例中,逆变换单元812中的卷积网络与变换单元514中的卷积网络完全对应。也就是说,逆变换单元812中的第一预测卷积网络P’
1、第一更新卷积网络U’
1、第二更新卷积网络U’
21、第二预测卷积网络P’
21、第三更新卷积网络U’
22、第三预测卷积网络P’
22与变换单元514中的第一预测卷积网络P
1、第一更新卷积网络U
1、第二更新卷积网络U
21、第二预测卷积网络P
21、第三更新卷积网络U
22、第三预测卷积网络P
22具有相同的结构和配置参数。
图9中示出的结构是非限制性的。例如,可以在逆变换单元812中对换第二预测单元910和第二更新单元920的结构。
图10示出了根据本公开的实施例的一种复合单元的示意图。复合单元可以将多个低分辨率的小图像复合为分辨率更高的复合图像。复合单元配置成执行如前所述的拆分单元的逆变换,从而将拆分后的低分辨率的小图像还原为高分辨率的原始图像。
在一些实施例中,当通过图像分类装置获得输入图像的多个输出子图像后,如果将得到的输出子图像按照输出的顺序输入图像还原装置,那么图像还原装置将输出还原的输入图像。例如,输入图像经过图像分类装置的处理后得到输出子图像C
0(REF)、C
1、C
2、C
3,如果将输出子图像C
0(REF)、C
1、C
2、C
3对应地输入逆变换单元的输入端,复合单元MUXOUT将依序聪哥输出子图像中提取对应的像素点,并将提取的像素点依次排列以生成还原图像。经过上述逆变换过程和复合操作,图像还原装置将输出与输入图像相同的还原图像。
在另一些实施例中,如果改变图像分类装置输出的输出子图像,并将改变后的多个输出子图像输入图像还原装置,那么图像还原装置将输出与输入 图像不同的还原装置。
例如,如果输入图像的左上角存在数字0,右下角存在数字2,那么经过图像分类装置的处理后得到的输出子图像中的C
0、C
2将包括左上角存在数字0,右下角存在数字2的像素信息。在还原过程中,如果将C
0和C
2的像素信息对换后输入图像还原装置,那么图像还原装置输出的是将输入图像中数字0和数字2对换后的图像。
又例如,如果将输入图像经过图像分类装置的处理后得到的输出子图像中的至少一个的像素信息(例如,对应于0的像素信息)替换为对应与其他类别的像素信息(例如,对应于5的像素信息),那么经过图像还原装置输出的还原图像是将原始的输入图像中的数字0替换为数字5的图像。
图11示意性地示出了对图像进行变换编码和变换解码的过程。在变换编码单元的输入端接收输入图像。如图11所示,输入图像可以包括任意多个通道,例如,RGB三通道。经过第1级变换解码单元的处理,输入图像经由拆分单元被拆分为四个分辨率更低的子图像。如上文所述,输入图像可以被拆分为任意多个子图像。通过变换单元对拆分后的子图像进行图像变换,获得图像成分。可以看出,对于包括多个通道的输入图像,如图11所示的第1级变换编码单元的每个箭头可以处理多个通道的数据。例如,对于包括RGB3个通道输入图像,第1级变换编码单元中的每个箭头表示在该次输入或输出中的数据存在3个通道。经过第1级变换编码单元后,输入图像的每个通道均被变换为四个图像成分。
根据图像处理的实际需要,可以使用多级变换编码单元对图像进行处理。例如,如图11所示的输入图像经过n级变换编码单元后,可以得到4
n个图像成分,其中一个或多个图像成分包含了输入图像的类别信息,其余是包含了其他细节信息的图像成分。与类别信息相比,其余图像成分的像素信息接近于零。也就是说,经过如本公开实施例提供的图像变换方法,通过变换后得到的图像成分的像素信息可以确定输入图像的类别,以及对应于该类别的输入图像中的像素信息。
此外,由于每一级变换编码单元都将输入图像拆分为更多的低分辨率的子图像,因此,每一级变换编码单元都可以比上一级变换编码单元具有更多的通道。例如,对于如图11中示出的输入图像,第1级变换编码单元中的每 个箭头表示输入/输出包括3个通道的数据,第2级变换编码单元中的每个箭头表示输入/输出包括12个通道的数据,依次类推,第n级变换编码单元中的每个箭头表示输入/输出包括3*4
n-1个通道的数据。
如上所述的图像变换编码过程是可逆的,对应于n级变换编码单元,使用相同配置的n级变换解码单元可以在不丢失图像信息的情况下还原输入图像。每一级变换解码单元用于对输入的多个图像成分进行逆变换,并对变换后的图像成分执行复合操作,将图像成分还原为分辨率更高的图像成分。对应于编码过程,经过相同级数的解码过程的处理,可以将多个图像成分还原为原始的输入图像。在此不再赘述。
图12示出了根据本公开的实施例的一种图像分类方法的流程图。可以利用如图5所示的图像分类装置执行图像分类方法1200。在步骤S1202中,接收输入图像。然后,在步骤S1204中,利用级联的n级编码单元对输入图像进行图像编码以产生输出图像,n为大于等于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m
i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m
i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数。在步骤S1206中,输出所述输出图像,所述输出图像包括m
n个输出子图像,所述m
n个输出子图像分别对应于第n级编码单元的m
n个输出图像成分,并且所述m
n个输出子图像的每一个对应于一种图像类别。在步骤S1208中,获取输出图像中m
n个输出子图像的每一个的像素值,根据像素值确定m
n个输出子图像中的一个是输入图像的类别子图像。在一些实施例中,步骤S1208包括比较所述m
n个输出子图像中每一个的像素值与第一阈值,将像素值大于第一阈值的输出子图像确定为类别子图像,并输出对应于所述类别子图像的类别标签,其中所述类别子图像包括输入图像中对应于所述类别标签的像素信息。在步骤S1210中,确定输入图像的类别为对应于所述类别子图像的图像类别。
上述图像分类方法能够对输入图像进行分类,确定输入图像的类别,并同时输出对应于输入图像的图像类别的像素信息。
图13示出了根据本公开的实施例的第i级变换编码单元的图像编码过程的流程图。可以利用如图5中示出的变换编码单元510-i执行图像编码过程1300。在步骤S1302中,接收第i级编码输入图像。在步骤S1304中,对于 第i级编码输入图像中的每个图像成分,将该图像成分拆分为m个编码输入成分。在步骤S1306中,对于第i级编码输入图像中的每个图像成分,对从该图像成分拆分得到的m个编码输入成分进行图像变换,生成对应于该图像成分的m个编码输出成分。在步骤S1308中,输出对应于第i级编码输入的m
i-1个图像成分的m
i个编码输出成分作为第i级编码输出图像。
图14示出了当m=4时,根据本公开的实施例的第i级变换编码单元中的图像变换过程的流程图。可以使用如图5或图7中示出的变换单元514执行图像变换过程1400。
当m=4时,第i级编码输入图像中的每个图像成分被拆分为第一编码输入成分、第二编码输入成分、第三编码输入成分和第四编码输入成分。因此在步骤S1402中,变换单元514接收第一编码输入成分、第二编码输入成分、第三编码输入成分和第四编码输入成分。在步骤S1404中,基于第一编码输入成分和第二编码输入成分生成预测图像并获取第三编码输入成分和第四编码输入成分和预测图像的差别图像。
其中,如图15A中所示出的,步骤S1404可以进一步包括:在步骤S1502中,利用将第一编码输入成分和第二编码输入成分作为输入的第一预测卷积网络P
1生成第一预测特征和第二预测特征。第一预测特征和第二预测特征可以是相同的,也可以是不同的。在步骤S1504中,对第三编码输入成分和第一预测特征执行去叠加操作以获得第一差别特征。在步骤S1506中,对第四编码输入成分和第二预测特征执行去叠加操作以获得第二差别特征。
在步骤S1406中,基于差别图像、第一编码输入成分和第二编码输入成分生成第一编码输入成分和第二编码输入成分的更新图像。
其中,如图15B中示出的,步骤S1404可以进一步包括:在步骤S1508中,利用将第一差别特征和第二差别特征作为输入的第一更新卷积网络U
1生成第一更新特征和第二更新特征。第一更新特征和第二更新特征可以是相同的,也可以是不同的。在步骤S1510中,对第一编码输入成分与第一更新特征执行叠加操作以获得第一叠加特征。在步骤S1512中,对第二编码输入成分与第二更新特征执行叠加操作以获得第二叠加特征。
在步骤S1408中,执行基于更新图像的小波变换,并基于小波变换的结果生成第一编码输出成分和第二编码输出成分。
在步骤S1410中,执行基于差别图像的小波变换,并基于小波变换的结果生成第三编码输出成分和第四编码输出成分。
图16示出了根据本公开的实施例的基于更新图像的小波变换的流程图。可以利用图7中示出的第一小波变换单元730实施基于更新图像的小波变换1600。在步骤S1602中,利用将第一叠加特征作为输入的第二预测卷积网络P
21生成关于第一叠加特征的第三预测特征。在步骤S1604中,对第二叠加特征与第三预测特征执行去叠加操作以获得第二编码输出成分。在步骤S1606中,利用将第二编码输出成分作为输入的第二更新卷积网络U
21生成关于第二编码输出成分的第三更新特征。在步骤S1608中,对第一叠加特征与第三更新特征执行叠加操作以获得第一编码输出成分。
图17示出了根据本公开的实施例的基于差别图像的小波变换的流程图。可以利用图7中示出的第二小波变换单元740实施基于差别图像的小波变换1700。在步骤S1702中,利用将第一差别特征作为输入的第三预测卷积网络P
22生成第四预测特征。在步骤S1704中,对第二差别特征与第四预测特征执行去叠加操作以获得第四编码输出成分。在步骤S1706中,利用将第四编码输出成分作为输入的第三更新卷积网络U
22生成第四更新特征。在步骤S1708中,对第一差别特征与第四更新特征执行叠加操作以获得第三编码输出成分。
根据本公开的实施例提供的图像变换方法,可以提取输入图像中的多个图像成分,并且基于提取后的多个图像成分的像素值确定输入图像的类别。
图18示出了根据本公开的实施例的一种图像还原方法的流程图。可以利用如图8所示的图像还原装置执行图像还原方法1800。在步骤S1802中,接收输入图像,输入图像包括m
n个图像成分。在步骤S1804中,利用级联的n级解码单元对输入图像进行图像解码以产生还原图像,对于1≤i<n,第i级解码单元的输入为第i级解码输入图像并包括m
i个图像成分,第i级解码单元的输出为第i级解码输出图像并包括m
i-1个图像成分,以及第i级解码单元的输出是第i+1级解码单元的输入。在步骤S1806中,输出对应于输入图像的还原图像。
为了无损地还原图像,图像还原方法1800是对应于图像分类方法1200的。也就是说,例如,当图像分类方法1200中包括n级编码单元时,图像还原方法1800中也相应地包括n级解码单元。
图19示出了根据本公开的实施例的第i级变换解码单元的图像解码方法的流程图。可以利用如图8中示出的变换解码单元810执行图像解码方法1900。在步骤S1902中,接收第i级解码输入图像,其中第i级输入图像包括m
i个输入子图像。在步骤S1904中,对m
i个图像成分进行图像逆变换,生成对应于第i级解码输入图像的m
i个解码输出成分。在步骤S1906中,将m
i个解码输出成分复合为m
i-1个解码输出子图像。在步骤S1908中,将对应于第i级解码输入图像的m
i个图像成分的m
i-1个解码输出子图像输出作为第i级解码输出图像。
图20示出了当m=4时,根据本公开的实施例的图像逆变换方法的流程图。可以利用如图8或图9中示出的逆变换单元812执行图像逆变换方法2000。在步骤S2002中,逆变换单元812接收第一解码输入成分、第二解码输入成分、第三解码输入成分以及第四解码输入成分。在步骤S2004中,执行基于第一解码输入成分和第二解码输入成分的逆小波变换,并基于逆小波变换的结果获得第一差别特征和第一叠加特征。在步骤S2006中,执行基于第三解码输入成分和第四解码输入成分的逆小波变换,并基于逆小波变换的结果获得第二差别特征和第二叠加特征。
在步骤S2008中,基于第二差别特征和第二叠加特征生成更新图像,并基于更新图像、第一差别特征和第一叠加特征生成第一解码输出成分和第二解码输出成分。
如图21A中所示出的,步骤S2008可以进一步包括:在步骤S2102中,利用将第二差别特征和第二叠加作为输入的第一更新卷积网络U’
1生成第一更新特征和第二更新特征。第一更新特征和第二更新特征可以是相同的,也可以是不同的。在步骤S2104中,对第一差别特征和第一更新特征执行去叠加操作以获得第一解码输出成分。在步骤S2106中,对第一叠加特征和第二更新特征执行去叠加操作以获得第二解码输出成分。
在步骤S2010中,基于第一解码输出成分和第二解码输出成分生成预测图像,并基于预测图像、第二差别特征和第二叠加特征生成第三解码输出成分和第四解码输出成分。
如图21B中所示出的,步骤S2010可以进一步包括:在步骤S2108中,利用将第一解码输出成分和第二解码输出成分作为输入的第一预测卷积网络 P’
1生成第一预测特征和第二预测特征。第一预测特征和第二预测特征可以是相同的,也可以是不同的。在步骤S2110中,对第二差别特征和第一预测特征执行叠加操作以获得第三解码输出成分。在步骤S2106中,对第二叠加特征和第二预测特征执行叠加操作以获得第四解码输出成分。
图22示出了基于第一解码输入成分和第二解码输入成分的逆小波变换方法的流程图。可以利用如图9中示出的逆小波变换单元930执行逆小波变换方法2200。在步骤S2202中,利用将第二解码输入成分作为输入的第二更新卷积网络U’
21生成第三更新特征。在步骤S2204中,对第一解码输入成分和第三更新特征执行去叠加操作以获得第一差别特征。在步骤S2206中,利用将第一差别特征作为输入的第二预测卷积网络P’
21生成第三预测特征。在步骤S2208中,对第二解码输入成分和第三预测特征执行叠加操作以获得第一叠加特征。
图23中示出了基于第三解码输入成分和第四解码输入成分的逆小波变换方法的流程图。可以利用如图9中示出的逆小波变换单元940执行逆小波变换方法2300。在步骤S2302中,利用将第四解码输入成分作为输入的第三更新卷积网络U’
22生成第四更新特征。在步骤S2304中,对第三解码输入成分和第四更新特征执行去叠加操作以获得第二差别特征。在步骤S2306中,利用将第二差别特征作为输入的第三预测卷积网络P’
22生成第四预测特征。步骤S2308中,对第四解码输入成分和第四预测特征执行叠加操作以获得第二叠加特征。
利用本公开的实施例提供的图像还原方法,可以在不丢失信息的情况下将图像成分还原为原始图像。
图24示出了根据本公开的实施例的一种图像处理器的示意图。如图24所示,图像处理器2400的前半部分可以是如图5所示的图像分类装置中的变换编码单元,用于从输入图像中提取多个图像成分。图像处理器2400的后半部分可以是如图8所示的图像还原装置,用于还原图像成分。利用图像处理器2400可以实现对图像的分类及还原过程,图像分类装置和还原装置的具体的结构已在上文中详细阐述,在此不再赘述。
利用深度学习方法可以实现对图像处理器2400中各卷积网络的参数的配置。
根据本公开的实施例的训练方法包括以下步骤:
将训练图像输入图像处理器,调整n级编码单元和n级解码单元中各卷积层中各卷积网络的权值,运行有限次迭代以使目标函数最优化。
对于如图24所示出的图像处理器,针对每一级编码单元和解码单元输入训练图像。例如,在图像处理器的输入端输入原始的高分辨率图像HR图像。
在一些实施例中,目标函数可以包括图像处理器中的编码损失、解码损失、风格损失、以及权重正则化系数中的一项或任意几项的和。下文中将介绍上述损失函数的计算方法。
在HR图像经过第1级编码单元的处理后,计算第1级编码单元输出的参考图像REF
1和第1级编码单元的训练图像LR
1之间的编码损失。上述编码损失可以通过式(1)中示出的编码损失函数L
ENCk进行计算:

在这里

其中REF
k是第k级编码单元输出的第一图像成分,LR
k是第k级编码单元的训练图像,其中LR
k是所述图像处理器的训练图像的下采样图像,并具有与REF
k相同的尺寸;C
0是所述训练图像的数量;C
ki是第k级编码单元输出的图像成分,其中1≤i≤m
k-1。
相应地,在解码过程中可以计算第k级解码单元输出的参考图像REF
k和第k级解码单元的训练图像之间的解码损失。解码单元的输入的训练图像包括M=m*n个图像成分,其中一个图像成分是HR图像的下采样图像,其余图像成分均为0。
上述解码损失可以通过式(2)中示出的解码损失函数L
DECk进行计算:

其中IQ函数评价REF
k与LR
k之间的差别。在一些实施例中,IQ函数可以是MSE函数:
MSE(X,Y)=||X-Y||
2,其中X、Y分别代表REF
k与LR
k的图像数据。
在一些实施例中,IQ函数可以是SSIM函数:

此外,根据第i级编码单元的输出以及对应一级的解码单元的输入可以计算这一级的风格损失函数。例如,可以根据第1级编码单元的输出以及第n级解码单元的输入计算第1级的风格损失函数。根据第2级编码单元的输出以及第n-1即解码单元的输入可以计算第2级的风格损失函数。风格损失函数可以通过式(3)定义:

其中对于具有m个通道的图像成分F,

其中G
X、G
Y分别是X图像、Y图像的格拉姆矩阵的特征量,X是第k级编码单元的输出图像,Y是第i+1-k级编码单元的输出图像,其中1≤k≤n。
此外,系统的权重正则化系数可以通过式(4)定义:

其中W是图像处理器中所有卷积网络的权重参数,b是图像处理器中所有卷积网络的偏置。
基于以上损失函数中的一项或多项可以计算图像处理器的总损失函数。可以将图像处理器的总损失函数应用于任何深度学习的优化策略,如随机梯度下降SGD或其变型(如动量SGD、Adam、RMSProp等)。
通过本公开的实施例提供的图像处理器的训练方法,可以利用深度学习的策略对图像处理器中的卷积神经网络进行参数配置。通过计算训练图像与图像处理器中生成的图像之间的损失函数作为目标函数,调整图像处理器中卷积神经网络的参数使得目标函数最优化,从而实现更好的图像分类效果。
需要说明的是,在本说明书中,术语“包括”、“包含”或者其任何其他变体意在涵盖非排他性的包含,从而使得包括一系列要素的过程、方法、物品或者设备不仅包括那些要素,而且还包括没有明确列出的其他要素,或者是还包括为这种过程、方法、物品或者设备所固有的要素。在没有更多限制的情况下,由语句“包括一个……”限定的要素,并不排除在包括所述要素的过程、方法、物品或者设备中还存在另外的相同要素。
最后,还需要说明的是,上述一系列处理不仅包括以这里所述的顺序按时间序列执行的处理,而且包括并行或分别地、而不是按时间顺序执行的处理。
通过以上的实施方式的描述,本领域的技术人员可以清楚地了解到本公开可借助软件加必需的硬件平台的方式来实现,当然也可以全部通过硬件来实施。基于这样的理解,本公开的技术方案对背景技术做出贡献的全部或者部分可以以软件产品的形式体现出来,该计算机软件产品可以存储在存储介质中,如ROM/RAM、磁碟、光盘等,包括若干指令用以使得一台计算机设备(可以是个人计算机,服务器,或者网络设备等)执行本公开各个实施例或者实施例的某些部分所述的方法。
以上对本公开进行了详细介绍,本文中应用了具体实施例对本公开的原理及实施方式进行了阐述,以上实施例的说明只是用于帮助理解本公开的方法及其核心思想;同时,对于本领域的一般技术人员,依据本公开的思想,在具体实施方式及应用范围上均会有改变之处,综上所述,本说明书内容不应理解为对本公开的限制。
Claims (22)
- 一种图像分类方法,包括:接收输入图像;利用级联的n级编码单元对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出所述输出图像,所述输出图像包括m n个输出子图像,所述m n个输出子图像分别对应于第n级编码单元的m n个输出图像成分,并且所述m n个输出子图像的每一个对应于一种图像类别;获取所述输出图像中m n个输出子图像的每一个的像素值,并根据像素值确定所述m n个输出子图像中的至少一个是所述输入图像的类别子图像,以及确定所述输入图像的类别为对应于所述类别子图像的图像类别。
- 如权利要求1所述的图像分类方法,其中根据所述m n个输出子图像中每一个的像素值,确定输入图像的类别包括:比较所述m n个输出子图像中每一个子图像中的每个像素点的像素值之和与第一阈值,将其像素值之和大于第一阈值的输出子图像确定为类别子图像,并输出对应于所述类别子图像的类别标签,其中所述类别子图像包括输入图像中对应于所述类别标签的像素信息。
- 如权利要求1-2所述的图像分类方法,其中所述输入图像、所述m n个输出子图像的每一个包括R、G、B三个通道。
- 如权利要求1-3所述的图像分类方法,其中,利用第i级编码单元进行图像编码包括:接收第i级编码输入图像;对于所述第i级编码输入图像中的每个图像成分,将该图像成分拆分为m个编码输入成分,其中所述m个编码输入成分中的每一个的尺寸是第i级编 码输入图像中的每个图像成分的尺寸的1/m倍,对所述m个编码输入成分进行图像变换,生成对应于该图像成分的m个编码输出成分,其中所述m个编码输出成分中的每一个的尺寸与所述m个编码输入成分中的每一个的尺寸相同;输出对应于第i级编码输入的m i-1个图像成分的m i个编码输出成分作为第i级编码输出图像。
- 如权利要求4所述的图像分类方法,其中m=4,所述第i级编码输入图像中的每个图像成分被拆分为第一编码输入成分、第二编码输入成分、第三编码输入成分和第四编码输入成分,利用第i级编码单元对所述第一编码输入成分、所述第二编码输入成分、所述第三编码输入成分和所述第四编码输入成分进行图像变换包括:接收所述第一编码输入成分、所述第二编码输入成分、所述第三编码输入成分和所述第四编码输入成分;基于所述第一编码输入成分和所述第二编码输入成分生成预测图像并获取所述第三编码输入成分和所述第四编码输入成分和所述预测图像的差别图像;基于所述差别图像、所述第一编码输入成分和所述第二编码输入成分生成关于所述第一编码输入成分和所述第二编码输入成分的更新图像;执行基于所述更新图像的小波变换,并基于小波变换的结果生成第一编码输出成分和第二编码输出成分;执行基于所述差别图像的小波变换,并基于小波变换的结果生成第三编码输出和第四编码输出。
- 如权利要求5所述的图像分类方法,其中,基于所述第一编码输入成分和所述第二编码输入成分生成预测图像并获取所述第三编码输入成分和所述第四编码输入成分和所述预测图像的差别图像包括:利用将所述第一编码输入成分和所述第二编码输入成分作为输入的第一预测卷积网络生成第一预测特征和第二预测特征;对所述第三编码输入成分和所述第一预测特征执行去叠加操作以获得第 一差别特征;对所述第四编码输入成分和所述第二预测特征执行去叠加操作以获得第二差别特征;其中,基于所述差别图像、所述第一编码输入成分和所述第二编码输入成分生成更新图像包括:利用将所述第一差别特征和所述第二差别特征作为输入的第一更新卷积网络生成第一更新特征和第二更新特征;对所述第一编码输入成分与所述第一更新特征执行叠加操作以获得第一叠加特征;对所述第二编码输入成分与所述第二更新特征执行叠加操作以获得第二叠加特征。
- 如权利要求6所述的图像分类方法,其中执行所述基于所述更新图像的小波变换,并基于小波变换的结果生成第一编码输出成分和第二编码输出成分包括:利用将所述第一叠加特征作为输入的第二预测卷积网络生成第三预测特征;对所述第二叠加特征与所述第三预测特征执行去叠加操作以获得所述第二编码输出成分;利用将所述第二编码输出成分作为输入的第二更新卷积网络生成第三更新特征;对所述第一叠加特征与所述第三更新特征执行叠加操作以获得所述第一编码输出成分。
- 如权利要求6-7任一项所述的图像分类方法,其中执行所述基于所述差别图像的小波变换,并基于小波变换的结果生成第三编码输出成分和第四编码输出成分包括:利用将所述第一差别特征作为输入的第三预测卷积网络生成第四预测特征;对所述第二差别特征与所述第四预测特征执行去叠加操作以获得所述第四编码输出成分;利用将所述第四编码输出成分作为输入的第三更新卷积网络生成第四更新特征;对所述第一差别特征与所述第四更新特征执行叠加操作以获得所述第三编码输出成分。
- 一种图像分类装置,包括:输入端,配置成接收输入图像;级联的n级编码单元,配置成对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出端,配置成输出所述输出图像,所述输出图像包括m n个输出子图像,所述m n个输出子图像分别对应于第n级编码单元的m n个输出图像成分,并且所述m n个输出子图像的每一个对应于一种图像类别;分类单元,配置成获取所述输出图像中m n个输出子图像的每一个的像素值,并根据像素值确定所述m n个输出子图像中的至少一个是所述输入图像的类别子图像,并确定所述输入图像的类别为对应于所述类别子图像的图像类别。
- 如权利要求9所述的图像分类装置,其中分类单元进一步配置成:比较所述m n个输出子图像中每一个子图像中的各像素的像素值之和与第一阈值,将像素值之和大于第一阈值的输出子图像确定为类别子图像,并输出对应于所述类别子图像的类别标签,其中所述类别子图像包括输入图像中对应于所述类别标签的像素信息。
- 如权利要求9-10任一项所述的图像分类装置,其中所述输入图像、所述m n个输出子图像中的每一个包括R、G、B三个通道。
- 如权利要求9-11任一项所述的图像分类装置,其中第i级编码单元包括:输入端,配置成接收第i级编码输入图像;拆分单元,配置成对于所述第i级编码输入图像中的每个图像成分,将该 图像成分拆分为m个编码输入成分,其中所述m个编码输入成分中的每一个的尺寸是第i级编码输入图像中的每个图像成分的尺寸的1/m倍;变换单元,配置成对于所述第i级编码输入图像中的每个图像成分,对从该图像成分拆分得到的所述m个编码输入成分进行图像变换,生成对应于该图像成分的m个编码输出成分,其中所述m个编码输出成分中的每一个的尺寸与所述m个编码输入成分中的每一个的尺寸相同;编码输出端,配置成输出对应于第i级编码输入的m i-1个图像成分的m i个编码输出成分作为第i级编码输出图像。
- 如权利要求12所述的图像分类装置,其中,m=4,所述第i级编码输入图像中的每个图像成分被拆分为第一编码输入成分、第二编码输入成分、第三编码输入成分和第四编码输入成分,第i级编码单元的变换单元进一步包括:第一预测单元,配置成基于所述第一编码输入成分和所述第二编码输入成分生成预测图像并获取所述第三编码输入成分和所述第四编码输入成分和所述预测图像的差别图像;第一更新单元,配置成基于所述差别图像、所述第一编码输入成分和所述第二编码输入成分生成关于所述第一编码输入成分和所述第二编码输入成分的更新图像;第一小波变换单元,配置成执行基于所述更新图像的小波变换,并基于小波变换的结果生成第一编码输出成分和第二编码输出成分;第二小波变换单元,配置成执行基于所述差别图像的小波变换,并基于小波变换的结果生成第三编码输出成分和第四编码输出成分。
- 如权利要求13所述的图像分类装置,其中第一预测单元进一步包括:第一预测卷积网络,配置成接收所述第一编码输入成分和所述第二编码输入成分作为输入,并生成第一预测特征和第二预测特征;第一去叠加单元,配置成对所述第三编码输入成分和所述第一预测特征执行去叠加操作以获得第一差别特征,以及对所述第四编码输入成分和所述第二预测特征执行去叠加操作以获得第二差别特征;第一更新单元进一步包括:第一更新卷积网络,配置成接收所述第一差别特征和所述第二差别特征作为输入,并生成第一更新特征和第二更新特征;第一叠加单元,配置成对所述第一编码输入成分与所述第一更新特征执行叠加操作以获得第一叠加特征,以及对所述第二编码输入成分与所述第二更新特征执行叠加操作以获得第二叠加特征。
- 如权利要求14所述的图像分类装置,其中所述第一小波变换单元进一步包括:第二预测卷积网络,配置成接收所述第一叠加特征作为输入,并生成第三预测特征;第二去叠加单元,配置成对所述第二叠加特征与所述第三预测特征执行去叠加操作以获得所述第二编码输出成分;第二更新卷积网络,配置成接收所述第二编码输出成分作为输入,并生成第三更新特征;第二叠加单元,配置成对所述第一叠加特征与所述第三更新特征执行叠加操作以获得所述第一编码输出成分。
- 如权利要求14-15所述的图像分类装置,其中所述第二小波变换单元进一步包括:第三预测卷积网络,配置成接收所述第一差别特征作为输入,并生成第四预测特征;第三去叠加单元,配置成对所述第二差别特征与所述第四预测特征执行去叠加操作以获得所述第四编码输出成分;第三更新卷积网络,配置成接收所述第四编码输出成分作为输入,并生成第四更新特征;第三叠加单元,配置成对所述第一差别特征与所述第四更新特征执行叠加操作以获得所述第三编码输出成分。
- 一种图像处理器,包括:图像编码装置,所述图像编码装置包括:编码输入端,配置成接收输入图像;级联的n级编码单元,配置成对所述输入图像进行图像编码以产生输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;编码输出端,配置成输出所述输出图像,所述输出图像包括m n个输出子图像,所述m n个输出子图像分别对应于第n级编码单元的m n个输出图像成分,并且所述m n个输出子图像的每一个对应于一种图像类别;图像解码装置,所述图像解码装置包括:解码输入端,配置成接收解码输入图像,所述解码输入图像包括m n个图像成分,其中m是大于1的整数,n是大于1的整数;级联的n级解码单元,配置成对所述解码输入图像进行图像解码以产生还原图像,n为大于1的整数,对于1≤i<n,第i级解码单元的输入为第i级解码输入图像并包括m i个图像成分,第i级解码单元的输出为第i级解码输出图像并包括m i-1个图像成分,以及第i级解码单元的输出是第i+1级解码单元的输入;解码输出端,配置成输出对应于所述解码输入图像的还原图像。
- 一种用于如权利要求17所述的图像处理器的训练方法,包括:将训练图像输入所述图像处理器,调整所述n级编码单元和所述n级解码单元中各卷积层中各卷积网络的权值,运行有限次迭代以使目标函数最优化。
- 如权利要求18所述的训练方法,其中所述目标函数是以下各项中的一项或多项的和:编码损失函数
 其中REF k是第k级编码单元输出的第一图像成分,LR k是第k级编码单元的训练图像,其中LR k是所述图像处理器的训练图像的下采样图像,并具有与REF k相同的尺寸;C 0是所述训练图像的数量;C ki是第k级编码单元输 出的图像成分,其中1≤i≤m k-1;解码损失函数
 其中IQ函数评价REF k与LR k之间的差别;风格损失函数
 其中
 其中G X、G Y分别是X图像、Y的格拉姆矩阵的特征量,X是第k级编码单元的输出图像,Y是第i+1-k级编码单元的输出图像,其中1≤k≤n;权重正则化系数
 其中W是所述图像处理器中所有卷积网络的权重参数,b是所述图像处理器中所有卷积网络的偏置。
- 一种图像转换方法,包括:接收第一输入图像和第二输入图像;利用级联的n级编码单元对所述第一输入图像进行图像编码以产生第一输出图像,n为大于1的整数,对于1≤i<n,第i级编码单元的输入为第i级编码输入图像并包括m i-1个图像成分,第i级编码单元的输出为第i级编码输出图像并包括m i个图像成分,以及第i级编码单元的输出是第i+1级编码单元的输入,其中m是大于1的整数;输出第一输出图像,所述第一输出图像包括m n个输出子图像,所述m n个输出子图像分别对应于第n级编码单元的m n个输出图像成分,并且所述m n个输出子图像的每一个对应于一种图像类别;获取所述第一输出图像中m n个输出子图像的每一个的像素值,并根据像素值确定所述m n个输出子图像中的至少一个是所述第一输入图像的类别子图像;确定所述第一输入图像的类别为对应于所述类别子图像的图像类别;获取所述类别子图像的像素信息;基于所述类别子图像的像素信息对所述第二输入图像进行图像变换,将所述第二输入图像变换为对应于所述第一输入图像的图像类别的第三图像。
- 一种如权利要求20所述的图像转换方法,其中利用第i级编码单元进行图像编码包括:接收第i级编码输入图像;对于所述第i级编码输入图像中的每个图像成分,将该图像成分拆分为m个编码输入成分,其中所述m个编码输入成分中的每一个的尺寸是第i级编码输入图像中的每个图像成分的尺寸的1/m倍,对所述m个编码输入成分进行图像变换,生成对应于该图像成分的m个编码输出成分,其中所述m个编码输出成分中的每一个的尺寸与所述m个编码输入成分中的每一个的尺寸相同;输出对应于第i级编码输入的m i-1个图像成分的m i个编码输出成分作为第i级编码输出图像。
- 一种计算机可读介质,其上存储有指令,当处理器执行所述指令时使得计算机执行如权利要求1-8中任一所述的图像分类方法或权利要求20-21中任一所述的图像转换方法。
Priority Applications (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| EP18875950.0A EP3709218A4 (en) | 2017-11-09 | 2018-10-31 | IMAGE CLASSIFICATION AND CONVERSION METHOD AND DEVICE, IMAGE PROCESSOR AND TRAINING METHOD FOR AND MEDIUM |
| US16/487,885 US11328184B2 (en) | 2017-11-09 | 2018-10-31 | Image classification and conversion method and device, image processor and training method therefor, and medium |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN201711100238.1A CN107895174B (zh) | 2017-11-09 | 2017-11-09 | 图像分类和转换方法、装置以及图像处理系统 |
| CN201711100238.1 | 2017-11-09 |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2019091318A1 true WO2019091318A1 (zh) | 2019-05-16 |
Family
ID=61804839
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/CN2018/113115 Ceased WO2019091318A1 (zh) | 2017-11-09 | 2018-10-31 | 图像分类和转换方法、装置、图像处理器及其训练方法和介质 |
Country Status (4)
| Country | Link |
|---|---|
| US (1) | US11328184B2 (zh) |
| EP (1) | EP3709218A4 (zh) |
| CN (1) | CN107895174B (zh) |
| WO (1) | WO2019091318A1 (zh) |
Families Citing this family (11)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN107895174B (zh) | 2017-11-09 | 2020-01-07 | 京东方科技集团股份有限公司 | 图像分类和转换方法、装置以及图像处理系统 |
| CN110751283B (zh) * | 2018-07-05 | 2022-11-15 | 第四范式(北京)技术有限公司 | 模型解释方法、装置、设备及存储介质 |
| US10955251B2 (en) * | 2018-09-06 | 2021-03-23 | Uber Technologies, Inc. | Identifying incorrect coordinate prediction using route information |
| CN109191382B (zh) * | 2018-10-18 | 2023-12-05 | 京东方科技集团股份有限公司 | 图像处理方法、装置、电子设备及计算机可读存储介质 |
| US20200137380A1 (en) * | 2018-10-31 | 2020-04-30 | Intel Corporation | Multi-plane display image synthesis mechanism |
| US11057634B2 (en) * | 2019-05-15 | 2021-07-06 | Disney Enterprises, Inc. | Content adaptive optimization for neural data compression |
| DE102021105020A1 (de) * | 2021-03-02 | 2022-09-08 | Carl Zeiss Microscopy Gmbh | Mikroskopiesystem und Verfahren zum Verarbeiten eines Mikroskopbildes |
| US20220201320A1 (en) * | 2021-03-11 | 2022-06-23 | Passant V. Karunaratne | Video analytics using scalable video coding |
| CN112906637B (zh) * | 2021-03-18 | 2023-11-28 | 北京海鑫科金高科技股份有限公司 | 基于深度学习的指纹图像识别方法、装置和电子设备 |
| CN113128670B (zh) * | 2021-04-09 | 2024-03-19 | 南京大学 | 一种神经网络模型的优化方法及装置 |
| KR102850663B1 (ko) * | 2022-08-22 | 2025-08-26 | 주식회사 스톡폴리오 | 영상 컨텐츠 키워드 태깅 시스템 및 이를 이용한 영상 컨텐츠 키워드 태깅 방법 |
Citations (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN103116766A (zh) * | 2013-03-20 | 2013-05-22 | 南京大学 | 一种基于增量神经网络和子图编码的图像分类方法 |
| EP2977933A1 (en) * | 2014-07-22 | 2016-01-27 | Baden-Württemberg Stiftung gGmbH | Image classification |
| CN105809182A (zh) * | 2014-12-31 | 2016-07-27 | 中国科学院深圳先进技术研究院 | 一种图像分类的方法及装置 |
| CN106845418A (zh) * | 2017-01-24 | 2017-06-13 | 北京航空航天大学 | 一种基于深度学习的高光谱图像分类方法 |
| CN107895174A (zh) * | 2017-11-09 | 2018-04-10 | 京东方科技集团股份有限公司 | 图像分类和转换方法、装置以及图像处理系统 |
Family Cites Families (21)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US7805386B2 (en) * | 2006-05-16 | 2010-09-28 | Greer Douglas S | Method of generating an encoded output signal using a manifold association processor having a plurality of pairs of processing elements trained to store a plurality of reciprocal signal pairs |
| CN104346622A (zh) * | 2013-07-31 | 2015-02-11 | 富士通株式会社 | 卷积神经网络分类器及其分类方法和训练方法 |
| US10289910B1 (en) * | 2014-07-10 | 2019-05-14 | Hrl Laboratories, Llc | System and method for performing real-time video object recognition utilizing convolutional neural networks |
| FR3025344B1 (fr) * | 2014-08-28 | 2017-11-24 | Commissariat Energie Atomique | Reseau de neurones convolutionnels |
| US10223333B2 (en) * | 2014-08-29 | 2019-03-05 | Nvidia Corporation | Performing multi-convolution operations in a parallel processing system |
| EP3234871B1 (en) * | 2014-12-17 | 2020-11-25 | Google LLC | Generating numeric embeddings of images |
| CN105120130B (zh) | 2015-09-17 | 2018-06-29 | 京东方科技集团股份有限公司 | 一种图像升频系统、其训练方法及图像升频方法 |
| US10402700B2 (en) * | 2016-01-25 | 2019-09-03 | Deepmind Technologies Limited | Generating images using neural networks |
| US20180082181A1 (en) * | 2016-05-13 | 2018-03-22 | Samsung Electronics, Co. Ltd. | Neural Network Reordering, Weight Compression, and Processing |
| US20180046903A1 (en) * | 2016-08-12 | 2018-02-15 | DeePhi Technology Co., Ltd. | Deep processing unit (dpu) for implementing an artificial neural network (ann) |
| CN110073359B (zh) * | 2016-10-04 | 2023-04-04 | 奇跃公司 | 用于卷积神经网络的有效数据布局 |
| CN107920248B (zh) | 2016-10-11 | 2020-10-30 | 京东方科技集团股份有限公司 | 图像编解码装置、图像处理系统、训练方法和显示装置 |
| GB2555431A (en) * | 2016-10-27 | 2018-05-02 | Nokia Technologies Oy | A method for analysing media content |
| KR102631381B1 (ko) * | 2016-11-07 | 2024-01-31 | 삼성전자주식회사 | 컨볼루션 신경망 처리 방법 및 장치 |
| US10824934B2 (en) * | 2017-01-12 | 2020-11-03 | Texas Instruments Incorporated | Methods and apparatus for matrix processing in a convolutional neural network |
| US10410322B2 (en) * | 2017-04-05 | 2019-09-10 | Here Global B.V. | Deep convolutional image up-sampling |
| CN107124609A (zh) | 2017-04-27 | 2017-09-01 | 京东方科技集团股份有限公司 | 一种视频图像的处理系统、其处理方法及显示装置 |
| US10325342B2 (en) * | 2017-04-27 | 2019-06-18 | Apple Inc. | Convolution engine for merging interleaved channel data |
| CN107122826B (zh) | 2017-05-08 | 2019-04-23 | 京东方科技集团股份有限公司 | 用于卷积神经网络的处理方法和系统、和存储介质 |
| KR102301232B1 (ko) * | 2017-05-31 | 2021-09-10 | 삼성전자주식회사 | 다채널 특징맵 영상을 처리하는 방법 및 장치 |
| CN107801026B (zh) * | 2017-11-09 | 2019-12-03 | 京东方科技集团股份有限公司 | 图像压缩方法及装置、图像压缩及解压缩系统 |
-
2017
- 2017-11-09 CN CN201711100238.1A patent/CN107895174B/zh active Active
-
2018
- 2018-10-31 EP EP18875950.0A patent/EP3709218A4/en active Pending
- 2018-10-31 US US16/487,885 patent/US11328184B2/en active Active
- 2018-10-31 WO PCT/CN2018/113115 patent/WO2019091318A1/zh not_active Ceased
Patent Citations (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN103116766A (zh) * | 2013-03-20 | 2013-05-22 | 南京大学 | 一种基于增量神经网络和子图编码的图像分类方法 |
| EP2977933A1 (en) * | 2014-07-22 | 2016-01-27 | Baden-Württemberg Stiftung gGmbH | Image classification |
| CN105809182A (zh) * | 2014-12-31 | 2016-07-27 | 中国科学院深圳先进技术研究院 | 一种图像分类的方法及装置 |
| CN106845418A (zh) * | 2017-01-24 | 2017-06-13 | 北京航空航天大学 | 一种基于深度学习的高光谱图像分类方法 |
| CN107895174A (zh) * | 2017-11-09 | 2018-04-10 | 京东方科技集团股份有限公司 | 图像分类和转换方法、装置以及图像处理系统 |
Non-Patent Citations (1)
| Title |
|---|
| See also references of EP3709218A4 * |
Also Published As
| Publication number | Publication date |
|---|---|
| US20200057921A1 (en) | 2020-02-20 |
| CN107895174A (zh) | 2018-04-10 |
| US11328184B2 (en) | 2022-05-10 |
| CN107895174B (zh) | 2020-01-07 |
| EP3709218A1 (en) | 2020-09-16 |
| EP3709218A4 (en) | 2021-08-04 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| CN107895174B (zh) | 图像分类和转换方法、装置以及图像处理系统 | |
| CN107820096B (zh) | 图像处理装置及方法、图像处理系统及训练方法 | |
| CN107801026B (zh) | 图像压缩方法及装置、图像压缩及解压缩系统 | |
| CN110728192B (zh) | 一种基于新型特征金字塔深度网络的高分遥感图像分类方法 | |
| CN117980914A (zh) | 用于以有损方式对图像或视频进行编码、传输和解码的方法及数据处理系统 | |
| Lodhi et al. | Multipath-DenseNet: A Supervised ensemble architecture of densely connected convolutional networks | |
| JP2021525408A (ja) | 画像または音声データの入力データセットペアの変位マップの生成 | |
| CN115345866A (zh) | 一种遥感影像中建筑物提取方法、电子设备及存储介质 | |
| CN116797787B (zh) | 基于跨模态融合与图神经网络的遥感影像语义分割方法 | |
| CN110351450B (zh) | 基于纵横交叉算法进行多直方图选点的可逆信息隐藏方法 | |
| CN114220019B (zh) | 一种轻量级沙漏式遥感图像目标检测方法及系统 | |
| CN116612416B (zh) | 一种指代视频目标分割方法、装置、设备及可读存储介质 | |
| CN115100543A (zh) | 面向小样本遥感影像场景分类的自监督自蒸馏元学习方法 | |
| CN111898614B (zh) | 神经网络系统以及图像信号、数据处理的方法 | |
| CN117372782B (zh) | 一种基于频域分析的小样本图像分类方法 | |
| CN117635935A (zh) | 轻量化无监督自适应图像语义分割方法及系统 | |
| CN116703757A (zh) | 一种基于背景引导的文本图像阴影消除方法 | |
| CN116168394A (zh) | 图像文本识别方法和装置 | |
| CN113554655B (zh) | 基于多特征增强的光学遥感图像分割方法及装置 | |
| Huan et al. | Learning deep cross-scale feature propagation for indoor semantic segmentation | |
| Ng et al. | Steganalysis classifier training via minimizing sensitivity for different imaging sources | |
| Sharma et al. | Dual Stage Semantic Information Based Generative Adversarial Network For Image Super-Resolution✱ | |
| CN115546236B (zh) | 基于小波变换的图像分割方法及装置 | |
| Sujatha et al. | A new logical compact LBP co-occurrence matrix for texture analysis | |
| CN118097693A (zh) | 一种基于领域噪音自适应的文档布局分析方法和系统 |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 18875950 Country of ref document: EP Kind code of ref document: A1 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| ENP | Entry into the national phase |
Ref document number: 2018875950 Country of ref document: EP Effective date: 20200609 |