WO2020029998A1 - 脑电图辅助的波束形成器和波束形成方法以及耳戴式听力系统 - Google Patents
脑电图辅助的波束形成器和波束形成方法以及耳戴式听力系统 Download PDFInfo
- Publication number
- WO2020029998A1 WO2020029998A1 PCT/CN2019/099594 CN2019099594W WO2020029998A1 WO 2020029998 A1 WO2020029998 A1 WO 2020029998A1 CN 2019099594 W CN2019099594 W CN 2019099594W WO 2020029998 A1 WO2020029998 A1 WO 2020029998A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- beamforming
- signal
- speech
- eeg
- beamformer
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Images


Classifications
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R25/00—Electric hearing aids
- H04R25/40—Arrangements for obtaining a desired directivity characteristic
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R25/00—Electric hearing aids
- H04R25/40—Arrangements for obtaining a desired directivity characteristic
- H04R25/405—Arrangements for obtaining a desired directivity characteristic by combining a plurality of transducers
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R25/00—Electric hearing aids
-
- A—HUMAN NECESSITIES
- A61—MEDICAL OR VETERINARY SCIENCE; HYGIENE
- A61B—DIAGNOSIS; SURGERY; IDENTIFICATION
- A61B5/00—Measuring for diagnostic purposes; Identification of persons
- A61B5/72—Signal processing specially adapted for physiological signals or for diagnostic purposes
- A61B5/7235—Details of waveform analysis
- A61B5/7253—Details of waveform analysis characterised by using transforms
- A61B5/7257—Details of waveform analysis characterised by using transforms using Fourier transforms
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R25/00—Electric hearing aids
- H04R25/50—Customised settings for obtaining desired overall acoustical characteristics
- H04R25/505—Customised settings for obtaining desired overall acoustical characteristics using digital signal processing
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R25/00—Electric hearing aids
- H04R25/60—Mounting or interconnection of hearing aid parts, e.g. inside tips, housings or to ossicles
- H04R25/604—Mounting or interconnection of hearing aid parts, e.g. inside tips, housings or to ossicles of acoustic or vibrational transducers
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04R—LOUDSPEAKERS, MICROPHONES, GRAMOPHONE PICK-UPS OR LIKE ACOUSTIC ELECTROMECHANICAL TRANSDUCERS; ELECTRIC HEARING AIDS; PUBLIC ADDRESS SYSTEMS
- H04R2225/00—Details of deaf aids covered by H04R25/00, not provided for in any of its subgroups
- H04R2225/43—Signal processing in hearing aids to enhance the speech intelligibility
Definitions
- the present invention relates to the field of hearing aid technology, and in particular, to an EEG-assisted multi-mode beamformer and beamforming method used in an ear-worn hearing system, and an ear including the beamformer. Wearable hearing system.
- Ear-worn hearing systems are used to help people with hearing loss by transmitting amplified sound to the ear canals. Damage to the patient's outer cochlea hair cells results in loss of the patient's hearing frequency resolution. As this situation develops, it becomes difficult for patients to distinguish between speech and environmental noise. Simple zooming cannot solve this problem. Therefore, there is a need to help such patients understand speech in a noisy environment. Beamformers are often used in ear-worn hearing systems to distinguish between speech and noise to help patients understand speech in a noisy environment.
- the application of spatially diverse binaural beamforming technology in a hearing system is a well-known technology that can significantly improve the user's ability to target the speaker in a noisy multiple speaker environment. Semantic understanding.
- two widely used beamformers such as Multi-channel Wiener Filter (MWF) beamformers and Minimum Variance Distortionless Response (MVDR) beamformers, require The prior information of the target speaker, that is, the traditional prior signal processing method is used to extract the spatial prior information of the speaker.
- MMF Multi-channel Wiener Filter
- MVDR Minimum Variance Distortionless Response
- the MWF beamformer needs to detect Voice Activity Detection (VAD) for participating speakers (Attended Talker), while the MVDR beamformer needs to identify the Acoustic Transfer Function (ATF) of the participating speakers ).
- VAD Voice Activity Detection
- ATF Acoustic Transfer Function
- this application is dedicated to integrating AA decoding and beamforming into an optimization model, and assigning users' attention preferences to different speech sources in the form of AA preferences.
- an auditory attention decoding and adaptive binaural beam for ear-worn hearing systems is proposed.
- the formed joint algorithm can effectively use the AA information contained in the EEG signal, avoid the sensitivity problem in the case of wrong AA decoding, and does not require an additional blind source separation process.
- the beamformer of the present inventive concept is named an EEG-assisted binaural beamformer.
- a low-complexity iterative algorithm ie, the well-known Gradient Projection Method (GPM) and Alternating Direction Method of Multiplexers (ADMM)
- GPM Gradient Projection Method
- ADMM Alternating Direction Method of Multiplexers
- a beamformer comprising: a device for receiving at least one electroencephalogram (EEG) signal and a plurality of input signals from a plurality of speech sources; and for building an optimization model And an apparatus for solving an optimization model, which obtains a beamforming weight coefficient that linearly or non-linearly combines the plurality of input signals; wherein the optimization model includes an optimization formula for obtaining the beamforming weight coefficient, and The optimization formula includes establishing an association between the at least one EEG signal and a beamforming output, and optimizing the association so as to construct a beamforming weight coefficient associated with the at least one EEG signal.
- EEG electroencephalogram
- a beamforming method for a beamformer including: receiving at least one electroencephalogram (EEG) signal and multiple input signals from multiple speech sources; and by constructing An optimization model and an optimization model are obtained to obtain a beamforming weight coefficient that linearly or non-linearly combines the plurality of input signals; wherein the optimization model includes an optimization formula for obtaining the beamforming weight coefficient, the optimization formula It includes establishing an association between the at least one EEG signal and a beamforming output, and optimizing the association so as to construct a beamforming weight coefficient associated with the at least one EEG signal.
- EEG electroencephalogram
- an ear-mounted hearing aid system comprising: a microphone configured to receive a plurality of input signals from a plurality of speech sources; and an electroencephalogram signal receiving interface configured to receive Information from one or more EEG electrodes and linearly or non-linearly transforming the EEG information to form at least one EEG signal; a beamformer that receives the plurality of input signals and the At least one EEG signal and outputting a beamforming weighting coefficient; and a synthesis module that linearly or non-linearly combines the plurality of input signals and the beamforming weighting coefficient to form a beamforming output, a speaker configured to convert The beamforming output is converted into an output sound, wherein the beamformer is a beamformer according to the present invention.
- a computer-readable medium comprising instructions, which when executed by a processor enables the processor to perform a beamforming method according to the present invention.
- the present invention integrates AA decoding and beamforming into an optimization model. Therefore, the AA information contained in the EEG signal can be effectively used, the sensitivity problem in the case of wrong AA decoding is avoided, and no additional blind source separation process is required.
- FIG. 1 is a block diagram of an example embodiment of an ear-worn hearing system according to the present invention.
- FIG. 2A is a schematic diagram showing the working principle of an EEG-assisted beamformer of the present invention
- FIG. 2B illustrates a schematic flowchart of a beamforming method performed by an EEG-assisted beamformer of FIG. 2A;
- FIG. 3 shows a top view of a simulated acoustic environment used to compare the EEG-assisted beamforming method of the present invention with a source separation (SP) -linearly constrained minimum variance (LCMV) method ;
- SP source separation
- LCMV linearly constrained minimum variance
- Figure 5 shows the percentage of IW-SINRI greater than or equal to 0dB, 2dB, 4dB for the beamforming method and SP-LCMV method of the present invention.
- FIG. 6 shows the relationship between IW-SD and Pearson correlation difference for the beamforming method and SP-LCMV method of the present invention.
- the beamformer of the embodiment of the present application aims to improve the speech of a speaker participating in a noisy multi-speaker environment by establishing an internal association between AEG decoding based on EEG assistance and binaural beamforming from a signal processing perspective. And reduce other impacts.
- the beamformer according to the embodiment of the present application based on the intrinsic correlation between AEG decoding assisted by AA and binaural beamforming, the following two aspects are achieved by balancing EEG-assisted beamformer: (1) Allocation of auditory attention preference under speech fidelity constraints; (2) Reduction of noise and interference suppression.
- FIG. 1 is a block diagram of an exemplary embodiment of an ear-worn hearing system 100 including an EEG-assisted beamformer 108 and a linear transformation module 110 according to the present invention.
- the hearing system 100 also includes a microphone 102, a hearing system processing circuit 104, and a speaker 106.
- the EEG-assisted beamformer 108 may be provided in the hearing system processing circuit 104 or may be separately provided from the hearing system processing circuit 104.
- the EEG-assisted beamformer 108 is provided in the hearing system processing circuit 104 as an example for description.
- the microphone 102 shown in FIG. 1 represents M microphones, each of which receives an input sound and generates an electric signal representing the input sound.
- the processing circuit 104 processes the microphone signal (s) to generate an output signal.
- the speaker 106 uses the output signal to generate an output sound including the voice.
- the input sound may include various components such as speech and noise interference, as well as the feedback sound from the speaker 106 via a sound feedback path.
- the processing circuit 104 includes an adaptive filter to reduce noise and acoustic feedback.
- the adaptive filter includes an EEG-assisted beamformer 108. Further, FIG.
- a linear transformation module 110 configured to receive an EEG signal from a head of a hearing system user through a sensor located on the head and perform a linear transformation on the received EEG signal to obtain an optimized linear transformation Coefficient, the linear transformation coefficient reconstructs the envelope of the speech source according to the EEG signal to obtain a reconstructed envelope of the speech source, and the linear transformation module 110 is further configured to pass the reconstructed envelope to the EEG-assisted Beamformer 108.
- the processing circuit 104 receives the microphone signal
- the EEG-assisted beamformer 108 uses the microphone signal from the hearing system and the reconstructed envelope to provide an adaptive Binaural beamforming.
- FIG. 2A shows a schematic diagram of the working principle of an EEG-assisted beamformer of the present disclosure.
- the microphone signal of the input voice signal of the EEG-assisted beamformer 108 received by the EEG-assisted beamformer 108 uses a short-time Fourier transform. (STFT) can be expressed in the Time-Frequency Domain as:
- Represents a microphone signal at a frame l (each frame corresponds to N input signal samples in the time domain) and a frequency band ⁇ ( ⁇ 1, 2, ..., ⁇ ) Is the acoustic transfer function (ATF) of the k-th speech source, and Is the corresponding input speech signal in the time-frequency domain; and Represents background noise.
- the EEG-assisted beamformer 108 generates an output signal at each ear by linearly combining input speech signals, as shown in FIG. 2A. Specifically, let with Denote beamformers applied to the left and right ears in the frequency band w, respectively.
- the output signals at the left and right speakers are:
- the time domain representation of the beamforming output can be synthesized.
- L and R will be omitted for the rest of this article.
- the EEG-assisted beamformer 108 is configured to have means for constructing an optimization model and solving an optimization model, which are based on a regression model of AA decoding to establish an EEG-assisted AA from a signal processing perspective
- the inherent correlation between decoding and binaural beamforming and by balancing the following two aspects: (1) the allocation of auditory attention preferences under the constraints of speech fidelity; (2) reducing noise and interference suppression to obtain multiple input speech Beamforming weights for linearly combining signals.
- the optimization model includes an optimization formula for suppressing interference in multiple input speech signals and obtaining a beamforming weight coefficient.
- the processing circuit 104 is configured to further solve the optimization formula by using a low-complexity iterative algorithm such that the output signal of the EEG-assisted beamformer 108 satisfies the Audible Attention Preference Distribution and Noise Reduction Standards under Speech Fidelity Constraints.
- the linear transformation module 110 is configured to obtain an optimized linear transformation coefficient, thereby reconstructing the envelope of the speech source to obtain a reconstructed envelope of the speech source.
- a linear transform is used to convert the EEG signal to the envelope of the speech signal of the speech source, and then the optimization model is solved to perform the beamformer design.
- the use of EEG signals for beamformer design includes, but is not limited to, the linear transformation method disclosed in the embodiments of the present invention, and also includes other methods, such as a non-linear transformation or a method using a neural network.
- Equation 2 g i ( ⁇ ) is a linear regression coefficient corresponding to an EEG signal with a delay ⁇ , and E is a desired operation sign.
- Optimization formula 2 is a method for improving eeg-based auditory attention detecting Speech envelop activation method for auditory apocalypse based on EEG based auditory attention detection in the environment), IEEE Transactions on Neural Systems and Rehabilitation Engineering, 25 (5): 402-412, May 2017 (the above documents are incorporated by reference)
- the convex quadratic formula of the closed form solution given in the method disclosed in () for all purposes) is not described here.
- the optimal linear transformation coefficient is known among them, This linear transform coefficient reconstructs the envelope s a (t) of the participating speech source from the EEG signal.
- the envelope of the participating speech source can be reconstructed from the EEG signal to
- the intrinsic correlation between the EEG signal and the beamforming signal will be given.
- the physical meaning of optimization formula 2 is the reconstructed envelope There should be a strong correlation with the envelope s 1 (t) of the participating speakers.
- the beamforming output is actually a prescribed mix of beamformers for different kinds of input signals received by the microphone.
- s 1 (t) can be the main component at the beamforming output. Therefore, the natural and straightforward way to design beamformers with EEG signals is to maximize the reconstructed envelope of the speech source Pearson correlation with the envelope of the beamforming output.
- the EEG-assisted beamformer 108 is configured to obtain an envelope of a beamforming output. Specifically, from the perspective of signal processing, each time sample is represented as a function of the beamformer. It is assumed that the beamforming output corresponds to the time sampling indices t, t + 1, ..., t + N-1.
- Equation 3 Is the diagonal matrix used to form the analytic signal, Is the inverse of the discrete Fourier transform matrix (DFT matrix), and Is a diagonal matrix used to compensate the synthesis window used in the short-time Fourier transform (STFT) used to represent multiple input signals.
- DFT matrix discrete Fourier transform matrix
- STFT short-time Fourier transform
- Equation 6 assumes a reconstructed envelope of the speech source And beamforming output envelope Synchronize at the same sampling rate.
- the reconstructed envelope of the speech source Have the same sampling rate as the EEG signal (i.e. tens or hundreds of Hz), while the envelope of the beamforming output Corresponds to the audio sampling rate (eg, 16 kHz).
- An additional synchronization process is required, but this process does not change Equation 6, that is, resampling from Equation 4 based on the sample rate ratio between the input speech signal and the EEG signal
- the optimization formula of the EEG-assisted beamformer of the present invention combines the Pearson correlation coefficient ⁇ ( ⁇ w ( ⁇ ) ⁇ ) with the following two main factors:
- Equation 7 ⁇ ( ⁇ w ( ⁇ ) ⁇ ) represents the Pearson correlation coefficient defined in Equation 6, which is a smooth non-convex function on the beamforming weight coefficient ⁇ w ( ⁇ ) ⁇ ⁇ in all frequency bands.
- the EEG-assisted beamformer 108 is configured to obtain an optimization formula of the EEG-assisted beamformer 108 according to the above factors. Specifically, combining the formulas 7 and 8, an optimized formula for the EEG-assisted beamformer 108 according to the present invention can be obtained:
- 2 is the regular term of the optimization formula, where
- 2 represents the vector ⁇ [ ⁇ 1 , ⁇ 2 , ..., ⁇ K ] T European norm, which is a predetermined auditory attention sparse preference, the one toward a dispensing ⁇ k, ⁇ k and the other toward 0 is assigned.
- ⁇ > 0 and ⁇ ⁇ 0 are predetermined parameters for balancing denoising, assigning attention preferences, and controlling sparsity of attention preferences.
- the processing circuit 104 is configured to solve the optimization formula by using a low-complexity iterative algorithm (ie, well-known GPM and ADMM).
- Formula 9 is a non-convex formula due to the non-linear functions - ⁇ ( ⁇ w ( ⁇ ) ⁇ ) and - ⁇
- GPM takes advantage of guaranteed convergence (see DPBertsekas, Nonlinear programming, Athena scientific Belmont), Proposition 2.3 in 1999) to solve Equation 9. Since the main computational work of solving the formula 9 of the GPM is the projection on the polyhedron defined by formulas (7a) and (7b), using ADMM to solve the projection formula, this leads to a closed-form beamformer ⁇ w ( ⁇ ) ⁇ ⁇ Parallel implementation of the original update.
- the solution algorithm follows the standard update process of GPM and ADMM algorithms.
- Equation 9 the objective function in Equation 9 is expressed as:
- Equation 11 The augmented Lagrangian function for Equation 11 is:
- ⁇ k, ⁇ , and ⁇ are Lagrangian factors, which are respectively associated with equation constraints (7a) and (7b); ⁇ > 0 is a predefined parameter for the ADMM algorithm. Since L ⁇ is separable in the frequency band w for ⁇ w ( ⁇ ) ⁇ , the ADMM algorithm iteratively updates ( ⁇ w ( ⁇ ) ⁇ , ⁇ , ⁇ k, ⁇ ⁇ , ⁇ ) as:
- l is the iteration index.
- formula (12a) is a simple unconstrained convex quadratic formula with a closed form solution (using a low-complexity iterative algorithm).
- Formula (12b) is a convex quadratic formula with a non-negative constraint ⁇ 0, which is easy to solve. All ADMM updates use low-complexity iterative algorithms, and formulas (12a) and (12c) can be further implemented in parallel in actual applications to improve computing efficiency.
- FIG. 2A illustrates a schematic diagram of the working principle of an EEG-assisted beamformer of the present disclosure
- FIG. 2B is a flowchart corresponding to FIG. 2A, which illustrates a flowchart of an EEG-assisted beamforming method of the present disclosure , Which includes three steps.
- the three-channel voice signal is shown by way of example only in this embodiment, but the present invention is not limited thereto.
- a first step S1 the input speech signals y 1 (t), y 2 (t) and y M (t) received at the microphone are appropriately transformed to the time-frequency domain signal y 1 (l, ⁇ ) by the STFT, y 2 (l, ⁇ ) and y M (l, ⁇ ), and the EEG signal are appropriately transformed into the time domain through a pre-trained linear transformation and input to an EEG-assisted beamformer.
- the appropriately transformed signals (including the transformed input voice signal and the transformed EEG signal) are combined to design a beamformer using the above optimization criteria, the purpose of which is to utilize the AA contained in the EEG signal
- the information enhances the speech of the participating speakers to obtain beamforming weight coefficients w 1 ( ⁇ ), w 2 ( ⁇ ), and w M ( ⁇ ).
- the beamforming weight coefficients obtained by the designed EEG-assisted beamformer are applied to the SFTF transformed signals y 1 (l, ⁇ ), y 2 (l, ⁇ ), and y M ( l, ⁇ ) are combined to synthesize a beamforming output via ISTFT.
- FIG. 3 shows a top view of a simulated acoustic environment for comparing an EEG-assisted beamforming method and an SP-LCMV method according to an embodiment of the present application.
- the simulated acoustic environment the rectangular coordinate system shown in FIG. 3, a range of 5m * 5m on a horizontal plane at a certain height in the room is selected to represent a part of the room, as shown in FIG.
- Speech source (speaker), of which only P5 and P6 are the target speakers, and P11-P26 are background speakers to simulate background noise; the experiment participants are in the middle of the room; P5 and P6 are directly below the experiment participants And directly above and at a distance of 1m from the experiment participants; P11-P26 are evenly distributed on a circle with the center radius of the experiment participants being 2m, that is, 22.5 degrees between adjacent speakers, of which P25 is in the experiment participants Just above, as shown in Figure 3.
- EEG signals were collected from 4 normal listening experiment participants in a noisy and echogenic environment with multiple speakers.
- the experimental participants are located in the center of the room, with the speakers directly below and directly above the experimental participants (P5, P6). While the experimental participants listened to one of the two speakers, the other one was interference, using the remaining 16 speech sources distributed in the room to generate background noise.
- the sound intensity of the two speakers is set to be the same, and is 5dB higher than the background noise.
- a set of ER-3 plug-in headphones were used to present the obtained audio signals to the participants. The intensity of the audio signals was at a "loud but comfortable" level.
- the experimental participants were instructed to perform a binaural listening task while listening to one of the speakers.
- some experimental conditions and 4 experimental participants are selected from the EEG database for evaluation.
- each experimental participant participating in the experiment is required to focus attention on speakers P5 and P6 for 10 minutes each.
- the total time recorded for each experimental participant was 20 minutes.
- the 20-minute record is divided into 40 time periods of 30 seconds that do not overlap. Leave a cross-validation during these time periods to train optimized linear transformation coefficients And evaluate beamforming performance.
- the beamforming method according to the present invention will be evaluated based on the established EEG database.
- AA decoding and beamforming are usually combined in a separable manner, that is, the source separation method is used to extract the AA decoded from
- the difference in performance between the speaker's speech signal and beamforming based on the decoded AA uses a separable method based on linearly constrained minimum variance (LCMV) beamforming as a benchmark.
- LCMV linearly constrained minimum variance
- This method applies two different LCMV beamformers (i.e., one speech source is retained and another is rejected using linear constraints) to compare the separated signals with respect to the reconstructed envelope Pearson correlation separates the signals of the two speech sources and then decodes AA.
- One LCMV beamforming output with a large Pearson correlation is selected as the final beamforming output.
- SP Source Separation
- Intelligent weighted signal interference and noise ratio improvement (Intelligibility-weighted SINR, improvement (IW-SINRI) and intelligent weighted spectral distortion (intelligibility-weighted, spectral distortion) (IW-SD) are used as performance metrics to evaluate beamforming output signals .
- Equation 2 the EEG signal and the input signal received at the microphone were resampled at 20 Hz and 16 kHz, respectively.
- the expectation operation in Equation 2 is replaced by the average of the samples of the limited record samples, and ⁇ in Equation 2 is fixed at 5 * 10 -3 .
- a 512-point FFT with 50% overlap is used in the STFT (Hanning window).
- ⁇ att ( ⁇ unatt ) is the reconstructed envelope
- ⁇ att ( ⁇ unatt ) is the reconstructed envelope
- the solid lines and dots in FIG. 4 indicate data obtained for the beam forming method of the present application
- the dotted lines and box points indicate data obtained for the SP-LCMV method.
- ⁇ att ( ⁇ unatt ) is the reconstructed envelope
- the solid lines and dots in FIG. 4 indicate data obtained for the beam forming method of the
- the value of ⁇ reflects the confidence that the speech source may be a participating speech source.
- the method of the present invention has an IW-SINRI range from -2 to 8 dB. This is because the method of the present invention assigns AA preferences of participating speech sources with some values between 0 and 1.
- IW-SINRI is grouped into approximately -2 or 8dB.
- the method of the invention is bipolar and has results very similar to the SP-LCMV method.
- the percentage of the corresponding IW-SINRI time period greater than a certain threshold is used as the evaluation metric.
- the method of the present invention and the SP-LCMV method are compared with respect to a percentage of IW-SINRI greater than or equal to 0, 2, and 4 dB, where, as shown in the figure, for each The depth of the six bar graphs gradually decreases.
- ⁇ 0, the depth of the obtained six percentage bar graphs gradually decreases.
- the six bar graphs are from left to right: data obtained by the beamforming method of this application when IW-SINRI is greater than or equal to 0dB; data obtained by SP-LCMV method when IW-SINRI is greater than or equal to 0dB ; IW-SINRI is greater than or equal to 2dB, the data obtained by the beam forming method of this application; IW-SINRI is greater than or equal to 2dB, the data obtained by the SP-LCMV method; IW-SINRI is greater than or equal to 4dB, the application is targeted
- the data obtained by the beamforming method of the method; when the IW-SINRI is greater than or equal to 4dB, the data obtained by the SP-LCMV method is shown in the description labeled in the figure.
- the distribution of the bar graphs shown has a similar pattern.
- FIG. 6 shows the relationship between the IW-SD and Pearson correlation difference of the method of the present invention and the SP-LCMV method.
- the solid line and dot in FIG. Dashed and boxed dots represent the data obtained for the SP-LCMV method.
- the method of the present invention adjusts ⁇ k between 0 and 1.
- the speech signal at the beamforming output is scaled according to ⁇ k .
- the beamformer according to the embodiment of the present application is based on the EEG-assisted AA decoding work, and aims to improve the internal correlation between EEG-assisted AA decoding and binaural beamforming from the perspective of signal processing to improve the noise in multiple speakers Voice of participating speakers in the environment and reduce other impacts.
- the beamformer according to the embodiment of the present application based on the intrinsic correlation between AEG decoding assisted by AA and binaural beamforming, the following two aspects are achieved by balancing EEG-assisted beamformer: (1) Allocation of auditory attention preference under speech fidelity constraints; (2) Reduction of noise and interference suppression.
- the ear-worn hearing system referred to in this application includes a processor, which may be a DSP, a microprocessor, a microcontroller, or other digital logic.
- the signal processing cited in this application may be performed by a processor.
- the processing circuit 104 may be implemented on such a processor. Processing can be done in the digital domain, the analog domain, or a combination thereof. Processing can be done using subband processing techniques. Processing can be done using frequency or time domain methods. For simplicity, in some examples, block diagrams for performing frequency synthesis, frequency analysis, analog-to-digital conversion, amplification, and other types of filtering and processing may be omitted.
- the processor is configured to execute instructions stored in a memory.
- the processor executes instructions to perform several signal processing tasks.
- the analog component communicates with the processor to perform a signal task, such as a microphone receiving or receiver sound embodiment (ie, in an application using such a sensor).
- a signal task such as a microphone receiving or receiver sound embodiment (ie, in an application using such a sensor).
- implementation of the block diagrams, circuits, or processes presented herein may occur without departing from the scope of the subject matter of this application.
- a BTE hearing aid may include a device substantially behind or above the ear.
- Such a device may include a hearing aid with a receiver associated with the electronic part of the behind-the-ear (BTE) device or a hearing aid type with a receiver in the ear canal of the user, including but not limited to a built-in receiver (RIC) or in-ear Receiver (RITE) design.
- BTE behind-the-ear
- RITE in-ear Receiver
- the subject matter of this application can also generally be used in hearing aid devices, such as hearing aid devices of the cochlear implant type. It should be understood that other hearing aid devices not explicitly stated herein may be used in conjunction with the subject matter of this application.
- Embodiment 1 A beamformer includes:
- a device for constructing an optimization model and solving an optimization model which obtains a beamforming weight coefficient that linearly or non-linearly combines the plurality of input signals
- the optimization model includes an optimization formula for obtaining the beamforming weight coefficient
- the optimization formula includes establishing an association between the at least one EEG signal and a beamforming output, and optimizing the association so as to construct Beamforming weights associated with at least one EEG signal.
- Embodiment 2 The beamformer according to embodiment 1, wherein establishing the association between the at least one EEG signal and the beamforming output includes establishing the at least one using a non-linear transformation or a neural network method. Correlation between EEG signals and beamforming output.
- Embodiment 3 The beamformer according to Embodiment 1, wherein establishing an association between the at least one EEG signal and a beamforming output includes establishing a linear transformation to establish the at least one EEG signal and beamforming Association between outputs.
- Embodiment 4 The beamformer according to Embodiment 3, wherein the optimization formula includes a Pearson correlation coefficient:
- Embodiment 5 The beamformer according to Embodiment 4, further comprising means for receiving an envelope of a reconstructed speech signal of a participating speech source, and wherein the linear transform coefficient is based on optimization Obtaining an envelope of the reconstructed speech signal of the participating speech source according to the at least one EEG signal And the envelope of the reconstructed speech signal of the participating speech source is passed to the device for receiving the envelope of the reconstructed speech signal of the participating speech source,
- the optimized linear transformation coefficient is obtained by solving the following formula
- s a (t) Represents an envelope of a speech signal of the participating speech source corresponding to the plurality of input signals;
- g i ( ⁇ ) is a linear regression coefficient of the EEG signal corresponding to the EEG channel i with a delay ⁇ , and E is an expectation Operator; regular function The time smoothness of the linear regression coefficient g i ( ⁇ ) is defined; and ⁇ ⁇ 0 is a corresponding regular parameter.
- Embodiment 6 The beamformer according to Embodiment 5, wherein the parsed signal is expressed according to the beamforming weight coefficient ⁇ w ( ⁇ ) ⁇ ⁇ by discrete Fourier transform as:
- Is a diagonal matrix used to form the parsed signal Is the inverse of the discrete Fourier transform matrix
- Represents the plurality of input signals at a frame l and a frequency band ⁇ ( ⁇ 1, 2, ..., ⁇ ), and the frame l corresponds to N sampling time points t, t + 1, ..., t + N-1
- STFT short-time Fourier transform
- the parsed signal is further equivalently expressed as:
- Embodiment 7 The beamformer according to Embodiment 6, wherein the envelope of the beamforming output The sampling rate of is corresponding to the audio sampling rate of the plurality of input signals.
- Embodiment 8 The beamformer according to Embodiment 6, wherein the optimizing the association so as to construct a beamforming weight coefficient associated with at least one EEG signal includes maximizing the Pearson correlation coefficient ⁇ ( ⁇ w ( ⁇ ) ⁇ ) to extract auditory attention (AA) information contained in the at least one EEG signal.
- Embodiment 9 The beamformer according to Embodiment 8, wherein a robust equality constraint is applied during the maximizing the Pearson correlation coefficient ⁇ ( ⁇ w ( ⁇ ) ⁇ ) To control speech distortion,
- ⁇ [ ⁇ 1 , ⁇ 2 , ..., ⁇ K ] T is an additional variable, which represents the auditory attention preference among the multiple speech sources; h k ( ⁇ ) is the acoustics of the k-th speech source Transfer function; K is the number of the multiple speech sources.
- Embodiment 10 The beamformer according to Embodiment 9, wherein the optimization formula becomes:
- 2 is the regular term of the optimization formula, where
- 2 represents the additional variable ⁇ [ ⁇ 1 , ⁇ 2 , ..., ⁇ K ] T 's Euclidean norm; ⁇ > 0 and ⁇ 0 are preset parameters that are used to balance denoising, assign attention preferences, and control sparsity of attention preferences, and Means that the sum of the elements in the additional variable is 1.
- Embodiment 11 The beamformer according to Embodiment 10, wherein the optimization model is solved using a gradient projection method (GPM) and an alternating direction multiplier method (ADMM), which includes the following steps:
- GPM gradient projection method
- ADMM alternating direction multiplier method
- ⁇ k, ⁇ and ⁇ are Lagrangian factors, which are respectively associated with the equation constraints; ⁇ > 0 is a predefined parameter for the ADMM algorithm,
- Equation 12 (e) The result of Equation 12 is obtained.
- Embodiment 12 A beamforming method for a beamformer, comprising:
- EEG electroencephalogram
- the optimization model includes an optimization formula for obtaining the beamforming weight coefficient
- the optimization formula includes establishing an association between the at least one EEG signal and a beamforming output, and optimizing the association so as to construct Beamforming weights associated with at least one EEG signal.
- Embodiment 13 The beamforming method according to Embodiment 12, wherein establishing the association between the at least one EEG signal and the beamforming output includes establishing the at least one using a non-linear transformation or a neural network method. Correlation between EEG signals and beamforming output.
- Embodiment 14 The beamforming method according to Embodiment 12, wherein establishing an association between the at least one EEG signal and a beamforming output includes establishing a linear transformation to establish the at least one EEG signal and beamforming Association between outputs.
- Embodiment 15 The beamforming method according to Embodiment 14, wherein the optimization formula includes a Pearson correlation coefficient:
- Embodiment 16 The beamforming method according to Embodiment 15, wherein the beamforming method is based on an optimized linear transformation coefficient Obtaining an envelope of the reconstructed speech signal of the participating speech source according to the at least one EEG signal And the method further includes receiving an envelope of the reconstructed speech signal of the participating speech source,
- the optimized linear transformation coefficient is obtained by solving the following formula
- s a (t) Represents an envelope of a speech signal of the participating speech source corresponding to the plurality of input signals;
- g i ( ⁇ ) is a linear regression coefficient of the EEG signal corresponding to the EEG channel i with a delay ⁇ , and E is an expectation Operator; regular function The time smoothness of the linear regression coefficient g i ( ⁇ ) is defined; and ⁇ ⁇ 0 is a corresponding regular parameter.
- Embodiment 17 The beamforming method according to Embodiment 16, wherein the parsed signal is expressed by the discrete Fourier transform according to the beamforming weight coefficient ⁇ w ( ⁇ ) ⁇ ⁇ as:
- Is a diagonal matrix used to form the parsed signal Is the inverse of the discrete Fourier transform matrix
- Represents the plurality of input signals at the frame l and the frequency band ⁇ ( ⁇ 1, 2, ..., ⁇ ), the frame l corresponds to N sampling time points t, t + 1, ..., t + N-1
- STFT short-time Fourier transform
- the parsed signal is further equivalently expressed as:
- Embodiment 18 The beamforming method according to Embodiment 17, wherein the envelope of the beamforming output The sampling rate of is corresponding to the audio sampling rate of the plurality of input signals.
- Embodiment 19 The beamforming method according to Embodiment 17, wherein the optimizing the association so as to construct a beamforming weight coefficient associated with at least one EEG signal includes maximizing the Pearson correlation coefficient ⁇ ( ⁇ w ( ⁇ ) ⁇ ) to extract auditory attention (AA) information contained in the at least one EEG signal.
- Embodiment 20 The beamforming method according to Embodiment 19, wherein a robust equality constraint is applied in the process of maximizing the Pearson correlation coefficient ⁇ ( ⁇ w ( ⁇ ) ⁇ ) To control speech distortion,
- ⁇ [ ⁇ 1 , ⁇ 2 , ..., ⁇ K ] T is an additional variable, which represents the auditory attention preference among the multiple speech sources; h k ( ⁇ ) is the acoustics of the k-th speech source Transfer function; K is the number of the multiple speech sources.
- Embodiment 21 The beamforming method according to Embodiment 20, wherein the optimization formula becomes:
- 2 is the regular term of the optimization formula, where
- 2 represents the additional variable ⁇ [ ⁇ 1 , ⁇ 2 , ..., ⁇ K ] T 's Euclidean norm; ⁇ > 0 and ⁇ 0 are preset parameters that are used to balance denoising, assign attention preferences, and control sparsity of attention preferences, and Means that the sum of the elements in the additional variable is 1.
- Embodiment 22 The beamforming method according to Embodiment 21, wherein the optimization model is solved by using a gradient projection method (GPM) and an alternating direction multiplier method (ADMM), which includes the following steps:
- GPM gradient projection method
- ADMM alternating direction multiplier method
- Is the gradient of the objective function at x t , [ ⁇ ] + represents the equality constraint with The projection operation, s is constant, and ⁇ t is determined according to the rules Armijo step size;
- ⁇ k, ⁇ and ⁇ are Lagrangian factors, which are respectively associated with the equation constraints; ⁇ > 0 is a predefined parameter for the ADMM algorithm,
- Equation 12 (e) The result of Equation 12 is obtained.
- Embodiment 23 An ear-mounted hearing system includes:
- a microphone configured to receive multiple input signals from multiple speech sources
- An EEG signal receiving interface configured to receive information from one or more EEG electrodes and linearly or non-linearly transform the EEG information to form at least one EEG signal;
- a beamformer that receives the plurality of input signals and the at least one EEG signal, and outputs a beamforming weight coefficient
- a synthesis module that linearly or non-linearly combines the multiple input signals and the beamforming weight coefficients to form a beamforming output
- a speaker configured to convert the beamforming output into an output sound
- the beamformer is the beamformer according to any one of embodiments 1-11.
- Embodiment 24 A computer-readable medium including instructions that, when executed by a processor, enable the processor to perform the beamforming method according to any one of embodiments 12-22.
Landscapes
- Health & Medical Sciences (AREA)
- Physics & Mathematics (AREA)
- Engineering & Computer Science (AREA)
- General Health & Medical Sciences (AREA)
- Signal Processing (AREA)
- Neurosurgery (AREA)
- Otolaryngology (AREA)
- Acoustics & Sound (AREA)
- Life Sciences & Earth Sciences (AREA)
- Psychiatry (AREA)
- Medical Informatics (AREA)
- Veterinary Medicine (AREA)
- Public Health (AREA)
- Animal Behavior & Ethology (AREA)
- Biophysics (AREA)
- Pathology (AREA)
- Biomedical Technology (AREA)
- Heart & Thoracic Surgery (AREA)
- Surgery (AREA)
- Molecular Biology (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Mathematical Physics (AREA)
- Artificial Intelligence (AREA)
- Physiology (AREA)
- Circuit For Audible Band Transducer (AREA)
- Psychology (AREA)
Abstract
本申请公开了一种多模式波束形成器,包括:用于接收多模式输入信号的装置;用于构建优化模型和求解优化模型的装置,其获得对所述多模式输入信号进行线性或非线性组合的波束形成权系数。所述优化模型包括用于获得所述波束形成权系数的优化公式。所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
Description
本发明涉及助听技术领域,具体地,涉及一种用在耳戴式(ear-worn)听力系统中的脑电图辅助的多模式波束形成器以及波束形成方法以及包括该波束形成器的耳戴式听力系统。
耳戴式听力系统用来通过传递放大的声音至遭受听觉损失的人的耳道来帮助他们。患者的耳蜗外毛细胞的损坏导致患者的听觉的频率分辨率损失。随着这种情况发展,患者难于区分语音和环境噪声。简单的放大解决不了这个问题。因此,需要帮助这类患者明白嘈杂环境下的语音。通常在耳戴式听力系统中应用波束形成器,以区分语音和噪声,从而帮助患者明白嘈杂环境下的语音。
一方面,在听力系统中应用(由麦克风阵列提供的)空间多样性的双耳波束形成技术是一项公知技术,其能明显改善使用者在嘈杂的多个讲话者环境下对目标讲话者的语义理解。然而,广泛使用的两类波束形成器,如多通道维纳滤波器(Multi-channel Wiener Filter,MWF)波束形成器和最小方差无失真响应(Minimum Variance Distortionless Response,MVDR)波束形成器,需要关于目标讲话者的先验信息,即,利用传统信号处理方法来提取讲话者的空间先验信息。具体地,MWF波束形成器需要针对参与的讲话者(Attended Talker)的语音活跃检测(Voice Activity Detection,VAD),而MVDR波束形成器需要识别参与的讲话者的声学传递函数(Acoustic Transfer Function,ATF)。在实际应用中,从嘈杂的多个讲话者环境精确地获得这种空间先验信息是不容易的。
另一方面,人脑在嘈杂的多个讲话者环境下识别和跟踪单个讲话者的机理是最近几十年活跃的研究课题。最近几年,通过使用者的脑电图信号(EEG)提取其在多个讲话者环境中的听觉注意力(Auditory Attention,AA),取得了实质性进展。例如,在S.Van Eyndhoven,T. Francart和A.Bertrand,EEG-informed attended speaker extraction from recorded speech mixtures with application in neuro-steered hearing prostheses(来自与在神经控制的听力修复中的应用的记录的语音混合的EEG信息的参与的扬声器提取),IEEE Transactions on Biomedical Engineering,64(5):1045-1056,2017年5月和N.Das,S.Van Eyndhoven,T.Francart和A.Bertrand,EEG-based attention-driven speech enhancement for noisy speech mixtures using n-fold multi-channel wiener filters(用于使用n重多通道维纳滤波器的嘈杂语音混合的基于EEG的注意力驱动的语音增强),In 2017 25
thEuropean Signal Processing Conference(EUSIPCO)中,1660-1664页,2017年8月(上述文件通过引用并入本文以用于所有目的)中公开了基于EEG辅助的AA解码波束形成方法,这些方法直接从EEG信号中获取使用者AA。但是这些方法均以分步骤的方式实现波束形成,即,第一步将通过使用者EEG信号提取(解码)AA,第二步再根据解码的AA实现波束形成或降低噪声。由于分步的实现过程,这些方法有以下两个缺点:
错误的注意力解码的敏感性:由于EEG信号反映人脑的复杂的活动,解码AA可能不总是正确的。一旦AA解码错误,真正目标讲话者会在波束形成阶段被抑制,这对于实际应用来说是非常糟糕的情况。
额外的源分离的过程:在AA解码的步骤中,为了获得每个语音源的包络信息,需要从麦克风接收到的混合的输入语音信号中提取每个语音源的信息,这就带来了额外的盲源分离需求,需要额外且复杂的信号处理方法以实现。
发明内容
因此,为了克服上述缺陷,本申请致力于将AA解码和波束形成整合在一个优化模型中,并以AA偏好的形式分配使用者对不同语音源的注意力偏好。具体地,通过从信号处理的角度建立基于EEG辅助的AA解码与双耳波束形成之间的内在关联,提出了一种用于耳戴式听力系统中的听觉注意力解码和自适应双耳波束形成的联合算法,该方法能够有效利用EEG信号中包含的AA信息,避免了错误AA解码情况下的敏感性问题且不需要额外的盲源分离过程。
将本发明构思的波束形成器命名为脑电图辅助的双耳波束形成器。 利用低复杂度的迭代算法(即,公知的梯度投影法(Gradient Projection Method,GPM)和交替方向乘子法(Alternating Direction Method of Multipliers,ADMM))求解所提出的公式。该迭代算法提供了一种可以在实际耳戴式听力系统中实现的有效的波束形成器实施方式。
根据本发明的一个实施例,公开了一种波束形成器,包括:用于接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号的装置;和用于构建优化模型和求解优化模型的装置,其获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
根据本发明的另一个实施例,公开了一种用于波束形成器的波束形成方法,包括:接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号;和通过构建优化模型和求解优化模型获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
根据本发明的又一个实施例,公开了一种耳戴式助听系统,包括:麦克风,其配置为接收来自多个语音源的多个输入信号;脑电图信号接收接口,其配置为接收来自一个或多个脑电图电极的信息并且将脑电图信息进行线性或非线性变换以形成至少一个脑电图(EEG)信号;波束形成器,其接收所述多个输入信号和所述至少一个EEG信号,并且输出波束形成权系数;以及合成模块,其将所述多个输入信号和所述波束形成权系数进行线性或非线性合成,以形成波束形成输出,扬声器,其配置为将所述波束形成输出转换为输出声音,其中,所述波束形成器为根据本发明的波束形成器。
根据本发明的进一步的实施例,公开了一种包括指令的计算机可读介质,所述指令当被处理器执行时能够使得所述处理器执行根据本发明的波束形成方法。
与现有技术中的以分步骤的方式将EEG信号并入波束形成(即, 先解码AA,然后进行波束形成)的方法相比,本发明将AA解码与波束形成整合在一个优化模型中,从而能够有效利用EEG信号中包含的AA信息,避免了错误AA解码情况下的敏感性问题且不需要额外的盲源分离过程。
图1是根据本发明的耳戴式听力系统的示例实施例的框图;
图2A示出本发明的脑电图辅助的波束形成器的工作原理的示意图;
图2B示出通过图2A的脑电图辅助的波束形成器执行的波束形成方法的示意流程图;
图3示出了用于对本发明的脑电图辅助的波束形成方法与源分离(source separation,SP)-线性约束最小方差(linearly constrained minimum variance,LCMV)方法进行比较的模拟的声学环境的俯视图;
图4示出针对本发明的波束形成方法和SP-LCMV方法的IW-SINRI与Pearson相关的差的关系;
图5示出针对本发明的波束形成方法和SP-LCMV方法的关于大于等于0dB、2dB、4dB的IW-SINRI的百分比;和
图6示出针对本发明的波束形成方法和SP-LCMV方法的IW-SD与Pearson相关的差的关系。
现在将参照以下实施例更加详细地描述本公开。应当注意的是,在本文中,一些实施例的以下描述仅仅是以示意和说明为目的而呈现的。其并非意为详尽的或者限于所公开的精确形式。
在本申请中所示出的数学公式中,粗体小写字母表示向量,粗体大写字母表示矩阵;H是共轭转置标记,T是转置标记;所有n维复向量的集合由
 表示;
 是
 的第i个元素。本申请的以下具体实施方式引用附图中的主题,通过例示的方式,本申请的说明书附图示出可实施本申请的主题的具体方面和实施例。这些实施例被充分描述以使本领域技术人员实施本申请的主题。对本公开的“一个(an或one)”或“各种”实施例的引用不必针对相同的实施例,并且这种引用预期一个以上的实施例。以下具体实施方式是说明性的并且不以限制意义被采用。
在下文中,将呈现用于描述根据本申请实施例的波束形成器的数学公式。本申请实施例的波束形成器旨在通过从信号处理的角度建立基于EEG辅助的AA解码与双耳波束形成之间的内在关联,改善在嘈杂的多个讲话者环境下参与的讲话者的语音并降低其他影响。为了有效利用EEG信号中包含的AA信息,在根据本申请实施例的波束形成器中,基于EEG辅助的AA解码与双耳波束形成之间的内在关联,通过平衡以下两个方面来实现所述脑电图辅助的波束形成器:(一)语音保真约束下的听觉注意力偏好分配;(二)降低噪声和干扰抑制。
图1是根据本发明的耳戴式听力系统100的示例实施例的框图,该听力系统100包括脑电图辅助的波束形成器108和线性变换模块110。听力系统100还包括:麦克风102,听力系统处理电路104和扬声器106。所述脑电图辅助的波束形成器108可以设置在听力系统处理电路104中,也可以与听力系统处理电路104分开设置。以下说明中,以所述脑电图辅助的波束形成器108设置在听力系统处理电路104中为例进行说明。在一个实施例中,多个讲话者环境中有K个语音源,也称为讲话者,其包括目标讲话者和背景讲话者(其模拟背景噪声),当目标讲话者之一与耳戴式听力系统使用者交谈时,该目标讲话者称为参与的讲话者,而其他目标讲话者视为干扰(也称为未参与的讲话者)。图1中所示的麦克风102表示M个麦克风,均接收输入声音并产生表示所述输入声音的电信号。处理电路104处理(一个或更多个)麦克风信号以产生输出信号。扬声器106使用所述输出信号产生包括所述语音的输出声音。在各种实施例中,输入声音可包括各种分量,如语音和噪声干扰,以及经由声音反馈路径来自扬声器106的所反馈的声音。处理电路104包括自适应滤波器以降低噪声和声音反馈。在所示实施例中,自适应滤波器包括脑电图辅助的波束形成器108。进一步地,图1还示出线性变换模块110,其经配置以通过位于头部的传感器从听力系统使用者的头部接收EEG信号并对接收到的EEG信号进行线性变换,以获知优化线性变换系数,该线性变换系数根据EEG信号重新构造语音源的包络,以得到语音源的重新构造的包络,并且线性变换模块110进一步经配置以将重新构造的包络传递至脑电图辅助的波束形成器108。在各种实施例中,在助听系统100被实施时,处理电路104接收麦克风信号,且脑电图辅助的波束形成器108利用来自听力系统的麦克风信号和重新构造的包络提供自适应的双耳波束形成。
图2A示出了本公开的脑电图辅助的波束形成器工作原理的示意图。在本发明的实施例中,结合图1所示,由脑电图辅助的波束形成器108接收的作为脑电图辅助的波束形成器108的输入语音信号的麦克风信号使用短时傅里叶变换(STFT)在时频域(Time-Frequency Domain)中可表示为:

其中,
 表示帧l(每帧对应于时域中N个输入信号采样)和频带ω(ω=1,2,…,Ω)处的麦克风信号;
 是第k个语音源的声学传递函数(ATF),且
 是时频域下的对应的输入语音信号;且
 表示背景噪声。附图2A中仅以示例方式示出了麦克风信号y
1(t),y
2(t)和y
M(t)和相应的时频域中的信号y
1(l,ω),y
2(l,ω)和y
M(l,ω)。
在本发明的实施例中,脑电图辅助的波束形成器108通过将输入语音信号线性组合而产生了每个耳朵处的输出信号,如图2A所示。具体地,令
 和
 分别表示在频带w应用于左耳和右耳的波束形成器。左扬声器和右扬声器处的输出信号为:

通过对{z
L(l,ω)}
l,ω和{z
R(l,ω)}
l,ω应用逆STFT(ISTFT),能够合成波束形成输出的时域表示。为简化符号,本文余下部分将省略L和R。通过简单规定听力系统左侧或右侧上的参考麦克风,可将本发明的设计标准应用于左耳或右耳。
在本发明的实施例中,脑电图辅助的波束形成器108经配置以具有用于构建优化模型和求解优化模型装置,其基于AA解码的回归模型,从信号处理的角度建立EEG辅助的AA解码与双耳波束形成之间的内在关联,并通过平衡以下两个方面:(一)语音保真约束下的听觉注意力偏好分配;(二)降低噪声和干扰抑制,获得对多个输入语音信号进行线性组合的波束形成权系数。其中,优化模型包括用于对多个输入语音信号中的干扰进行抑制并获得波束形成权系数的优化公式。在各种实施例中,处理电路104经配置以进一步通过利用低复杂度的迭代算法求解该优化公式,使得所述脑电图辅助的波束形成器108的输出信号满足关于所述输出信号中的语音保真约束下的听觉注意力偏好分配和降低噪声规定的标准。
在本公开的实施例中,线性变换模块110经配置以获知优化线性变 换系数,由此重新构造语音源的包络,以得到语音源的重新构造的包络。换句话说,在本公开的实施例中,用线性变换把脑电图信号转换到语音源的语音信号的包络,然后通过求解优化模型以进行波束形成器设计。另外,将脑电图信号用于波束形成器设计包括但不限于本发明的实施例所公开的线性变换方法,还包括其他方法,如,非线性变换,或者用神经网络的方法。具体地,令
 为使用者在时刻t(t=1,2,…)时EEG通道i(i=1,2…,C)的EEG信号,并假定讲话者1为参与的讲话者(与听力系统使用者交谈的目标讲话者),其包络为s
1(t),且令s
a(t)表示对应于时域中的输入语音信号的参与语音源的语音信号的包络。以均方差而言,给出优化模型公式:
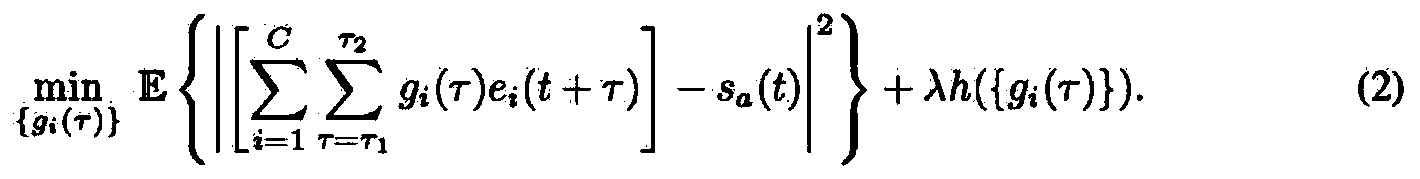
在公式2中,g
i(τ)是对应于具有延迟τ的EEG信号的线性回归系数,E是期望运算符号。正则函数
 规定线性回归系数g
i(τ)的时间平滑偏好,表示g
i(τ)-g
i(τ+1)不能太大,且λ≥0是对应的正则参数,且
 为EEG信号,其具有不同的延迟τ=τ
1,τ
1+1,…,τ
2。优化公式2是具有在(W.Biesmans,N.Das,T.Francart,and A.Bertrand,Auditory-inspired speech envelope extraction methods for improved eeg-based auditory attention detection in a cocktail party scenario(用于改善鸡尾酒会环境中的基于EEG的听觉注意力检测的听觉启示的语音包络激活方法),IEEE Transactions on Neural Systems and Rehabilitation Engineering,25(5):402-412,2017年5月(上述文件通过引用并入本文以用于所有目的)中公开的)方法中给出的封闭形式的解的凸二次公式,在此不进行描述。以此方式,获知优化线性变换系数
 其中,
 该线性变换系数根据EEG信号重新构造参与的语音源的包络s
a(t)。
基于获知的优化线性变换系数
 参与的语音源的包络可根据EEG信号被重新构造为

接下来,将给出EEG信号与波束形成信号之间的内在关联。直观地,优化公式2的物理含义是重新构造的包络
 应当具有与参与的讲话者的包络s
1(t)的强的相关。另一方面,波束形成输出实际是由麦克风接收的不同种类的输入信号的波束形成器规定的混合。在波束形成器的适当规定的情况下,s
1(t)能够是波束形成输出处的主要分量。因此,用于利用EEG信号设计波束形成器的自然且直接的方式是最大化语音源的重新构造的包络
 和波束形成输出的包络之间的Pearson相关。
为此,首先,给出时域下的波束形成输出的包络的数学公式。在本公开的实施例中,脑电图辅助的波束形成器108经配置以得到波束形成输出的包络。具体地,从信号处理的角度,每个时间采样被表示为波束形成器的函数。假设波束形成输出对应于时间采样指数t,t+1,…,t+N-1。令z(t),z(t+1),…,z(t+N-1)表示时域下的波束形成输出,则其包络实际是对应的解析信号形式
 的绝对值,其能够通过离散傅里叶变换(DFT)根据波束形成权系数{w(ω)}
ω被表示为:

在公式3中,
 是用于形成解析信号的对角矩阵,
 是离散傅里叶变换矩阵(DFT矩阵)的逆,而
 是用于补偿在用于表示多个输入信号所使用的短时傅里叶变换(STFT)中使用的合成窗的对角矩阵。为了简化符号,公式3简写为:

其中,
 是所要求解的波束形成权系数,且
 由{y(l,ω)}
ω和矩阵D
W,F和D
H中的系数确定。通过公式3和4,波束形成输出的包络表示为:

进一步地,在本公开的实施例中,脑电图辅助的波束形成器108经配置以得到由线性变换模块110所传递的重新构造的包络
 和波束形成输出的包络
 之间的Pearson相关。具体地,对于给定的时间段t=t
1,t
1+1,...,t
2,相应语音源的包络
 和波束形成输出的包络
 之间的Pearson相关系数表示为:

其中,
 和

注意,公式6假设语音源的重新构造的包络
 和波束形成输出的包络
 以相同的采样率同步。实际上,语音源的重新构造的包络
 具有与EEG信号相同的采样率(即,几十或几百Hz),而波束形成输出的包络
 对应于音频采样率(如,16kHz)。需要额外的同步过程,但该过程不改变公式6,即,根据输入语音信号和EEG信号之间的采样率比从公式4中重新采样

接着,通过最大化Pearson相关系数κ({w(ω)}),提取EEG信号中包含的AA信息以设计波束形成器。然而,双耳波束形成器的实际设计还需要若干其他不可忽视的考虑,即,语音失真、降低噪声和干扰抑制等。因此,本发明的脑电图辅助的波束形成器的优化公式将Pearson相关系数κ({w(ω)})与以下两个主要因素组合:
(1)语音保真约束下的听觉注意力偏好分配:从信号处理的角度,仅最大化Pearson相关系数κ({w(ω)})来设计波束形成器{w(ω)}
ω可导致每个语音源的不受控的语音失真。由于允许在不同频带之间的w(ω)
Hh
k(ω)处的空间响应的任何变化,因此,为了控制语音失真,一组鲁棒的等式约束
 经施加以保证第k个语音源的所有频带上的空间响应共用公共的实值α
k。这种等式约束表示在波束形成输出处的第k个语音源的输入语音信号的分量仅由α
k缩放而不具有任何频率失真。在上述考虑下,听觉注意力偏好分配被公式化为:


在公式7中,κ({w(ω)})表示公式6中限定的Pearson相关系数,其是在所有频带上的关于波束形成权系数{w(ω)}
ω的平滑的非凸函数。额外的变量α=[α
1,α
2,…,α
K]
T以及约束(7a)保证在波束形成输出处的K个语音源的输入语音信号由α线性组合,且公式7b表示向量α=[α
1,α
2,…,α
K]
T中的元素的和为1。以此方式,α实际表示K个语音源中的听觉注意力偏好。
(2)降低噪声和干扰抑制:除了调整听觉注意力,还考虑背景噪声 的能量以最小方差的形式减少:

其中,
 是背景噪声相关矩阵。
进一步地,在本公开的实施例中,脑电图辅助的波束形成器108经配置以根据以上因素得到脑电图辅助的波束形成器108的优化公式。具体地,组合公式7和8,可得到根据本发明的用于脑电图辅助的波束形成器108的优化公式:

在公式9中,额外的正则项-γ||α||
2为优化公式的正则项,其中,||·||
2表示向量α=[α
1,α
2,…,α
K]
T的欧式范数,其规定听觉注意力的稀疏偏好,该项将一个α
k朝向1分配,而将其他的α
k朝向0分配。μ>0和γ≥0是预定参数,其用于平衡去噪、分配注意力偏好和控制注意力偏好稀疏度。
在各种实施例中,处理电路104经配置以通过利用低复杂度的迭代算法(即,公知的GPM和ADMM)求解该优化公式。在本发明的实施例中,由于非线性函数-μκ({w(ω)})和-γ||α||
2,公式9是非凸公式。由于其约束偏好于有利形式,即,在公式7a中在频带w上关于波束形成器{w(ω)}
ω的可分离的线性约束,因此,采用GPM来求解,通过采用该可分离的属性,其承认计算上有效的实施方式。在适当步长规则的情况下(即,在试验中采用Armijo(阿米霍)规则),GPM利用保证的收敛性(见D.P.Bertsekas,Nonlinear programming(非线性规划),雅典娜科学贝尔蒙特(Athena scientific Belmont),1999年中的命题2.3)求解公式9。由于GPM求解公式9的主要计算工作是由公式(7a)和(7b)限定的多面体上的投影,使用ADMM来求解该投影公式,这导致关于封闭形式的波束形成器{w(ω)}
ω的原始更新的并行实施方式。求解算法遵从GPM和ADMM算法的标准更新过程。
下面将介绍求解根据本发明的用于脑电图辅助的波束形成器108的优化公式的具体过程。具体地,将公式9中的目标函数表示为:

并令

其为目标函数f({w(ω)},α)的梯度,其中,
 (或
 )表示关于w(ω)(或α)的梯度分量。GPM将
 迭代地更新为:


其中,t为迭代指数,
 为x
t处的目标函数f({w(ω)},α)的梯度,[·]
+表示对等式约束(7b)和(7a)的投影运算,s为预定的正标量(常数),且λ
t为根据Armijo规则确定的步长。上述GPM更新的主要计算过程是对公式(10a)中的投影运算。接着,将针对公式(10a)导出ADMM算法,其是低复杂度的迭代算法并接受频带上的并行实施方式。
公式(10a)中的投影运算等同于以下凸优化方程(省略迭代指数t)


针对方程11的增广拉格朗日函数为:

其中,ζ
k,ω和η为拉格朗日因子,其分别与等式约束(7a)和(7b)相关联;ρ>0是针对ADMM算法的预定义的参数。由于针对{w(ω)}在频带w上L
ρ是可分离的,ADMM算法将({w(ω)},α,{ζ
k,ω},η)迭代地更新为:


η
l+1=η
l+ρ(1
Tα-1) (12d)
其中,l为迭代指数。
注意,公式(12a)为简单的无约束的凸二次公式,其具有封闭形式的解(利用低复杂度的迭代算法)。公式(12b)为具有非负约束α≥0的凸二次公式,其是容易求解的。所有的ADMM更新利用低复杂度的迭代算法,且公式(12a)和(12c)能够在实际应用中进一步并行实施以提高计算效率。
在本发明的实施例中,从信号处理的角度建立EEG信号与波束形成信号之间的内在关联并将AA解码和波束形成集成在单个优化模型(公式 9)中。图2A示出了本公开的脑电图辅助的波束形成器工作原理的示意图,图2B是与图2A对应的流程图,其示出了本公开的脑电图辅助的波束形成方法的流程图,其包括三个步骤。如图2A和2B所示,本实施例中仅仅以示例方式示出了三通道的语音信号,但是本发明不限于此。在第一步骤S1中,麦克风处接收的输入语音信号y
1(t),y
2(t)和y
M(t)通过STFT适当地变换至时频域的信号y
1(l,ω),y
2(l,ω)和y
M(l,ω),以及EEG信号通过预训练的线性变换适当地变换至时域并且输入至脑电图辅助的波束形成器。在第二步骤S2中,适当变换的信号(包括经过变换的输入语音信号和经过变换的EEG信号)被组合以利用如上的优化标准设计波束形成器,其目的在于通过利用EEG信号中包含的AA信息增强参与的讲话者的语音,以得到波束形成权系数w
1(ω),w
2(ω)和w
M(ω)。在最后一个步骤S3中,应用所设计的脑电图辅助的波束形成器获得的波束形成权系数对经过SFTF变换的信号y
1(l,ω),y
2(l,ω)和y
M(l,ω)进行组合以经由ISTFT合成波束形成输出。
下面将描述EEG数据库,从该EEG数据库选取实验参与者进行后续实验以体现根据本发明的波束形成方法的性能优势。图3示出了用于对根据本申请实施例的脑电图辅助的波束形成方法与SP-LCMV方法进行比较的模拟的声学环境的俯视图。在所述模拟的声学环境(如图3所示的直角坐标系,选取房间内某一高度的水平面上的5m*5m的范围表示房间的一部分)中,如图3所示,共包括18个语音源(讲话者),其中只有P5和P6为目标讲话者,P11-P26均为背景讲话者,用以模拟背景噪声;实验参与者在房间中间;P5和P6分别在实验参与者的正下方和正上方且在距离实验参与者1m的位置处;P11-P26均匀分布在以实验参与者为圆心半径为2m的圆周上,即,相邻扬声器之间呈22.5度,其中,P25在实验参与者正上方,如图3所示。
在多个讲话者的嘈杂且有回声的环境下,从4个正常听力实验参与者收集EEG信号。实验参与者位于房间的中心位置处,其中讲话者在实验参与者正下方和正上方(P5,P6)。在实验参与者倾听两个讲话者之一的说话时,两个讲话者中的另一个就是干扰,使用分布在房间中的其余16个语音源生成背景噪声。两个讲话者说话声音大小强度设定为一样,且高于背景噪声5dB。实验中使用一组ER-3插入式耳机将所得到的音频信号呈献给实验参与者,音频信号的强度处于“大声但舒适”的水平。
指示实验参与者进行双耳听力任务且同时倾听讲话者之一的说话。
具体地,在本发明的实施例中,从EEG数据库选择部分实验条件以及4个实验参与者用于评估。在本发明的实施例中,每个参与实验的实验参与者被要求将注意力集中在讲话者P5和P6各10分钟。针对每个实验参与者记录的总时间为20分钟。将20分钟的记录分成不重叠的长度30秒的40个时间段。这些时间段中的留一交叉验证用来训练优化线性变换系数
 并评估波束形成性能。具体地,对于每个时间段,通过将其相应的30秒EEG信号和训练的
 并入波束形成过程,
 对所有其他时间段训练,且波束形成性能对自身评估。
使用64通道的头皮EEG系统以10khz的采样频率记录实验参与者的响应。所有记录在脑产品硬件上完成。
以此方式,建立EEG数据库。下面将根据所建立的EEG数据库对根据本发明的波束形成方法进行评估。
具体地,在本发明的实施例中,为了研究根据本发明的波束形成方法和其他可分离方法(AA解码和波束形成通常以可分离的方式组合,即,使用源分离方法提取AA解码的来自讲话者的语音信号,然后基于解码的AA进行波束形成)之间的性能差别,使用基于线性约束最小方差(linearly constrained minimum variance,LCMV)波束形成的可分离方法作为基准。该方法应用两个不同的LCMV波束形成器(即,使用线性约束保留一个语音源且拒绝另一个语音源)来通过比较分离的信号关于重新构造的包络
 的Pearson相关而分离两个语音源的信号且然后解码AA。具有较大Pearson相关的一个LCMV波束形成输出被选择作为最终波束形成输出。为了简便起见,将该方法作为源分离(SP)-LCMV方法。
智能加权的信号干扰和噪声比改善(Intelligibility-weighted SINR improvement,IW-SINRI)和智能加权的谱失真(intelligibility-weighted spectral distortion,IW-SD)被用作性能的度量标准以评估波束形成输出信号。
在本实验中,EEG信号和麦克风处接收到的输入信号分别以20Hz和16kHz重新采样。在线性回归系数g
i(τ)的训练阶段,在公式2中使用所有C=63个EEG通道,且EEG信号的延迟针对每个EEG通道被规定为0-250ms(其对应于20Hz采样率下的τ=0,1,…,5)。公式2中的期望运算由有限记录样本的样本平均替换,且公式2中的λ是固定的,为5*10
-3。在波束形成评估阶段,具有50%重叠的512点FFT用在STFT(汉宁(Hanning) 窗)中。
图4示出本发明的波束形成方法和SP-LCMV方法在处理AA信息的不确定性方面的语音增强行为的差异,其示出IW-SINRI与Pearson相关的差Δρ=ρ
att-ρ
unatt的关系。其中,ρ
att(ρ
unatt)是重新构造的包络
 与参与的(未参与的)讲话者的输入信号之间的Pearson相关,其由适当的LCMV波束形成器从麦克风信号分离。另外,图4中的实线和圆点表示针对本申请的波束形成方法所得到的数据,而虚线和方框点表示针对SP-LCMV方法所得到的数据。特别地,如图4中所示,对于实验参与者2,在γ=10时,通过两种方法所得到的实线和虚线几乎重合。在EEG信号中包含的AA信息通过获知的优化线性变换系数
 根据包络
 编码,在某些方面,Δρ的值反映其中语音源可能是参与的语音源的置信度。根据图4,能观察到,在γ=0时,本发明的方法的IW-SINRI范围从-2至8dB。这是因为本发明的方法为参与的语音源分配具有在0和1之间的一些值的AA偏好。对于SP-LCMV方法,由于其分离的AA解码过程,IW-SINRI被分组为大约-2或8dB。在γ增加到100时,本发明的方法为双极形式并具有与SP-LCMV方法非常类似的结果。有意思的观察是在γ=0时,IW-SINRI与Δρ之间的近似线性相关能够被观察到,这展示出本发明的方法捕获AA信息的不确定性的能力。Δρ越大,参与的语音源的AA的置信度越高,并且因此实现较高的IW-SINRI。
由于本发明的方法以柔和方式增强语音,因此,为了定量评估其语音增强能力,使用大于一定阈值的对应的IW-SINRI的时间段的百分比作为评估度量标准。具体地,在图5中比较本发明的方法和SP-LCMV方法关于大于等于0、2、4dB的IW-SINRI的百分比,其中,如图所示,针对每个实验参与者的每个γ,六个条形图的深度逐渐减轻,具体地,如,对于图5中的(a)实验参与者1而言,在γ=0时,所得的六个百分比的条形图的深度逐渐减轻,并且六个条形图从左至右依次是:IW-SINRI大于等于0dB时,针对本申请的波束形成方法所得到的数据;IW-SINRI大于等于0dB时,针对SP-LCMV方法所得到的数据;IW-SINRI大于等于2dB时,针对本申请的波束形成方法所得到的数据;IW-SINRI大于等于2dB时,针对SP-LCMV方法所得到的数据;IW-SINRI大于等于4dB时,针对本申请的波束形成方法所得到的数据;IW-SINRI大于等于4dB时,针对SP-LCMV方法所得到的数据,如图中所标注的说明所示。类似地,对于图5中的(a)实验参与者1而言,在γ=10时与γ=100时,条形图的分布与之相似;进 一步地,其他实验参与者的在图5中所示的条形图的分布也具有类似的规律。
能够发现,在γ=0时,本发明的方法针对IW-SINRI≥0dB具有最大的百分比还针对IW-SINRI≥4dB具有最小的百分比。这意味着在γ=0时,本发明的方法对增强语音执行“安全策略”,即,针对Δρ接近于0的那些时间段,如主要在图4中示出的,每个语音源被部分保留在波束形成输出处。在另一方面,随着γ增加,更多的时间段具有大于4dB的IW-SINRI,其中,一些时间段的IW-SINRI的耗费低于0dB。而且,γ=100给出与SP-LCMV方法类似的结果。
此外,语音增强的另一个重要问题是语音失真。由于本发明的方法和SP-LCMV方法针对每个语音源都有线性约束,因此他们具有类似的IW-SD,如图6所示。图6示出本发明的方法和SP-LCMV方法的IW-SD与Pearson相关的差的关系,其中,图6中的实线和圆点表示针对本申请的波束形成方法所得到的数据,而虚线和方框点表示针对SP-LCMV方法所得到的数据。注意,本发明的方法调整0和1之间的α
k,在计算IW-SD时,波束形成输出处的语音信号根据α
k被缩放。而且对于两种方法,其中参与的语音源被完全拒绝的那些时间段(即,w(ω)
Hh(ω)=0)在图6中未示出。
根据本申请实施例的波束形成器基于EEG辅助的AA解码工作,旨在通过从信号处理的角度建立EEG辅助的AA解码与双耳波束形成之间的内在关联,改善在嘈杂的多个讲话者环境下参与的讲话者的语音并降低其他影响。为了有效利用EEG信号中包含的AA信息,在根据本申请实施例的波束形成器中,基于EEG辅助的AA解码与双耳波束形成之间的内在关联,通过平衡以下两个方面来实现所述脑电图辅助的波束形成器:(一)语音保真约束下的听觉注意力偏好分配;(二)降低噪声和干扰抑制。
应当理解,本申请所引用的耳戴式听力系统包括处理器,其可为DSP、微处理器、微控制器或其他数字逻辑。本申请所引用的信号处理可利用处理器执行。在各种实施例中,处理电路104可在这种处理器上实施。处理可在数字域、模拟域或其组合中完成。可使用子带处理技术完成处理。可利用频域或时间域方法完成处理。为了简便,在一些示例中,可省略用于执行频率合成、频率分析、模数转换、放大以及其他类型的滤波和处理的框图。在各种实施例中,处理器经配置以执行存储在存储器中的指令。在各种实施例中,处理器执行指令以 执行若干信号处理任务。在这种实施例中,模拟分量与处理器通信以执行信号任务,如,麦克风接收或接收器声音实施例(即,在使用这种传感器的应用中)。在各种实施例中,本文所提出的框图、电路或过程的实现可在不偏离本申请的主题的范围的情况下发生。
本申请的主题被示为用于耳戴式听力系统,包括助听器,包括但不限于,耳背式(BTE)助听器、耳内式(ITE)助听器、耳道式(ITC)助听器、内置受话器(RIC)助听器或完全耳道式(CIC)助听器。应当理解,耳背式(BTE)助听器可包括基本在耳朵后面或耳朵上面的装置。这种装置可包括具有与耳背式(BTE)装置的电子部分相关联的接收器的助听器或具有在使用者的耳道中的接收器类型的助听器,包括但不限于内置受话器(RIC)或耳中接收器(RITE)设计。本申请的主题通常还能够用在助听装置中,如,人工耳蜗类型的助听装置。应当理解,本文未明确陈述的其他助听装置可与本申请的主题结合使用。
还描述了本发明的以下示例实施例:
实施例1、一种波束形成器,包括:
用于接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号的装置;和
用于构建优化模型和求解优化模型的装置,其获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;
其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
实施例2、根据实施例1所述的波束形成器,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用非线性变换或用神经网络的方法建立所述至少一个脑电图信号与波束形成输出之间的关联。
实施例3、根据实施例1所述的波束形成器,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用线性变换建立所述至少一个脑电图信号与波束形成输出之间的关联。
实施例4、根据实施例3所述的波束形成器,其中,所述优化公式包括Pearson相关系数:

其中,
 和

且其中,
 是由所述至少一个EEG信号重新构造的参与语音源的语音信号的包络;z(t)表示波束形成输出;
 是对应于所述波束形成输出的解析信号;
 是所述波束形成输出的包络,其是所述解析信号
 的绝对值;κ({w(ω)})表示对于给定的时间段t=t
1,t
1+1,...,t
2,所述重新构造的参与语音源的语音信号的包络
 和所述波束形成输出的包络
 之间的所述Pearson相关系数;{w(ω)}
ω为所述波束形成权系数;ω(ω=1,2,…,Ω)表示频带。
实施例5、根据实施例4所述的波束形成器,进一步包括用于接收重新构造的参与语音源的语音信号的包络的装置,且其中,基于优化线性变换系数
 根据所述至少一个EEG信号,得到所述重新构造的参与语音源的语音信号的包络
 且所述重新构造的参与语音源的语音信号的包络被传递至所述用于接收重新构造的参与语音源的语音信号的包络的装置,
其中,根据对以下公式求解获知所述优化线性变换系数


其中,
 为时刻t(t=1,2,…)时所述至少一个EEG信号中的EEG通道i(i=1,2…,C)所对应的EEG信号且τ为时间延迟;s
a(t)表示对应于所述多个输入信号的所述参与语音源的语音信号的包络;g
i(τ)是对应于具有延迟τ的EEG通道i的所述EEG信号的线性回归系数,E是期望运算符号;正则函数
 限定所述线性回归系数g
i(τ)的时间平滑性;且λ≥0是对应的正则参数。
实施例6、根据实施例5所述的波束形成器,其中,所述解析信号通过离散傅里叶变换根据所述波束形成权系数{w(ω)}
ω被表示为:

其中,
 是用于形成所述解析信号的对角矩阵,
 是所述离散傅里叶变换矩阵的逆;
 表示帧l和频带ω(ω=1,2,…,Ω)处的所述多个输入信号,帧l对应于N个采样时间点t,t+1,…,t+N-1,而
 是用于补偿在用于表示所述多个输入信号所使用的短时傅里叶变换(STFT)中使用的合成窗的对角矩阵,
所述解析信号进一步被等价地表示为:

其中,
 是所述波束形成权系数,且
 由{y(l,ω)}
ω和矩阵D
W,F和D
H中的系数确定,以及
通过所述解析信号,将所述波束形成输出的包络
 表示为:

实施例7、根据实施例6所述的波束形成器,其中,所述波束形成输出的包络
 的采样率对应于所述多个输入信号的音频采样率。
实施例8、根据实施例6所述的波束形成器,其中,所述优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数包括最大化所述Pearson相关系数κ({w(ω)}),以提取所述至少一个EEG信号中包含的听觉注意力(AA)信息。
实施例9、根据实施例8所述的波束形成器,其中,在所述最大化所述Pearson相关系数κ({w(ω)})过程中施加具有鲁棒性的等式约束
 以控制语音失真,
其中,α=[α
1,α
2,…,α
K]
T为额外的变量,其表示所述多个语音源中的听觉注意力偏好;h
k(ω)是第k个语音源的声学传递函数;K为所述多个语音源的个数。
实施例10、根据实施例9所述的波束形成器,其中,所述优化公式变为:


其中,
 是背景噪声相关矩阵;-γ||α||
2为所述优化公式的正则项,其中,||·||
2表示所述额外的变量α=[α
1,α
2,…,α
K]
T的欧式范数;μ>0和γ≥0是预先设定的参数,其用于平衡去噪、分配注意力偏好和控制注意力偏好稀疏度,且
 表示所述额外的变量中的元素的和为1。
实施例11、根据实施例10所述的波束形成器,其中,所述优化模型利用梯度投影法(GPM)和交替方向乘子法(ADMM)求解,其包括以下步骤:
(a)将所述优化公式中的目标函数表示为:

并令
 优化公式的梯度,
其中,
 表示关于w(ω)的梯度分量;
 表示关于α的梯度分量;
(b)所述GPM将
 迭代地更新为:


其中,t为迭代指数,
 为x
t处的所述目标函数的梯度,[·]
+表示对等式约束
 和
 的投影运算,s为常数,且λ
t为根据Armijo规则确定的步长;
(c)公式(10a)中的投影运算等同于以下凸优化方程:


针对方程11a、11b和11c的增广拉格朗日函数为:

其中,ζ
k,ω和η为拉格朗日因子,其分别与所述等式约束相关联;ρ>0是针对ADMM算法的预定义的参数,
(d)所述ADMM算法将({w(ω)},α,{ζ
k,ω},η)迭代地更新为:


η
l+1=η
l+ρ(1
Tα-1) (12d)
其中,l为迭代指数;以及
(e)得到公式12的结果。
实施例12.一种用于波束形成器的波束形成方法,包括:
接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号;和
通过构建优化模型和求解优化模型获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;
其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
实施例13、根据实施例12所述的波束形成方法,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用非线性变换或用神经网络的方法建立所述至少一个脑电图信号与波束形成输出之间的关联。
实施例14、根据实施例12所述的波束形成方法,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用线性变换建立所述至少一个脑电图信号与波束形成输出之间的关联。
实施例15、根据实施例14所述的波束形成方法,其中,所述优化公式包括Pearson相关系数:

其中

且其中,
 是由所述至少一个EEG信号重新构造的参与语音源的语音信号的包络;z(t)表示波束形成输出;
 是对应于所述波束形成输出的解析信号;
 是所述波束形成输出的包络,其是所述解析信号
 的绝对值;κ({w(ω)})表示对于给定的时间段t=t
1,t
1+1,...,t
2, 所述重新构造的参与语音源的语音信号的包络
 和所述波束形成输出的包络
 之间的所述Pearson相关系数;{w(ω)}
ω为所述波束形成权系数;ω(ω=1,2,…,Ω)表示频带。
实施例16、根据实施例15所述的波束形成方法,其中,基于优化线性变换系数
 根据所述至少一个EEG信号,得到所述重新构造的参与语音源的语音信号的包络
 且所述方法进一步包括接收所述重新构造的参与语音源的语音信号的包络,
其中,根据对以下公式求解获知所述优化线性变换系数


其中,
 为时刻t(t=1,2,…)时所述至少一个EEG信号中的EEG通道i(i=1,2…,C)所对应的EEG信号且τ为时间延迟;s
a(t)表示对应于所述多个输入信号的所述参与语音源的语音信号的包络;g
i(τ)是对应于具有延迟τ的EEG通道i的所述EEG信号的线性回归系数,E是期望运算符号;正则函数
 限定所述线性回归系数g
i(τ)的时间平滑性;且λ≥0是对应的正则参数。
实施例17、根据实施例16所述的波束形成方法,其中,所述解析信号通过离散傅里叶变换根据所述波束形成权系数{w(ω)}
ω被表示为:

其中,
 是用于形成所述解析信号的对角矩阵,
 是所述离散傅里叶变换矩阵的逆;
 表示帧l和频带ω(ω=1,2,…,Ω)处的所述多个输入信号,帧l对应于N个采样时间点t,t+1,…,t+N-1,而
 是用于补偿在用于表示所述多个输入信号所使用的短时傅里叶变换(STFT)中使用的合成窗的对角矩阵,
所述解析信号进一步被等价地表示为:

其中,
 是所述波束形成权系数, 且
 由{y(l,ω)}
ω和矩阵D
W,F和D
H中的系数确定,以及
通过所述解析信号,将所述波束形成输出的包络
 表示为:

实施例18、根据实施例17所述的波束形成方法,其中,所述波束形成输出的包络
 的采样率对应于所述多个输入信号的音频采样率。
实施例19、根据实施例17所述的波束形成方法,其中,所述优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数包括最大化所述Pearson相关系数κ({w(ω)}),以提取所述至少一个EEG信号中包含的听觉注意力(AA)信息。
实施例20、根据实施例19所述的波束形成方法,其中,在所述最大化所述Pearson相关系数κ({w(ω)})过程中施加具有鲁棒性的等式约束
 以控制语音失真,
其中,α=[α
1,α
2,…,α
K]
T为额外的变量,其表示所述多个语音源中的听觉注意力偏好;h
k(ω)是第k个语音源的声学传递函数;K为所述多个语音源的个数。
实施例21、根据实施例20所述的波束形成方法,其中,所述优化公式变为:


其中,
 是背景噪声相关矩阵;-γ||α||
2为所述优化公式的正则项,其中,||·||
2表示所述额外的变量α=[α
1,α
2,…,α
K]
T的欧式范数;μ>0和γ≥0是预先设定的参数,其用于平衡去噪、分配注意力偏好和控制注意力偏好稀疏度,且
 表示所述额外的变量中的元素的和为1。
实施例22、根据实施例21所述的波束形成方法,其中,所述优化模型利用梯度投影法(GPM)和交替方向乘子法(ADMM)求解,其包括以下步骤:
(a)将所述优化公式中的目标函数表示为:

并令
 优化公式的梯度,
其中,
 表示关于w(ω)的梯度分量;
 表示关于α的梯度分量;
(b)所述GPM将
 迭代地更新为:


其中,t为迭代指数,
 为x
t处的所述目标函数的梯度,[·]
+表示对等式约束
 和
 的投影运算,s为常数,且λ
t为根据Armijo规则确定的步长;
(c)公式(10a)中的投影运算等同于以下凸优化方程:


针对方程11a、11b和11c的增广拉格朗日函数为:

其中,ζ
k,ω和η为拉格朗日因子,其分别与所述等式约束相关联;ρ>0是针对ADMM算法的预定义的参数,
(d)所述ADMM算法将({w(ω)},α,{ζ
k,ω},η)迭代地更新为:


η
l+1=η
l+ρ(1
Tα-1) (12d)
其中,l为迭代指数;以及
(e)得到公式12的结果。
实施例23、一种耳戴式听力系统,包括:
麦克风,其配置为接收来自多个语音源的多个输入信号;
脑电图信号接收接口,其配置为接收来自一个或多个脑电图电极的信息并且将脑电图信息进行线性或非线性变换以形成至少一个 脑电图(EEG)信号;
波束形成器,其接收所述多个输入信号和所述至少一个EEG信号,并且输出波束形成权系数;以及
合成模块,其将所述多个输入信号和所述波束形成权系数进行线性或非线性合成,以形成波束形成输出,
扬声器,其配置为将所述波束形成输出转换为输出声音,
其中,所述波束形成器为根据实施例1-11中任意一项所述的波束形成器。
实施例24.一种包括指令的计算机可读介质,所述指令当被处理器执行时能够使得所述处理器执行根据实施例12-22中任意一项所述的波束形成方法。
本申请旨在覆盖本申请的主题的实施方式或变体。应当理解,所述说明旨在是示例性的而非限制性的。
Claims (24)
- 一种波束形成器,包括:用于接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号的装置;和用于构建优化模型和求解优化模型的装置,其获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
- 根据权利要求1所述的波束形成器,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用非线性变换或用神经网络的方法建立所述至少一个脑电图信号与波束形成输出之间的关联。
- 根据权利要求1所述的波束形成器,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用线性变换建立所述至少一个脑电图信号与波束形成输出之间的关联。
- 根据权利要求3所述的波束形成器,其中,所述优化公式包括Pearson相关系数:
 其中
 且其中,是由所述至少一个EEG信号重新构造的参与语音源的语音信号的包络;z(t)表示波束形成输出;
 是对应于所述波束形成输出的解析信号;
 是所述波束形成输出的包络,其是所述解析信号
 的绝对值;κ({w(ω)})表示对于给定的时间段t=t 1,t 1+1,...,t 2,所述重新构造的参与语音源的语音信号的包络
 和所述波束形成输出的包络
 之间的所述Pearson相关系数;{w(ω)} ω为所述波束形 成权系数;ω(ω=1,2,…,Ω)表示频带。

- 根据权利要求4所述的波束形成器,进一步包括用于接收重新构造的参与语音源的语音信号的包络的装置,且其中,基于优化线性变换系数根据所述至少一个EEG信号,得到所述重新构造的参与语音源的语音信号的包络
 且所述重新构造的参与语音源的语音信号的包络被传递至所述用于接收重新构造的参与语音源的语音信号的包络的装置,
 其中,根据对以下公式求解获知所述优化线性变换系数

 其中,为时刻t(t=1,2,…)时所述至少一个EEG信号中的EEG通道i(i=1,2,…,C)所对应的EEG信号且τ为时间延迟;s a(t)表示对应于所述多个输入信号的所述参与语音源的语音信号的包络;g i(τ)是对应于具有延迟τ的EEG通道i的所述EEG信号的线性回归系数,E是期望运算符号;正则函数

 其限定所述线性回归系数g i(τ)的时间平滑性;且λ≥0是对应的正则参数。
- 根据权利要求5所述的波束形成器,其中,所述解析信号通过离散傅里叶变换根据所述波束形成权系数{w(ω)} ω被表示为:
 其中,是用于形成所述解析信号的对角矩阵,
 是所述离散傅里叶变换矩阵的逆;
 表示帧
 和频带ω(ω=1,2,…,Ω)处的所述多个输入信号,帧
 对应于N个采样时间点t,t+1,…,t+N-1,而
 是用于补偿在用于表示所述多个输入信号所使用的短时傅里叶变换(STFT)中使用的合成窗的对角矩阵,
 所述解析信号进一步被等价地表示为:
 其中,是所述波束形成权系数,且
 由
 和矩阵D W,F和D H中的系数确定,以及通过所述解析信号,将所述波束形成输出的包络
 表示为:


- 根据权利要求6所述的波束形成器,其中,所述波束形成输出的包络的采样率对应于所述多个输入信号的音频采样率。

- 根据权利要求6所述的波束形成器,其中,所述优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数包括最大化所述Pearson相关系数κ({w(ω)}),以提取所述至少一个EEG信号中包含的听觉注意力(AA)信息。
- 根据权利要求8所述的波束形成器,其中,在所述最大化所述Pearson相关系数κ({w(ω)})过程中施加具有鲁棒性的等式约束以控制语音失真,
 其中,α=[α 1,α 2,…,α K] T为额外的变量,其表示所述多个语音源中的听觉注意力偏好;h k(ω)是第k个语音源的声学传递函数;K为所述多个语音源的个数。
- 根据权利要求9所述的波束形成器,其中,所述优化公式变为:
 其中,是背景噪声相关矩阵;-γ||α|| 2为所述优化公式的正则项,其中,||·|| 2表示所述额外的变量α=[α 1,α 2,…,α K] T的欧式范数;μ>0和γ≥0是预先设定的参数,其用于平衡去噪、分配注意力偏好和控制注意力偏好稀疏度,且
 表示所述额外的变量中的元素的和为1。

- 根据权利要求10所述的波束形成器,其中,所述优化模型利用梯度投影法(GPM)和交替方向乘子法(ADMM)求解,其包括以下步骤:(a)将所述优化公式中的目标函数表示为:
 并令优化公式的梯度,
 其中,表示关于w(ω)的梯度分量;
 表示关于α的梯度分量;
 (b)所述GPM将迭代地更新为:


 其中,t为迭代指数,为x t处的所述目标函数的梯度,[·] +表示对等式约束
 和
 的投影运算,s为常数,且λ t为根据Armijo规则确定的步长;
 (c)公式(10a)中的投影运算等同于以下凸优化方程:


 针对方程11a、11b和11c的增广拉格朗日函数为:
 其中,ζ k,ω和η为拉格朗日因子,其分别与所述等式约束相关联;ρ>0是针对ADMM算法的预定义的参数,(d)所述ADMM算法将({w(ω)},α,{ζ k,ω},η)迭代地更新为:


 其中,l为迭代指数;以及(e)得到公式12的结果。
- 一种用于波束形成器的波束形成方法,包括:接收至少一个脑电图(EEG)信号和来自多个语音源的多个输入信号;和通过构建优化模型和求解优化模型获得对所述多个输入信号进行线性或非线性组合的波束形成权系数;其中,所述优化模型包括用于获得所述波束形成权系数的优化公式,所述优化公式包括建立所述至少一个脑电图信号与波束形成输出之间的关联、优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数。
- 根据权利要求12所述的波束形成方法,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用非线性变换或用神经网络的方法建立所述至少一个脑电图信号与波束形成输出之间的关联。
- 根据权利要求12所述的波束形成方法,其中,建立所述至少一个脑电图信号与波束形成输出之间的关联包括利用线性变换建立所述至少一个脑电图信号与波束形成输出之间的关联。
- 根据权利要求14所述的波束形成方法,其中,所述优化公式包括Pearson相关系数:
 其中
 且其中,是由所述至少一个EEG信号重新构造的参与语音源的语音信号的包络;z(t)表示波束形成输出;
 是对应于所述波束形成输出的解析信号;
 是所述波束形成输出的包络,其是所述解析信号
 的绝对值;κ({w(ω)})表示对于给定的时间段t=t 1,t 1+1,...,t 2,所述重新构造的参与语音源的语音信号的包络
 和所述波束形成输 出的包络
 之间的所述Pearson相关系数;{w(ω)} ω为所述波束形成权系数;ω(ω=1,2,…,Ω)表示频带。

- 根据权利要求15所述的波束形成方法,其中,基于优化线性变换系数根据所述至少一个EEG信号,得到所述重新构造的参与语音源的语音信号的包络
 且所述方法进一步包括接收所述重新构造的参与语音源的语音信号的包络,
 其中,根据对以下公式求解获知所述优化线性变换系数

 其中,为时刻t(t=1,2,…)时所述至少一个EEG信号中的EEG通道i(i=1,2,…,C)所对应的EEG信号且τ为时间延迟;s a(t)表示对应于所述多个输入信号的所述参与语音源的语音信号的包络;g i(τ)是对应于具有延迟τ的EEG通道i的所述EEG信号的线性回归系数,E是期望运算符号;正则函数
 限定所述线性回归系数g i(τ)的时间平滑性;且λ≥0是对应的正则参数。

- 根据权利要求16所述的波束形成方法,其中,所述解析信号通过离散傅里叶变换根据所述波束形成权系数{w(ω)} ω被表示为:
 其中,是用于形成所述解析信号的对角矩阵,
 是所述离散傅里叶变换矩阵的逆;
 表示帧
 和频带ω(ω=1,2,…,Ω)处的所述多个输入信号,帧
 对应于N个采样时间点t,t+1,…,t+N-1,而
 是用于补偿在用于表示所述多个输入信号所使用的短时傅里叶变换(STFT)中使用的合成窗的对角矩阵,
 所述解析信号进一步被等价地表示为:
 其中,是所述波束形成权系数, 且
 由
 和矩阵D W,F和D H中的系数确定,以及
 通过所述解析信号,将所述波束形成输出的包络表示为:


- 根据权利要求17所述的波束形成方法,其中,所述波束形成输出的包络的采样率对应于所述多个输入信号的音频采样率。

- 根据权利要求17所述的波束形成方法,其中,优化所述关联以便构建出与至少一个脑电图信号相关联的波束形成权系数包括最大化所述Pearson相关系数κ({w(ω)}),以提取所述至少一个EEG信号中包含的听觉注意力(AA)信息。
- 根据权利要求19所述的波束形成方法,其中,在所述最大化所述Pearson相关系数κ({w(ω)})过程中施加具有鲁棒性的等式约束以控制语音失真,
 其中,α=[α 1,α 2,…,α K] T为额外的变量,其表示所述多个语音源中的听觉注意力偏好;h k(ω)是第k个语音源的声学传递函数;K为所述多个语音源的个数。
- 根据权利要求20所述的波束形成方法,其中,所述优化公式变为:
 其中,是背景噪声相关矩阵;-γ||α|| 2为所述优化公式的正则项,其中,||·|| 2表示所述额外的变量α=[α 1,α 2,…,α K] T的欧式范数;μ>0和γ≥0是预先设定的参数,其用于平衡去噪、分配注意力偏好和控制注意力偏好稀疏度,且
 表示所述额外的变量中的元素的和为1。

- 根据权利要求21所述的波束形成方法,其中,所述优化模 型利用梯度投影法(GPM)和交替方向乘子法(ADMM)求解,其包括以下步骤:(a)将所述优化公式中的目标函数表示为:
 并令优化公式的梯度,
 其中,表示关于w(ω)的梯度分量;
 表示关于α的梯度分量;
 (b)所述GPM将迭代地更新为:


 其中,t为迭代指数,为x t处的所述目标函数的梯度,[·] +表示对等式约束
 和
 的投影运算,s为常数,且λ t为根据Armijo规则确定的步长;
 (c)公式(10a)中的投影运算等同于以下凸优化方程:


 针对方程11a、11b和11c的增广拉格朗日函数为:
 其中,ζ k,ω和η为拉格朗日因子,其分别与所述等式约束相关联;ρ>0是针对ADMM算法的预定义的参数,(d)所述ADMM算法将({w(ω)},α,{ζ k,ω},η)迭代地更新为:


 其中,l为迭代指数;以及(e)得到公式12的结果。
- 一种耳戴式听力系统,包括:麦克风,其配置为接收来自多个语音源的多个输入信号;脑电图信号接收接口,其配置为接收来自一个或多个脑电图电极的信息并且将脑电图信息进行线性或非线性变换以形成至少一个脑电图(EEG)信号;波束形成器,其接收所述多个输入信号和所述至少一个EEG信号,并且输出波束形成权系数;以及合成模块,其将所述多个输入信号和所述波束形成权系数进行线性或非线性合成,以形成波束形成输出,扬声器,其配置为将所述波束形成输出转换为输出声音,其中,所述波束形成器为根据权利要求1-11中任意一项所述的波束形成器。
- 一种包括指令的计算机可读介质,所述指令当被处理器执行时能够使得所述处理器执行根据权利要求12-22中任意一项所述的波束形成方法。
Priority Applications (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| EP19846617.9A EP3836563A4 (en) | 2018-08-08 | 2019-08-07 | ELECTROENCEPHALOGRAM ASSISTED BEAMFORMER, BEAMFORMING PROCEDURE AND EAR-MOUNTED HEARING AID |
| US17/265,931 US11617043B2 (en) | 2018-08-08 | 2019-08-07 | EEG-assisted beamformer, beamforming method and ear-worn hearing system |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN201810896174.9 | 2018-08-08 | ||
| CN201810896174.9A CN110830898A (zh) | 2018-08-08 | 2018-08-08 | 脑电图辅助的波束形成器和波束形成方法以及耳戴式听力系统 |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2020029998A1 true WO2020029998A1 (zh) | 2020-02-13 |
Family
ID=69414530
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/CN2019/099594 Ceased WO2020029998A1 (zh) | 2018-08-08 | 2019-08-07 | 脑电图辅助的波束形成器和波束形成方法以及耳戴式听力系统 |
Country Status (4)
| Country | Link |
|---|---|
| US (1) | US11617043B2 (zh) |
| EP (1) | EP3836563A4 (zh) |
| CN (1) | CN110830898A (zh) |
| WO (1) | WO2020029998A1 (zh) |
Cited By (3)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN115243180A (zh) * | 2022-07-21 | 2022-10-25 | 香港中文大学(深圳) | 类脑助听方法、装置、助听设备和计算机设备 |
| CN116035593A (zh) * | 2023-02-02 | 2023-05-02 | 中国科学技术大学 | 一种基于生成对抗式并行神经网络的脑电降噪方法 |
| JP2023544131A (ja) * | 2020-09-25 | 2023-10-20 | ボーズ・コーポレーション | 機械学習ベースの自己発話除去 |
Families Citing this family (5)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| EP4007309A1 (en) * | 2020-11-30 | 2022-06-01 | Oticon A/s | Method for calculating gain in a heraing aid |
| CN113780533B (zh) * | 2021-09-13 | 2022-12-09 | 广东工业大学 | 基于深度学习及admm的自适应波束成形方法及系统 |
| CN115153563B (zh) * | 2022-05-16 | 2024-08-06 | 天津大学 | 基于eeg的普通话听觉注意解码方法及装置 |
| CN115086836B (zh) * | 2022-06-14 | 2023-04-18 | 西北工业大学 | 一种波束形成方法、系统及波束形成器 |
| CN116165976A (zh) * | 2022-12-26 | 2023-05-26 | 阿里云计算有限公司 | 生产系统的控制方法、装置、系统、设备及存储介质 |
Citations (7)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US20060094974A1 (en) * | 2004-11-02 | 2006-05-04 | Cain Robert C | Systems and methods for detecting brain waves |
| CN103716744A (zh) * | 2012-10-08 | 2014-04-09 | 奥迪康有限公司 | 具有随脑电波而变的音频处理的听力装置 |
| CN103873999A (zh) * | 2012-12-14 | 2014-06-18 | 奥迪康有限公司 | 可配置的听力仪器 |
| CN104980865A (zh) * | 2014-04-03 | 2015-10-14 | 奥迪康有限公司 | 包括双耳降噪的双耳助听系统 |
| CN105451147A (zh) * | 2014-09-22 | 2016-03-30 | 奥迪康有限公司 | 包括用于拾取脑电波信号的电极的助听系统 |
| CN107049305A (zh) * | 2015-12-22 | 2017-08-18 | 奥迪康有限公司 | 包括用于从身体拾取电磁信号的传感器的听力装置 |
| CN107864440A (zh) * | 2016-07-08 | 2018-03-30 | 奥迪康有限公司 | 包括eeg记录和分析系统的助听系统 |
Family Cites Families (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US943277A (en) | 1909-12-14 | Benjamin F Silliman | Steam-generator. |
-
2018
- 2018-08-08 CN CN201810896174.9A patent/CN110830898A/zh active Pending
-
2019
- 2019-08-07 US US17/265,931 patent/US11617043B2/en active Active
- 2019-08-07 EP EP19846617.9A patent/EP3836563A4/en not_active Withdrawn
- 2019-08-07 WO PCT/CN2019/099594 patent/WO2020029998A1/zh not_active Ceased
Patent Citations (7)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US20060094974A1 (en) * | 2004-11-02 | 2006-05-04 | Cain Robert C | Systems and methods for detecting brain waves |
| CN103716744A (zh) * | 2012-10-08 | 2014-04-09 | 奥迪康有限公司 | 具有随脑电波而变的音频处理的听力装置 |
| CN103873999A (zh) * | 2012-12-14 | 2014-06-18 | 奥迪康有限公司 | 可配置的听力仪器 |
| CN104980865A (zh) * | 2014-04-03 | 2015-10-14 | 奥迪康有限公司 | 包括双耳降噪的双耳助听系统 |
| CN105451147A (zh) * | 2014-09-22 | 2016-03-30 | 奥迪康有限公司 | 包括用于拾取脑电波信号的电极的助听系统 |
| CN107049305A (zh) * | 2015-12-22 | 2017-08-18 | 奥迪康有限公司 | 包括用于从身体拾取电磁信号的传感器的听力装置 |
| CN107864440A (zh) * | 2016-07-08 | 2018-03-30 | 奥迪康有限公司 | 包括eeg记录和分析系统的助听系统 |
Non-Patent Citations (4)
| Title |
|---|
| N. DASS. VAN EYNDHOVENT. FRANCARTA. BERTRAND: "EEG-based attention-driven speech enhancement for noisy speech mixtures using n-fold multi-channel wiener filters", 2017 25TH EUROPEAN SIGNAL PROCESSING CONFERENCE (EUSIPCO, August 2017 (2017-08-01), pages 1660 - 1664, XP033236119, DOI: 10.23919/EUSIPCO.2017.8081390 |
| S. VAN EYNDHOVENT. FRANCARTA. BERTRAND: "EEG-informed attended talker extraction from recorded speech mixtures with application in neuro-steered hearing prostheses", IEEE TRANSACTIONS ON BIOMEDICAL ENGINEERING, vol. 64, no. 5, May 2017 (2017-05-01), pages 1045 - 1056 |
| See also references of EP3836563A4 |
| W. BIESMANSN. DAST. FRANCARTA. BERTRAND: "Auditory-inspired speech envelope extraction methods for improved eeg-based auditory attention detection in a cocktail party scenario", IEEE TRANSACTIONS ON NEURAL SYSTEMS AND REHABILITATION ENGINEERING, vol. 25, no. 5, May 2017 (2017-05-01), pages 402 - 412 |
Cited By (6)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| JP2023544131A (ja) * | 2020-09-25 | 2023-10-20 | ボーズ・コーポレーション | 機械学習ベースの自己発話除去 |
| JP7636527B2 (ja) | 2020-09-25 | 2025-02-26 | ボーズ・コーポレーション | 機械学習ベースの自己発話除去 |
| CN115243180A (zh) * | 2022-07-21 | 2022-10-25 | 香港中文大学(深圳) | 类脑助听方法、装置、助听设备和计算机设备 |
| CN115243180B (zh) * | 2022-07-21 | 2024-05-10 | 香港中文大学(深圳) | 类脑助听方法、装置、助听设备和计算机设备 |
| CN116035593A (zh) * | 2023-02-02 | 2023-05-02 | 中国科学技术大学 | 一种基于生成对抗式并行神经网络的脑电降噪方法 |
| CN116035593B (zh) * | 2023-02-02 | 2024-05-07 | 中国科学技术大学 | 一种基于生成对抗式并行神经网络的脑电降噪方法 |
Also Published As
| Publication number | Publication date |
|---|---|
| EP3836563A4 (en) | 2022-04-20 |
| US20210306765A1 (en) | 2021-09-30 |
| CN110830898A (zh) | 2020-02-21 |
| EP3836563A1 (en) | 2021-06-16 |
| US11617043B2 (en) | 2023-03-28 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| US11617043B2 (en) | EEG-assisted beamformer, beamforming method and ear-worn hearing system | |
| US11503414B2 (en) | Hearing device comprising a speech presence probability estimator | |
| Van Eyndhoven et al. | EEG-informed attended speaker extraction from recorded speech mixtures with application in neuro-steered hearing prostheses | |
| US20210185465A1 (en) | Signal processing in a hearing device | |
| CA2805491C (en) | Method of signal processing in a hearing aid system and a hearing aid system | |
| DK2986026T3 (en) | DEVICE FOR HEARING AID WITH RADIATION FORMS WITH OPTIMIZED APPLICATION OF SPACE INFORMATION PROVIDED IN ADVANCE | |
| EP3471440A1 (en) | A hearing device comprising a speech intelligibilty estimator for influencing a processing algorithm | |
| CN107046668B (zh) | 单耳语音可懂度预测单元、助听器及双耳听力系统 | |
| CN107454538A (zh) | 包括含有平滑单元的波束形成器滤波单元的助听器 | |
| Aroudi et al. | Cognitive-driven binaural LCMV beamformer using EEG-based auditory attention decoding | |
| EP4199541A1 (en) | A hearing device comprising a low complexity beamformer | |
| Klasen et al. | Binaural multi-channel Wiener filtering for hearing aids: preserving interaural time and level differences | |
| Salehi et al. | Learning-based reference-free speech quality measures for hearing aid applications | |
| Pandey et al. | Low-delay signal processing for digital hearing aids | |
| Marquardt et al. | Optimal binaural LCMV beamformers for combined noise reduction and binaural cue preservation | |
| Azarpour et al. | Binaural noise reduction via cue-preserving MMSE filter and adaptive-blocking-based noise PSD estimation | |
| Aroudi et al. | Cognitive-driven convolutional beamforming using EEG-based auditory attention decoding | |
| Alamdari et al. | An educational tool for hearing aid compression fitting via a web-based adjusted smartphone app | |
| Sanchez-Lopez et al. | Technical evaluation of hearing-aid fitting parameters for different auditory profiles | |
| Pu et al. | Evaluation of joint auditory attention decoding and adaptive binaural beamforming approach for hearing devices with attention switching | |
| US9124963B2 (en) | Hearing apparatus having an adaptive filter and method for filtering an audio signal | |
| Puder | Adaptive signal processing for interference cancellation in hearing aids | |
| Courtois | Spatial hearing rendering in wireless microphone systems for binaural hearing aids | |
| Kokkinakis et al. | Advances in modern blind signal separation algorithms: theory and applications | |
| Levitt | Future directions in hearing aid research |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 19846617 Country of ref document: EP Kind code of ref document: A1 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| ENP | Entry into the national phase |
Ref document number: 2019846617 Country of ref document: EP Effective date: 20210309 |