WO2021073449A1 - 基于机器学习的去伪影方法、去伪影模型训练方法及装置 - Google Patents
基于机器学习的去伪影方法、去伪影模型训练方法及装置 Download PDFInfo
- Publication number
- WO2021073449A1 WO2021073449A1 PCT/CN2020/120006 CN2020120006W WO2021073449A1 WO 2021073449 A1 WO2021073449 A1 WO 2021073449A1 CN 2020120006 W CN2020120006 W CN 2020120006W WO 2021073449 A1 WO2021073449 A1 WO 2021073449A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- image frame
- sample
- feature
- model
- feature vector
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Images


Classifications
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N19/00—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals
- H04N19/85—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using pre-processing or post-processing specially adapted for video compression
- H04N19/86—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using pre-processing or post-processing specially adapted for video compression involving reduction of coding artifacts, e.g. of blockiness
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F18/00—Pattern recognition
- G06F18/20—Analysing
- G06F18/21—Design or setup of recognition systems or techniques; Extraction of features in feature space; Blind source separation
- G06F18/214—Generating training patterns; Bootstrap methods, e.g. bagging or boosting
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F18/00—Pattern recognition
- G06F18/20—Analysing
- G06F18/25—Fusion techniques
- G06F18/253—Fusion techniques of extracted features
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N20/00—Machine learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/0464—Convolutional networks [CNN, ConvNet]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/084—Backpropagation, e.g. using gradient descent
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/09—Supervised learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V10/00—Arrangements for image or video recognition or understanding
- G06V10/70—Arrangements for image or video recognition or understanding using pattern recognition or machine learning
- G06V10/82—Arrangements for image or video recognition or understanding using pattern recognition or machine learning using neural networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06V—IMAGE OR VIDEO RECOGNITION OR UNDERSTANDING
- G06V10/00—Arrangements for image or video recognition or understanding
- G06V10/98—Detection or correction of errors, e.g. by rescanning the pattern or by human intervention; Evaluation of the quality of the acquired patterns
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N19/00—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals
- H04N19/10—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using adaptive coding
- H04N19/102—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using adaptive coding characterised by the element, parameter or selection affected or controlled by the adaptive coding
- H04N19/117—Filters, e.g. for pre-processing or post-processing
-
- H—ELECTRICITY
- H04—ELECTRIC COMMUNICATION TECHNIQUE
- H04N—PICTORIAL COMMUNICATION, e.g. TELEVISION
- H04N19/00—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals
- H04N19/50—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using predictive coding
- H04N19/587—Methods or arrangements for coding, decoding, compressing or decompressing digital video signals using predictive coding involving temporal sub-sampling or interpolation, e.g. decimation or subsequent interpolation of pictures in a video sequence
Definitions
- This application relates to the field of artificial intelligence, and in particular to a de-artifacting method based on machine learning, a de-artifacting model training method and device.
- the main function of the video enhancement filter is to remove random noise in the flat pixel area, and the effect of removing video artifacts is limited.
- the embodiments of the present application provide a de-artifacting method, de-artifacting model training method and device based on machine learning.
- the de-artifacting model can be used to preprocess the artifacts that may occur in the encoding and compression process of the video to avoid encoding.
- the compressed video clearly shows many types of artifacts.
- the technical solution is as follows:
- a method for removing artifacts based on machine learning which is applied to an electronic device, and the method includes:
- At least two target image frames corresponding to the at least two original image frames are sequentially encoded and compressed to obtain a de-artifacted video frame sequence.
- a method for training a de-artifacting model based on machine learning is provided, which is applied to an electronic device, and the method includes:
- each group of training samples includes the original image frame samples of the video samples and the image frame samples encoded and compressed by the original image frame samples;
- a device for removing artifacts based on machine learning comprising:
- the first acquisition module is configured to acquire a to-be-processed video, where the video includes at least two original image frames;
- the first calling module is used to call the artifact removal model to predict the residual between the i-th original image frame of the video and the compressed image frame of the i-th original image frame to obtain the prediction residual of the i-th original image frame , I is a positive integer;
- the first calling module is used to call the anti-artifact model to add the prediction residual to the i-th original image frame to obtain the target image frame after the anti-artifact processing;
- the encoding module is used to sequentially encode and compress at least two target image frames corresponding to at least two original image frames to obtain a de-artifacted video frame sequence.
- an anti-artifact model training device based on machine learning including:
- the second acquisition module is used to acquire training samples, each group of training samples includes the original image frame samples of the video samples and the image frame samples encoded and compressed by the original image frame samples;
- the second calling module is used to call the artifact removal model to predict the residuals between the original image frame samples and the encoded and compressed image frame samples in each group of training samples, to obtain the sample residuals;
- the second calling module is used to call the de-artifacting model to add the sample residual and the encoded and compressed image frame samples to obtain the target image frame sample after the de-artifact processing;
- the training module is used to determine the loss between the target image frame sample and the original image frame sample, and adjust the model parameters in the de-artifacting model according to the loss, and train the residual learning ability of the de-artifacting model.
- an electronic device which includes:
- the processor connected to the memory;
- the processor is configured to load and execute executable instructions to implement the method for removing artifacts based on machine learning as described in the above-mentioned one aspect and its optional embodiments, and as described in the above-mentioned another aspect and its optional embodiments.
- a computer-readable storage medium stores at least one instruction, at least one program, code set, or instruction set, the above-mentioned at least one instruction, at least one program,
- the code set or instruction set is loaded and executed by the processor to implement the machine learning-based de-artifacting method as described in the above-mentioned one aspect and its optional embodiments, as well as the above-mentioned other aspect and its optional embodiments.
- the training method of anti-artifact model based on machine learning.
- a computer program product includes computer instructions, and the computer instructions are stored in a computer-readable storage medium.
- the processor of the computer device reads the aforementioned computer instructions from the computer-readable storage medium, and the processor executes the aforementioned computer instructions, so that the aforementioned computer device executes the method for removing artifacts based on machine learning as described in the aforementioned one aspect and its optional embodiments , And the method for training an anti-artifact model based on machine learning as described in the above another aspect and its optional embodiments.
- This method preprocesses the artifacts that may occur in the video compression process by using a de-artifact model of the residual learning structure, and accurately retains more video frame textures during the feature extraction process of the video frame through residual learning.
- the quality of the compressed and decompressed video frame is higher; the artifact removal model is used to preprocess the artifacts that may appear in the video encoding and compression process, so as to avoid the obvious multiple types of artifacts in the encoded and compressed video.
- the serial combination of different filters and a large number of tests are required to achieve the desired anti-artifact effect, which can save a lot of test costs and solve the problem of unified processing of multiple types of artifacts. problem.
- FIG. 1 is a schematic structural diagram of a de-artifacting model framework based on machine learning provided by an exemplary embodiment of the present application;
- FIG. 2 is a schematic structural diagram of an application framework of a de-artifacting model based on machine learning provided by an exemplary embodiment of the present application;
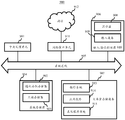
- Fig. 3 is a schematic structural diagram of a computer system provided by an exemplary embodiment of the present application.
- Fig. 4 is a flowchart of a method for training a de-artifacting model based on machine learning provided by an exemplary embodiment of the present application;
- Fig. 5 is a schematic diagram of a training sample generation process provided by an exemplary embodiment of the present application.
- Fig. 6 is a flowchart of a method for removing artifacts based on machine learning provided by an exemplary embodiment of the present application
- FIG. 7 is a schematic diagram of displaying after decompressing a video frame that has not been processed by a de-artifacting model according to an exemplary embodiment of the present application.
- Fig. 8 is a schematic diagram of displaying after decompressing a video frame processed by a de-artifacting model according to an exemplary embodiment of the present application
- FIG. 9 is a schematic diagram showing a comparison between a video frame that has not been processed by a de-artifacting model and a video frame that has been processed by a de-artifacting model provided by an exemplary embodiment of the present application after decompression;
- Fig. 10 is a block diagram of a device for removing artifacts based on machine learning provided by an exemplary embodiment of the present application
- FIG. 11 is a block diagram of a device for training an anti-artifact model based on machine learning according to an exemplary embodiment of the present application
- FIG. 12 is a schematic structural diagram of a terminal provided by an exemplary embodiment of the present application.
- Fig. 13 is a schematic structural diagram of a server provided by an exemplary embodiment of the present application.
- Video codec It is a kind of video compression technology that essentially realizes video compression by reducing redundant pixels in the video image.
- the most important video coding and decoding standards include the International Telecommunication Union’s video coding standards H.261, H.263, H.264, Motion-Joint Photographic Exoerts Group (M-JPEG), and international standardization Organized Moving Picture Experts Group (MPEG) series standards; in addition, video coding and decoding standards also include the RealVideo video format on the Internet, Windows Media Video (WMV), and QuickTime.
- WMV Windows Media Video
- video compression includes: lossy compression. That is to say, in the process of video encoding and compression, the removal of high-frequency information due to pixel quantization, block division, etc. will lead to loss of information in the video image, and negative effects including blocking, ringing and edge burrs will appear. .
- the above-mentioned negative effects are artifacts.
- blocking effect refers to that in the video encoding process, the correlation of the video image is destroyed due to the way that the video image is divided into macroblocks for encoding and compression, resulting in visible discontinuities at the boundary of small blocks.
- the above-mentioned “ringing effect” refers to that in the process of processing the video image through the filter, the filter has a sharp change, which causes oscillations in the sharp change of the gray level of the output video image of the filter.
- edge burr refers to the random thorn-like effect generated at the edge of the main body of the video image due to the serious loss of video image content due to multiple encodings of the same video image.
- This application provides a de-artifacting model based on machine learning, which can achieve a better de-artifacting effect on video images in the process of video encoding and compression.
- the aforementioned anti-artifact model based on machine learning includes:
- Input layer 101 feature extraction module 102, feature reconstruction module 103, and output layer 104;
- the feature extraction module 102 includes at least two feature extraction units 11 and a first feature fusion layer 12; at least two feature extraction units 11 are connected in sequence, and at least two feature extraction units 11 are connected in sequence.
- the input terminal is also connected to the output terminal of the input layer 101; the output terminal of each feature extraction unit 11 is connected to the input terminal of the first feature fusion layer 12.
- the feature reconstruction module 103 includes a dimensionality reduction unit 21 and a feature reconstruction unit 22; the input end of the dimensionality reduction unit 21 is connected to the output end of the first feature fusion layer 12, and the output end of the dimensionality reduction unit 21 is connected to the input end of the feature reconstruction unit 22 The output end of the feature reconstruction unit 22 is connected to the input end of the output layer 104; the input end of the output layer 104 is also connected to the output end of the input layer 101.
- the dimensionality reduction unit 21 includes a first 1 ⁇ 1 convolutional layer 31.
- the dimensionality reduction unit 21 includes a first 1 ⁇ 1 convolutional layer 31, a second 1 ⁇ 1 convolutional layer 32, a first feature extraction layer 33, and a second feature fusion layer 34;
- the input end of the first 1 ⁇ 1 convolutional layer 31 is connected to the output end of the first feature fusion layer 12, and the output end of the first 1 ⁇ 1 convolutional layer 31 is connected to the input end of the second feature fusion layer 34;
- the input end of the second 1 ⁇ 1 convolutional layer 32 is connected to the output end of the first feature fusion layer 12
- the output end of the second 1 ⁇ 1 convolutional layer 32 is connected to the input end of the first feature extraction layer 33
- the first The output terminal of the feature extraction layer 33 is connected to the input terminal of the second feature fusion layer 34.
- the amount of model parameters in the convolutional layer corresponding to each feature extraction unit 11 decreases layer by layer in a direction away from the input layer 101.
- the model parameter quantity may include at least one of the size of the convolution kernel and the number of channels of the convolution kernel.
- the model parameter quantity of the first feature extraction unit 11 connected to the input layer 101 is m 1
- the model parameter quantity of the second feature extraction unit 11 connected to the first feature extraction unit 11 is m 2 , where, m 1 is greater than m 2
- m 1 and m 2 are positive integers.
- the feature reconstruction unit 22 includes a feature reconstruction layer 41; the input end of the feature reconstruction layer 41 is connected to the output end of the second feature fusion layer 34, and the output end of the feature reconstruction layer 41 is connected to the input end of the output layer 104 .
- the feature reconstruction layer 41 may be a 3 ⁇ 3 convolutional layer.
- the feature reconstruction unit 22 further includes a second feature extraction layer 42; the second feature extraction layer 42 is connected to the feature reconstruction layer 41, and the input end of the second feature extraction layer 42 is connected to the output of the second feature fusion layer 34 The output terminal of the second feature extraction layer 42 is connected to the input terminal of the feature reconstruction layer 41.
- the feature reconstruction unit 22 in FIG. 1 includes two feature reconstruction layers 41 and a second feature extraction layer 42.
- the two feature reconstruction layers 41 are connected to the second feature extraction layer 42, and the second feature extraction layer 42
- the input end of is connected to the output end of the second feature fusion layer 34
- the input end of the first feature reconstruction layer 41 is connected to the output end of the second feature extraction layer 42
- the second feature reconstruction layer 41 (that is, away from the second feature
- the input end of the feature reconstruction layer 41) of the extraction layer 42 is connected to the output end of the first feature reconstruction layer 41
- the output end of the second feature reconstruction layer 41 is connected to the input end of the output layer 104.
- each feature extraction layer and each feature reconstruction layer in the above-mentioned machine learning-based de-artifacting model uses a convolutional network.
- the size of the convolution kernel in the above-mentioned convolutional network is 3, the step size is 1, and the padding is (padding) is 1; the above-mentioned padding is used to define the space between the element border and the element content.
- the overall architecture of the above-mentioned de-artifacting model based on machine learning adopts the structure of residual learning.
- residual learning more texture details of the video frame are retained during the feature extraction process of the video frame, so that the decompressed video frame Higher quality; and by training the anti-artifact model based on machine learning to preprocess the artifacts that may appear in the video encoding and compression process, avoiding the obvious multiple types of artifacts in the encoded and compressed video, compared with the traditional anti-artifact
- the shadow method requires serial combination of different filters and a large number of tests to achieve the desired anti-artifact effect, which can save a lot of test costs and solve the problem of unified processing of multiple types of artifacts.
- the implementation framework 200 for applying the aforementioned anti-artifact model based on machine learning to perform video encoding compression includes a pre-processing module 201 and a compression module 202.
- the anti-artifact model 51 based on machine learning is set in the pre-processing module 201 for performing anti-artifact processing on the image frame before compression;
- the pre-processing module 201 also includes a denoising unit 52 and an enhancement unit 53, wherein
- the noise unit 52 is used to remove noise in the image frame, and the enhancement unit 53 is used to enhance the signal intensity of the pixels in the image frame.
- the compression module 202 includes a signal shaping unit 61, a bit rate determination unit 62, a region compression unit 63, and an encoder 64.
- the signal shaping unit 61 is used to shape the signal of the image frame after the pre-compression processing performed by the pre-processing module 201, for example, to reduce the waveform;
- the bit rate determining unit 62 is used to determine the bit rate of image frame compression;
- the area compression unit 63 It is used to perform regional compression on the image frame by the encoder 64.
- the foregoing implementation framework 200 is set in a server, and the server implements the encoding and compression of video through the foregoing implementation framework 200, as shown in FIG. 3, which shows the performance of the computer system provided by an exemplary embodiment of the present application.
- the computer system includes a first terminal 301, a server 302, and a second terminal 303.
- the first terminal 301 and the second terminal 303 are connected to the server 302 through a wired or wireless network, respectively.
- the first terminal 301 may include at least one of a notebook computer, a desktop computer, a smart phone, and a tablet computer.
- the first terminal 301 uploads the captured video to the server 302 through a wired or wireless network; or, the first terminal 301 uploads a locally stored video to the server 302 through a wired or wireless network, and the locally stored video may be Downloaded from a website or transmitted to the first terminal 301 from other devices.
- the server 302 includes a memory and a processor.
- a program is stored in the memory, and the program is called by the processor to implement the steps executed on the server side in the method for removing artifacts based on machine learning provided in this application.
- a de-artifacting model based on machine learning is stored in the memory, and the aforementioned de-artifacting model based on machine learning is called by the processor to implement the steps executed on the server side in the aforementioned de-artifacting method based on machine learning.
- the memory may include but is not limited to the following: Random Access Memory (RAM), Read Only Memory (ROM), Programmable Read-Only Memory (PROM) ), Erasable Programmable Read-Only Memory (EPROM), and Electrical Erasable Programmable Read-Only Memory (EEPROM).
- RAM Random Access Memory
- ROM Read Only Memory
- PROM Programmable Read-Only Memory
- EPROM Erasable Programmable Read-Only Memory
- EEPROM Electrical Erasable Programmable Read-Only Memory
- the server 302 after the server 302 receives the video uploaded by the first terminal 301, it calls the pre-processing module 201 in the implementation framework 200 to perform compression pre-processing on the video; regarding the de-artifact processing of the video, the server 302 calls the machine learning
- the anti-artifact model predicts the residual between the i-th original image frame of the video and the compressed image frame of the i-th original image frame to obtain the prediction residual of the i-th original image frame; call the anti-artifact model
- the prediction residual is added to the i-th original image frame to obtain the target image frame after de-artifacting processing.
- the server 302 After the pre-compression processing of the pre-processing module 201, the server 302 calls the compression module 202 in the implementation framework 200 to compress the above-mentioned target image frame to obtain a compressed video; where i is a positive integer.
- the server 302 sends the compressed video to the second terminal 303 through a wired or wireless network, and the second terminal 303 can play the compressed video through decompression.
- Fig. 4 shows a flowchart of a method for training a de-artifacting model based on machine learning according to an exemplary embodiment of the present application.
- the method is applied to an electronic device.
- the electronic device may be a terminal or a server.
- the method includes:
- Step 401 The electronic device obtains training samples, and each group of training samples includes the original image frame samples of the video samples and the image frame samples encoded and compressed by the original image frame samples.
- the above training sample is to compress the original video to obtain a compressed video; randomly extract n original image frame samples from the above original video, and extract n coded and compressed images corresponding to the n original image frame samples from the above compressed video Frame samples; n original image frame samples and n coded and compressed image frame samples are combined into n groups of training samples in a one-to-one correspondence; n is a positive integer. That is, each group of training samples includes an original image frame sample and an image frame sample encoded and compressed by the original image frame sample.
- the electronic device calls the decoder 71 based on the H.264 coding standard to decapsulate the high-definition video to obtain a video frame stream in the YUV format; where Y represents Brightness (Lnminance or Luma), which is the grayscale value; U and V represent chrominance (Chrominance or Chrome), used to describe the color and saturation of the image, and specify the color of the pixel.
- the electronic device calls the encoder 72 set based on the H.264 coding standard to encode and compress the above-mentioned video frame stream to obtain a compressed video.
- the electronic device correspondingly extracts image frames in the original high-definition video and compressed video; among them, the image frames extracted from the compressed video include artifacts, such as blocking effects, ringing effects, and edge burrs and other negative effects.
- the electronic device uses the color space conversion engine 73 to extract the Y channel data in the YUV format of each group of image frames as training samples.
- the electronic device randomly selects a constant rate factor (CRF) within a preset range for compression. While ensuring the compression quality, the artifacts included in the compressed image frame are increased. diversification.
- the preset range of CRF is 30 to 60, and the electronic device selects a value from 30 to 60 in the encoding stage as the CRF for this encoding compression.
- the electronic device also increases the amount of data of training samples through data augmentation; illustratively, before training, a method of data augmentation may be to randomly extract samples from the time series of the video.
- a method of data augmentation may be to randomly extract samples from the time series of the video.
- Frame another way of data augmentation can be random cropping in the pixel space according to a predetermined size, for example, random cropping of 512 ⁇ 512 size in the pixel space; in the training phase, vertical flipping and horizontal flipping can be used , Or 90-degree rotation and other data augmentation methods.
- the electronic device after the electronic device obtains the training sample through the method shown in Figure 5 above, it can flip the training sample vertically, horizontally, or 90-degree rotation to get more training sample.
- step 402 the electronic device calls the anti-artifact model to predict the residuals between the original image frame samples and the encoded and compressed image frame samples in each group of training samples, to obtain the sample residuals.
- the schematic steps for the electronic device to learn sample residuals through the de-artifacting model are as follows:
- the electronic device calls the de-artifacting model to perform feature extraction on the coded and compressed image frame samples, and obtains the sample feature vector of the coded and compressed image frame samples.
- the de-artifacting model includes at least two feature extraction units and a first feature fusion layer; at least two feature extraction units are connected in sequence, and the output end of each feature extraction unit is also connected to the input end of the first feature fusion layer connection.
- the electronic device calls each of the at least two feature extraction units to perform feature extraction on the original image frame samples to obtain at least two sample feature sub-vectors; calls the first feature fusion layer to fuse at least two sample feature sub-vectors , Get the sample feature vector.
- the anti-artifact model includes 5 feature extraction units and 1 feature fusion layer.
- the electronic device inputs each set of training samples into the first feature extraction unit, and the first feature extraction unit performs feature extraction on the training samples.
- Obtain the sample feature sub-vector A 1 input the sample feature sub-vector A 1 into the second feature extraction unit, and the second feature extraction unit performs feature extraction on the sample feature sub-vector A 1 to obtain the sample feature sub-vector A 2 ;
- the third feature extraction unit performs feature extraction on the sample feature sub-vector A 2 to obtain the sample feature sub-vector A 3
- the fourth feature extraction unit performs feature extraction on the sample feature sub-vector A 3 to obtain the sample feature sub-vector A 4
- the fifth feature extraction unit performs feature extraction on the sample feature sub-vector A 4 to obtain the sample feature sub-vector A 5 ; input the above-mentioned sample feature sub-vectors A 1 , A 2 , A 3 , A 4 and A 5 into the first
- the amount of model parameters in each feature extraction unit of the at least two feature extraction units that are sequentially connected decreases layer by layer in a direction approaching the first feature fusion layer.
- the electronic device calls the de-artifact model to reduce the dimensionality of the sample feature vector, and obtains the sample feature vector after the dimensionality reduction.
- the electronic device calls the de-artifacting model to reduce the dimensionality of the sample feature vector.
- the de-artifacting model can include the first 1 ⁇ 1 convolutional layer; the sample feature vector is reduced in dimensionality through the first 1 ⁇ 1 convolutional layer, Get the sample feature vector after dimensionality reduction.
- the de-artifacting model may include a first 1 ⁇ 1 convolutional layer, a second 1 ⁇ 1 convolutional layer, a first feature extraction layer, and a second feature fusion layer; call the first 1 ⁇ 1 convolutional layer Reduce the dimensionality of the sample feature vector to obtain the reduced dimensionality of the first sample feature vector; call the second 1 ⁇ 1 convolutional layer to reduce the dimensionality of the sample feature vector to obtain the reduced dimensionality of the second sample feature vector; call the first feature The extraction layer performs feature extraction on the feature vector of the second sample to obtain the feature vector of the second sample after feature extraction; call the second feature fusion layer to fuse the feature vector of the first sample with the feature vector of the second sample after feature extraction, to obtain The sample feature vector after dimensionality reduction.
- the electronic device calls the first 1 ⁇ 1 convolutional layer in the de-artifacting model to reduce the dimensionality of the sample feature vector A 1 A 2 A 3 A 4 A 5 to obtain the reduced dimensionality of the first sample feature vector B 1 ; call the second 1 ⁇ 1 convolutional layer to reduce the dimensionality of the sample feature vector A 1 A 2 A 3 A 4 A 5 to obtain the reduced dimensionality of the second sample feature vector B 2 , call the first feature extraction layer to pair Perform feature extraction on the second sample feature vector B 2 to obtain the second sample feature vector B 3 after feature extraction; call the second feature fusion layer to combine the first sample feature vector B 1 with the feature extracted second sample feature vector B 3 Perform fusion to obtain the sample feature vector B 1 B 3 after dimensionality reduction.
- the electronic device calls the de-artifact model to reconstruct the feature vector of the sample after dimensionality reduction, and obtain the sample residual.
- the de-artifacting model includes a feature reconstruction layer, and the dimensionality-reduced sample feature vector is reconstructed through the feature reconstruction layer to obtain the sample residual.
- the de-artifacting model includes a 3 ⁇ 3 convolutional layer; the 3 ⁇ 3 convolutional layer is used to perform feature reconstruction on the dimensionality-reduced sample feature vector to obtain the sample residual.
- the de-artifacting model includes at least two feature reconstruction layers, and the dimensionality-reduced sample feature vector is reconstructed through the at least two feature reconstruction layers connected in sequence to obtain the sample residual.
- the de-artifacting model includes at least two 3 ⁇ 3 convolutional layers connected in sequence; the feature reconstruction of the sample feature vector after dimensionality reduction is performed through the above-mentioned at least two 3 ⁇ 3 convolution layers connected in sequence , Get the sample residual.
- step 403 the electronic device invokes the de-artifacting model to add the sample residual and the coded and compressed image frame samples to obtain the target image frame sample after the de-artifact processing.
- Step 404 The electronic device determines the loss between the target image frame sample and the original image frame sample.
- the electronic device calls the loss function in the de-artifacting model to calculate the loss between the target image frame sample and the original image frame sample corresponding to the target image frame sample, for example, the target image frame sample and the original image frame corresponding to the target image frame sample The average absolute error, or mean square error, or average deviation error between samples.
- Step 405 The electronic device adjusts the model parameters in the de-artifacting model according to the loss, and trains the residual learning ability of the de-artifacting model.
- the de-artifacting model in the electronic device back-propagates the aforementioned loss, and the model parameters in the de-artifacting model are adjusted through the aforementioned loss to train the residual learning ability of the de-artifacting model.
- the de-artifacting model in the electronic device back-propagates the average absolute error, and the model parameters in the de-artifacting model are adjusted through the above-mentioned average absolute error to train the residual learning ability of the de-artifacting model.
- the machine learning-based de-artifacting model training method trains the de-artifacting model that adopts the residual learning structure, so that the de-artifacting model can pass residual learning after training.
- the de-artifacting model obtained by training can be used to preprocess the video encoding and compression
- the artifacts that may appear in the process can avoid the obvious appearance of multiple types of artifacts in the encoded and compressed video.
- the serial combination of different filters and a large number of tests are required.
- Fig. 6 shows a flowchart of a method for removing artifacts based on machine learning provided by an exemplary embodiment of the present application.
- the method is applied to an electronic device.
- the above-mentioned electronic device may be a terminal or a server.
- Artifact model the method includes:
- Step 501 The electronic device obtains a video to be processed, and the video includes at least two original image frames.
- the above-mentioned video to be processed may be a video uploaded to the electronic device through a physical interface on the electronic device, or may be a video transmitted to the electronic device through a wired or wireless network.
- the electronic device may be a server, the terminal sends a video to the server through a wired or wireless network, and the server receives the video.
- Step 502 The electronic device calls the de-artifacting model to predict the residual between the i-th original image frame of the video and the compressed image frame of the i-th original image frame to obtain the prediction residual of the i-th original image frame.
- the electronic device calls the anti-artifact model to perform residual learning on the video, and the schematic steps are as follows:
- the electronic device calls the artifact removal model to perform feature extraction on the i-th original image frame to obtain the feature vector of the i-th original image frame.
- the de-artifacting model includes at least two feature extraction units and a first feature fusion layer; at least two feature extraction units are connected in sequence, and the output end of each feature extraction unit is also connected to the input end of the first feature fusion layer connection.
- the electronic device calls each of the at least two feature extraction units to perform feature extraction on the i-th original image frame to obtain at least two feature sub-vectors; calls the first feature fusion layer to fuse the at least two feature sub-vectors , Get the feature vector.
- the de-artifacting model includes 3 feature extraction units and 1 feature fusion layer.
- the electronic device inputs each original image frame into the first feature extraction unit, and the first feature extraction unit features the original image frame Extract the feature sub-vector C 1 ; input the feature sub-vector C 1 into the second feature extraction unit, and the second feature extraction unit performs feature extraction on the feature sub-vector C 1 to obtain the feature sub-vector C 2 ; C 2 inputs the third feature extraction unit, and the third feature performs feature extraction on feature sub-vector C 2 to obtain feature sub-vector C 3 ; input the above-mentioned feature sub-vectors C 1 , C 2 and C 3 into the first feature fusion layer Perform feature fusion to obtain the sample feature vector C 1 C 2 C 3 .
- the amount of model parameters in the convolutional layer corresponding to each feature extraction unit of the at least two feature extraction units that are connected in sequence is decreased layer by layer in the direction close to the feature fusion layer, for example, the above-mentioned sequentially connected 3
- the first feature extraction unit corresponds to 10,000 model parameters in the convolutional layer
- the second feature extraction unit corresponds to 5000 model parameters in the convolutional layer
- the third feature extraction unit corresponds to There are 3000 model parameters in the convolutional layer.
- the de-artifacting model in the electronic device extracts the feature vector through at least two feature extraction units connected in sequence.
- the electronic device calls the artifact removal model to reduce the dimensionality of the feature vector, and obtains the feature vector after the dimensionality reduction.
- the de-artifacting model includes a first 1 ⁇ 1 convolutional layer; the electronic device reduces the dimensionality of each feature vector through the first 1 ⁇ 1 convolutional layer in the de-artifacting model to obtain the reduced dimensionality Feature vector.
- the de-artifacting model includes a first 1 ⁇ 1 convolutional layer, a second 1 ⁇ 1 convolutional layer, a first feature extraction layer, and a second feature fusion layer; the electronic device calls the first 1 ⁇ 1 convolution The dimensionality of the feature vector is reduced by layer to obtain the first feature vector after dimensionality reduction; the second 1 ⁇ 1 convolutional layer is called to reduce the dimensionality of the feature vector to obtain the second feature vector after dimensionality; the first feature extraction layer is called for the first feature vector Perform feature extraction on two feature vectors to obtain the second feature vector after feature extraction; call the second feature fusion layer to fuse the first feature vector with the second feature vector after feature extraction to obtain the feature vector after dimensionality reduction.
- the electronic device calls the de-artifacting model to perform feature reconstruction on the dimensionality-reduced feature vector, and obtains the prediction residual between the i-th original image frame and the compressed image frame of the i-th original image frame.
- the de-artifacting model includes a feature reconstruction layer; the electronic device performs feature reconstruction on the dimensionality-reduced feature vector through the feature reconstruction layer in the de-artifacting model to obtain the i-th original image frame and the i-th original image Prediction residuals between image frames after frame compression.
- the feature reconstruction layer is a 3 ⁇ 3 convolutional layer; the electronic device uses the 3 ⁇ 3 convolutional layer in the de-artifacting model to perform feature reconstruction on the dimensionality-reduced feature vector to obtain the i-th original image frame and the Prediction residuals between compressed image frames of i original image frames.
- the de-artifacting model includes at least two feature reconstruction layers that are sequentially connected; the electronic device performs feature reconstruction on the dimensionality-reduced feature vector through the at least two feature reconstruction layers in the de-artifacting model to obtain the i-th The prediction residual between the original image frame and the compressed image frame of the i-th original image frame.
- the de-artifacting model includes at least two 3 ⁇ 3 convolutional layers sequentially connected; the electronic device performs dimensionality reduction on the feature vector through at least two 3 ⁇ 3 convolutional layers in the de-artifacting model. Reconstruction of features to obtain prediction residuals.
- the de-artifacting model further includes a second feature extraction layer; the electronic device uses the second feature extraction layer in the de-artifacting model to perform feature extraction on the dimensionality-reduced feature vectors to obtain candidate feature vectors;
- the feature vector is input to at least two feature reconstruction layers to perform feature reconstruction, and the prediction residual between the i-th original image frame and the compressed image frame of the i-th original image frame is obtained.
- step 503 the electronic device calls the de-artifacting model to add the prediction residual to the i-th original image frame to obtain the target image frame after the de-artifact processing.
- the electronic device calls the anti-artifact model to add the prediction residual of the i-th original image frame to the i-th original image frame to obtain the target image frame after the anti-artifact processing.
- at least two original image frames correspond to At least two target image frames.
- the step of the electronic device calling the anti-artifact model to add the prediction residual and the i-th original image frame to obtain the target image frame is a step of the electronic device performing pre-compression processing on the video.
- the electronic device needs to perform de-artifact processing before compressing the video.
- Step 504 The electronic device sequentially encodes and compresses the at least two target image frames corresponding to the at least two original image frames to obtain a de-artifacted video frame sequence.
- An encoding compression module is provided in the electronic device, and at least two target image frames are sequentially encoded and compressed by the encoding compression module to obtain a de-artifacted video frame sequence.
- the above-mentioned de-artifacted video frame sequence is a video frame after encoding and compression, and the video played by the user on the terminal is obtained by decompressing the above-mentioned de-artifacted video frame sequence.
- the method for removing artifacts based on machine learning preprocesses the artifacts that may be generated in the video compression process by using the artifact removal model of the residual learning structure, and the residual learning is accurate
- the de-artifact model is used to preprocess the video encoding and compression process that may occur Artifacts, to avoid the obvious appearance of multiple types of artifacts in the encoded and compressed video.
- the peak signal to noise ratio (Peak Signal to Noise Ratio, PSNR) is used to measure image quality, and the structural similarity (Structural SIMilarity index, SSIM) is used to measure the similarity between two images; PSNR is used in the experiment Perform the performance test of the de-artifact model with the two indicators of SSIM.
- PSNR Peak Signal to Noise Ratio
- structural similarity index Structural SIMilarity index
- Fig. 7 shows the decompression effect before the de-artifacting process by the de-artifacting model
- Fig. 8 shows the decompression effect after the de-artifacting process. It can be clearly seen that the image The burrs are significantly reduced, the contours are cleaner, and the subjective quality is significantly enhanced. Also take the de-artifacting model to remove the ringing effect as an example, as shown in Figure 9.
- the left picture is the original image frame that has not been processed by the de-artifacting model, and the right picture is the image frame processed by the de-artifacting model.
- the comparison clearly shows that there is a large amount of ringing effect in the center area of the upper and lower half of the image, and the ringing effect can be effectively removed by the de-artifacting model processing.
- de-artifacting method based on machine learning can be widely used in different video-related application scenarios such as online video, online games, video surveillance, and video publishing.
- the first game terminal receives an operation event triggered by the user and reports the operation time to the server; the server according to the first game terminal The reported operation event updates the video screen of the online game; the server is equipped with a de-artifacting model, and the server calls the de-artifacting model to de-artifactize the updated video screen, and perform the de-artifacting process on the video screen.
- the first terminal uses a camera to record a picture within the shooting range, and uploads the recorded video to the server;
- a de-artifacting model is set.
- the server calls the de-artifacting model to de-artifactize the video uploaded by the first terminal, encodes and compresses the de-artifacted video picture, and sends the encoded and compressed video picture to the first terminal.
- Two terminals; the second terminal decompresses and plays the above-mentioned encoded and compressed video pictures.
- the second terminal is also recording video, and the corresponding server sends the de-artifacting encoded and compressed video to the first terminal for playback.
- the first terminal uploads the stored video to the server; a de-artifacting model is set in the server, and the server calls the de-artifacting model to
- the video uploaded by the first terminal undergoes anti-artifact processing, encodes and compresses the video images that have undergone the anti-artifact processing, and sends the encoded and compressed video images to the second terminal; the second terminal receives the user’s trigger for the video Play the video after the playback operation.
- the anti-artifact methods based on machine learning can effectively remove multiple types of artifacts in the encoded and compressed video, and improve the user's visual experience.
- first and second in this application do not carry any sorting meaning, and are only used to distinguish different things, for example, “the first game terminal” and “the second game terminal” The “first” and “second” in “are used to distinguish two different gaming terminals.
- Fig. 10 shows a block diagram of a device for removing artifacts based on machine learning provided by an exemplary embodiment of the present application.
- the device is implemented as part or all of a terminal or a server through software, hardware, or a combination of the two.
- the device includes:
- the first obtaining module 601 is configured to obtain a video to be processed, and the video includes at least two original image frames;
- the first calling module 602 is used to call the artifact removal model to predict the residual between the i-th original image frame of the video and the compressed image frame of the i-th original image frame to obtain the prediction residual of the i-th original image frame Difference, i is a positive integer;
- the first calling module 602 is used to call the de-artifacting model to add the prediction residual to the i-th original image frame to obtain the target image frame after the de-artifact processing;
- the encoding module 603 is configured to sequentially encode and compress at least two target image frames corresponding to the at least two original image frames to obtain a de-artifacted video frame sequence.
- the first calling module 602 is used to call the anti-artifact model to perform feature extraction on the i-th original image frame to obtain the feature vector of the i-th original image frame; call the anti-artifact model to reduce the feature vector Dimension, get the feature vector after dimensionality reduction; call the de-artifact model to reconstruct the feature vector after dimensionality, and get the prediction residual.
- the de-artifacting model includes at least two feature extraction units and a first feature fusion layer, at least two feature extraction units are connected in sequence, and the output end of each feature extraction unit is also connected to the first feature fusion layer.
- the first calling module 602 is configured to call each of the at least two feature extraction units to perform feature extraction on the i-th original image frame to obtain at least two feature sub-vectors; call the first feature fusion layer to perform feature extraction on the i-th original image frame; The eigenvectors are merged to obtain the eigenvector.
- the de-artifacting model includes a first 1 ⁇ 1 convolutional layer, a second 1 ⁇ 1 convolutional layer, a first feature extraction layer, and a second feature fusion layer;
- the first calling module 602 is used to call the first 1 ⁇ 1 convolutional layer to reduce the dimensionality of the feature vector to obtain the reduced dimensionality of the first feature vector; call the second 1 ⁇ 1 convolutional layer to reduce the dimensionality of the feature vector to obtain the reduced dimensionality Dimensional second feature vector; call the first feature extraction layer to perform feature extraction on the second feature vector to obtain the second feature vector after feature extraction; call the second feature fusion layer to extract the first feature vector and the first feature vector after feature extraction The two feature vectors are fused to obtain the feature vector after dimensionality reduction.
- the anti-artifact device based on machine learning preprocesses the artifacts that may be generated in the video compression process by adopting the anti-artifact model of the residual learning structure, and is accurate through residual learning.
- the de-artifact model is used to preprocess the video encoding and compression process that may occur Artifacts, to avoid the obvious appearance of multiple types of artifacts in the encoded and compressed video.
- FIG. 11 shows a block diagram of a device for de-artifacting model training based on machine learning provided by an exemplary embodiment of the present application.
- the device is implemented as part or all of a terminal or a server through software, hardware, or a combination of the two. include:
- the second acquisition module 701 is configured to acquire training samples, and each group of training samples includes original image frame samples of video samples and image frame samples encoded and compressed by the original image frame samples;
- the second calling module 702 is used to call a de-artifacting model to predict the residuals between the original image frame samples and the encoded and compressed image frame samples in each group of training samples to obtain the sample residuals;
- the second calling module 702 is used to call the de-artifacting model to add the sample residual and the coded and compressed image frame samples to obtain the target image frame sample after the de-artifact processing;
- the training module 703 is used to determine the loss between the target image frame sample and the original image frame sample, and adjust the model parameters in the de-artifacting model according to the loss, and train the residual learning ability of the de-artifacting model.
- the second calling module 702 is used to call the de-artifact model to perform feature extraction on the coded and compressed image frame samples to obtain the sample feature vector of the coded and compressed image frame samples; call the de-artifacting model to The dimensionality of the sample feature vector is reduced, and the dimensionality-reduced sample feature vector is obtained; the artifact removal model is used to perform feature reconstruction on the dimensionality-reduced sample feature vector, and the sample residual is obtained.
- the de-artifacting model includes at least two feature extraction units and a first feature fusion layer, at least two feature extraction units are connected in sequence, and the output end of each feature extraction unit is also connected to the first feature fusion layer.
- the second calling module 702 is configured to call each of the at least two feature extraction units to perform feature extraction on the original image frame samples to obtain at least two sample feature sub-vectors; call the first feature fusion layer to perform feature extraction on at least two The sample feature sub-vectors are fused to obtain the sample feature vector.
- the de-artifacting model includes a first 1 ⁇ 1 convolutional layer, a second 1 ⁇ 1 convolutional layer, a first feature extraction layer, and a second feature fusion layer;
- the second calling module 702 is used to call the first 1 ⁇ 1 convolutional layer to reduce the dimensionality of the sample feature vector to obtain the reduced dimensionality of the first sample feature vector; call the second 1 ⁇ 1 convolutional layer to reduce the sample feature vector Dimension, get the second sample feature vector after dimensionality reduction; call the first feature extraction layer to perform feature extraction on the second sample feature vector to obtain the second sample feature vector after feature extraction; call the second feature fusion layer to make the first This feature vector is fused with the feature vector of the second sample after feature extraction to obtain the sample feature vector after dimensionality reduction.
- the machine learning-based anti-artifact model training device trains the anti-artifact model using the residual learning structure, so that the anti-artifact model can pass residual learning after training.
- the de-artifacting model obtained by training can be used to preprocess the video encoding and compression Artifacts that may appear in the process, to avoid the obvious effect of multiple types of artifacts in the encoded and compressed video.
- the serial combination of different filters and a large number of tests are required. In order to achieve the desired effect of removing artifacts, a large amount of test costs can be saved, and the problem of unified processing of multiple types of artifacts can be avoided.
- FIG. 12 shows a structural block diagram of a terminal 800 provided by an exemplary embodiment of the present application.
- the terminal 800 can be: a smart phone, a tablet computer, an MP3 player (Moving Picture Experts Group Audio Layer III, moving picture expert compression standard audio layer 3), MP4 (Moving Picture Experts Group Audio Layer IV, moving picture expert compressing standard audio Level 4) Player, laptop or desktop computer.
- the terminal 800 may also be called user equipment, portable terminal, laptop terminal, desktop terminal and other names.
- the terminal 800 includes a processor 801 and a memory 802.
- the processor 801 may include one or more processing cores, such as a 4-core processor, an 8-core processor, and so on.
- the processor 801 may adopt at least one hardware form among DSP (Digital Signal Processing), FPGA (Field-Programmable Gate Array), and PLA (Programmable Logic Array, Programmable Logic Array). achieve.
- the processor 801 may also include a main processor and a coprocessor.
- the main processor is a processor used to process data in the wake state, also called a CPU (Central Processing Unit, central processing unit); the coprocessor is A low-power processor used to process data in the standby state.
- the processor 801 may be integrated with a GPU (Graphics Processing Unit, image processor), and the GPU is used to render and draw content that needs to be displayed on the display screen.
- the processor 801 may further include an AI (Artificial Intelligence) processor, and the AI processor is used to process computing operations related to machine learning.
- AI Artificial Intelligence
- the memory 802 may include one or more computer-readable storage media, which may be non-transitory.
- the memory 802 may also include high-speed random access memory and non-volatile memory, such as one or more magnetic disk storage devices and flash memory storage devices.
- the non-transitory computer-readable storage medium in the memory 802 is used to store at least one instruction, and the at least one instruction is used to be executed by the processor 801 to implement the machine-based Learned anti-artifact method and training method of anti-artifact model.
- the terminal 800 may optionally further include: a peripheral device interface 803 and at least one peripheral device.
- the processor 801, the memory 802, and the peripheral device interface 803 may be connected by a bus or a signal line.
- Each peripheral device can be connected to the peripheral device interface 803 through a bus, a signal line, or a circuit board.
- the peripheral device includes: at least one of a radio frequency circuit 804, a display screen 805, an audio circuit 806, a positioning component 807, and a power supply 808.
- the peripheral device interface 803 can be used to connect at least one peripheral device related to I/O (Input/Output) to the processor 801 and the memory 802.
- the processor 801, the memory 802, and the peripheral device interface 803 are integrated on the same chip or circuit board; in some other embodiments, any one of the processor 801, the memory 802, and the peripheral device interface 803 or The two can be implemented on a separate chip or circuit board, which is not limited in this embodiment.
- the radio frequency circuit 804 is used for receiving and transmitting RF (Radio Frequency, radio frequency) signals, also called electromagnetic signals.
- the radio frequency circuit 804 communicates with a communication network and other communication devices through electromagnetic signals.
- the radio frequency circuit 804 converts electrical signals into electromagnetic signals for transmission, or converts received electromagnetic signals into electrical signals.
- the radio frequency circuit 804 includes: an antenna system, an RF transceiver, one or more amplifiers, a tuner, an oscillator, a digital signal processor, a codec chipset, a user identity module card, and so on.
- the radio frequency circuit 804 can communicate with other terminals through at least one wireless communication protocol.
- the wireless communication protocol includes, but is not limited to: metropolitan area networks, various generations of mobile communication networks (2G, 3G, 4G, and 5G), wireless local area networks, and/or WiFi (Wireless Fidelity, wireless fidelity) networks.
- the radio frequency circuit 804 may also include a circuit related to NFC (Near Field Communication), which is not limited in this application.
- the display screen 805 is used to display UI (User Interface, user interface).
- the UI can include graphics, text, icons, videos, and any combination thereof.
- the display screen 805 also has the ability to collect touch signals on or above the surface of the display screen 805.
- the touch signal can be input to the processor 801 as a control signal for processing.
- the display screen 805 may also be used to provide virtual buttons and/or virtual keyboards, also called soft buttons and/or soft keyboards.
- the display screen 805 may be one display screen 805, which is provided with the front panel of the terminal 800; in other embodiments, there may be at least one display screen 805, which are respectively provided on different surfaces of the terminal 800 or in a folding design;
- the display screen 805 may be a flexible display screen, which is arranged on a curved surface or a folding surface of the terminal 800.
- the display screen 805 can also be set as a non-rectangular irregular pattern, that is, a special-shaped screen.
- the display screen 805 may be made of materials such as LCD (Liquid Crystal Display), OLED (Organic Light-Emitting Diode, organic light-emitting diode).
- the audio circuit 806 may include a microphone and a speaker.
- the microphone is used to collect sound waves of the user and the environment, and convert the sound waves into electrical signals to be input to the processor 801 for processing, or input to the radio frequency circuit 804 to implement voice communication. For the purpose of stereo collection or noise reduction, there may be multiple microphones, which are set in different parts of the terminal 800 respectively.
- the microphone can also be an array microphone or an omnidirectional collection microphone.
- the speaker is used to convert the electrical signal from the processor 801 or the radio frequency circuit 804 into sound waves.
- the speaker can be a traditional thin-film speaker or a piezoelectric ceramic speaker.
- the speaker When the speaker is a piezoelectric ceramic speaker, it can not only convert the electrical signal into human audible sound waves, but also convert the electrical signal into human inaudible sound waves for distance measurement and other purposes.
- the audio circuit 806 may also include a headphone jack.
- the positioning component 807 is used to locate the current geographic location of the terminal 800 to implement navigation or LBS (Location Based Service, location-based service).
- the positioning component 807 may be a positioning component based on the GPS (Global Positioning System, Global Positioning System) of the United States, the Beidou system of China, the Granus system of Russia, or the Galileo system of the European Union.
- the power supply 808 is used to supply power to various components in the terminal 800.
- the power source 808 may be alternating current, direct current, disposable batteries, or rechargeable batteries.
- the rechargeable battery may support wired charging or wireless charging.
- the rechargeable battery can also be used to support fast charging technology.
- FIG. 12 does not constitute a limitation on the terminal 800, and may include more or fewer components than shown in the figure, or combine some components, or adopt different component arrangements.
- Fig. 13 shows a schematic structural diagram of a server provided by an embodiment of the present application.
- the server is used to implement the de-artifacting method based on machine learning and the de-artifacting model training method provided in the above embodiments. Specifically:
- the server 900 includes a central processing unit (CPU, Central Processing Unit) 901, a system memory 904 including a random access memory (RAM, Random Access Memory) 902 and a read only memory (ROM, Read Only Memory) 903, and a connection system
- the server 900 also includes a basic input/output system (I/O system, Input Output System) 906 that helps to transfer information between various devices in the computer, and a module 915 for storing the operating system 913, application programs 914, and other programs.
- the basic input/output system 906 includes a display 908 for displaying information and an input device 909 such as a mouse and a keyboard for the user to input information.
- the display 908 and the input device 909 are both connected to the central processing unit 901 through the input and output controller 910 connected to the system bus 905.
- the basic input/output system 906 may also include an input and output controller 910 for receiving and processing input from multiple other devices such as a keyboard, a mouse, or an electronic stylus.
- the input and output controller 910 also provides output to a display screen, a printer, or other types of output devices.
- the mass storage device 907 is connected to the central processing unit 901 through a mass storage controller (not shown) connected to the system bus 905.
- the mass storage device 907 and its associated computer readable medium provide non-volatile storage for the server 900. That is, the mass storage device 907 may include a computer readable medium (not shown) such as a hard disk or a compact disc read only memory (CD-ROM, Compact Disc Read Only Memory) drive.
- a computer readable medium such as a hard disk or a compact disc read only memory (CD-ROM, Compact Disc Read Only Memory) drive.
- Computer-readable media may include computer storage media and communication media.
- Computer storage media includes volatile and nonvolatile, removable and non-removable media implemented in any method or technology for storing information such as computer readable instructions, data structures, program modules or other data.
- Computer storage media include RAM, ROM, Erasable Programmable Read Only Memory (EPROM, Electrically Erasable Programmable Read Only Memory), flash memory or other solid-state storage Its technology, CD-ROM, Digital Versatile Disc (DVD, Digital Versatile Disc) or Solid State Drives (SSD, Solid State Drives), other optical storage, tape cartridges, magnetic tape, disk storage or other magnetic storage devices.
- the random access memory may include resistive random access memory (ReRAM, Resistance Random Access Memory) and dynamic random access memory (DRAM, Dynamic Random Access Memory).
- ReRAM resistive random access memory
- DRAM Dynamic Random Access Memory
- the computer storage medium is not limited to the foregoing.
- the aforementioned system memory 904 and mass storage device 907 may be collectively referred to as a memory.
- the server 900 may also be connected to a remote computer on the network to run through a network such as the Internet. That is, the server 900 can be connected to the network 912 through the network interface unit 911 connected to the system bus 905, or in other words, can also use the network interface unit 911 to connect to other types of networks or remote computer systems (not shown) .
- the present application also provides a computer device, the computer device comprising: a processor and a memory, the memory stores at least one instruction, at least one program, code set or instruction set, at least one instruction, at least one program, code set or The instruction set is loaded and executed by the processor to implement the anti-artifact method based on machine learning and the anti-artifact model training method provided by the foregoing method embodiments.
- the present application also provides a computer-readable storage medium in which at least one instruction, at least one program, code set or instruction set is stored, and the at least one instruction, at least one program, code set or instruction set is processed by the The device is loaded and executed to implement the anti-artifact method based on machine learning and the anti-artifact model training method provided by the foregoing method embodiments.
- the application also provides a computer program product.
- the computer program product includes computer instructions, and the computer instructions are stored in a computer-readable storage medium.
- the processor of the computer device reads the above-mentioned computer instructions from the computer-readable storage medium, and the processor executes the above-mentioned computer instructions, so that the above-mentioned computer device executes the method for removing artifacts based on machine learning provided in the various optional implementations of the previous aspect. , And the training method of de-artifacting model.
- the program can be stored in a computer-readable storage medium.
- the storage medium mentioned can be a read-only memory, a magnetic disk or an optical disk, etc.
Landscapes
- Engineering & Computer Science (AREA)
- Theoretical Computer Science (AREA)
- Physics & Mathematics (AREA)
- Data Mining & Analysis (AREA)
- Evolutionary Computation (AREA)
- General Physics & Mathematics (AREA)
- Multimedia (AREA)
- Artificial Intelligence (AREA)
- Software Systems (AREA)
- General Engineering & Computer Science (AREA)
- Signal Processing (AREA)
- Life Sciences & Earth Sciences (AREA)
- Computing Systems (AREA)
- Mathematical Physics (AREA)
- General Health & Medical Sciences (AREA)
- Health & Medical Sciences (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Biomedical Technology (AREA)
- Molecular Biology (AREA)
- Computational Linguistics (AREA)
- Biophysics (AREA)
- Evolutionary Biology (AREA)
- Bioinformatics & Computational Biology (AREA)
- Medical Informatics (AREA)
- Bioinformatics & Cheminformatics (AREA)
- Quality & Reliability (AREA)
- Databases & Information Systems (AREA)
- Compression Or Coding Systems Of Tv Signals (AREA)
- Image Analysis (AREA)
Abstract
本申请公开了一种基于机器学习的去伪影方法、去伪影模型训练方法及装置,涉及人工智能领域。上述方法包括:通过获取待处理的视频;调用去伪影模型预测视频的第i个原始图像帧的残差,得到第i个原始图像帧的预测残差;调用去伪影模型将预测残差与对应的原始图像帧相加,得到去伪影处理后的目标图像帧;将至少两个目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。该方法通过采用残差学习结构的去伪影模型对视频压缩过程中可能产生的伪影进行预处理,避免编码压缩后视频明显地出现多类伪影,可以解决对多类伪影统一处理的难题。
Description
本申请要求于2019年10月16日提交的申请号为201910984591.3、发明名称为“基于机器学习的去伪影方法、去伪影模型训练方法及装置”的中国专利申请的优先权,其全部内容通过引用结合在本申请中。
本申请涉及人工智能领域,特别涉及一种基于机器学习的去伪影方法、去伪影模型训练方法及装置。
互联网视频数据急剧增长,为了降低视频的存储和传输成本,会采用较高的压缩率对视频进行编码压缩。
在视频编码压缩的过程中,由于量化、分块等移除高频信息的操作导致信息损失,从而出现伪影这一负面效果,比如,块效应、振铃效应和边缘毛刺等。上述伪影会严重降低视频画质,影响用户的观看体验。因此,需要在视频编码压缩的过程中加入去伪影这一步骤。传统的视频去伪影是通过视频增强滤波器进行图像的亮度调整、饱和度调整、锐化以及去噪等操作来实现的。
但是,视频增强滤波器的主要功能是对平坦像素区域的随机噪声的去除,对于视频伪影的去除效果有限。
发明内容
本申请实施例提供了一种基于机器学习的去伪影方法、去伪影模型训练方法及装置,可以通过去伪影模型对视频在编码压缩过程中可能出现的伪影进行预处理,避免编码压缩后的视频明显地出现多类伪影。所述技术方案如下:
根据本申请的一个方面,提供了一种基于机器学习的去伪影方法,应用于电子设备中,该方法包括:
获取待处理的视频,该视频包括至少两个原始图像帧;
调用去伪影模型预测视频的第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的残差,得到第i个原始图像帧的预测残差,i为正整数;
调用去伪影模型将预测残差与第i个原始图像帧相加,得到去伪影处理后的 目标图像帧;
将至少两个原始图像帧对应的至少两个目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。
根据本申请的另一个方面,提供了一种基于机器学习的去伪影模型训练方法,应用于电子设备中,该方法包括:
获取训练样本,每组训练样本包括视频样本的原始图像帧样本和原始图像帧样本编码压缩后的图像帧样本;
调用去伪影模型预测每组训练样本中原始图像帧样本与编码压缩后的图像帧样本之间的残差,得到样本残差;
调用去伪影模型将样本残差与编码压缩后的图像帧样本相加,得到去伪影处理后的目标图像帧样本;
确定目标图像帧样本与原始图像帧样本之间的损失,并根据损失对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。
根据本申请的另一方面,提供了一种基于机器学习的去伪影装置,该装置包括:
第一获取模块,用于获取待处理的视频,该视频包括至少两个原始图像帧;
第一调用模块,用于调用去伪影模型预测视频的第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的残差,得到第i个原始图像帧的预测残差,i为正整数;
第一调用模块,用于调用去伪影模型将预测残差与第i个原始图像帧相加,得到去伪影处理后的目标图像帧;
编码模块,用于将至少两个原始图像帧对应的至少两个目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。
根据本申请的另一方面,提供了一种基于机器学习的去伪影模型训练装置,该装置包括:
第二获取模块,用于获取训练样本,每组训练样本包括视频样本的原始图像帧样本和原始图像帧样本编码压缩后的图像帧样本;
第二调用模块,用于调用去伪影模型预测每组训练样本中原始图像帧样本与编码压缩后的图像帧样本之间的残差,得到样本残差;
第二调用模块,用于调用去伪影模型将样本残差与编码压缩后的图像帧样本相加,得到去伪影处理后的目标图像帧样本;
训练模块,用于确定目标图像帧样本与原始图像帧样本之间的损失,并根据损失对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。
根据本申请的另一方面,提供了一种电子设备,该电子设备包括:
存储器;
与存储器相连的处理器;
其中,处理器被配置为加载并执行可执行指令以实现如上述一个方面及其可选实施例所述的基于机器学习的去伪影方法,以及如上述另一方面及其可选实施例所述的基于机器学习的去伪影模型训练方法。
根据本申请的另一方面,提供了一种计算机可读存储介质,上述计算机可读存储介质中存储有至少一条指令、至少一段程序、代码集或指令集,上述至少一条指令、至少一段程序、代码集或指令集由处理器加载并执行以实现如上述一个方面及其可选实施例所述的基于机器学习的去伪影方法,以及如上述另一方面及其可选实施例所述的基于机器学习的去伪影模型训练方法。
根据本申请的另一方面,提供了一种计算机程序产品,上述计算机程序产品包括计算机指令,上述计算机指令存储在计算机可读存储介质中。计算机设备的处理器从计算机可读存储介质读取上述计算机指令,处理器执行上述计算机指令,使得上述计算机设备执行如上述一个方面及其可选实施例所述的基于机器学习的去伪影方法,以及如上述另一方面及其可选实施例所述的基于机器学习的去伪影模型训练方法。
本申请实施例提供的技术方案带来的有益效果至少包括:
该方法通过采用残差学习结构的去伪影模型对视频在压缩过程中可能产生的伪影进行预处理,通过残差学习准确的在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使压缩并解压后的视频帧的质量更高;通过去伪影模型来预处理视频编码压缩过程中可能出现的伪影,避免编码压缩后的视频明显地出现多类伪影,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以解决对多类伪影统一处理的难题。
图1是本申请一个示例性实施例提供的基于机器学习的去伪影模型框架的结构示意图;
图2是本申请一个示例性实施例提供的基于机器学习的去伪影模型的应用框架的结构示意图;
图3是本申请一个示例性实施例提供的计算机系统的结构示意图;
图4是本申请一个示例性实施例提供的基于机器学习的去伪影模型训练方法的流程图;
图5是本申请一个示例性实施例提供的训练样本的生成流程的示意图;
图6是本申请一个示例性实施例提供的基于机器学习的去伪影方法的流程图;
图7是本申请一个示例性实施例提供的对未经去伪影模型处理的视频帧解压缩后显示的示意图;
图8是本申请一个示例性实施例提供的对经去伪影模型处理的视频帧解压缩后显示的示意图;
图9是本申请一个示例性实施例提供的未经去伪影模型处理的视频帧与经去伪影模型处理的视频帧分别解压缩后显示的对比示意图;
图10是本申请一个示例性实施例提供的基于机器学习的去伪影装置的框图;
图11是本申请一个示例性实施例提供的基于机器学习的去伪影模型训练装置的框图;
图12是本申请一个示例性实施例提供的终端的结构示意图;
图13是本申请一个示例性实施例提供的服务器的结构示意图。
首先,对本申请涉及的若干个名词进行解释:
视频编解码:是一种视频压缩技术,实质上是通过减少视频图像中的冗余像素来实现对视频的压缩。其中,最为重要的视频编解码标准包括国际电信联盟的视频编码标准H.261、H.263、H.264,运动静止图像专家组(Motion-Joint Photographic Exoerts Group,M-JPEG),以及国际标准化组织的运动图像专家组(Moving Picture Experts Group,MPEG)系列标准;此外,视频编解码标准还包括互联网上的RealVideo视频格式,Windows媒体视频格式(Windows Media Video,WMV),以及QuickTime等。
一般情况下,视频压缩包括:有损压缩。也就是说,在视频编码压缩的过程中,由于像素的量化、分块等移除高频信息的操作会导致视频图像的信息损失,出现包括块效应、振铃效应和边缘毛刺等的负面效果。上述负面效果即为伪影。
上述“块效应”是指在视频编码过程中,由于对视频图像划分宏块进行编码压缩的方式导致视频图像的相关性被破坏,从而产生可见的小块边界处的不连续。
上述“振铃效应”是指通过滤波器对视频图像处理的过程中,滤波器具有陡峭的变化,导致滤波器输出视频图像的灰度剧烈变化处产生震荡。
上述“边缘毛刺”是指由于对相同视频图像进行了多次编码,导致视频图像内容严重损失,在视频图像的主体边缘处产生的随机刺状效应。
本申请提供了一种基于机器学习的去伪影模型,能够在视频编码压缩的过程中达到更佳地对视频图像的去伪影效果。示意性的,如图1,上述基于机器学习的去伪影模型包括:
输入层101、特征提取模块102、特征重建模块103和输出层104;
特征提取模块102包括至少两个特征提取单元11与第一特征融合层12;至少两个特征提取单元11顺次连接,顺次连接的至少两个特征提取单元11中首部的特征提取单元11的输入端还与输入层101的输出端连接;每一个特征提取单元11的输出端与第一特征融合层12的输入端相连。
特征重建模块103包括降维单元21与特征重建单元22;降维单元21的输入端与第一特征融合层12的输出端相连、降维单元21的输出端与特征重建单元22的输入端相连;特征重建单元22的输出端与输出层104的输入端相连;输出层104的输入端还与输入层101的输出端相连。
在一些实施例中,降维单元21包括第一1×1卷积层31。
在一些实施例中,降维单元21包括第一1×1卷积层31、第二1×1卷积层32、第一特征提取层33和第二特征融合层34;
第一1×1卷积层31的输入端与第一特征融合层12的输出端相连,第一1×1卷积层31的输出端与第二特征融合层34的输入端相连;
第二1×1卷积层32的输入端与第一特征融合层12的输出端相连,第二1×1卷积层32的输出端与第一特征提取层33的输入端相连,第一特征提取层33的 输出端与第二特征融合层34的输入端相连。
在一些实施例中,每一个特征提取单元11对应的卷积层中模型参数量是按照远离输入层101的方向逐层递减的。示意性的,模型参数量可以包括卷积核的尺寸、卷积核的通道数中的至少一种。比如,与输入层101连接的第一个特征提取单元11的模型参数量为m
1,与第一个特征提取单元11连接的第二个特征提取单元11的模型参数量为m
2,其中,m
1大于m
2,m
1与m
2为正整数。
在一些实施例中,特征重建单元22包括特征重建层41;特征重建层41的输入端与第二特征融合层34的输出端相连,特征重建层41的输出端与输出层104的输入端相连。示意性的,特征重建层41可以是3×3卷积层。
在一些实施例中,特征重建单元22还包括第二特征提取层42;第二特征提取层42与特征重建层41连接,第二特征提取层42的输入端与第二特征融合层34的输出端相连,第二特征提取层42的输出端与特征重建层41的输入端相连。
示意性的,图1中特征重建单元22包括了两个特征重建层41和一个第二特征提取层42,上述两个特征重建层41与第二特征提取层42连接,第二特征提取层42的输入端与第二特征融合层34的输出端相连,第一个特征重建层41的输入端与第二特征提取层42的输出端相连,第二个特征重建层41(即远离第二特征提取层42的特征重建层41)的输入端与第一个特征重建层41的输出端相连,第二个特征重建层41的输出端与输出层104的输入端相连。
示意性的,在上述基于机器学习的去伪影模型中各个特征提取层与各个特征重建层均采用了卷积网络,上述卷积网络中卷积核的大小为3,步长为1,填充(padding)为1;其中,上述填充用于定义元素边框与元素内容之间的空间。
上述基于机器学习的去伪影模型的整体架构采用了残差学习的结构,通过残差学习在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使解压后的视频帧的质量更高;且通过训练基于机器学习的去伪影模型来预处理视频编码压缩过程中可能出现的伪影,避免编码压缩后的视频明显地出现多类伪影,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以解决对多类伪影统一处理的难题。
示意性的,应用上述基于机器学习的去伪影模型进行视频编码压缩的实现框架200,如图2所示,包括了前处理模块201和压缩模块202。基于机器学习的去伪影模型51设置在前处理模块201中,用于对图像帧进行压缩前的去伪影 处理;前处理模块201还包括去噪单元52、以及增强单元53,其中,去噪单元52用于去除图像帧中的噪声,增强单元53用于增强图像帧中像素点的信号强度。
压缩模块202包括了信号整形单元61、比特率确定单元62、区域压缩单元63、以及编码器64。信号整形单元61用于对经过前处理模块201进行压缩前处理后的图像帧的信号进行整形,比如,将波形缩小;比特率确定单元62用于确定图像帧压缩的比特率;区域压缩单元63用于通过编码器64对图像帧进行分区域压缩。
最终,经过上述前处理模块201与压缩模块202的编码压缩处理,得到视频的压缩帧。
在一些业务应用场景中,上述实现框架200被设置于服务器中,由服务器通过上述实现框架200实现对视频的编码压缩,如图3,示出了本申请一示例性实施例提供的计算机系统的结构示意图,该计算机系统包括第一终端301、服务器302、第二终端303。
第一终端301、第二终端303分别与服务器302之间通过有线或者无线网络相互连接。
可选地,第一终端301可以包括笔记本电脑、台式电脑、智能手机、平板电脑中的至少一种。示意性的,第一终端301通过有线或者无线网络将拍摄得到的视频上传至服务器302;或者,第一终端301通过有线或者无线网络将本地存储的视频上传至服务器302,本地存储的视频可以是从网站下载的或者其他设备传输至第一终端301的。
服务器302包括存储器和处理器。存储器中存储有程序,上述程序被处理器调用来实现本申请提供的基于机器学习的去伪影方法中服务器侧执行的步骤。可选地,存储器中存储有基于机器学习的去伪影模型,上述基于机器学习的去伪影模型被处理器调用以实现上述基于机器学习的去伪影方法中服务器侧执行的步骤。
可选地,存储器可以包括但不限于以下几种:随机存取存储器(Random Access Memory,RAM)、只读存储器(Read Only Memory,ROM)、可编程只读存储器(Programmable Read-Only Memory,PROM)、可擦除只读存储器(Erasable Programmable Read-Only Memory,EPROM)、以及电可擦除只读存储器(Electric Erasable Programmable Read-Only Memory,EEPROM)。
示意性的,服务器302在接收到第一终端301上传的视频之后,调用实现框架200中的前处理模块201对视频进行压缩前处理;关于对视频的去伪影处理,服务器302调用基于机器学习的去伪影模型预测视频的第i个原始图像帧与第i个原始图像帧编码压缩后的图像帧之间的残差,得到第i个原始图像帧的预测残差;调用去伪影模型将预测残差与第i个原始图像帧相加,得到去伪影处理后的目标图像帧。在经过前处理模块201的压缩前处理之后,服务器302调用实现框架200中的压缩模块202对上述目标图像帧进行压缩,得到压缩视频;其中,i为正整数。
服务器302通过有线或无线网络将上述压缩视频发送至第二终端303中,第二终端303可以通过解压缩对上述压缩视频进行播放。
图4示出了本申请一个示例性实施例提供的基于机器学习的去伪影模型的训练方法的流程图,该方法应用于电子设备中,上述电子设备可以是终端或者服务器,该方法包括:
步骤401,电子设备获取训练样本,每组训练样本包括视频样本的原始图像帧样本和该原始图像帧样本编码压缩后的图像帧样本。
上述训练样本是对原始视频进行压缩,得到压缩视频;从上述原始视频中随机抽取n个原始图像帧样本,并从上述压缩视频中抽取n个原始图像帧样本对应的n个编码压缩后的图像帧样本;n个原始图像帧样本与n个编码压缩后的图像帧样本一一对应组合成为n组训练样本;n为正整数。也即每组训练样本包括一个原始图像帧样本和该原始图像帧样本编码压缩后的图像帧样本。
示意性的,对训练样本的生成进行详细说明,如图5,电子设备调用基于H.264编码标准设置的解码器71对高清视频进行解封装,得到YUV格式的视频帧流;其中,Y表示明亮度(Lnminance或Luma),也就是灰阶值;U和V表示色度(Chrominance或Chrome),用于描述影像色彩及饱和度,指定像素的颜色。其次,电子设备调用基于H.264编码标准设置的编码器72对上述视频帧流进行编码压缩,得到压缩视频。电子设备对应抽取原始高清视频和压缩视频中的图像帧;其中,从压缩视频中抽取得到的图像帧中包括伪影,比如,块效应、振铃效应、以及边缘毛刺等负面效应。再次,电子设备通过色彩空间转换引擎73提取每组图像帧的YUV格式中Y通道数据作为训练样本。
需要说明的是,在上述编码阶段中,电子设备在预设范围内随机选取固定 码率系数(Constant Rate Factor,CRF)进行压缩,在保证压缩质量的同时,使压缩图像帧包括的伪影更加多样化。比如,CRF的预设范围为30至60,电子设备在编码阶段从30至60这一范围内选取一个值作为本次编码压缩的CRF。
还需要说明的是,电子设备还通过数据增广的方式增加训练样本的数据量;示意性的,在训练之前,一种数据增广的方式可以是抽取样本时在视频的时间序列上随机抽帧,另一种数据增广的方式可以是在像素空间上按照预定大小进行随机剪裁,比如,在像素空间上进行512×512大小的随机剪裁;在训练阶段,则可以采用垂直翻转、水平翻转、或者90度旋转等数据增广的方式,比如,电子设备通过上述图5所示的方法得到训练样本之后,对训练样本进行垂直翻转、水平翻转、或者90度旋转等方式得到更多的训练样本。
步骤402,电子设备调用去伪影模型预测每组训练样本中原始图像帧样本与编码压缩后的图像帧样本之间的残差,得到样本残差。
可选地,电子设备通过去伪影模型学习样本残差的示意性步骤如下:
1)电子设备调用去伪影模型对编码压缩后的图像帧样本进行特征提取,得到编码压缩后的图像帧样本的样本特征向量。
可选地,去伪影模型包括至少两个特征提取单元和第一特征融合层;至少两个特征提取单元顺次连接,每一个特征提取单元的输出端还与第一特征融合层的输入端连接。电子设备调用至少两个特征提取单元中的每一个特征提取单元对原始图像帧样本进行特征提取,得到至少两个样本特征子向量;调用第一特征融合层将至少两个样本特征子向量进行融合,得到样本特征向量。
示意性的,去伪影模型中包括5个特征提取单元和1个特征融合层,电子设备将每组训练样本输入第1个特征提取单元,第1个特征提取单元对训练样本进行特征提取,得到样本特征子向量A
1;将样本特征子向量A
1输入第2个特征提取单元,第2个特征提取单元对样本特征子向量A
1进行特征提取,得到样本特征子向量A
2;以此类推,第3个特征提取单元对样本特征子向量A
2进行特征提取得到样本特征子向量A
3,第4个特征提取单元对样本特征子向量A
3进行特征提取得到样本特征子向量A
4,第5个特征提取单元对样本特征子向量A
4进行特征提取得到样本特征子向量A
5;将上述样本特征子向量A
1、A
2、A
3、A
4和A
5输入第一特征融合层中进行特征融合,得到样本特征向量A
1A
2A
3A
4A
5,其中,上述样本特征向量A
1A
2A
3A
4A
5是样本特征子向量A
1、A
2、A
3、A
4和A
5级联得到的。
可选地,顺次连接的至少两个特征提取单元中每一个特征提取单元中的模型参数量是按照靠近第一特征融合层的方向逐层递减的。
2)电子设备调用去伪影模型对样本特征向量降维,得到降维后的样本特征向量。
电子设备调用去伪影模型对样本特征向量降维,可选地,去伪影模型中可以包括第一1×1卷积层;通过第一1×1卷积层对样本特征向量降维,得到降维后的样本特征向量。
可选地,去伪影模型中可以包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;调用第一1×1卷积层对样本特征向量降维,得到降维后的第一样本特征向量;调用第二1×1卷积层对样本特征向量降维,得到降维后的第二样本特征向量;调用第一特征提取层对第二样本特征向量进行特征提取,得到特征提取后的第二样本特征向量;调用第二特征融合层将第一样本特征向量与特征提取后的第二样本特征向量进行融合,得到降维后的样本特征向量。
示意性的,电子设备调用去伪影模型中的第一1×1卷积层对样本特征向量A
1A
2A
3A
4A
5进行降维,得到降维后的第一样本特征向量B
1;调用第二1×1卷积层对样本特征向量A
1A
2A
3A
4A
5进行降维,得到降维后的第二样本特征向量B
2,调用第一特征提取层对第二样本特征向量B
2进行特征提取,得到特征提取后的第二样本特征向量B
3;调用第二特征融合层将第一样本特征向量B
1与特征提取后的第二样本特征向量B
3进行融合,得到降维后的样本特征向量B
1B
3。
3)电子设备调用去伪影模型对降维后的样本特征向量进行特征重建,得到样本残差。
可选地,去伪影模型中包括特征重建层,通过特征重建层对降维后的样本特征向量进行特征重建,得到样本残差。示意性的,去伪影模型中包括3×3卷积层;通过3×3卷积层对降维后的样本特征向量进行特征重建,得到样本残差。
可选地,去伪影模型中包括至少两个特征重建层,通过顺次连接的至少两个特征重建层对降维后的样本特征向量进行特征重建,得到样本残差。示意性的,去伪影模型中包括顺次连接的至少两个3×3卷积层;通过上述顺次连接的至少两个3×3卷积层对降维后的样本特征向量进行特征重建,得到样本残差。
步骤403,电子设备调用去伪影模型将样本残差与编码压缩后的图像帧样本相加,得到去伪影处理后的目标图像帧样本。
步骤404,电子设备确定目标图像帧样本与原始图像帧样本之间的损失。
电子设备调用去伪影模型中的损失函数计算目标图像帧样本与该目标图像帧样本对应的原始图像帧样本之间的损失,比如,目标图像帧样本与该目标图像帧样本对应的原始图像帧样本之间的平均绝对误差、或者均方误差、或者平均偏差误差。
步骤405,电子设备根据损失对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。
电子设备中去伪影模型对上述损失进行反向传播,通过上述损失对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。比如,电子设备中去伪影模型对平均绝对误差进行反向传播,通过上述平均绝对误差对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。
综上所述,本实施例提供的基于机器学习的去伪影模型训练方法,对采用了残差学习结构的去伪影模型进行训练,使去伪影模型在经过训练后能够通过残差学习准确的在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使解压后的视频帧的质量更高;进一步地,可以通过训练得到的去伪影模型来预处理视频编码压缩过程中可能出现的伪影,达到避免编码压缩后的视频明显地出现多类伪影的效果,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以解决对多类伪影统一处理的难题。其次,对于上述训练样本的获取,是通过自动化程序生成的,能够减少人工标注所消耗的人力成本。
图6示出了本申请一个示例性实施例提供的基于机器学习的去伪影方法的流程图,该方法应用于电子设备中,上述电子设备可以是终端或者服务器,上述电子设备中设置有去伪影模型,该方法包括:
步骤501,电子设备获取待处理的视频,该视频包括至少两个原始图像帧。
上述待处理的视频可以是通过该电子设备上的物理接口上传至该电子设备的视频,也可以是通过有线或者无线网络传输至该电子设备的视频。比如,该电子设备可以是服务器,终端通过有线或者无线网络向服务器发送视频,服务器接收得到视频。
步骤502,电子设备调用去伪影模型预测视频的第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的残差,得到第i个原始图像帧的预测残差。
可选地,电子设备调用去伪影模型对视频进行残差学习,示意性步骤如下:
1)电子设备调用去伪影模型对第i个原始图像帧进行特征提取,得到第i个原始图像帧的特征向量。
可选地,去伪影模型包括至少两个特征提取单元和第一特征融合层;至少两个特征提取单元顺次连接,每一个特征提取单元的输出端还与第一特征融合层的输入端连接。电子设备调用至少两个特征提取单元中的每一个特征提取单元对第i个原始图像帧进行特征提取,得到至少两个特征子向量;调用第一特征融合层将至少两个特征子向量进行融合,得到特征向量。
示意性的,去伪影模型中包括3个特征提取单元和1个特征融合层,电子设备将每一个原始图像帧输入第1个特征提取单元,第1个特征提取单元对原始图像帧进行特征提取,得到特征子向量C
1;将特征子向量C
1输入第2个特征提取单元,第2个特征提取单元对特征子向量C
1进行特征提取,得到特征子向量C
2;将特征子向量C
2输入第3个特征提取单元,第3个特征对特征子向量C
2进行特征提取得到特征子向量C
3;将上述特征子向量C
1、C
2和C
3输入第一特征融合层中进行特征融合,得到样本特征向量C
1C
2C
3。
可选地,顺次连接的至少两个特征提取单元中每一个特征提取单元对应的卷积层中模型参数量是按照靠近特征融合层的方向逐层递减的,比如,上述顺次连接的3个特征提取单元中,第1个特征提取单元对应的卷积层中有10000个模型参数,第2个特征提取单元对应的卷积层中有5000个模型参数,第3个特征提取单元对应的卷积层中有3000个模型参数。电子设备中去伪影模型通过上述顺次连接的至少两个特征提取单元提取得到特征向量。
2)电子设备调用去伪影模型对特征向量降维,得到降维后的特征向量。
可选地,去伪影模型中包括第一1×1卷积层;电子设备通过去伪影模型中的第一1×1卷积层对每一个特征向量进行降维,得到降维后的特征向量。
可选地,去伪影模型中包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;电子设备调用第一1×1卷积层对特征向量降维,得到降维后的第一特征向量;调用第二1×1卷积层对特征向量降维,得到降维后的第二特征向量;调用第一特征提取层对第二特征向量进行特征提取,得到特征提取后的第二特征向量;调用第二特征融合层将第一特征向量与特征提取后的第二特征向量进行融合,得到降维后的特征向量。
3)电子设备调用去伪影模型对降维后的特征向量进行特征重建,得到第i 个原始图像帧与第i个原始图像帧压缩后的图像帧之间的预测残差。
可选地,去伪影模型中包括特征重建层;电子设备通过去伪影模型中的特征重建层对降维后的特征向量进行特征重建,得到第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的预测残差。示意性的,特征重建层为3×3卷积层;电子设备通过去伪影模型中的3×3卷积层对降维后的特征向量进行特征重建,得到第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的预测残差。
可选地,去伪影模型中包括顺次连接的至少两个特征重建层;电子设备通过去伪影模型中的至少两个特征重建层对降维后的特征向量进行特征重建,得到第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的预测残差。示意性的,去伪影模型中包括顺次连接的至少两个3×3卷积层;电子设备通过去伪影模型中的至少两个3×3卷积层对降维后的特征向量进行特征重建,得到预测残差。可选地,去伪影模型中还包括一个第二特征提取层;电子设备通过去伪影模型中的第二特征提取层对降维后的特征向量进行特征提取,得到候选特征向量;将候选特征向量输入至少两个特征重建层进行特征重建,得到第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的预测残差。
步骤503,电子设备调用去伪影模型将预测残差与第i个原始图像帧相加,得到去伪影处理后的目标图像帧。
电子设备调用去伪影模型将第i个原始图像帧的预测残差与第i个原始图像帧相加,得到去伪影处理后的目标图像帧,相应地,至少两个原始图像帧对应得到至少两个目标图像帧。
需要说明的是,电子设备调用去伪影模型将预测残差与第i个原始图像帧相加得到的目标图像帧的步骤是电子设备对视频进行压缩前处理的一个步骤。也就是说,电子设备在对视频进行压缩前,需要进行去伪影处理。
步骤504,电子设备将至少两个原始图像帧对应的至少两个目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。
电子设备中设置有编码压缩模块,通过上述编码压缩模块对至少两个目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。需要说明的是,上述去伪影后的视频帧序列即是编码压缩后的视频帧,用户在终端上播放的视频是通过对上述去伪影后的视频帧序列解压缩得到的。
综上所述,本实施例提供的基于机器学习的去伪影方法,通过采用残差学习结构的去伪影模型对视频在压缩过程中可能产生的伪影进行预处理,通过残 差学习准确的在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使压缩并解压后的视频帧的质量更高;通过去伪影模型来预处理视频编码压缩的过程中可能出现的伪影,避免编码压缩后的视频明显地出现多类伪影,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以避免对多类伪影统一处理的难题;还可以通过模型本身的泛化能力达到自适应强度目的。
示意性的,峰值信噪比(Peak Signal to Noise Ratio,PSNR)用于衡量图像质量,结构相似性(Structural SIMilarity index,SSIM)用于衡量两幅图像之间的相似度;在实验中用PSNR和SSIM两个指标进行去伪影模型的性能测试,首先,在CRF值处于20至40的压缩视频中,对应每一个值随机选取一帧作为测试集;其次,观察在模型参数量限制在26436个的情况下,去伪影模型对视频去伪影的客观指标的变化,如表1,客观指标均有提升,主观质量评测明显提升,即PSNR与SSIM均有所提升。
表1

如图7,示出了经过去伪影模型进行去伪影处理前的解压缩效果,如图8,示出了去伪影处理后的解压缩下效果,可以明显的看出,图像中的毛刺显著减少,轮廓更加干净,主观质量明显增强。还以去伪影模型对振铃效应的去除效果进行举例说,如图9,左图是未经去伪影模型处理的原始图像帧,右图是经过去伪影模型处理的图像帧,通过对比可以明显看出图像的上半部分和下半部分的中心区域存在大量的振铃效应,经过去伪影模型处理能够有效的去除了振铃效应。
还需要说明的是,上述基于机器学习的去伪影方法可以广泛的应用于在线视频、在线游戏、视频监控、视频发布等不同的有关视频的应用场景中。
若以上述去伪影方法应用于多人在线的游戏场景中为例进行说明,示意性的,第一游戏终端接收到用户触发的操作事件,将操作时间上报至服务器;服务器根据第一游戏终端上报的操作事件对在线游戏的视频画面进行更新;服务器中设置有去伪影模型,服务器调用去伪影模型对更新后的视频画面进行去伪影处理,对经过去伪影处理的视频画面进行编码压缩,并将编码压缩后的视频 画面发送至第一游戏终端和第二游戏终端;第一游戏终端和第二游戏终端分别对上述编码压缩后的视频画面进行解压缩并播放。
若以上述去伪影方法应用于在线视频会议的场景中为例进行说明,示意性的,第一终端通过摄像头对拍摄范围内的画面进行录制,并将录制得到的视频上传至服务器;服务器中设置有去伪影模型,服务器调用去伪影模型对第一终端上传的视频进行去伪影处理,对经过去伪影处理的视频画面进行编码压缩,并将编码压缩后的视频画面发送至第二终端;第二终端对上述编码压缩后的视频画面进行解压缩并播放。与此同时,第二终端也在录制视频,对应的服务器将经去伪影处理的编码压缩视频发送至第一终端进行播放。
若以上述去伪影方法应用于视频发布的场景中为例进行说明,示意性的,第一终端将存储的视频上传至服务器;服务器中设置有去伪影模型,服务器调用去伪影模型对第一终端上传的视频进行去伪影处理,对经过去伪影处理的视频画面进行编码压缩,并将编码压缩后的视频画面发送至第二终端;第二终端在接收到用户针对该视频触发的播放操作后对该视频进行播放。
在上述不同的应用场景中,基于机器学习的去伪影方法均能够有效的去除编码压缩后视频中的多类伪影,提高用户的视觉体验。
还需要说明的是,本申请中的“第一”、“第二”等词语不带有任何排序含义,仅是为了区别不同的事物,比如,“第一游戏终端”与“第二游戏终端”中的“第一”与“第二”是为了区别两个不同的游戏终端。
图10示出了本申请一个示例性实施例提供的基于机器学习的去伪影装置的框图,该装置通过软件、硬件或者二者的结合实现成为终端或者服务器的部分或者全部,该装置包括:
第一获取模块601,用于获取待处理的视频,该视频包括至少两个原始图像帧;
第一调用模块602,用于调用去伪影模型预测视频的第i个原始图像帧与第i个原始图像帧压缩后的图像帧之间的残差,得到第i个原始图像帧的预测残差,i为正整数;
第一调用模块602,用于调用去伪影模型将预测残差与第i个原始图像帧相加,得到去伪影处理后的目标图像帧;
编码模块603,用于将至少两个原始图像帧对应的至少两个目标图像帧按序 进行编码压缩,得到去伪影后的视频帧序列。
在一些实施例中,第一调用模块602,用于调用去伪影模型对第i个原始图像帧进行特征提取,得到第i个原始图像帧的特征向量;调用去伪影模型对特征向量降维,得到降维后的特征向量;调用去伪影模型对降维后的特征向量进行特征重建,得到预测残差。
在一些实施例中,去伪影模型包括至少两个特征提取单元和第一特征融合层,至少两个特征提取单元顺次连接,每一个特征提取单元的输出端还与第一特征融合层的输入端连接;
第一调用模块602,用于调用至少两个特征提取单元中的每一个特征提取单元对第i个原始图像帧进行特征提取,得到至少两个特征子向量;调用第一特征融合层将至少两个特征子向量进行融合,得到特征向量。
在一些实施例中,去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;
第一调用模块602,用于调用第一1×1卷积层对特征向量降维,得到降维后的第一特征向量;调用第二1×1卷积层对特征向量降维,得到降维后的第二特征向量;调用第一特征提取层对第二特征向量进行特征提取,得到特征提取后的第二特征向量;调用第二特征融合层将第一特征向量与特征提取后的第二特征向量进行融合,得到降维后的特征向量。
综上所述,本实施例提供的基于机器学习的去伪影装置,通过采用残差学习结构的去伪影模型对视频在压缩过程中可能产生的伪影进行预处理,通过残差学习准确的在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使压缩并解压后的视频帧的质量更高;通过去伪影模型来预处理视频编码压缩的过程中可能出现的伪影,避免编码压缩后的视频明显地出现多类伪影,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以避免对多类伪影统一处理的难题;还可以通过模型本身的泛化能力达到自适应强度目的。
图11示出了本申请一个示例性实施例提供的基于机器学习的去伪影模型训练装置的框图,该装置通过软件、硬件或者二者的结合实现成为终端或者服务器的部分或者全部,该装置包括:
第二获取模块701,用于获取训练样本,每组训练样本包括视频样本的原始 图像帧样本和该原始图像帧样本编码压缩后的图像帧样本;
第二调用模块702,用于调用去伪影模型预测每组训练样本中原始图像帧样本与编码压缩后的图像帧样本的残差,得到样本残差;
第二调用模块702,用于调用去伪影模型将样本残差与编码压缩后的图像帧样本相加,得到去伪影处理后的目标图像帧样本;
训练模块703,用于确定目标图像帧样本与原始图像帧样本之间的损失,并根据损失对去伪影模型中的模型参数进行调整,训练去伪影模型的残差学习能力。
在一些实施例中,第二调用模块702,用于调用去伪影模型对编码压缩后的图像帧样本进行特征提取,得到编码压缩后的图像帧样本的样本特征向量;调用去伪影模型对样本特征向量降维,得到降维后的样本特征向量;调用去伪影模型对降维后的样本特征向量进行特征重建,得到样本残差。
在一些实施例中,去伪影模型包括至少两个特征提取单元和第一特征融合层,至少两个特征提取单元顺次连接,每一个特征提取单元的输出端还与第一特征融合层的输入端连接;
第二调用模块702,用于调用至少两个特征提取单元中的每一个特征提取单元对原始图像帧样本进行特征提取,得到至少两个样本特征子向量;调用第一特征融合层将至少两个样本特征子向量进行融合,得到样本特征向量。
在一些实施例中,去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;
第二调用模块702,用于调用第一1×1卷积层对样本特征向量降维,得到降维后的第一样本特征向量;调用第二1×1卷积层对样本特征向量降维,得到降维后的第二样本特征向量;调用第一特征提取层对第二样本特征向量进行特征提取,得到特征提取后的第二样本特征向量;调用第二特征融合层将第一样本特征向量与特征提取后的第二样本特征向量进行融合,得到降维后的样本特征向量。
综上所述,本实施例提供的基于机器学习的去伪影模型训练装置,对采用了残差学习结构的去伪影模型进行训练,使去伪影模型在经过训练后能够通过残差学习准确的在视频帧的特征抽取过程中保留更多的视频帧的纹理细节,从而使解压后的视频帧的质量更高;进一步地,可以通过训练得到的去伪影模型来预处理视频编码压缩的过程中可能出现的伪影,达到避免编码压缩后的视频 明显地出现多类伪影的效果,相比于传统的去伪影方式所需要的对不同的滤波器进行串行组合以及大量测试以达到想要的去伪影效果,能够节省大量的测试成本,可以避免对多类伪影统一处理的难题。
图12示出了本申请一个示例性实施例提供的终端800的结构框图。该终端800可以是:智能手机、平板电脑、MP3播放器(Moving Picture Experts Group Audio Layer III,动态影像专家压缩标准音频层面3)、MP4(Moving Picture Experts Group Audio Layer IV,动态影像专家压缩标准音频层面4)播放器、笔记本电脑或台式电脑。终端800还可能被称为用户设备、便携式终端、膝上型终端、台式终端等其他名称。
通常,终端800包括有:处理器801和存储器802。
处理器801可以包括一个或多个处理核心,比如4核心处理器、8核心处理器等。处理器801可以采用DSP(Digital Signal Processing,数字信号处理)、FPGA(Field-Programmable Gate Array,现场可编程门阵列)、PLA(Programmable Logic Array,可编程逻辑阵列)中的至少一种硬件形式来实现。处理器801也可以包括主处理器和协处理器,主处理器是用于对在唤醒状态下的数据进行处理的处理器,也称CPU(Central Processing Unit,中央处理器);协处理器是用于对在待机状态下的数据进行处理的低功耗处理器。在一些实施例中,处理器801可以在集成有GPU(Graphics Processing Unit,图像处理器),GPU用于负责显示屏所需要显示的内容的渲染和绘制。一些实施例中,处理器801还可以包括AI(Artificial Intelligence,人工智能)处理器,该AI处理器用于处理有关机器学习的计算操作。
存储器802可以包括一个或多个计算机可读存储介质,该计算机可读存储介质可以是非暂态的。存储器802还可包括高速随机存取存储器,以及非易失性存储器,比如一个或多个磁盘存储设备、闪存存储设备。在一些实施例中,存储器802中的非暂态的计算机可读存储介质用于存储至少一个指令,该至少一个指令用于被处理器801所执行以实现本申请中方法实施例提供的基于机器学习的去伪影方法、以及去伪影模型训练方法。
在一些实施例中,终端800还可选包括有:外围设备接口803和至少一个外围设备。处理器801、存储器802和外围设备接口803之间可以通过总线或信号线相连。各个外围设备可以通过总线、信号线或电路板与外围设备接口803 相连。具体地,外围设备包括:射频电路804、显示屏805、音频电路806、定位组件807和电源808中的至少一种。
外围设备接口803可被用于将I/O(Input/Output,输入/输出)相关的至少一个外围设备连接到处理器801和存储器802。在一些实施例中,处理器801、存储器802和外围设备接口803被集成在同一芯片或电路板上;在一些其他实施例中,处理器801、存储器802和外围设备接口803中的任意一个或两个可以在单独的芯片或电路板上实现,本实施例对此不加以限定。
射频电路804用于接收和发射RF(Radio Frequency,射频)信号,也称电磁信号。射频电路804通过电磁信号与通信网络以及其他通信设备进行通信。射频电路804将电信号转换为电磁信号进行发送,或者,将接收到的电磁信号转换为电信号。可选地,射频电路804包括:天线系统、RF收发器、一个或多个放大器、调谐器、振荡器、数字信号处理器、编解码芯片组、用户身份模块卡等等。射频电路804可以通过至少一种无线通信协议来与其它终端进行通信。该无线通信协议包括但不限于:城域网、各代移动通信网络(2G、3G、4G及5G)、无线局域网和/或WiFi(Wireless Fidelity,无线保真)网络。在一些实施例中,射频电路804还可以包括NFC(Near Field Communication,近距离无线通信)有关的电路,本申请对此不加以限定。
显示屏805用于显示UI(User Interface,用户界面)。该UI可以包括图形、文本、图标、视频及其它们的任意组合。当显示屏805是触摸显示屏时,显示屏805还具有采集在显示屏805的表面或表面上方的触摸信号的能力。该触摸信号可以作为控制信号输入至处理器801进行处理。此时,显示屏805还可以用于提供虚拟按钮和/或虚拟键盘,也称软按钮和/或软键盘。在一些实施例中,显示屏805可以为一个,设置终端800的前面板;在另一些实施例中,显示屏805可以为至少一个,分别设置在终端800的不同表面或呈折叠设计;在一些实施例中,显示屏805可以是柔性显示屏,设置在终端800的弯曲表面上或折叠面上。甚至,显示屏805还可以设置成非矩形的不规则图形,也即异形屏。显示屏805可以采用LCD(Liquid Crystal Display,液晶显示屏)、OLED(Organic Light-Emitting Diode,有机发光二极管)等材质制备。
音频电路806可以包括麦克风和扬声器。麦克风用于采集用户及环境的声波,并将声波转换为电信号输入至处理器801进行处理,或者输入至射频电路804以实现语音通信。出于立体声采集或降噪的目的,麦克风可以为多个,分别 设置在终端800的不同部位。麦克风还可以是阵列麦克风或全向采集型麦克风。扬声器则用于将来自处理器801或射频电路804的电信号转换为声波。扬声器可以是传统的薄膜扬声器,也可以是压电陶瓷扬声器。当扬声器是压电陶瓷扬声器时,不仅可以将电信号转换为人类可听见的声波,也可以将电信号转换为人类听不见的声波以进行测距等用途。在一些实施例中,音频电路806还可以包括耳机插孔。
定位组件807用于定位终端800的当前地理位置,以实现导航或LBS(Location Based Service,基于位置的服务)。定位组件807可以是基于美国的GPS(Global Positioning System,全球定位系统)、中国的北斗系统、俄罗斯的格雷纳斯系统或欧盟的伽利略系统的定位组件。
电源808用于为终端800中的各个组件进行供电。电源808可以是交流电、直流电、一次性电池或可充电电池。当电源808包括可充电电池时,该可充电电池可以支持有线充电或无线充电。该可充电电池还可以用于支持快充技术。
本领域技术人员可以理解,图12中示出的结构并不构成对终端800的限定,可以包括比图示更多或更少的组件,或者组合某些组件,或者采用不同的组件布置。
图13示出了本申请一个实施例提供的服务器的结构示意图。该服务器用于实施上述实施例中提供的基于机器学习的去伪影方法、以及去伪影模型训练方法。具体来讲:
所述服务器900包括中央处理单元(CPU,Central Processing Unit)901、包括随机存取存储器(RAM,Random Access Memory)902和只读存储器(ROM,Read Only Memory)903的系统存储器904,以及连接系统存储器904和中央处理单元901的系统总线905。所述服务器900还包括帮助计算机内的各个器件之间传输信息的基本输入/输出系统(I/O系统,Input Output System)906,和用于存储操作系统913、应用程序914和其他程序模块915的大容量存储设备907。
所述基本输入/输出系统906包括有用于显示信息的显示器908和用于用户输入信息的诸如鼠标、键盘之类的输入设备909。其中所述显示器908和输入设备909都通过连接到系统总线905的输入输出控制器910连接到中央处理单元901。所述基本输入/输出系统906还可以包括输入输出控制器910以用于接收和处理来自键盘、鼠标、或电子触控笔等多个其他设备的输入。类似地,输入输 出控制器910还提供输出到显示屏、打印机或其他类型的输出设备。
所述大容量存储设备907通过连接到系统总线905的大容量存储控制器(未示出)连接到中央处理单元901。所述大容量存储设备907及其相关联的计算机可读介质为服务器900提供非易失性存储。也就是说,所述大容量存储设备907可以包括诸如硬盘或者紧凑型光盘只读存储器(CD-ROM,Compact Disc Read Only Memory)驱动器之类的计算机可读介质(未示出)。
不失一般性,所述计算机可读介质可以包括计算机存储介质和通信介质。计算机存储介质包括以用于存储诸如计算机可读指令、数据结构、程序模块或其他数据等信息的任何方法或技术实现的易失性和非易失性、可移动和不可移动介质。计算机存储介质包括RAM、ROM、可擦除可编程只读存储器(EPROM,Erasable Programmable Read Only Memory)、带电可擦可编程只读存储器(EEPROM,Electrically Erasable Programmable Read Only Memory)、闪存或其他固态存储其技术,CD-ROM、数字通用光盘(DVD,Digital Versatile Disc)或固态硬盘(SSD,Solid State Drives)、其他光学存储、磁带盒、磁带、磁盘存储或其他磁性存储设备。其中,随机存取记忆体可以包括电阻式随机存取记忆体(ReRAM,Resistance Random Access Memory)和动态随机存取存储器(DRAM,Dynamic Random Access Memory)。当然,本领域技术人员可知所述计算机存储介质不局限于上述几种。上述的系统存储器904和大容量存储设备907可以统称为存储器。
根据本申请的各种实施例,所述服务器900还可以通过诸如因特网等网络连接到网络上的远程计算机运行。也即服务器900可以通过连接在所述系统总线905上的网络接口单元911连接到网络912,或者说,也可以使用网络接口单元911来连接到其他类型的网络或远程计算机系统(未示出)。
本申请还提供了一种计算机设备,该计算机设备包括:处理器和存储器,该存储器中存储有至少一条指令、至少一段程序、代码集或指令集,至少一条指令、至少一段程序、代码集或指令集由处理器加载并执行以实现上述各方法实施例提供的基于机器学习的去伪影方法、以及去伪影模型训练方法。
本申请还提供了一种计算机可读存储介质,该存储介质中存储有至少一条指令、至少一段程序、代码集或指令集,至少一条指令、至少一段程序、代码集或指令集由所述处理器加载并执行以实现上述各方法实施例提供的基于机器 学习的去伪影方法、以及去伪影模型训练方法。
本申请还提供了一种计算机程序产品,上述计算机程序产品包括计算机指令,上述计算机指令存储在计算机可读存储介质中。计算机设备的处理器从计算机可读存储介质读取上述计算机指令,处理器执行上述计算机指令,使得上述计算机设备执行如上一个方面的各种可选实现方式中提供的基于机器学习的去伪影方法、以及去伪影模型训练方法。
上述本申请实施例序号仅仅为了描述,不代表实施例的优劣。
本领域普通技术人员可以理解实现上述实施例的全部或部分步骤可以通过硬件来完成,也可以通过程序来指令相关的硬件完成,所述的程序可以存储于一种计算机可读存储介质中,上述提到的存储介质可以是只读存储器,磁盘或光盘等。
以上所述仅为本申请的可选实施例,并不用以限制本申请,凡在本申请的精神和原则之内,所作的任何修改、等同替换、改进等,均应包含在本申请的保护范围之内。
Claims (20)
- 一种基于机器学习的去伪影方法,其特征在于,应用于电子设备中,所述方法包括:获取待处理的视频,所述视频包括至少两个原始图像帧;调用去伪影模型预测所述视频的第i个原始图像帧与第i个所述原始图像帧压缩后的图像帧之间的残差,得到第i个所述原始图像帧的预测残差,i为正整数;调用所述去伪影模型将所述预测残差与第i个所述原始图像帧相加,得到去伪影处理后的目标图像帧;将所述至少两个原始图像帧对应的至少两个所述目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。
- 根据权利要求1所述的方法,其特征在于,所述调用去伪影模型预测所述视频的第i个原始图像帧与第i个所述原始图像帧压缩后的图像帧之间的残差,得到第i个所述原始图像帧的预测残差,包括:调用所述去伪影模型对第i个所述原始图像帧进行特征提取,得到第i个所述原始图像帧的特征向量;调用所述去伪影模型对所述特征向量降维,得到降维后的特征向量;调用所述去伪影模型对所述降维后的特征向量进行特征重建,得到第i个所述原始图像帧与第i个所述原始图像帧压缩后的图像帧之间的所述预测残差。
- 根据权利要求2所述的方法,其特征在于,所述去伪影模型包括至少两个特征提取单元和第一特征融合层,至少两个所述特征提取单元顺次连接,每一个所述特征提取单元的输出端还与所述第一特征融合层的输入端连接;所述调用所述去伪影模型对第i个所述原始图像帧进行特征提取,得到第i个所述原始图像帧的特征向量,包括:调用至少两个所述特征提取单元中的每一个所述特征提取单元对第i个所述原始图像帧进行特征提取,得到至少两个特征子向量;调用所述第一特征融合层将至少两个所述特征子向量进行融合,得到所述 特征向量。
- 根据权利要求2所述的方法,其特征在于,所述去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;所述调用所述去伪影模型对所述特征向量降维,得到降维后的特征向量,包括:调用所述第一1×1卷积层对所述特征向量降维,得到降维后的第一特征向量;调用所述第二1×1卷积层对所述特征向量降维,得到降维后的第二特征向量;调用所述第一特征提取层对所述第二特征向量进行特征提取,得到特征提取后的第二特征向量;调用所述第二特征融合层将所述第一特征向量与所述特征提取后的第二特征向量进行融合,得到所述降维后的特征向量。
- 根据权利要求1至4任一所述的方法,其特征在于,所述去伪影模型是通过如下方式训练得到的:获取训练样本,每组训练样本包括视频样本的每一个原始图像帧样本和所述原始图像帧样本编码压缩后的图像帧样本;调用所述去伪影模型预测所述每组训练样本中所述原始图像帧样本与编码压缩后的所述图像帧样本之间的残差,得到样本残差;调用所述去伪影模型将所述样本残差与编码压缩后的所述图像帧样本相加,得到去伪影处理后的目标图像帧样本;确定所述目标图像帧样本与所述原始图像帧样本之间的损失,并根据所述损失对所述去伪影模型中的模型参数进行调整,训练所述去伪影模型的残差学习能力。
- 根据权利要求5所述的方法,其特征在于,所述调用所述去伪影模型预测所述每组训练样本中所述原始图像帧样本与编码压缩后的所述图像帧样本之间的残差,得到样本残差,包括:调用所述去伪影模型对编码压缩后的所述图像帧样本进行特征提取,得到编码压缩后的所述图像帧样本的样本特征向量;调用所述去伪影模型对所述样本特征向量降维,得到降维后的样本特征向量;调用所述去伪影模型对所述降维后的样本特征向量进行特征重建,得到所述样本残差。
- 根据权利要求6所述的方法,其特征在于,所述去伪影模型包括至少两个特征提取单元和第一特征融合层,至少两个所述特征提取单元顺次连接,每一个所述特征提取单元的输出端还与所述第一特征融合层的输入端连接;所述调用所述去伪影模型对编码压缩后的所述图像帧样本进行特征提取,得到编码压缩后的所述图像帧样本的样本特征向量,包括:调用至少两个所述特征提取单元中的每一个所述特征提取单元对所述原始图像帧样本进行特征提取,得到至少两个样本特征子向量;调用所述第一特征融合层将至少两个所述样本特征子向量进行融合,得到所述样本特征向量。
- 根据权利要求6所述的方法,其特征在于,所述去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;所述调用所述去伪影模型对所述样本特征向量降维,得到降维后的样本特征向量,包括:调用所述第一1×1卷积层对所述样本特征向量降维,得到降维后的第一样本特征向量;调用所述第二1×1卷积层对所述样本特征向量降维,得到降维后的第二样本特征向量;调用所述第一特征提取层对所述第二样本特征向量进行特征提取,得到特征提取后的第二样本特征向量;调用所述第二特征融合层将所述第一样本特征向量与所述特征提取后的第二样本特征向量进行融合,得到所述降维后的样本特征向量。
- 一种基于机器学习的去伪影模型训练方法,其特征在于,应用于电子设 备中,所述方法包括:获取训练样本,每组训练样本包括视频样本的原始图像帧样本和所述原始图像帧样本编码压缩后的图像帧样本;调用所述去伪影模型预测所述每组训练样本中所述原始图像帧样本与编码压缩后的所述图像帧样本之间的残差,得到样本残差;调用所述去伪影模型将所述样本残差与编码压缩后的所述图像帧样本相加,得到去伪影处理后的目标图像帧样本;确定所述目标图像帧样本与所述原始图像帧样本之间的损失,并根据所述损失对所述去伪影模型中的模型参数进行调整,训练所述去伪影模型的残差学习能力。
- 一种基于机器学习的去伪影装置,其特征在于,所述装置包括:第一获取模块,用于获取待处理的视频,所述视频包括至少两个原始图像帧;第一调用模块,用于调用去伪影模型预测所述视频的第i个原始图像帧与第i个所述原始图像帧压缩后的图像帧之间的残差,得到第i个所述原始图像帧的预测残差,i为正整数;所述第一调用模块,用于调用所述去伪影模型将所述预测残差与第i个所述原始图像帧相加,得到去伪影处理后的目标图像帧;编码模块,用于将所述至少两个原始图像帧对应的至少两个所述目标图像帧按序进行编码压缩,得到去伪影后的视频帧序列。
- 根据权利要求10所述的装置,其特征在于,所述第一调用模块,用于调用所述去伪影模型对第i个所述原始图像帧进行特征提取,得到第i个所述原始图像帧的特征向量;调用所述去伪影模型对所述特征向量降维,得到降维后的特征向量;调用所述去伪影模型对所述降维后的特征向量进行特征重建,得到第i个所述原始图像帧与第i个所述原始图像帧压缩后的图像帧之间的所述预测残差。
- 根据权利要求11所述的装置,其特征在于,所述去伪影模型包括至少 两个特征提取单元和第一特征融合层,至少两个所述特征提取单元顺次连接,每一个所述特征提取单元的输出端还与所述第一特征融合层的输入端连接;所述第一调用模块,用于调用至少两个所述特征提取单元中的每一个所述特征提取单元对第i个所述原始图像帧进行特征提取,得到至少两个特征子向量;调用所述第一特征融合层将至少两个所述特征子向量进行融合,得到所述特征向量。
- 根据权利要求11所述的装置,其特征在于,所述去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;所述第一调用模块,用于调用所述第一1×1卷积层对所述特征向量降维,得到降维后的第一特征向量;调用所述第二1×1卷积层对所述特征向量降维,得到降维后的第二特征向量;调用所述第一特征提取层对所述第二特征向量进行特征提取,得到特征提取后的第二特征向量;调用所述第二特征融合层将所述第一特征向量与所述特征提取后的第二特征向量进行融合,得到所述降维后的特征向量。
- 根据权利要求10至13任一所述的装置,其特征在于,所述装置还包括:第二获取模块,用于获取训练样本,每组训练样本包括视频样本的每一个原始图像帧样本和所述原始图像帧样本编码压缩后的图像帧样本;第二调用模块,用于调用所述去伪影模型预测所述每组训练样本中所述原始图像帧样本与编码压缩后的所述图像帧样本之间的残差,得到样本残差;所述第二调用模块,用于调用所述去伪影模型将所述样本残差与编码压缩后的所述图像帧样本相加,得到去伪影处理后的目标图像帧样本;训练模块,用于确定所述目标图像帧样本与所述原始图像帧样本之间的损失,并根据所述损失对所述去伪影模型中的模型参数进行调整,训练所述去伪影模型的残差学习能力。
- 根据权利要求14所述的装置,其特征在于,所述第二调用模块,用于调用所述去伪影模型对编码压缩后的所述图像帧 样本进行特征提取,得到编码压缩后的所述图像帧样本的样本特征向量;调用所述去伪影模型对所述样本特征向量降维,得到降维后的样本特征向量;调用所述去伪影模型对所述降维后的样本特征向量进行特征重建,得到所述样本残差。
- 根据权利要求15所述的装置,其特征在于,所述去伪影模型包括至少两个特征提取单元和第一特征融合层,至少两个所述特征提取单元顺次连接,每一个所述特征提取单元的输出端还与所述第一特征融合层的输入端连接;所述第二调用模块,用于调用至少两个所述特征提取单元中的每一个所述特征提取单元对所述原始图像帧样本进行特征提取,得到至少两个样本特征子向量;调用所述第一特征融合层将至少两个所述样本特征子向量进行融合,得到所述样本特征向量。
- 根据权利要求15所述的装置,其特征在于,所述去伪影模型包括第一1×1卷积层、第二1×1卷积层、第一特征提取层和第二特征融合层;所述第二调用模块,用于调用所述第一1×1卷积层对所述样本特征向量降维,得到降维后的第一样本特征向量;调用所述第二1×1卷积层对所述样本特征向量降维,得到降维后的第二样本特征向量;调用所述第一特征提取层对所述第二样本特征向量进行特征提取,得到特征提取后的第二样本特征向量;调用所述第二特征融合层将所述第一样本特征向量与所述特征提取后的第二样本特征向量进行融合,得到所述降维后的样本特征向量。
- 一种基于机器学习的去伪影模型训练装置,其特征在于,所述装置包括:第二获取模块,用于获取训练样本,每组训练样本包括视频样本的原始图像帧样本和所述原始图像帧样本编码压缩后的图像帧样本;第二调用模块,用于调用所述去伪影模型预测所述每组训练样本中所述原始图像帧样本与编码压缩后的所述图像帧样本之间的残差,得到样本残差;所述第二调用模块,用于调用所述去伪影模型将所述样本残差与编码压缩后的所述图像帧样本相加,得到去伪影处理后的目标图像帧样本;训练模块,用于确定所述目标图像帧样本与所述原始图像帧样本之间的损失,并根据所述损失对所述去伪影模型中的模型参数进行调整,训练所述去伪影模型的残差学习能力。
- 一种电子设备,其特征在于,所述电子设备包括:存储器;与所述存储器相连的处理器;其中,所述处理器被配置为加载并执行可执行指令以实现如权利要求1至8任一所述的基于机器学习的去伪影方法,以及如权利要求9所述的基于机器学习的去伪影模型训练方法。
- 一种计算机可读存储介质,其特征在于,所述计算机可读存储介质中存储有至少一条指令、至少一段程序、代码集或指令集;所述至少一条指令、所述至少一段程序、所述代码集或所述指令集由处理器加载并执行以实现如权利要求1至8任一所述的基于机器学习的去伪影方法,以及如权利要求9所述的基于机器学习的去伪影模型训练方法。
Priority Applications (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| EP20876460.5A EP3985972A4 (en) | 2019-10-16 | 2020-10-09 | MACHINE LEARNING BASED ARTIFACT REMOVAL METHOD AND DEVICE AND MACHINE LEARNING BASED MODEL TRAINING METHOD AND DEVICE FOR ARTIFACT REMOVAL |
| US17/501,217 US11985358B2 (en) | 2019-10-16 | 2021-10-14 | Artifact removal method and apparatus based on machine learning, and method and apparatus for training artifact removal model based on machine learning |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN201910984591.3 | 2019-10-16 | ||
| CN201910984591.3A CN110677649B (zh) | 2019-10-16 | 2019-10-16 | 基于机器学习的去伪影方法、去伪影模型训练方法及装置 |
Related Child Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| US17/501,217 Continuation US11985358B2 (en) | 2019-10-16 | 2021-10-14 | Artifact removal method and apparatus based on machine learning, and method and apparatus for training artifact removal model based on machine learning |
Publications (1)
| Publication Number | Publication Date |
|---|---|
| WO2021073449A1 true WO2021073449A1 (zh) | 2021-04-22 |
Family
ID=69082807
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/CN2020/120006 Ceased WO2021073449A1 (zh) | 2019-10-16 | 2020-10-09 | 基于机器学习的去伪影方法、去伪影模型训练方法及装置 |
Country Status (4)
| Country | Link |
|---|---|
| US (1) | US11985358B2 (zh) |
| EP (1) | EP3985972A4 (zh) |
| CN (1) | CN110677649B (zh) |
| WO (1) | WO2021073449A1 (zh) |
Families Citing this family (10)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN110677649B (zh) | 2019-10-16 | 2021-09-28 | 腾讯科技(深圳)有限公司 | 基于机器学习的去伪影方法、去伪影模型训练方法及装置 |
| WO2021236061A1 (en) * | 2020-05-19 | 2021-11-25 | Google Llc | Debanding using a novel banding metric |
| CN113256529B (zh) * | 2021-06-09 | 2021-10-15 | 腾讯科技(深圳)有限公司 | 图像处理方法、装置、计算机设备及存储介质 |
| CN116074540B (zh) * | 2021-10-27 | 2025-05-30 | 四川大学 | 一种基于深度学习的vvc压缩伪影去除半盲方法 |
| CN114240787B (zh) * | 2021-12-20 | 2025-11-18 | 北京市商汤科技开发有限公司 | 压缩图像修复方法及装置、电子设备和存储介质 |
| CN114638772B (zh) * | 2022-03-18 | 2025-04-29 | 北京达佳互联信息技术有限公司 | 视频处理方法、装置以及设备 |
| US12437504B1 (en) * | 2022-03-24 | 2025-10-07 | Ambarella International Lp | Video correctness checking |
| CN115984125B (zh) * | 2022-12-09 | 2026-05-08 | 南京邮电大学 | 一种面向宽码率动态点云编码的占位图引导伪影去除方法 |
| US20250307994A1 (en) * | 2024-03-28 | 2025-10-02 | Amazon Technologies, Inc. | Automatic selection of compression artifact removal models |
| CN118134786B (zh) * | 2024-04-08 | 2024-12-06 | 烟台睿创微纳技术股份有限公司 | 红外图像的多路isp处理方法、装置、设备及介质 |
Citations (6)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN107463989A (zh) * | 2017-07-25 | 2017-12-12 | 福建帝视信息科技有限公司 | 一种基于深度学习的图像去压缩伪影方法 |
| US20180197278A1 (en) * | 2017-01-12 | 2018-07-12 | Postech Academy-Industry Foundation | Image processing apparatus and method |
| CN108710950A (zh) * | 2018-05-11 | 2018-10-26 | 上海市第六人民医院 | 一种图像量化分析方法 |
| CN109257600A (zh) * | 2018-11-28 | 2019-01-22 | 福建帝视信息科技有限公司 | 一种基于深度学习的视频压缩伪影自适应去除方法 |
| CN110276736A (zh) * | 2019-04-01 | 2019-09-24 | 厦门大学 | 一种基于权值预测网络的磁共振图像融合方法 |
| CN110677649A (zh) * | 2019-10-16 | 2020-01-10 | 腾讯科技(深圳)有限公司 | 基于机器学习的去伪影方法、去伪影模型训练方法及装置 |
Family Cites Families (13)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| GB201119206D0 (en) * | 2011-11-07 | 2011-12-21 | Canon Kk | Method and device for providing compensation offsets for a set of reconstructed samples of an image |
| EP2792146A4 (en) * | 2011-12-17 | 2015-12-09 | Dolby Lab Licensing Corp | MULTI-STAGE NESTED FRAME COMPATIBLE VIDEO OUTPUT WITH INCREASED RESOLUTION |
| CN106204489B (zh) * | 2016-07-12 | 2019-04-16 | 四川大学 | 结合深度学习与梯度转换的单幅图像超分辨率重建方法 |
| US10083499B1 (en) * | 2016-10-11 | 2018-09-25 | Google Llc | Methods and apparatus to reduce compression artifacts in images |
| EP3451293A1 (en) * | 2017-08-28 | 2019-03-06 | Thomson Licensing | Method and apparatus for filtering with multi-branch deep learning |
| EP3451670A1 (en) * | 2017-08-28 | 2019-03-06 | Thomson Licensing | Method and apparatus for filtering with mode-aware deep learning |
| CN107871332A (zh) * | 2017-11-09 | 2018-04-03 | 南京邮电大学 | 一种基于残差学习的ct稀疏重建伪影校正方法及系统 |
| CN109166161B (zh) * | 2018-07-04 | 2023-06-30 | 东南大学 | 一种基于噪声伪影抑制卷积神经网络的低剂量ct图像处理系统 |
| CN109064521A (zh) * | 2018-07-25 | 2018-12-21 | 南京邮电大学 | 一种使用深度学习的cbct去伪影方法 |
| CN109785249A (zh) * | 2018-12-22 | 2019-05-21 | 昆明理工大学 | 一种基于持续性记忆密集网络的图像高效去噪方法 |
| US11017506B2 (en) * | 2019-05-03 | 2021-05-25 | Amazon Technologies, Inc. | Video enhancement using a generator with filters of generative adversarial network |
| EP3973498B1 (en) * | 2019-06-18 | 2025-08-06 | Huawei Technologies Co., Ltd. | Real-time video ultra resolution |
| US11405626B2 (en) * | 2020-03-03 | 2022-08-02 | Qualcomm Incorporated | Video compression using recurrent-based machine learning systems |
-
2019
- 2019-10-16 CN CN201910984591.3A patent/CN110677649B/zh active Active
-
2020
- 2020-10-09 WO PCT/CN2020/120006 patent/WO2021073449A1/zh not_active Ceased
- 2020-10-09 EP EP20876460.5A patent/EP3985972A4/en active Pending
-
2021
- 2021-10-14 US US17/501,217 patent/US11985358B2/en active Active
Patent Citations (6)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| US20180197278A1 (en) * | 2017-01-12 | 2018-07-12 | Postech Academy-Industry Foundation | Image processing apparatus and method |
| CN107463989A (zh) * | 2017-07-25 | 2017-12-12 | 福建帝视信息科技有限公司 | 一种基于深度学习的图像去压缩伪影方法 |
| CN108710950A (zh) * | 2018-05-11 | 2018-10-26 | 上海市第六人民医院 | 一种图像量化分析方法 |
| CN109257600A (zh) * | 2018-11-28 | 2019-01-22 | 福建帝视信息科技有限公司 | 一种基于深度学习的视频压缩伪影自适应去除方法 |
| CN110276736A (zh) * | 2019-04-01 | 2019-09-24 | 厦门大学 | 一种基于权值预测网络的磁共振图像融合方法 |
| CN110677649A (zh) * | 2019-10-16 | 2020-01-10 | 腾讯科技(深圳)有限公司 | 基于机器学习的去伪影方法、去伪影模型训练方法及装置 |
Non-Patent Citations (3)
| Title |
|---|
| KEHUI NIE, LIU WENZHE ,TONG TONG, DU MIN, GAO QINQUAN: "Video compression artifact removal algorithm based on adaptive separable convolution network", JOURNAL OF COMPUTER APPLICATIONS, JISUANJI YINGYONG, CN, vol. 39, no. 5, 10 May 2019 (2019-05-10), CN, pages 1473 - 1479, XP055802883, ISSN: 1001-9081 * |
| See also references of EP3985972A4 |
| TAO CHEN, HONG REN WU, BIN QIU: "Adaptive Postfiltering of Transform Coefficients for the Reduction of Blocking Artifacts", IEEE TRANSACTIONS ON CIRCUITS AND SYSTEMS FOR VIDEO TECHNOLOGY, INSTITUTE OF ELECTRICAL AND ELECTRONICS ENGINEERS, US, vol. 11, no. 5, 1 May 2001 (2001-05-01), US, XP011014196, ISSN: 1051-8215 * |
Also Published As
| Publication number | Publication date |
|---|---|
| EP3985972A1 (en) | 2022-04-20 |
| CN110677649A (zh) | 2020-01-10 |
| EP3985972A4 (en) | 2022-11-16 |
| US20220038749A1 (en) | 2022-02-03 |
| CN110677649B (zh) | 2021-09-28 |
| US11985358B2 (en) | 2024-05-14 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| US11985358B2 (en) | Artifact removal method and apparatus based on machine learning, and method and apparatus for training artifact removal model based on machine learning | |
| US12192494B2 (en) | Chroma prediction method and device | |
| JP7085014B2 (ja) | ビデオ符号化方法並びにその装置、記憶媒体、機器、及びコンピュータプログラム | |
| KR101848191B1 (ko) | 이미지 압축 방법, 장치 및 서버 | |
| CN109688465B (zh) | 视频增强控制方法、装置以及电子设备 | |
| CN112702604B (zh) | 用于分层视频的编码方法和装置以及解码方法和装置 | |
| CN113038124B (zh) | 视频编码方法、装置、存储介质及电子设备 | |
| US12058312B2 (en) | Generative adversarial network for video compression | |
| CN114554212A (zh) | 视频处理装置及方法、计算机存储介质 | |
| EP4287110A1 (en) | Method and device for correcting image on basis of compression quality of image in electronic device | |
| CN1914925A (zh) | 为了在移动网络上传输而进行的图像压缩 | |
| US9997132B2 (en) | Data transmission method, data transmission system and portable display device of transmitting compressed data | |
| CN114422782B (zh) | 视频编码方法、装置、存储介质及电子设备 | |
| CN116055778B (zh) | 视频数据的处理方法、电子设备及可读存储介质 | |
| CN114630123A (zh) | 用于低时延视频编码的自适应质量提升 | |
| CN117768650A (zh) | 图像块的色度预测方法、装置、电子设备及存储介质 | |
| CN116847087A (zh) | 视频处理方法、装置、存储介质及电子设备 | |
| CN116074512A (zh) | 视频编码方法、装置、电子设备以及存储介质 | |
| HK40018776A (zh) | 基於机器学习的去伪影方法、去伪影模型训练方法及装置 | |
| HK40018776B (zh) | 基於机器学习的去伪影方法、去伪影模型训练方法及装置 | |
| CN116418988A (zh) | 视频流码率控制方法、装置、存储介质以及电子设备 | |
| CN114697664A (zh) | 视频编码器、视频解码器及相关方法 | |
| US12526437B2 (en) | Enhanced resolution generation at decoder | |
| US20260143145A1 (en) | Enhanced resolution generation at decoder | |
| CN114697666B (zh) | 屏幕编码方法、屏幕解码方法及相关装置 |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 20876460 Country of ref document: EP Kind code of ref document: A1 |
|
| ENP | Entry into the national phase |
Ref document number: 2020876460 Country of ref document: EP Effective date: 20220112 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |