WO2024215250A1 - 机器学习模型训练、对话方法、装置、设备及介质 - Google Patents
机器学习模型训练、对话方法、装置、设备及介质 Download PDFInfo
- Publication number
- WO2024215250A1 WO2024215250A1 PCT/SG2024/050199 SG2024050199W WO2024215250A1 WO 2024215250 A1 WO2024215250 A1 WO 2024215250A1 SG 2024050199 W SG2024050199 W SG 2024050199W WO 2024215250 A1 WO2024215250 A1 WO 2024215250A1
- Authority
- WO
- WIPO (PCT)
- Prior art keywords
- information
- text
- voice
- encoding
- speech
- Prior art date
- Legal status (The legal status is an assumption and is not a legal conclusion. Google has not performed a legal analysis and makes no representation as to the accuracy of the status listed.)
- Ceased
Links
Classifications
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/26—Speech to text systems
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
- G06N3/0455—Auto-encoder networks; Encoder-decoder networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/33—Querying
- G06F16/332—Query formulation
- G06F16/3329—Natural language query formulation
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/33—Querying
- G06F16/332—Query formulation
- G06F16/3329—Natural language query formulation
- G06F16/33295—Natural language query formulation in dialogue systems
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/33—Querying
- G06F16/3331—Query processing
- G06F16/334—Query execution
- G06F16/3343—Query execution using phonetics
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/33—Querying
- G06F16/3331—Query processing
- G06F16/334—Query execution
- G06F16/3344—Query execution using natural language analysis
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F16/00—Information retrieval; Database structures therefor; File system structures therefor
- G06F16/30—Information retrieval; Database structures therefor; File system structures therefor of unstructured textual data
- G06F16/33—Querying
- G06F16/335—Filtering based on additional data, e.g. user or group profiles
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06F—ELECTRIC DIGITAL DATA PROCESSING
- G06F18/00—Pattern recognition
- G06F18/20—Analysing
- G06F18/25—Fusion techniques
- G06F18/253—Fusion techniques of extracted features
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N20/00—Machine learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/044—Recurrent networks, e.g. Hopfield networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/044—Recurrent networks, e.g. Hopfield networks
- G06N3/0442—Recurrent networks, e.g. Hopfield networks characterised by memory or gating, e.g. long short-term memory [LSTM] or gated recurrent units [GRU]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/045—Combinations of networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/0464—Convolutional networks [CNN, ConvNet]
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/04—Architecture, e.g. interconnection topology
- G06N3/0475—Generative networks
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/084—Backpropagation, e.g. using gradient descent
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/088—Non-supervised learning, e.g. competitive learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/0895—Weakly supervised learning, e.g. semi-supervised or self-supervised learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/09—Supervised learning
-
- G—PHYSICS
- G06—COMPUTING OR CALCULATING; COUNTING
- G06N—COMPUTING ARRANGEMENTS BASED ON SPECIFIC COMPUTATIONAL MODELS
- G06N3/00—Computing arrangements based on biological models
- G06N3/02—Neural networks
- G06N3/08—Learning methods
- G06N3/096—Transfer learning
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/06—Creation of reference templates; Training of speech recognition systems, e.g. adaptation to the characteristics of the speaker's voice
- G10L15/063—Training
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/08—Speech classification or search
- G10L15/18—Speech classification or search using natural language modelling
- G10L15/1822—Parsing for meaning understanding
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/22—Procedures used during a speech recognition process, e.g. man-machine dialogue
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L25/00—Speech or voice analysis techniques not restricted to a single one of groups G10L15/00 - G10L21/00
- G10L25/48—Speech or voice analysis techniques not restricted to a single one of groups G10L15/00 - G10L21/00 specially adapted for particular use
- G10L25/51—Speech or voice analysis techniques not restricted to a single one of groups G10L15/00 - G10L21/00 specially adapted for particular use for comparison or discrimination
- G10L25/63—Speech or voice analysis techniques not restricted to a single one of groups G10L15/00 - G10L21/00 specially adapted for particular use for comparison or discrimination for estimating an emotional state
-
- G—PHYSICS
- G10—MUSICAL INSTRUMENTS; ACOUSTICS
- G10L—SPEECH ANALYSIS TECHNIQUES OR SPEECH SYNTHESIS; SPEECH RECOGNITION; SPEECH OR VOICE PROCESSING TECHNIQUES; SPEECH OR AUDIO CODING OR DECODING
- G10L15/00—Speech recognition
- G10L15/04—Segmentation; Word boundary detection
- G10L15/05—Word boundary detection
Definitions
- Machine learning model training, dialogue method, device, equipment and medium Cross-reference
- This disclosure claims the priority of the Chinese patent application filed with the Chinese Patent Office on April 11, 2023, application number 202310397072.3, application name "Machine learning model training, dialogue method, device, equipment and medium", all of which are incorporated by reference into this disclosure.
- Technical field This disclosure relates to the field of information technology, and in particular to a machine learning model training, dialogue method, device, equipment and medium.
- Background technology At present, intelligent customer service can communicate with users in some business scenarios, thereby providing users with business consulting, business processing and other services. Specifically, intelligent customer service can be implemented by a machine learning model deployed on a computing device such as a computer or a computer cluster. However, the current machine learning model does not have high accuracy in understanding user speech.
- the present disclosure provides a machine learning model training, dialogue method, device, equipment and medium to improve the pre-trained model's understanding of voice information and text information, thereby improving the accuracy of the pre-trained model's understanding of user speech.
- the present disclosure provides a machine learning model training method, including: obtaining voice information and text information corresponding to the voice information; encoding the text information and the voice information respectively to obtain text encoding information and voice encoding information; fusing the text encoding information and the voice encoding information to obtain fused encoding information; predicting the time information corresponding to each text unit in the text information in the voice information according to the encoding information corresponding to the text information in the fused encoding information; pre-training a first machine learning model according to the predicted time information and the position annotation of the voice unit corresponding to each text unit in the text information in the voice information.
- the embodiment of the present disclosure provides a method for training a machine learning model, the method comprising: obtaining sample data of a target task, the sample data comprising data to be processed and annotated results of the data to be processed, the data to be processed comprising sample speech and sample text corresponding to the sample speech; inputting the data to be processed into a second machine learning model so that the second machine learning model outputs a processed result, the second machine learning model being a pre-trained model obtained according to the training method described in the first aspect; training the second machine learning model according to the processed result output by the second machine learning model and the annotated results of the data to be processed, to obtain a trained machine learning model.
- the embodiment of the present disclosure provides an intelligent dialogue method, the method comprising: obtaining a historical dialogue between a target user and an intelligent dialogue system, and text information corresponding to the historical dialogue;
- the embodiment of the present disclosure provides a machine learning model training device, comprising: an acquisition module, configured to acquire voice information and text information corresponding to the voice information; an encoding module, configured to encode the text information and the voice information respectively, and obtain text encoding information and voice encoding information; a fusion processing module, configured to perform fusion processing on the text encoding information and the voice encoding information, and obtain the fused encoding information; a prediction module, configured to predict the time information corresponding to each text unit in the text information in the voice information according to the encoding information corresponding to the text information in the fused encoding information; a pre-training module, configured to pre-train the first machine learning model according to the predicted time information and the position annotation of the voice unit corresponding to each text unit in the text information in the voice information.
- an embodiment of the present disclosure provides an electronic device, comprising: a memory; a processor; and a computer program; wherein the computer program is stored in the memory and is configured to be executed by the processor to implement the method described in the first aspect, the second aspect, or the third aspect.
- an embodiment of the present disclosure provides a computer-readable storage medium, on which a computer program is stored, and the computer program is executed by the processor to implement the method described in the first aspect, the second aspect, or the third aspect.
- the machine learning model training, dialogue method, apparatus, device, and medium provided by the embodiment of the present disclosure obtain voice information and text information corresponding to the voice information, and encode the text information and the voice information respectively to obtain text encoding information and voice encoding information.
- the pre-trained model can align the voice information and text information in time sequence, for example, the alignment between finer-grained text units in the text information and finer-grained voice units in the voice information, thereby improving the pre-trained model's understanding of the voice information and text information, thereby improving the accuracy of the pre-trained model's understanding of the user's speech.
- FIG1 is a flow chart of a model pre-training method provided in an embodiment of the present disclosure
- FIG2 is a schematic diagram of an application scenario provided in an embodiment of the present disclosure
- FIG3 is a schematic diagram of a machine learning model provided in an embodiment of the present disclosure
- FIG4 is a schematic diagram of a conversation between a user and an intelligent dialogue system provided in an embodiment of the present disclosure
- FIG5 is a schematic diagram of a time series prediction provided in another embodiment of the present disclosure
- FIG6 is a schematic diagram of a machine learning model provided in another embodiment of the present disclosure
- FIG7 is a schematic diagram of the construction of a first loss function provided in another embodiment of the present disclosure
- FIG8 is a schematic diagram of multiple types of sample data provided in another embodiment of the present disclosure
- FIG9 is a flow chart of a model pre-training method provided in another embodiment of the present disclosure
- FIG10 is a schematic diagram of a machine learning model provided in another embodiment of the present disclosure
- FIG10 is a schematic diagram of a machine learning
- the voice information including but not limited to user voice collected by terminal devices
- text information including but not limited to text information corresponding to user voice, etc.
- the machine learning model training and dialogue method will involve the following several explanations, the details of which are as follows: Speech and semantic joint modeling: The system takes speech and corresponding text transcription as input at the same time, and under the guidance of tasks such as speech and text alignment, it realizes the joint improvement of speech and text understanding.
- Pre-training An important means to allow the model to perform unsupervised learning on large-scale corpus, which can greatly improve the results of downstream tasks.
- Temporal refers to the characteristics of the input sequence having a time order. Both speech and text have temporal.
- Navigation The user calls the voice robot.
- Outbound call The voice robot calls the user.
- intelligent customer service can communicate with users in some business scenarios, thereby providing users with business consultation, business processing and other services.
- intelligent customer service can be implemented by a machine learning model deployed on a computing device such as a computer or a computer cluster.
- the current machine learning model does not have high accuracy in understanding user speech.
- the embodiment of the present disclosure provides a machine learning model training method, which is introduced below in conjunction with a specific embodiment.
- the cloud multiple computing nodes can be organized to provide a certain service, and of course, a computing node can also provide one or more services.
- the cloud may provide the service by providing a service interface to the outside, and the user calls the service interface to use the corresponding service.
- the service interface includes a software development kit (SDK), an application programming interface (API), and the like.
- SDK software development kit
- API application programming interface
- the machine learning model training method described in this embodiment may be applicable to an application scenario as shown in FIG2.
- the application scenario includes a terminal 21 and a server 22, wherein the server 22 may use the machine learning model training method described in this embodiment to pre-train a first machine learning model, and the first machine learning model may obtain a pre-trained model after pre-training.
- the pre-trained model may be retained in the server 22, or the server 22 may store the pre-trained model in the server 22.
- the model is deployed to the terminal 21 or other server.
- the method is described in detail below in conjunction with Figure 2. As shown in Figure 1, the specific steps of the method are as follows:
- the server 22 may be provided with an intelligent dialogue system.
- the terminal 21 shown in FIG. 2 may collect user voice and send the user voice to the server 22.
- the intelligent dialogue system may make a voice reply according to the user voice.
- the server 22 may feed back the voice reply of the intelligent dialogue system to the terminal 21, and so on, so that the user of the terminal 21 may have a voice dialogue with the intelligent dialogue system.
- the server 22 may acquire voice information, and the voice information may be a voice dialogue between the user and the intelligent dialogue system.
- the server 22 may also convert the voice dialogue into corresponding text information through speech recognition (Automatic Speech Recognition, ASR), that is, the text information is a text transcription of the voice dialogue.
- ASR Automatic Speech Recognition
- the voice information acquired by the server 22 may be the user voice, and the text information is a text transcription of the user voice.
- the voice information and the text information corresponding to the voice information may be used as inputs of the first machine learning model.
- the text information may include at least one sentence.
- the voice information may include the voice of each sentence in the at least one sentence, or include the voice of part of the at least one sentence.
- encoding the text information and the voice information respectively to obtain text encoding information and voice encoding information includes: encoding at least one encoding unit respectively included in each text unit in the text information by a text encoder to obtain text encoding information, wherein the text encoding information includes a representation vector of each encoding unit; encoding each voice segment in the voice information by a voice encoder to obtain voice encoding information, wherein the voice encoding information includes a representation vector of each voice segment.
- each sentence in the text information is composed of text units, and the text unit may be a character, a word, a phrase, a subword, a single word, etc. For example, a sentence is "They won five games successively".
- each text unit can also include at least one encoding unit.
- “he” includes one character
- “he” includes one encoding unit, that is, “he” itself.
- “Five” includes two characters. If one character is used as a coding unit, then “five” includes two encoding units. Therefore, the sentence “They won five games successively” includes 6 encoding units, namely "he", “they”, “win”, "have”, “five”, and "have”. Therefore, when the sentence "They won five games successively” is encoded by a text encoder, the 6 encoding units can be encoded separately.
- each encoding unit corresponds to a representation vector.
- a sentence is "They won five games successively”.
- the sentence includes a total of 5 words.
- Each word is regarded as a text unit. Since the first four words are shorter, each of the four words can be regarded as a coding unit. However, the last word, " successively ", is longer.
- the word can be divided into two coding units, namely " success " and " ively ". Therefore, when encoding the sentence " They won five games successively " through a text encoder, six coding units, namely " They ", “ won “, “ five “, “ games “, “ success “, and “ ively “, can be encoded respectively.
- each coding unit corresponds to a representation vector. Since the text information includes not limited to one sentence, each sentence may include multiple text units, and each text unit may also include at least one coding unit. Therefore, the text information is encoded through a text encoder. , each coding unit in the text information can be encoded by a text encoder to obtain text coding information, and the text coding information includes the representation vector of each coding unit.
- the speech of each sentence in the speech information can be an audio signal with a length of 10 seconds. Before speech coding, the speech of each sentence can also be divided into multiple speech segments, for example, the length of each speech segment can be 1 second. Further, each speech segment in the speech information is encoded by a speech encoder to obtain speech coding information, and the speech coding information includes the representation vector of each speech segment.
- the first machine learning model may further include a modal fusion layer.
- the text encoding information and the speech encoding information may be spliced, and the spliced result may be used as the input of the modal fusion layer, so that the modal fusion layer performs a fusion process on the text encoding information and the speech encoding information to obtain fused encoding information, and the fused encoding information may also be recorded as a joint representation vector.
- the input and output of the modal fusion layer correspond one-to-one.
- the input of the modal fusion layer includes representation vectors of m encoding units and representation vectors of n speech segments, that is, the input of the modal fusion layer includes m+n representation vectors, and the output of the modal fusion layer also includes m+n representation vectors, and the m+n representation vectors in the input correspond one-to-one to the m+n representation vectors in the output.
- the representation vector contains both text components and speech components. Therefore, each representation vector output by the modality fusion layer can be recorded as a fused representation vector.
- the text information includes m coding units
- the voice information includes n voice segments
- the input of the modal fusion layer includes the representation vectors of the m coding units and the representation vectors of the n voice segments. Since the input and output of the modal fusion layer are one-to-one corresponding, the first m representation vectors output by the modal fusion layer are the coding information corresponding to the text information, and the last n representation vectors output by the modal fusion layer are the coding information corresponding to the voice information.
- the first machine learning model can predict the time information corresponding to each text unit in the text information in the voice information according to the first m representation vectors output by the modal fusion layer.
- the time information corresponding to each text unit in the voice information includes the start time and the end time corresponding to the text unit in the voice information.
- text units such as “he”, “they”, “win”, “have”, and “five” are text-type information, and each text unit corresponds to a voice word, which is voice-type information.
- the voice word corresponding to a text unit can be the pronunciation of the text unit by the user or the intelligent dialogue system.
- the start time corresponding to the text unit in the voice information is specifically the start time corresponding to the voice word corresponding to the text unit in the voice information (for example, the start time of pronunciation), and the end time corresponding to the text unit in the voice information is specifically the end time corresponding to the voice word corresponding to the text unit in the voice information (for example, the end time of pronunciation).
- the first machine learning model Pre-train the first machine learning model according to the predicted time information and the position of the speech unit corresponding to each text unit in the text information in the speech information, and obtain a pre-trained model. Specifically, in this embodiment, the position of the speech unit corresponding to each text unit in the text information in the speech information can be pre-marked. Further, according to the time information corresponding to each text unit in the text information in the speech information predicted by the first machine learning model, and the position of the speech unit corresponding to each text unit in the text information in the speech information, a first loss function is constructed, and then the first machine learning model is pre-trained according to the first loss function. For example, the text information in this embodiment is "They won five times", and the speech information is the speech of "They won five times".
- the position of the speech unit corresponding to each text unit in the text information in the speech information can be pre-marked.
- the text information includes five text units: “he”, “we”, “win”, “have”, and “five”.
- the voice information includes five text units: “he”, “we”, “win”, “have”, and “five”.
- the corresponding speech words of " ⁇ ” are recorded as speech units.
- the corresponding speech word of " ⁇ " is the pronunciation of " ⁇ ”.
- the starting position (such as starting time or starting moment) and ending position (such as ending time or ending moment) of the speech word corresponding to " ⁇ " in the speech information can be pre-marked.
- the starting position and ending position of the speech words corresponding to " ⁇ ", “ ⁇ ”, “ ⁇ ”, and “ ⁇ ” in the speech information can be pre-marked. Further, according to the starting time and ending time of " ⁇ ”, “ ⁇ ”, “ ⁇ ”, “ ⁇ ”, and “ ⁇ ” predicted by the first machine learning model in the speech information, and the pre-marked starting position and ending position of " ⁇ ", “ ⁇ ", “ ⁇ ”, “ ⁇ ”, and “ ⁇ ” in the speech information, a first loss function is constructed.
- the first machine learning model is pre-trained according to the first loss function to obtain a pre-trained model.
- the embodiment of the present disclosure obtains voice information and text information corresponding to the voice information, and encodes the text information and the voice information respectively to obtain text encoding information and voice encoding information. Further, the text encoding information and the voice encoding information are fused to obtain the fused encoding information, and the corresponding time information of each text unit in the text information in the voice information is predicted according to the fused encoding information, and then the first machine learning model is pre-trained according to the predicted time information and the position annotation of the voice unit corresponding to each text unit in the text information in the voice information to obtain the pre-trained model.
- the pre-trained model can align the voice information and the text information in time sequence, for example, the alignment between the finer-grained text unit in the text information and the finer-grained voice unit in the voice information, thereby improving the pre-trained model's understanding of the voice information and the text information, thereby improving the accuracy of the pre-trained model's understanding of the user's speech.
- FIG3 is a schematic diagram of the structure of the first machine learning model.
- the first machine learning model includes a text encoder, a voice encoder, and a modal fusion layer.
- the pre-training method is described in detail below in conjunction with FIG3.
- the input of the first machine learning model includes text information and voice information, that is, the input of the first machine learning model is multimodal information.
- the voice information includes historical voice and current voice
- the text information includes historical text and current text. That is to say, for each modality of information, historical information and current information are included.
- the voice information is a voice dialogue between a user and an intelligent dialogue system
- the content of the dialogue is constantly increasing. Therefore, during the dialogue process, some voices can be used as historical voices, and some voices can be used as current voices.
- the text information is a text transcription of the voice dialogue
- some sentences in the text information can be used as historical texts, and some sentences can be used as current texts.
- FIG4 is a schematic diagram of a dialogue between a user and an intelligent dialogue system. Assume that the dialogue content shown in FIG4 is a text transcription.
- the text transcription of each sentence spoken by the user can be recorded as a round of text, and the text transcription of each sentence spoken by the intelligent dialogue system can be recorded as a round of text. Therefore, the dialogue content shown in FIG4 is 8 rounds of text, namely, "AAAAAA",
- HHHHH is a round of text.
- the first 7 rounds of text in the 8 rounds of text can be recorded as historical text, and the last round of text, that is, the text "HHHHH", can be recorded as the current text.
- the last round of text that is, the text "HHHHH”
- 8 rounds of text correspond to 8 rounds of voice
- the first 7 rounds of voice in the 8 rounds of voice are recorded as historical voice
- the voice corresponding to the last round of voice, that is, "HHHHH” is recorded as the current voice.
- the maximum length of a round of voice can be 10 seconds.
- the storage space occupied by the same round of text and the same round of voice may be different.
- the storage space occupied by the same round of voice can be can be larger, therefore, the same round of text and the same round of speech can be used as the input of the first machine learning model, or the first round of text and the second round of speech can be used as the input of the first machine learning model, where the first round is greater than the second round.
- 8 rounds of text and 2 rounds of speech can be selected as the input of the first machine learning model as shown in FIG3.
- the 8 rounds of text include 7 rounds of historical text and 1 round of current text.
- the 2 rounds of speech include 1 round of historical speech and 1 round of current speech.
- the 1 round of current text and the 1 round of current speech are aligned here, for example, the 1 round of current text here is "HHHHH", and the 1 round of current speech is the speech corresponding to "HHHHH". Therefore, the historical text shown in FIG3 can be the 7 rounds of historical text here, and the current text shown in FIG3 can be the 1 round of current text here.
- the historical speech shown in FIG3 can be the 1 round of historical speech here, and the current speech shown in FIG3 can be the 1 round of current speech here. That is, 7 rounds of historical text and 1 round of current text constitute text information, and 1 round of historical speech and 1 round of current speech constitute speech information.
- the text information is encoded by a text encoder to obtain text encoding information
- the speech information is encoded by a speech encoder to obtain speech encoding information.
- a preset symbol ⁇ s> can be added at the starting position of the 7 rounds of historical text, and a preset symbol ⁇ /s> can be added at the position between the 7 rounds of historical text and the 1 round of current text.
- a preset symbol ⁇ /s> can be added at the position between each adjacent two rounds of text, that is, ⁇ /s> is set to separate each round of text.
- preset symbols similar to vs> and v/s> can be used to separate the historical speech from the current speech, or to separate each round of speech.
- ⁇ s>, the 7 rounds of historical text as described above, ⁇ /s>, and the 1 round of current text as described above are encoded by a text encoder.
- the 1 round of historical speech as described above and the 1 round of current speech are encoded by a speech encoder.
- each round of text can be a sentence.
- Each sentence is composed of text units, and each text unit can also include at least one encoding unit.
- the historical text and the current text shown in FIG3 can be divided into several encoding units respectively, for example, box 31 represents any encoding unit.
- the preset symbol ⁇ s> can be used as an encoding unit
- the preset symbol ⁇ /s> can be used as an encoding unit.
- text encoding information is obtained, and the text encoding information includes the representation vector of each encoding unit.
- the text encoding information includes each representation vector in box 32 as shown in FIG3, and each small box (for example, box 33) in box 32 represents the representation vector of a coding unit.
- the historical voice and the Danghu voice shown in FIG3 are audio signals with a length of 10 seconds respectively.
- the historical voice can be divided into multiple voice segments, and the current voice can also be divided into multiple voice segments.
- the length of each voice segment can be 1 second.
- each speech segment in the historical speech is encoded by a speech encoder, and each speech segment in the current speech is encoded by a speech encoder to obtain speech encoding information, and the speech encoding information includes representation vectors of each speech segment.
- the speech encoding information includes each representation vector in the box 34 shown in FIG3 , and each small box (for example, box 35) in the box 34 represents a representation vector of a speech segment.
- the text encoding information represented by the box 32 and the speech encoding information represented by the box 34 are spliced, and the spliced result is used as the input of the modal fusion layer, so that the modal fusion layer performs a fusion process on the text encoding information and the speech encoding information to obtain the fused encoding information, and the fused encoding information can also be recorded as a joint representation vector.
- the fused encoding information includes each representation vector in the box 36 shown in FIG3 , and each small box (for example, box 37) in the box 36 represents a representation vector output by the modal fusion layer.
- box 33 represents the representation vector of the preset character ⁇ s>
- box 37 represents the first representation vector output by the modal fusion layer.
- the first representation vector is the fusion result of the text encoding information and the speech encoding information, that is, the first representation vector is the representation vector of the preset character ⁇ s>, the representation vector of the twilight encoding unit in the historical text, the representation vector of the preset character ⁇ /s>, the representation vector of each encoding unit in the current text, the representation vector of each speech segment in the historical speech, and the representation vector of each speech segment in the current speech. Therefore, the first representation vector does not contain It contains not only text components, but also speech components.
- representation vectors output by the modal fusion layer contain both text components and speech components.
- a part of the representation vectors is intercepted from each representation vector in the box 36 shown in FIG3 , for example, the representation vector corresponding to the current text output by the modal fusion layer is intercepted, that is, each representation vector in the box 38.
- the time information corresponding to each text unit in the current text in the current speech is predicted.
- the current speech is a 10-second speech. After normalizing the length of the current speech, the start position of the current speech can be recorded as 0, and the end position can be recorded as lo.
- the start time corresponding to each text unit in the current text in the current speech is predicted by the fully connected layer 1, and the end time corresponding to each text unit in the current text in the current speech is predicted by the fully connected layer 2.
- the start time for example, 0.05
- the end time for example, 0.16
- the start time for example, 0.18
- the end time for example, 0.32
- the start time for example, .067) and the end time (for example, 0.97) corresponding to "five times” in the current speech.
- the current text and the current speech are samples, respectively. Therefore, the position of the speech unit corresponding to each text unit in the current text in the speech information can be pre-marked.
- the current speech includes speech words corresponding to "he", “them”, “win”, “le”, and “five times", respectively, and the speech words are recorded as speech units.
- the speech word corresponding to "he” is the pronunciation of "he”. In this embodiment, "he" can be pre-marked.
- the starting position (e.g., starting time or starting moment) and ending position (e.g., ending time or ending moment) of the corresponding speech word in the current speech can be pre-marked.
- the starting time corresponding to " ⁇ ", “ ⁇ ”, “ ⁇ ”, “ ⁇ ”, and “ ⁇ ” in the current speech predicted by the fully connected layer 1 the starting position of the speech words corresponding to " ⁇ ", " ⁇ ", “ ⁇ ", “ ⁇ ”, and “ ⁇ ” in the current speech respectively, the first difference is constructed.
- the second difference is constructed. Further, a first loss function is constructed according to the first difference and the second difference, and the first machine learning model shown in FIG3 is pre-trained by the first loss function to obtain a pre-trained model.
- the fused encoded information includes the fused representation vectors corresponding to the respective encoding units and the fused representation vectors corresponding to the respective voice segments; according to the fused encoded information, predicting the time information corresponding to each text unit in the text information in the voice information includes: if the text unit includes one encoding unit, predicting the start time and end time corresponding to the text unit in the voice information according to the fused representation vector corresponding to the encoding unit; if the text unit includes multiple encoding units, predicting the start time corresponding to the text unit in the voice information according to the fused representation vector corresponding to the first encoding unit among the multiple encoding units, and predicting the end time corresponding to the text unit in the voice information according to the fused representation vector corresponding to the last encoding unit among the multiple encoding units.
- each fusion representation vector output by the modal fusion layer includes a fusion representation vector corresponding to the preset character vs>, a fusion representation vector corresponding to each coding unit in the historical text, a fusion representation vector corresponding to the preset character ⁇ /s>, a fusion representation vector corresponding to each coding unit in the current text, and a fusion representation vector corresponding to each speech segment.
- the time information corresponding to each text unit in the historical text in the historical speech can be predicted.
- the start time and end time corresponding to each text unit in the first round of historical speech are predicted, and so on, the start time and end time corresponding to each text unit in the eighth round of historical text in the eighth round of historical speech are predicted.
- the time information corresponding to each text unit in the current text can be predicted.
- the fused representation vectors corresponding to each coding unit predict the start time and end time corresponding to each text unit in the current text in the current speech. For example, the current text is "They won five times", "he", “they”, “win”, “have”, “five”, “have” are coding units respectively.
- the fused representation vectors output by the modality fusion layer include the fused representation vectors corresponding to "he", “they”, “win”, “have", “five”, “have”.
- a shown in Figure 6 represents the fused representation vector corresponding to "he”, and so on, F represents the fused representation vector corresponding to "have”.
- the text unit includes a coding unit, for example, “he” is a text unit, and the text unit includes a coding unit, and the coding unit is "he”, that is, "he” is both a text unit and a coding unit included in the text unit, therefore, the start time and end time corresponding to "he” in the current speech can be predicted according to the fused representation vector A corresponding to "he".
- the fully connected layer 1 shown in FIG6 includes a parameter W start
- the fully connected layer 2 includes a parameter Wend .
- the start time corresponding to "he” predicted by the fully connected layer 1 in the current speech is recorded as W start A
- the end time corresponding to "he” predicted by the fully connected layer 2 in the current speech is recorded as Wend A.
- the fully connected layer 1 can also predict the start time corresponding to "men”, “win”, and “le” in the current speech
- the fully connected layer 2 can also predict the end time corresponding to "men", "win”, and “le” in the current speech.
- “ ⁇ ” is a text unit, but the text unit includes multiple coding units, for example, " ⁇ ” is the first coding unit in the text unit, and " ⁇ " is the last coding unit in the text unit.
- the start time corresponding to " ⁇ " in the current speech can be predicted
- the fused representation vector corresponding to the last coding unit the end time corresponding to " ⁇ ” in the current speech can be predicted.
- the fused representation vector corresponding to " ⁇ ” is recorded as E
- the fusion representation vector corresponding to " ⁇ ” is denoted as F
- the corresponding start time of " ⁇ ” predicted by the fully connected layer 1 in the current speech is denoted as W start E
- W end time of " ⁇ ” predicted by the fully connected layer 2 in the current speech is denoted as W end F.
- pre-training the first machine learning model according to the predicted time information and the position annotation of the speech unit corresponding to each text unit in the text information in the speech information includes: constructing a first loss function according to the start time and end time corresponding to the text unit in the speech information, and the start position and end position of the speech unit corresponding to the text unit in the speech information that are pre-annotated; pre-training the first machine learning model according to the first loss function.
- the first loss function includes a first difference and a second difference
- the first difference is the difference obtained according to the start time and the start position
- the second difference is the difference obtained according to the end time and the end position.
- the duration of the current speech is 10 seconds, that is, the current speech starts from the 0th second and ends at the 10th second.
- the start position and end position of the speech unit corresponding to each text unit in the current text can be pre-marked in the current speech.
- the start position of the speech unit corresponding to "he" in the current speech is 0.6 seconds and the end position is 1.7 seconds.
- the start position of the speech unit corresponding to "five times" in the current speech is 6.9 seconds and the end position is 9.9 seconds.
- the duration of the current speech can be normalized in this embodiment, for example, the duration of the Dang Hu speech is normalized to 1 second, that is, the start position of the current speech is normalized to the second, and the end position of the current speech is normalized to the 1st second.
- the start and end positions of the speech units corresponding to each text unit in "They won five times" in the current speech are normalized.
- the start position of the speech unit corresponding to "he” in the current speech is 0.06 seconds and the end position is 0.17 seconds.
- the start position of the speech unit corresponding to "five times" in the current speech is 0.69 seconds and the end position is 0.99 seconds.
- the duration of the current speech (for example, 10 seconds) is uniformly divided.
- the fully connected layer 1 predicts The corresponding start time of "he” in the current speech is 0.05, while the start position of the speech unit corresponding to the pre-marked “he” in the current speech is 0.06 seconds, that is, there is a certain difference between the start time and the start position, and the difference is recorded as the first difference.
- the end time of "he” predicted by the fully connected layer 2 in the current speech is 0.16, while the end position of the speech unit corresponding to the pre-marked "he” in the current speech is 0.17 seconds, that is, there is a certain difference between the end time and the end position, and the difference is recorded as the second difference.
- first and second differences there are similar first and second differences.
- this embodiment is a schematic explanation based on the prediction of the start time and end time of each text unit in the current text.
- the time information corresponding to each text unit in the historical text in the historical speech can also be predicted. For example, according to the fusion representation vectors corresponding to each coding unit in the first round of historical text, the start time and end time corresponding to each text unit in the first round of historical text in the first round of historical speech are predicted, and so on, the start time and end time corresponding to each text unit in the eighth round of historical text in the eighth round of historical speech are predicted. Therefore, for each text unit in each round of historical text, there are similar first differences and second differences.
- this embodiment can construct a first loss function based on the first differences and second differences corresponding to each text unit in multiple rounds of text (including historical text and current text). Further, the first machine learning model shown in Figure 3 is pre-trained according to the first loss function.
- the first loss function can be expressed as the following formula:
- the first loss function uses the mean square error (MSE), which is the square of the difference between the prediction result (e.g., the predicted start time or end time) and the actual position (e.g., the pre-marked start position or end position).
- MSE mean square error
- i represents the i-th round of text
- m represents the round number or number of texts.
- j represents the j-th text unit in the i-th round of text, such as the /th word.
- n represents the number of words included in the i-th round of text.
- md represents the parameters included in the fully connected layer 2
- W start h s represents the fused representation vector corresponding to the first coding unit in the j-th text unit in the i-th round text
- W end h eij represents the fused representation vector corresponding to the last coding unit in the j-th text unit in the i-th round text.
- the j-th text unit includes multiple coding units, the first coding unit and the last coding unit here are different, that is, / ⁇ and ⁇ /are different. It can be understood that in the pre-training process, ⁇ and "end are parameters to be trained respectively.
- W start h s . represents the start time of the j-th text unit in the i-th round text predicted by the fully connected layer 1 in the i-th round speech
- W end h eij represents the end time of the J-th text unit in the i-th round text predicted by the fully connected layer 2 in the i-th round speech.
- Scale represents the duration of the Z-th round speech, or represents the maximum duration in multiple rounds of speech, and Scale is set to perform the above normalization processing.
- the parameters in each structure to be trained as shown in FIG. 3 or FIG. 6 are adjusted so that the prediction result output by the first machine learning model and the pre-marked true position gradually become similar in the subsequent iterative training process.
- the parameter adjustment can be guided according to the gradient data between the prediction result output by the first machine learning model and the pre-marked true position.
- the original meaning of the gradient is a vector (vector), indicating that the directional derivative of a function at this point obtains the maximum value along this direction, that is, the function changes fastest along this direction (the direction of this gradient) at this point, and the rate of change is the largest. It is also based on this principle that the adjustment direction of the parameters can be guided so that the prediction result output by the first machine learning model is close to the pre-marked real position.
- the sample data used when pre-training the first machine learning model includes text information and voice information.
- the text information includes 7 rounds of historical text and 1 round of current text
- the voice information includes 1 round of historical voice and 1 round of current voice
- the 7 rounds of historical text and 1 round of current text are 8 consecutive sentences in the same conversation
- 1 round of historical voice and 1 round of current voice are 2 consecutive voices in the same conversation. That is, there is a coherent semantics between the 7 rounds of historical text and 1 round of current text, and there is a coherent semantics between 1 round of historical voice and 1 round of current voice.
- three other sample data can be derived from the sample data.
- the first derived sample data is obtained after replacing 1 round of current text in the sample data with a sentence in other conversations, so that the semantics between the 7 rounds of historical text and 1 round of current text are no longer coherent, but the coherent semantics between 1 round of historical voice and 1 round of current voice are retained.
- the second derived sample data is obtained, resulting in the semantics between one round of historical speech and one round of current speech no longer being coherent, but the semantics between seven rounds of historical text and one round of current text are retained.
- the third derived sample data is obtained, resulting in the semantics between seven rounds of historical text and one round of current text no longer being coherent, and the semantics between one round of historical speech and one round of current speech no longer being coherent.
- the original sample data is recorded as sample data with a label (Label) of 0 as shown in FIG8
- the other three sample data derived from the original sample data are sample data with Label of 1, Label of 2, and Label of 3 as shown in FIG8 , respectively.
- QueryJ represents the historical text
- Query1 represents the current text
- Query represents the historical voice
- the pre-training method further includes the following steps as shown in FIG9:
- sample data with Label 0, Label 1, Label 2, or Label 3 can be used as It can be understood that if the current text is Query 1, the historical text matches the current text, that is, the speech between the historical text and the current text is coherent, and the historical text and the current text have obvious contextual relevance in semantic content. At this time, the historical text and the current text are contexts in the same conversation. If the current text is Query 2 , the historical text and the current text do not match, that is, the historical text and the current text are not contexts in the same conversation.
- the current voice is Query (, then the historical voice and the current voice match, that is, the voice between the historical voice and the current voice is coherent, and the historical voice and the current voice have obvious contextual relevance in semantic content.
- the historical voice and the current voice are the context in the same conversation.
- the current voice is Query (, then the historical voice and the current voice do not match, that is, the historical voice and the current voice are not the context in the same conversation. Therefore, the first judgment result as described above has two results, one result is that the historical voice and the current voice match, and the other result is that the historical voice and the current voice do not match.
- the second judgment result also has two results, one result is that the historical text and the current text match, and the other result is that the historical text and the current text do not match.
- the fully connected layer 3 may predict the type of the input sample according to the first judgment result and the second judgment result. For example, if the first judgment result indicates that the historical voice matches the current voice, and the second judgment result indicates that the historical text matches the current text, the fully connected layer 3 predicts that the input sample is a sample with a Label of 0. If the first judgment result indicates that the historical voice matches the current voice, and the second judgment result indicates that the historical text does not match the current text, the fully connected layer 3 predicts that the input sample is a sample with a Label of 1.
- This embodiment can also pre-annotate whether the historical speech and the current speech in the input sample actually constitute context information, and pre-annotate whether the historical text and the current text in the input sample actually constitute context information. That is, this embodiment can pre-annotate the actual type of the input sample, that is, pre-annotate whether the input sample is a sample with Label 0, Label 1, Label 2, or Label 3.
- this embodiment can construct a second loss function according to the type of the input sample predicted by the fully connected layer 3 and the actual type of the pre-annotated input sample, and the second loss function can be a classified cross-beam loss function.
- the first machine learning model shown in FIG10 is pre-trained according to the second loss function. This embodiment determines whether the historical speech and the current speech match through the coded information after the fusion process to obtain a first judgment result, and determines whether the historical text and the current text match to obtain a second judgment result. The first machine learning model can predict the type of the input sample according to the first judgment result and the second judgment result.
- the type of the input sample is pre-marked according to whether the historical speech and the current speech actually constitute context information, and whether the historical text and the current text actually constitute context information.
- the type of the input sample is predicted according to the pre-marked type of the input sample and the type of the input sample predicted by the first machine learning model. type, construct a second loss function, and pre-train the first machine learning model according to the second loss function to obtain a pre-trained model.
- the pre-trained model can recognize context information, which is conducive to improving the accuracy of the pre-trained model in recognizing user intentions, sentiment analysis, etc.
- this embodiment can pre-train the first machine learning model according to the first loss function or the second loss function alone, or can pre-train the first machine learning model according to the first loss function and the second loss function.
- the first machine learning model in addition to the above-mentioned time series prediction tasks (such as predicting the start time and end time of a text unit in speech) and cross-modal dialogue response selection tasks (such as predicting the type of input samples), can also be pre-trained through other tasks.
- the first machine learning model can also be pre-trained through a mask prediction task.
- this embodiment can mask some words in the historical text or the current text, and/or mask some speech segments in the historical speech or the current speech.
- the masked sample is input into the first machine learning model, and further, the masked part of the word and/or part of the speech is predicted according to the fusion representation vector output by the modality fusion layer.
- a third loss function is constructed according to the predicted masked part of the word and/or part of the speech, and the actually masked part of the word and/or part of the speech, and the first machine learning model is pre-trained according to the third loss function.
- different modal information for example, text and speech, is used to model the interaction of the two modalities of text and speech. It can be understood that after pre-training the first machine learning model, a pre-trained model can be obtained, and the pre-trained model can be used as a model basis.
- FIG. 11 is a flow chart of a machine learning model training method provided in another embodiment of the present disclosure.
- the machine learning model training method can be a method for training or fine-tuning the pre-trained model.
- the specific steps of the method are as follows:
- the pre-trained model may be retained in the server 22, and further, the server 22 may train or fine-tune the pre-trained model.
- the server 22 may obtain sample data of a target task, wherein the target task may be a downstream task as described above, wherein the sample data includes data to be processed and a labeling result of the data to be processed, wherein the data to be processed includes sample speech and sample text corresponding to the sample speech.
- the labeling result of the data to be processed is a user emotion category, a user emotion category, a user intention, or key information in the sample speech or sample text pre-labeled according to the sample speech and/or sample text.
- the target task includes at least one of the following: an emotion analysis task, an emotion recognition task, an intention analysis task, and a key information collection task.
- the sample data acquired by the server 22 includes a sample speech, a sample text corresponding to the sample speech, and a user sentiment category corresponding to the sample speech or sample text marked in advance.
- the sample text includes a historical text and a current text
- the sample speech includes a historical speech and a current speech.
- the second machine learning model is a pre-trained model obtained according to the pre-training method as described above.
- the historical text, current text, historical speech and current speech are input into the second machine learning model, i.e., the pre-trained model, so that the text encoder, speech encoder and modality fusion layer in the pre-trained model process the input of the pre-trained model, and predict the user emotion category corresponding to the sample speech or sample text according to the fusion representation vector (e.g., the first fusion representation vector) output by the modality fusion layer.
- the user emotion category can be used as the processing result output by the pre-trained model.
- the pre-trained model is trained or fine-tuned according to the user emotion category corresponding to the sample speech or sample text predicted by the pre-trained model, and the user emotion category corresponding to the sample speech or sample text marked in advance, so as to obtain a trained machine learning model.
- the pre-trained model can be trained or fine-tuned by using sample data of an emotion recognition task, an intention analysis task, or a key information collection task.
- the pre-trained model can be trained or fine-tuned by the emotion analysis task, the emotion recognition task, the intention analysis task, or the key information collection task alone.
- the pre-trained model is trained or fine-tuned by jointly using the emotion analysis task, the emotion recognition task, the intention analysis task, and the key information collection task.
- the pre-trained model is not limited to being trained or fine-tuned by the several tasks described above.
- other tasks can also be used to train or fine-tune the pre-trained model.
- the sample speech is a dialogue between a user and an intelligent dialogue system. During the dialogue, the user and the intelligent dialogue system may talk about some key information.
- This embodiment is the first to perform joint modeling based on speech semantics in a dialogue scenario, pre-train the first machine learning model through the time series prediction task according to the temporal characteristics of the speech, and introduce a cross-modal dialogue reply selection task to pre-train the first machine learning model.
- the pre-trained model obtained after pre-training can not only align the voice information and text information in time sequence, but also identify context information.
- the solution provided in this embodiment is 5-20 percentage points higher than the existing voice semantic modeling method, and can more accurately understand the user's speech and improve the user experience. Therefore, in use, the solution described in this embodiment can not only learn more fine-grained and accurate voice text alignment, but also capture more voice information, better help the system understand the user's intention, and improve the user experience.
- the method described in this embodiment is improved over both the pure text model and the pure voice model, and the improvement is more than the voice model, which shows that our model has well promoted the joint modeling of voice and semantics.
- our method has a huge improvement over the existing optimal pre-training method for joint modeling of voice and semantics.
- FIG12 is a flow chart of an intelligent dialogue method provided by another embodiment of the present disclosure.
- the method can be executed by a cloud server.
- the cloud server is deployed with a machine learning model that has been trained or fine-tuned as described above.
- the cloud server can implement the intelligent dialogue method described in this embodiment through the machine learning model that has been trained or fine-tuned.
- the specific steps of the method are as follows:
- S1201 Obtain historical conversations between a target user and an intelligent dialogue system, and text information corresponding to the historical conversations.
- the cloud server may be pre-deployed with an intelligent dialogue system, and the cloud server may obtain historical conversations between a target user and the intelligent dialogue system, and text information corresponding to the historical conversations.
- S1202 Input the historical conversation and the text information into a trained machine learning model, so that the machine learning model outputs at least one of the emotion, mood, intention, and key information of the target user, and the machine learning model is trained according to the above method.
- the cloud server may input the historical conversation and the text information into a trained or fine-tuned machine learning model, so that the machine learning model outputs at least one of the emotion, mood, intention, and key information of the target user. At least one of the information.
- the cloud server may conduct an intelligent dialogue with the target user according to at least one of the target user's emotion, mood, intention, and key information.
- the cloud server may conduct an intelligent dialogue with the target user according to at least one of the target user's emotion, mood, intention, and key information.
- the cloud server may generate reply information for the question according to at least one of the target user's emotion, mood, intention, and key information, and feed the reply information back to the target user's terminal.
- the cloud server may generate a question sentence according to at least one of the target user's emotion, mood, intention, and key information, and feed the question sentence back to the target user's terminal, so that the target user and the intelligent dialogue system in the cloud server continue to have a dialogue.
- This embodiment obtains the historical dialogue between the target user and the intelligent dialogue system, as well as the text information corresponding to the historical dialogue, and inputs the historical dialogue and the text information into the trained machine learning model, so that the machine learning model outputs at least one of the emotion, mood, intention, and key information of the target user. This improves the accuracy of the machine learning model in understanding the target user.
- the machine learning model training device 130 includes: an acquisition module 131, which is configured to acquire voice information and text information corresponding to the voice information; an encoding module 132, which is configured to encode the text information and the voice information respectively to obtain text encoding information and voice encoding information; a fusion processing module 133, which is configured to fuse the text encoding information and the voice encoding information to obtain the fused encoding information; a prediction module 134, which is configured to predict the time information corresponding to each text unit in the text information in the voice information according to the encoding information corresponding to the text information in the fused encoding information; a pre-training module 135, which is configured to pre-train the first machine learning model according to the predicted time information and the position annotation of the voice unit corresponding to each text unit in the text information in the voice information.
- the encoding module 132 encodes the text information and the voice information respectively to obtain text encoding information and voice encoding information
- it is specifically configured to: encode at least one encoding unit respectively included in each text unit in the text information by a text encoder to obtain text encoding information, wherein the text encoding information includes representation vectors of each encoding unit; and encode each voice segment in the voice information by a voice encoder to obtain voice encoding information, wherein the voice encoding information includes representation vectors of each voice segment.
- the fused encoding information includes the fused representation vectors corresponding to the respective encoding units and the fused representation vectors corresponding to the respective voice segments; when the prediction module 134 predicts the time information corresponding to each text unit in the text information in the voice information according to the fused encoding information, it is specifically set to: if the text unit includes one encoding unit, then the start time and end time corresponding to the text unit in the voice information are predicted according to the fused representation vector corresponding to the encoding unit; if the text unit includes multiple encoding units, then the start time corresponding to the text unit in the voice information is predicted according to the fused representation vector corresponding to the first encoding unit in the multiple encoding units, and the end time corresponding to the text unit in the voice information is predicted according to the fused representation vector corresponding to the last encoding unit in the multiple encoding units.
- the pre-training module 135 predicts the time information corresponding to each text unit in the text information according to the predicted time information and the fused representation vector corresponding to the last encoding unit in the multiple encoding units.
- the position of the speech unit corresponding to this unit in the speech information is marked.
- pre-training the first machine learning model it is specifically set to: construct a first loss function according to the start time and end time corresponding to the text unit in the speech information, and the start position and end position of the speech unit corresponding to the pre-marked text unit in the speech information; pre-train the first machine learning model according to the first loss function.
- the first loss function includes a first difference and a second difference, the first difference is the difference obtained according to the start time and the start position, and the second difference is the difference obtained according to the end time and the end position.
- the voice information includes historical voice and current voice
- the text information includes historical text and current text
- the model pre-training device 130 also includes: a judgment module 136, which is configured to judge whether the historical voice and the current voice match according to the coded information after the fusion process, and obtain a first judgment result, and judge whether the historical text and the current text match, and obtain a second judgment result
- the pre-training module 135 is also configured to predict the type of input sample according to the first judgment result and the second judgment result, and the input sample includes the voice information and the text information; according to the predicted type of input sample and the type of the pre-labeled input sample, a second loss function is constructed, and the first machine learning model is pre-trained according to the second loss function to obtain a pre-trained model.
- FIG. 14 is a structural schematic diagram of a machine learning model training device provided in an embodiment of the present disclosure.
- the machine learning model training device provided in the embodiment of the present disclosure can execute the processing flow provided in the machine learning model training method embodiment.
- the machine learning model training device 140 includes: an acquisition module 141, which is configured to acquire sample data of a target task, wherein the sample data includes data to be processed and the annotation results of the data to be processed, and the data to be processed includes sample speech and sample text corresponding to the sample speech; an input module 142, which is configured to input the data to be processed into a second machine learning model so that the second machine learning model outputs a processed result, and the second machine learning model is a pre-trained model obtained according to the pre-training method described above; a training module 143, which is configured to train the second machine learning model according to the processed result output by the second machine learning model and the annotation results of the data to be processed, to obtain a trained machine learning model.
- an acquisition module 141 which is configured to acquire sample data of a target task, wherein the sample data includes data to be processed and the annotation results of the data to be processed, and the data to be processed includes sample speech and sample text corresponding to the sample speech
- an input module 142 which is configured to input the data to be
- the target task includes at least one of the following: sentiment analysis task, emotion recognition task, intention analysis task, and key information collection task.
- the model training device of the embodiment shown in FIG14 can be configured to execute the technical solution of the above method embodiment, and its implementation principle and technical effect are similar, which will not be repeated here.
- FIG15 is a schematic diagram of the structure of an intelligent dialogue device provided in an embodiment of the present disclosure.
- the intelligent dialogue device provided in an embodiment of the present disclosure can execute the processing flow provided in an embodiment of an intelligent dialogue method.
- an intelligent dialogue device 150 includes: an acquisition module 151, which is configured to acquire a historical dialogue between a target user and an intelligent dialogue system, and text information corresponding to the historical dialogue; an input module 152, which is configured to input the historical dialogue and the text information into a trained machine learning model, so that the machine learning model outputs at least one of the emotion, mood, intention, and key information of the target user, and the machine learning model is trained according to the method described above; a dialogue module 153, which is configured to conduct an intelligent dialogue with the target user according to at least one of the emotion, mood, intention, and key information of the target user.
- FIG16 is a schematic diagram of the structure of an electronic device embodiment provided by an embodiment of the present disclosure.
- the electronic device includes a memory 161 and a processor 162.
- the memory 161 is configured to store programs.
- the memory 161 can also be configured to store various other data to support operations on the electronic device. Examples of these data include instructions of any application or method set to operate on the electronic device, contact data, phone book data, messages, pictures, videos, etc.
- the memory 161 can be implemented by any type of volatile or non-volatile storage device or a combination thereof, such as a static random access memory (SRAM), an electrically erasable programmable read-only memory (EEPROM), an erasable programmable read-only memory (EPROM), a programmable read-only memory (PROM), a read-only memory (ROM), a magnetic memory, a flash memory, a disk or an optical disk.
- SRAM static random access memory
- EEPROM electrically erasable programmable read-only memory
- EPROM erasable programmable read-only memory
- PROM programmable read-only memory
- ROM read-only memory
- the processor 162 is coupled to the memory 161, and executes the program stored in the memory 161, so as to be set to: obtain voice information and text information corresponding to the voice information; encode the text information and the voice information respectively to obtain text encoding information and voice encoding information; fuse the text encoding information and the voice encoding information to obtain the fused encoding information; predict the time information corresponding to each text unit in the text information in the voice information according to the encoding information corresponding to the text information in the fused encoding information: pre-train the first machine learning model according to the predicted time information and the position mark of the voice unit corresponding to each text unit in the text information in the voice information to obtain the pre-trained model.
- the electronic device may also include: a communication component 163, a power supply component 164, an audio component 165, a display 166 and other components.
- FIG16 only schematically shows some components, which does not mean that the electronic device only includes the components shown in FIG16.
- the communication component 163 is configured to facilitate wired or wireless communication between the electronic device and other devices.
- the electronic device can access a wireless network based on a communication standard, such as WiFi, 2G or 3G, or a combination thereof.
- the communication component 163 receives a broadcast signal or broadcast-related information from an external broadcast management system via a broadcast channel.
- the communication component 163 also includes a near field communication (NFC) module to facilitate short-range communication.
- NFC near field communication
- the NFC module can be implemented based on radio frequency identification (RFID) technology, infrared data association (IrDA) technology, ultra-wideband (UWB) technology, Bluetooth (BT) technology and other technologies.
- RFID radio frequency identification
- IrDA infrared data association
- UWB ultra-wideband
- BT Bluetooth
- the power supply component 164 provides power for various components of the electronic device.
- the power supply component 164 may include a power management system, one or more power supplies, and other components associated with generating, managing and distributing power for the electronic device.
- the audio component 165 is configured to output and/or input audio signals.
- the audio component 165 includes a microphone (M1C), and when the electronic device is in an operating mode, such as a call mode, a recording mode, and a voice recognition mode, the microphone is configured to receive an external audio signal.
- M1C microphone
- the received audio signal may be further stored in the memory 161 or sent via the communication component 163.
- the audio component 165 further includes a speaker configured to output an audio signal.
- the display 166 includes a screen, which may include a liquid crystal display (LCD) and a touch panel (TP). If the screen includes a touch panel, the screen may be implemented as a touch screen to receive input signals from a user.
- the touch panel includes one or more touch sensors to sense touch, slide, and gestures on the touch panel. The touch sensor may not only sense the boundaries of a touch or slide action, but also detect the duration and pressure associated with the touch or slide operation.
- embodiments of the present disclosure further provide a computer-readable storage medium on which a computer program is stored, and the computer program is executed by a processor to implement the model pre-training, training, and intelligent dialogue methods described in the above embodiments.
- relational terms such as “first” and “second” are used to distinguish one entity or operation from another entity or operation, and do not necessarily require or imply any such actual relationship or order between these entities or operations.
- the terms "including”, “comprising” or any other variations thereof are intended to cover non-exclusive inclusion, so that a process, method, article or device including a series of elements includes not only those elements, but also other elements not explicitly listed, or also includes elements inherent to such process, method, article or device.
- the machine learning model training, dialogue method, device, equipment and medium provided by the embodiments of the present disclosure are applied to machine learning scenarios, by acquiring voice information and text information corresponding to the voice information, and encoding the text information and the voice information respectively, to obtain text encoding information and voice encoding information. Further, the text encoding information and the voice encoding information are fused to obtain the fused encoding information, and the time information corresponding to each text unit in the text information in the voice information is predicted according to the fused encoding information, and then the first machine learning model is pre-trained according to the predicted time information and the position annotation of the voice unit corresponding to each text unit in the text information in the voice information to obtain a pre-trained model.
- the pre-trained model can align the voice information and text information in time sequence, for example, the alignment between finer-grained text units in the text information and finer-grained voice units in the voice information, thereby improving the pre-trained model's understanding of the voice information and text information, thereby improving the accuracy of the pre-trained model's understanding of user speech.
Landscapes
- Engineering & Computer Science (AREA)
- Physics & Mathematics (AREA)
- Theoretical Computer Science (AREA)
- Computational Linguistics (AREA)
- Artificial Intelligence (AREA)
- Data Mining & Analysis (AREA)
- Health & Medical Sciences (AREA)
- General Engineering & Computer Science (AREA)
- General Physics & Mathematics (AREA)
- Mathematical Physics (AREA)
- Evolutionary Computation (AREA)
- Software Systems (AREA)
- General Health & Medical Sciences (AREA)
- Life Sciences & Earth Sciences (AREA)
- Computing Systems (AREA)
- Molecular Biology (AREA)
- Biophysics (AREA)
- Biomedical Technology (AREA)
- Human Computer Interaction (AREA)
- Audiology, Speech & Language Pathology (AREA)
- Acoustics & Sound (AREA)
- Multimedia (AREA)
- Databases & Information Systems (AREA)
- Computer Vision & Pattern Recognition (AREA)
- Evolutionary Biology (AREA)
- Bioinformatics & Computational Biology (AREA)
- Bioinformatics & Cheminformatics (AREA)
- Medical Informatics (AREA)
- Child & Adolescent Psychology (AREA)
- Hospice & Palliative Care (AREA)
- Psychiatry (AREA)
- Signal Processing (AREA)
- Machine Translation (AREA)
- Electrically Operated Instructional Devices (AREA)
Abstract
说明书摘要本公开实施例涉及一种机器学习模型训练、对话方法、装置、设备及介质。本公开通过获取语音信息、以及语音信息对应的文本信息,并分别对文本信息和语音信息进行编码,得到文本编码信息和语音编码信息。对文本编码信息和语音编码信息进行融合处理,得到融合处理后的编码信息,根据融合处理后的编码信息,预测文本信息中每个文本单元在语音信息中对应的时间信息,根据预测的时间信息、以及文本信息中每个文本单元对应的语音单元在语音信息中的位置标注,对第一机器学习模型进行预训练,得到预训练模型。
Description
机器学习模型训练、 对话方法、 装置、 设备及介质 交叉援引 本公开要求于 2023年 04月 11 日提交中国专利局、 申请号 202310397072.3、 申 请名称 “机器学习模型刮练、 对话方法、 装置、 设备及介质” 的中国专利申请的优先 权, 其全部内容通过引用结合在本公开中。 技术领域 本公开涉及信息技术领域, 尤其涉及一种机器学习模型训练、 对话方法、 装置、 设备及介质。 背景技术 目前, 智能客服在一些业务场景下可以与用户进行对话, 从而为用户提供业务咨 询、 业务办理等服务。 具体的, 智能客服可以通过部署在计算设备例如计算机或计算 机集群上的机器学习模型来实现。 但是, 目前的机器学习模型对用户话语理解的精准度不高。 发明内容 为了解决上述技术问题或者至少部分地解决上述技术问题, 本公开提供了一种机 器学习模型训练、 对话方法、 装置、 设备及介质, 以提高预训练模型对语音信息和文 本信息的理解力, 从而提高预训练模型对用户话语理解的精准度。 第一方面, 本公开实施例提供一种机器学习模型训练方法, 包括: 获取语音信息、 以及所述语音信息对应的文本信息; 分别对所述文本信息和所述语音信息进行编码 , 得到文本编码信息和语音编码信 息; 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码 信息; 根据所述融合处理后的编码信息中与所述文本信息对应的编码信息, 预测所述文 本信息中每个文本单元在所述语音信息中对应的时间信息; 根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语音单元在 所述语音信息中的位置标注, 对第一机器学习模型进行预训练。 第二方面, 本公开实施例提供一种机器学习模型训练方法, 所述方法包括: 获取目标任务的样本数据, 所述样本数据包括待处理数据和所述待处理数据的标 注结果, 所述待处理数据包括样本语音、 以及所述样本语音对应的样本文本; 将所述待处理数据输入到第二机器学习模型中, 使得所述第二机器学习模型输出 处理后的结果, 所述第二机器学习模型是根据如第一方面所述的训练方法得到的预训 练模型; 根据所述第二机器学习模型输出的处理后的结果、 以及所述待处理数据的标注结 果, 对所述第二机器学习模型进行训练, 得到训练后的机器学习模型。 第三方面, 本公开实施例提供- ■种智能对话方法, 所述方法包括: 获取目标用户和智能对话系统之间的历史对话, 以及所述历史对话对应的文本信 息;
' 将所述历史对话和所述文本信息输入到训练后的机器学习模型中, 使得所述机器 学习模型输出所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 所述机器 学习模型是根据第二方面所述的方法训练得到的;
根据所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 与所述目标用 户进行智能对话。 第四方面, 本公开实施例提供一种机器学习模型训练装置, 包括: 获取模块, 被设置为获取语音信息、 以及所述语音信息对应的文本信息; 编码模块, 被设置为分别对所述文本信息和所述语音信息进行编码, 得到文本编 码信息和语音编码信息; 融合处理模块, 被设置为对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码信息; 预测模块, 被设置为根据所述融合处理后的编码信息中与所述文本信息对应的编 码信息, 预测所述文本信息中每个文本单元在所述语音信息中对应的时间信息; 预训练模块, 被设置为根据所述预测的时间信息、 以及所述文本信息中每个文本 单元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练。 第五方面, 本公开实施例提供一种电子设备, 包括: 存储器; 处理器; 以及 计算机程序; 其中, 所述计算机程序存储在所述存储器中, 并被配置为由所述处理器执行以实 现如第一方面、 第二方面或第三方面所述的方法。 第六方面,本公开实施例提供一种计算机可读存储介质,其上存储有计算机程序, 所述计算机程序被处理器执行以实现第一方面、 第二方面或第三方面所述的方法。 本公开实施例提供的机器学习模型训练、 对话方法、 装置、 设备及介质, 通过获 取语音信息、 以及所述语音信息对应的文本信息, 并分别对所述文本信息和所述语音 信息进行编码, 得到文本编码信息和语音编码信息。 进一步, 对所述文本编码信息和 所述语音编码信息进行融合处理, 得到融合处理后的编码信息, 根据所述融合处理后 的编码信息, 预测所述史本信息中每个文本单元在所述语音信息中对应的时间信息, 然后根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语音单元在 所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模型。 使 得预训练模型可以将语音信息和文本信息在时序上进行对齐, 例如, 文本信息中更细 粒度的文本单元与语音信息中更细粒度的语音单元之间的对齐, 从而提高预训练模型 对语音信息和文本信息的理解力, 从而提高预训练模型对用户话语理解的精准度。 附图说明 此处的附图被并入说明书中并构成本说明书的一部分, 示出了符合本公开的实施 例, 并与说明书一起用于解释本公开的原理。 为了更清楚地说明本公开实施例或现有技术中的技术方案, 下面将对实施例或现 有技术描述中所需要使用的附图作简单地介绍, 显而易见地, 对于本领域普通技术人 员而言, 在不付出创造性劳动性的前提下, 还可以根据这些附图获得其他的附图。 图 1为本公开实施例提供的模型预训练方法流程图; 图 2为本公开实施例提供的应用场景的示意图; 图 3为本公开实施例提供的机器学习模型的示意图; 图 4为本公开实施例提供的用户与智能对话系统对话的示意图; 图 5为本公开另一实施例提供的时序预测的示意图; 图 6为本公开另一实施例提供的机器学习模型的示意图; 图 7为本公开另一实施例提供的第一损失函数的构造示意图; 图 8为本公开另一实施例提供的多种类型的样本数据的示意图; 图 9为本公开另一实施例提供的模型预训练方法流程图; 图 10为本公开另一实施例提供的机器学习模型的示意图;
图 11 为本公开另一实施例提供的模型训练方法流程图; 图 12为本公开另一实施例提供的智能对话方法流程图; 图 13为本公开实施例提供的模型预训练装置的结构示意图; 图 14为本公开实施例提供的模型训练装置的结构示意图; 图 15为本公开实施例提供的智能对话装置的结构示意图; 图 16为本公开实施例提供的电子设备实施例的结构示意图。 具体实施方式 为了能够更清楚地理解本公开的上述目的、 特征和优点, 下面将对本公开的方案 进行进一步描述。 需要说明的是, 在不冲突的情况下, 本公开的实施例及实施例中的 特征可以相互组合。 在下面的描述中阐述了很多具体细节以便于充分理解本公开, 但本公开还可以采 用其他不同于在此描述的方式来实施; 显然, 说明书中的实施例只是本公开的一部分 实施例, 而不是全部的实施例。 需要说明的是, 本公开所涉及的语音信息 (包括但不限于终端设备采集的用户语 音) 和文本信息 (包括但不限于用户语音对应的文本信息等) , 均为经用户授权或者 经过各方充分授权的信息和数据, 并且相关数据的收集、 使用和处理需要遵守相关国 家和地区的相关法律法规和标准, 并提供有相应的操作入口, 供用户选择授权或者拒 绝。 另外, 本公开提供的机器学习模型训练、对话方法会涉及到如下的几个札语解释, 详细内容如下: 语音语义联合建模: 系统同时将语音和对应的文本转写作为输入, 在语音文本对 齐等任务的引导下, 实现语音和文本理解的共同提升。 预训练: 重要的手段, 让模型在大规模语料上进行无监督的学习, 可以大幅度提 升下游任务的结果。 时序性: 指输入序列有时间顺序的特性。 语音和文本都具有时序性。 导航: 用户打电话给语音机器人。 外呼: 语音机器人向用户拨打电话。 通常情况下, 智能客服在一些业务场景下可以与用户进行对话, 从而为用户提供 业务咨询、 业务办理等服务。 具体的, 智能客服可以通过部署在计算设备例如计算机 或计算机集群上的机器学习模型来实现。 但是, 目前的机器学习模型对用户话语理解 的精准度不高。 针对该问题, 本公开实施例提供了一种机器学习模型训练方法, 下面 结合具体的实施例对该方法进行介绍。 图 1 为本公开实施例提供的机器学习模型训练方法流程图。 该机器学习模型训练 方法具体可以是预训练方法。 该方法可以由机器学习模型训练装置执行, 该装置可以 采用软件和/或硬件的方式实现, 该装置可配置于电子设备中, 例如服务器或终端中, 其中, 终端具体包括手机、 电脑或平板电脑等。 服务器具体可以是云端的服务器, 该 机器学习模型训练方法可以由云端来执行, 在云端可以部署有若干计算节点 (云服务 器) , 每个计算节点中都具有计算、 存储等处理资源。 在云端, 可以组织由多个计算 节点来提供某种服务, 当然, 一个计算节点也可以提供一种或多种服务。 云端提供该 服务的方式可以是对外提供服务接口, 用户调用该服务接口以使用相应的服务。 服务 接口包括软.件开发工具包 (Software Development Kit, 简称 SDK) 、 应用程序接口 (Application Programming Interface, 简称 API) 等形式。 另外, 本实施例所述的机器 学习模型训练方法可以适用于如图 2所示的应用场景。 如图 2所示, 该应用场景包括 终端 21和服务器 22, 其中, 服务器 22可以采用本实施例所述的机器学习模型训练方 法对第一机器学习模型进行预训练, 该第一机器学习模型经过预训练之后得到预训练 模型, 进一步, 该预训练模型可以保留在服务器 22中, 或者服务器 22可以将预训练
模型部署到终端 21 或其他服务器上。 下面结合图 2对该方法进行详细介绍, 如图 1 所示, 该方法具体步骤如下:
5101、 获取语音信息、 以及所述语音信息对应的文本信息。 例如, 服务器 22中可设置有智能对话系统, 如图 2所示的终端 21可以采集用户 语音, 并将用户语音发送给服务器 22, 该智能对话系统可以根据该用户语音进行语音 回复。 进一步, 服务器 22将该智能对话系统的语音回复反馈给终端 21 , 依此类推, 使得终端 21 的用户可以与该智能对话系统进行语音对话。 在对话过程中, 服务器 22 可以获取语音信息, 该语音信息可以是用户与智能对话系统之间的语音对话。进一步, 服务器 22还可以通过语音识别 (Automatic Speech Recognition, ASR) 将该语音对话 转换为相应的文本信息, 即该文本信息是该语音对话的文本转写。 或者, 服务器 22 获取的语音信息可以是用户语音, 该文本信息是该用户语音的文本转写。 具体的, 该语音信息、 以及该语音信息对应的文本信息可作为第一机器学习模型 的输入。 在本实施例中, 该文本信息可以包括至少一个句子。 该语音信息可包括该至 少一个句子中每个句子的语音, 或者包括该至少一个句子中部分句子的语音。
5102、 分别对所述文本信息和所述语音信息进行编码, 得到文本编码信息和语音 编码信息。 在本实施例中, 第一机器学习模型可包括文本编码器和语音编码器, 其中, 文本 编码器可被设置为对文本信息进行编码, 得到文本编码信息。 语音编码器可被设置为 对语音信息进行编码, 得到语音编码信息。 在一种可行的实现方式中, 文本编码器可以对该文本信息中包括的每个句子分别 进行编码, 得到文本编码信息, 该文本编码信息包括每个句子的表示向量。 同理, 语 音编码器可以对该语音信息中每个句子的语音分别进行编码, 得到语音编码信息, 该 语音编码信息包括每个句子的语音的表示向量。 在另一种可行的实现方式中, 分别对所述文本信息和所述语音信息进行编码, 得 到文本编码信息和语音编码信息, 包括: 通过文本编码器对所述文本信息中每个文本 单元分别包括的至少一个编码单元进行编码, 得到文本编码信息, 所述文本编码信息 包括各个编码单元的表示向量; 通过语音编码器对所述语音信息中的每个语音片段进 行编码, 得到语音编码信息, 所述语音编码信息包括各个语音片段的表示向量。 例如, 该文本信息中的每个句子由文本单元构成, 该文本单元可以是字符、 字、 词、 词组、 子词、 单词等。 例如, 一个句子是 ' '他们赢了五把" , 以词作为文本单元 时, 该句子可分割为 5 个词, 分别是 “他” 、 "们” 、 “赢” 、 “了 ” 、 “五把” 。 其中,每个文本单元还可以包括至少一个编码单元,例如, “他"包括一个字, 则 “他” 包括一个编码单元, 即 "他” 本身。 “五把” 包括两个字, 如果将一个字作为一个编 码单元, 则 “五把 " 包括两个编码单元。 因此, “他们赢了五把 " 这句话包括 6个编 码单元, 分别是 "他” 、 "们” 、 “赢” 、 "了 ” 、 “五 " 、 "把” o 因此, 通过文 本编码器对 "他们赢了五把 ” 这句话编码时, 可以对该 6 个编码单元分别进行编码, 经过编码之后, 每个编码单元对应一个表示向量。 再例如, 一个句子是" They won five games successively , 该句子一共包括 5个 单词, 每个单词作为一个文本单元, 由于前 4个单词分别较短, 因此, 的 4个单词中 的每个单词可分别作为一个编码单元。 但是, 最后一个单词即 " successively ” 较长, 此处可以将该单词划分为两个编码单元, 分别是 “ success" 和 “ively" 。 因此, 通过 文本编码器对 " They won five games successively” 这句话编码时, 可以对 6个编码单 元即 “ They" 、 "won" 、 “ five" 、 “ games” 、 " success” 、 " ively" 分别进行编 码, 经过编码之后, 每个编码单元对应一个表示向量。 由于该文本信息包括的句子不限于一个, 每个句子可包括多个文本单元, 每个文 本单元还可以包括至少一个编码单元, 因此, 通过文本编码器对该文本信息进行编码
时, 可通过文本编码器对该文本信息中的每个编码单元进行编码,得到文本编码信息, 文本编码信息包括各个编码单元的表示向量。 另外, 语音信息中每个句子的语音可以是长度为 10 秒的音频信号, 在进行语音 编码之前, 还可以将每个句子的语音拆分为多个语音片段, 例如, 每个语音片段的长 度可以是 1秒。 进一步, 通过语音编码器对该语音信息中的每个语音片段分别进行编 码, 得到语音编码信息, 该语音编码信息包括各个语音片段的表示向量。
5103、 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后 的编码信息。 在本实施例中, 第一机器学习模型还可以包括模态融合层。 在得到如上所述的文 本编码信息和语音编码信息之后, 可以将该文本编码信息和语音编码信息进行拼接, 并将拼接后的结果作为该模态融合层的输入, 使得该模态融合层对该文本编码信息和 语音编码信息进行融合处理, 得到融合处理后的编码信息, 该融合处理后的编码信息 也可记为联合表示向量。 具体的, 模态融合层的输入和输出一一对应, 例如, 模态融 合层的输入包括 m个编码单元的表示向量和 n个语音片段的表示向量,即模态融合层 的输入包括 m+n个表示向量, 则模态融合层的输出也包括 m+n个表示向量, 并且输 入中的 m+n个表示向量和输出中的 m+n个表示向量一一对应。 对于模态融合层输出 的每个表示向量而言, 该表示向量同时包含文本成分和语音成分。 因此, 模态融合层 输出的每个表示向量可记为融合表示向量。
5104、 根据所述融合处理后的编码信息中与所述文本信息对应的编码信息, 预测 所述文本信息中每个文本单元在所述语音信息中对应的时间信息。 例如, 文本信息包括 m个编码单元, 语音信息包括 n个语音片段, 模态融合层的 输入包括 m个编码单元的表示向量和 n个语音片段的表示向量。由于模态融合层的输 入和输出是一一对应的, 因此, 模态融合层输出的前 m个表示向量是与该文本信息对 应的编码信息, 模态融合层输出的后 n 个表示向量是与该语音信息对应的编码信息。 由于模态融合层输出的每个表示向量同时包含文本成分和语音成分, 因此, 第一机器 学习模型根据模态融合层输出的前 m个表示向量,可预测出该文本信息中每个文本单 元在该语音信息中对应的时间信息。 例如, 每个文本单元在该语音信息中对应的时间 信息包括该文本单元在该语音信息中对应的开始时间和结束时间。 可以理解的是, 文 本单元例如 “他” 、 "们” 、 “赢” 、 “了 ” 、 “五把” 分别是文本类型的信息, 每 个文本单元分别对应一个语音词, 该语音词是语音类型的信息, 一个文本单元对应的 语音词可以是用户或智能对话系统对该文本单元的发音。 因此, 该文本单元在该语音 信息中对应的开始时间具体是该文本单元对应的语音词在该语音信息中对应的开始 时间 (例如发音的开始时刻) , 该文本单元在该语音信息中对应的结束时间具体是该 文本单元对应的语音词在该语音信息中对应的结束时间 (例如发音的结束时刻) 。
5105、 根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语音 单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模 型。 具体的, 在本实施例中, 可以预先标注该文本信息中的每个文本单元对应的语音 单元在该语音信息中的位置。 进一步, 根据第一机器学习模型预测出的文本信息中每 个文本单元在所述语音信息中对应的时间信息、 以及预先标注该文本信息中的每个文 本单元对应的语音单元在该语音信息中的位置, 构建第一损失函数, 然后根据该第一 损失函数对该第一机器学习模型进行预训练。 例如, 本实施例中的文本信息是 “他们赢了五把”, 语音信息是 “他们赢了五把" 的语音。 在本实施例中, 可以预先标注该文本信息中的每个文本单元对应的语音单元 在该语音信息中的位置。 例如, 该文本信息包括 ' '他 " 、 "们” 、 "赢 " 、 "了 " 、 “五把” 这 5个文本单元。 该语音信息包括 “他” 、 “们” 、 “赢” 、 “了 ” 、 “五
把”分别对应的语音词, 该语音词记为语音单元, 例如, “他 ”对应的语音词是' '他” 的发音。 本实施例可以预先标注 “他” 对应的语音词在该语音信息中的开始位置 (例 如开始时间或开始时刻) 和结束位置 (例如结束时间或结束时刻) 。 同理, 可以预先 标注 “们” 、 “赢” 、 “了 ” 、 “五把 ” 分别对应的语音词在该语音信息中的开始位 置和结束位置。 进一步, 根据第一机器学习模型预测出的 “他” 、 “们” 、 “赢” 、 “了 ”、 “五把 ”分别在该语音信息中的开始时间和结束时间、 以及预先标注的“他”、 "们 " 、 "赢 " 、 "了 ” 、 “五把" 分别在该语音信息中的开始位置和结束位置, 构 建第一损失函数。 具体的, 根据第一机器学习模型预测出的 “他 " 、 “们 " 、 “赢” 、 “了 ” 、 “五 把”分别在该语音信息中的开始时间、 以及预先标注的“他”、 "们”、 "赢 "、 "了 "、 “五把 ” 分别对应的语音词在该当前语音中的开始位置, 计算第一差值。 根据第一机 器学习模型预测出的 “他 " 、 "们 " 、 "赢” 、 “了 ” 、 “五把" 疗别在该语音信息 中的结束时间、 以及预先标注的 “他” 、 “们” 、 “赢” 、 “了 ” 、 “五把 ” 分别对 应的语音词在该当前语音中的结束位置, 计算第二差值。 进一步, 根据第一差值和第 二差值构建第一损失函数。 并根据该第一损失函数对第一机器学习模型进行预训练, 得到预训练模型。 本公开实施例通过获取语音信息、 以及所述语音信息对应的文本信息, 并分别对 所述文本信息和所述语音信息进行编码,得到文本编码信息和语音编码信息。进一步, 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码信息, 根据所述融合处理后的编码信息, 预测所述文本信息中每个文本单元在所述语音信息 中对应的时间信息, 然后根据所述预测的时间信息、 以及所述文本信息中每个文本单 元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模型。 使得预训练模型可以将语音信息和文本信息在时序上进行对齐, 例 如, 文本信息中更细粒度的文本单元与语音信息中更细粒度的语音单元之间的对齐, 从而提高预训练模型对语音信息和文本信息的理解力, 从而提高预训练模型对用户话 语理解的精准度。 如图 3所示为第一机器学习模型的结构示意图。 具体的, 该第一机器学习模型包 括文本编码器、语音编码器、模态融合层。下面结合图 3对预训练方法进行详细介绍。 具体的, 第一机器学习模型的输入包括文本信息和语音信息, 即第一机器学习模 型的输入是多模态信息。 可选的, 所述语音信息包括历史语音和当胡语音, 所述文本 信息包括历史文本和当前文本。 也就是说, 对于每一种模态的信息而言, 均包括历史 信息和当前信息。 例如, 当该语音信息是用户与智能对话系统之间的语音对话时, 随 着时间的增加, 对话内容在不断的增加, 因此, 在对话过程中, 有些语音可作为历史 语音, 有些语音可作为当前语音。 同理, 由于文本信息是该语音对话的文本转写, 因 此, 文本信息中有些句子可作为历史文本, 有些句子可作为当前文本。 如图 4所示为用户与智能对话系统之间的对话示意图。 假设图 4所示的对话内容 是文本转写。 用户说的每句话的文本转写可记为一轮文本, 智能对话系统说的每句话 的文本转写可记为一轮文本,因此,如图 4所示的对话内容是 8轮文本,即 " AAAAAA"、
“BBBBBB" 、 “CCCC" 、 “DDDD" 、 "EEEEEE" 、 “FFFFFF" 、 “ GGGGG" 、
“HHHHH” 分别是一轮文本。 另外, 本实施例可以将该 8轮文本中的前 7轮文本记 为历史文本, 最后 1轮文本即文本 "HHHHH" 记为当前文本。 同理, 由于 8轮文本 中的每轮文本对应一个语音, 且一个语音记为一轮语音, 因此, 8轮文本对应有 8轮 语音, 该 8轮语音中的前 7轮语音记为历史语音, 最后 1轮语音即 ''HHHHH” 对应 的语音记为当前语音。 此外, 暮一轮语音的最大长度可以是 10秒。 由于文本信息和语音信息是两种不同模态的信息, 因此, 同一轮数的文本和同一 轮数的语音所占的存储空间可能是不同的, 例如, 同一轮数的语音所占的存储空间可
能更大, 因此, 可以将同一轮数的文本和同一轮数的语音作为第一机器学习模型的输 入, 或者将第一轮数的文本和第二轮数的语音作为第一机器学习模型的输入, 此处第 一轮数大于第二轮数。 例如, 在本实施例中, 可以选择 8轮文本和 2轮语音作为如图 3所示的第一机器 学习模型的输入。 具体的, 该 8轮文本中包括 7轮历史文本和 1轮当前文本。 该 2轮 语音中包括 1轮历史语音和 1轮当前语音。 另外, 此处的 1轮当前文本和 1轮当前语 音是对齐的, 例如, 此处的 1轮当前文本是“ HHHHH”, 1轮当前语音是 “ HHHHH" 对应的语音。 因此, 如图 3所示的历史文本可以是此处的 7轮历史文本, 如图 3所示 的当前文本可以是此处的 1轮当前文本。 如图 3所示的历史语音可以是此处的 1轮历 史语音, 如图 3所示的当前语音可以是此处的 1轮当前语音。 即 7轮历史文本和 1轮 当前文本构成文本信息, 1轮历史语音和 1轮当前语音构成语音信息。 进一步, 通过 文本编码器对该文本信息进行编码, 得到文本编码信息; 通过语音编码器对该语音信 息进行编码, 得到语音编码信息。 如图 3所示, 为了将 7轮历史文本和 1轮当前文本进行区分, 可以在 7轮历史文 本的起始位置增加预设符号<s>, 在 7轮历史文本和 1 轮当前文本之间的位置增加预 设符号</s>o 或者, 在每相邻的两轮文本之间的位置增加预设符号</s>, 即</s>被设 置为分割每一轮文本。 同理, 可以采用类似于 vs>和 v/s>的预设符号, 将历史语音和当 前语音分割开, 或者将每一轮语音分割开。 进一步, 通过文本编码器对<s>、 如上所述的 7轮历史文本、 </s>和如上所述的 1 轮当前文本进行编码。 通过语音编码器对如上所述的 1轮历史语音和 1轮当前语音进 行编码。 例如, 对于如上所述的 7轮历史文本和 1轮当前文本而言, 每一轮文本可以是一 个句子。 每个句子由文本单元构成, 每个文本单元还可以包括至少一个编码单元。 因 此, 可以将如图 3所示的历史文本和当前文本分别分割为若干个编码单元, 例如框 31 表示任意一个编码单元。 同时, 预设符号<s〉可作为一个编码单元, 预设符号</s>可作 为一个编码单元。 如图 3 所示, 通过文本编码器对各个编码单元分别进行编码之后, 得到文本编码信息, 该文本编码信息包括各个编码单元的表示向量。 例如, 该文本编 码信息包括如图 3所示的框 32 内的各个表示向量, 框 32内的每个小框 (例如框 33) 表示一个编码单元的表示向量。 另外, 在本实施例中, 如图 3 所示的历史语音和当胡语音分别是长度为 10秒的 音频信号, 在进行编码之前, 可以将该历史语音拆分为多个语音片段, 将该当前语音 也拆分为多个语音片段, 例如, 每个语音片段的长度可以是 1秒。 如图 3所示, 通过 语音编码器对该历史语音中的每个语音片段进行编码, 以及通过语音编码器对该当前 语音中的每个语音片段进行编码, 得到语音编码信息, 该语音编码信息包括各个语音 片段的表示向量。例如,该语音编码信息包括如图 3所示的框 34内的各个表示向量, 框 34内的每个小框 (例如框 35) 表示一个语音片段的表示向量。 如图 3所示,将框 32表示的文本编码信息和框 34表示的语音编码信息进行拼接, 并将拼接后的结果作为模态融合层的输入, 使得模态融合层对文本编码信息和语音编 码信息进行融合处理, 得到融合处理后的编码信息, 该融合处理后的编码信息也可记 为联合表示向量。 例如, 该融合处理后的编码信息包括如图 3 所示的框 36 内的各个 表示向量, 框 36 内的每个小框 (例如框 37) 表示模态融合层输出的一个表示向量。 例如框 33 表示预设字符<s>的表示向量, 框 37表示模态融合层输出的第一个表示向 量, 该第一个表示向量是文本编码信息和语音编码信息的融合结果, 即该第一个表示 向量是预设字符<s>的表示向量、 历史文本中暮个编码单元的表示向量、预设字符</s> 的表示向量、 当前文本中每个编码单元的表示向量、 历史语音中每个语音片段的表示 向量、 当前语音中每个语音片段的表示向量的融合结果, 因此, 第一个表示向量中不
仅包含文本成分, 还包括语音成分。 同理, 模态融合层输出的其他表示向量均同时包 含文本成分和语音成分。 进一步, 从图 3 所示的框 36 内的各个表示向量中截取部分表示向量, 例如截取 模态融合层输出的与当前文本对应的表示向量, 即框 38内的各个表示向量。进一步, 根据框 38 内的各个表示向量, 预测当前文本中每个文本单元在当的语音中对应的时 间信息。 例如, 当前语音是一个 10 秒长的语音。 对该当前语音的长度进行归一化处 理后, 可将当前语音的开始位置记为 0, 结束位置记为 l o 如图 3 所示, 通过全连接 层 1预测该当前文本中每个文本单元在当前语音中对应的开始时间, 通过全连接层 2 预测该当前文本中每个文本单元在当前语音中对应的结束时间。 例如图 5所示, 假设 当前文本是 “他们赢了五把" , 根据模态融合层输出的与当前文本对应的表示向量, 可预测出 "他' '在当前语音中对应的开始时间 (例如 0.05)和结束时间 (例如 0.16) , “们 " 在当前语音中对应的开始时间 (例如 0.18) 和结束时间 (例如 0 32) , 依次类 推, “五把 ” 在当前语音中对应的开始时间 (例如 .067) 和结束时间 (例如 0.97) 。 例如, 当前文本和当前语音分别是样本, 因此, 可以预先标注当前文本中的每个 文本单元对应的语音单元在该语音信息中的位置。 例如, 该当前语音中包括 “他” 、 "们 " 、 "赢 " 、 “了 " 、 “五把 " 分别对应的语音词, 该语音词记为语音单元, 例 如, “他” 对应的语音词是 “他” 的发音。 本实施例可以预先标注 “他' ' 对应的语音 词在该当前语音中的开始位置 (例如开始时间或开始时刻) 和结束位置 (例如结束时 间或结束时刻) 。 同理, 可以预先标注 “们” 、 "赢 " 、 "了 " 、 “五把” 分别对应 的语音词在该当前语音中的开始位置和结束位置。进一步,根据全连接层 1预测的 “他 "、 "们 " 、 "赢 " 、 “了 " 、 “五把" 分别在当衬语音中对应的开始时间、 以及预先标 注的 “他” 、 “们” 、 “赢” 、 “了 ” 、 “五把” 分别对应的语音词在该当前语音中 的开始位置, 构建第一差值。 根据全连接层 2预测的 “他"、 "们 "、 "赢 "、 “了 ”、 “五把 ”分别在当前语音中对应的结束时间、 以及预先标注的“他”、 “们”、 “赢”、 “了 ” 、 “五把 ” 分别对应的语音词在该当前语音中的结束位置, 构建第二差值。 进 一步, 根据第一差值和第二差值构建第一损失函数, 通过该第一损失函数对如图 3所 示的第一机器学习模型进行预训练, 得到预训练模型。 在上述实施例中, 所述融合处理后的编码信息包括所述各个编码单元分别对应的 融合表示向量、 以及所述各个语音片段分别对应的融合表示向量; 根据所述融合处理 后的编码信息, 预测所述文本信息中每个文本单元在所述语音信息中对应的时间信息, 包括:若所述文本单元包括一个编码单元, 则根据所述编码单元对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间和结束时间; 若所述文本单元包 括多个编码单元, 则根据所述多个编码单元中第一个编码单元对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间, 以及根据所述多个编码单元中 最后一个编码单元对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的 结束时间。 如图 6 所示, 模态融合层输出的各个融合表示向量中包括预设字符 vs>对应的融 合表示向量、 历史文本中各个编码单元分别对应的融合表示向量、 预设字符</s>对应 的融合表示向量、 当前文本中各个编码单元分别对应的融合表示向量、 以及各个语音 片段分别对应的融合表示向量。 具体的, 如果历史文本有 8轮, 历史语音有 8轮, 并 且 8轮历史文本和 8轮历史语音是 —对齐的, 那么根据历史文本中各个编码单元分 别对应的融合表示向量, 可以预测历史文本中每个文本单元在历史语音中对应的时间 信息。 例如, 根据第 1轮历史文本中各个编码单元分别对应的融合表示向量, 预测该 第 1轮历史文本中每个文本单元在第 1轮历史语音中对应的开始时间和结束时间, 依 此类推, 预测该第 8轮历史文本中每个文本单元在第 8轮历史语音中对应的开始时间 和结束时间。 另外, 由于当前文本和当前语音是对齐的, 因此, 可以根据当前文本中
各个编码单元分别对应的融合表示向量, 预测当前文本中每个文本单元在当前语音中 对应的开始时间和结束时间。 例如, 当前文本是 "他们赢了五把”, “他 " 、 "们 " 、 "赢 " 、 "了 "、 “五” 、 “把 ”分别是编码单元。 模态融合层输出的各个融合表示向量中包括“他”、 “们”、 “嬴 " 、 “了 ” 、 “五” 、 “把" 分别对应的融合表示向量。 例如图 6所示的 A表示 “他 ”对应的融合表示向量,依次类推, F表示 “把 ”对应的融合表示向量。由于 “他”、 "们 "、 "赢 "、 "了' '分别是文本单元, 并且该文本单元包括一个编码单元, 例如, “他” 是一个文本单元, 并且该文本单元包括一个编码单元, 该编码单元是 “他” , 即 ' '他" 既是一个文本单元, 也是该文本单元中包括的一个编码单元, 因此, 可以根 据 “他” 对应的融合表示向量 A, 预测 "他" 在当前语音中对应的开始时间和结束时 间。 例如图 6所示的全连接层 1包括参数 Wstart , 全连接层 2包括参数 Wend, 由全连接 层 1预测的 “他”在当前语音中对应的开始时间记为 WstartA ,由全连接层 2预测的' '他 " 在当前语音中对应的结束时间记为 WendA.同理,全连接层 1还可以预测出 “们”、“赢 ”、 “了 ”分别在当前语音中对应的开始时间, 全连接层 2还可以预测出 “们 "、 "赢 "、 “了 ” 分别在当前语音中对应的结束时间。 另外, 由于 “五把 "是文本单元, 但是该文本单元包括多个编码单元, 例如 “五" 是该文本单元中的第一个编码单元, “把 ” 是该文本单元中的最后一个编码单元。 因 此, 根据第一个编码单元对应的融合表示向量, 可预测 "五把" 在当前语音中对应的 开始时间, 以及根据最后一个编码单元对应的融合表示向量, 可预测 “五把" 在当前 语音中对应的结束时间。 例如, “五 ” 对应的融合表示向量记为 E, “把 ” 对应的融 合表示向量记为 F, 则由全连接层 1预测的 “五把” 在当衬语音中对应的开始时间记 为 WstartE, 由全连接层 2预测的 "五把” 在当前语音中对应的结束时间记为 WendF。 例 如图 5所示为全连接层 1预测出的各个文本单元的开始时间、 以及全连接层 2预测出 的各个文本单元的结束时间。 可选的, 根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语 音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 包括: 根据 所述文本单元在所述语音信息中对应的开始时间和结束时间, 以及预先标注的所述文 本单元对应的语音单元在所述语音信息中的开始位置和结束位置, 构建第一损失函数 ; 根据所述第一损失函数, 对第一机器学习模型进行预训练。 可选的, 所述第一损失函 数包括第一差值和第二差值, 所述第一差值是根据所述开始时间和所述开始位置得到 的差值, 所述第二差值是根据所述结束时间和所述结束位置得到的差值。 例如图 7所示, 当前语音的时长是 10秒, 即当前语音从第 0秒开始、 在第 10秒 结束。 本实施例可以预先标注当前文本例如 “他们赢了五把” 中各个文本单元对应的 语音单元在该当前语音中的开始位置和结束位置。 例如, "他" 对应的语音单元在该 当前语音中的开始位置是第 0.6秒、 结束位置是 1.7秒, 依此类推, “五把” 对应的 语音单元在该当前语音中的开始位置是第 6.9秒、 结束位置是第 9.9秒。 由于如上所述的全连接层 1 预测的开始时间和全连接层 2 预测的结束时间均是 0-1 之间的数值, 因此, 为了与该 0-1 之间的数值进行数量级上的匹配, 本实施例可 以对当前语音的时长进行归一化处理, 例如, 将当胡语音的时长归一化为 1秒, 即将 该当前语音的开始位置归一化为第 。秒, 将该当前语音的结束位置归一化为第 1 秒。 从而使得 “他们赢了五把” 中各个文本单元对应的语音单元在该当前语音中的开始位 置和结束位置均被归一化, 例如, 经过归一化处理后, “他 ” 对应的语音单元在该当 前语音中的开始位置是第 0.06秒、 结束位置是第 0.17秒, 依此类推, “五把 ” 对应 的语音单元在该当前语音中的开始位置是第 0.69秒、 结束位置是第 0.99秒。 也就是 说, 在归一化处理的过程中, 统一除以当前语音的时长 (例如 10秒) 。 如图 7所示, 针对当前文本中的同一个文本单元, 例如 “他” , 全连接层 1预测
的 “他” 在当前语音中对应的开始时间是 0.05 , 而预先标注的 "他” 对应的语音单元 在该当前语音中的开始位置是第 0.06秒,即该开始时间和该开始位置之间存在一定的 差值, 该差值记为第一差值。 同时, 全连接层 2预测的 “他 ” 在当前语音中对应的结 束时间是 0.16, 而预先标注的 “他” 对应的语音单元在该当前语音中的结束位置是第 0.17秒, 即该结束时间和该结束位置之间存在一定的差值, 该差值记为第二差值。 另 外,对于当前文本中的其他文本单元而言,也存在类似的第一差值和第二差值。此外, 本实施例是以预测当前文本中各个文本单元的开始时间和结束时间为例进行的示意 性说明, 在其他实施例中, 还可以预测历史文本中每个文本单元在历史语音中对应的 时间信息。 例如, 根据第 1轮历史文本中各个编码单元分别对应的融合表示向量, 预 测该第 1轮历史文本中每个文本单元在第 1轮历史语音中对应的开始时间和结束时间, 依此类推, 预测该第 8轮历史文本中每个文本单元在第 8轮历史语音中对应的开始时 间和结束时间。 因此, 对于每轮历史文本中的各个文本单元而言, 也存在类似的第一 差值和第二差值。 因此, 本实施例可以基于多轮文本 (包括历史文本和当前文本) 中各个文本单元 分别对应的第一差值和第二差值构建第一损失函数。 进一步, 根据该第一损失函数对 如图 3所示的第一机器学习模型进行预训练。 例如, 该第一损失函数£奶户可表示为如 下公式:
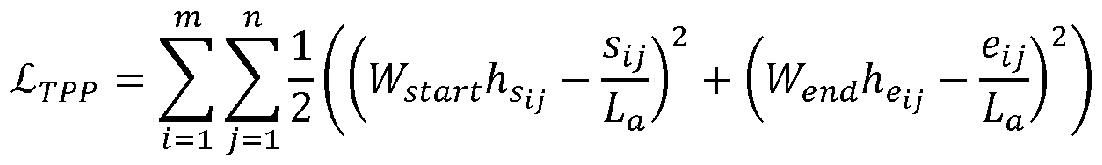 其中, 该第一损失函数使用均方误差 (Mean Squared Error, MSE) , 即预测结果 (例如预测的开始时间或结束时间) 与真实位置 (例如预先标注的开始位置或结束位 置) 的差的平方。 i表示第 i轮文本, m表示文本的轮数或个数。 j表示第 i轮文本中的第 j个文本单元, 例如第/个词。 n表示第 i轮文本中包括的词的个数。 必血代表示全连接层 1 包括的参数, "md表示全连接层 2 包括的参数, 为 j表示第,轮文本中第 j个文本单元 中第一个编码单元对应的融合表示向量, 姐,表示第 i轮文本中第 j ,个文本单元中最后一 个编码单元对应的融合表示向量。如果第 /个文本单元包括一个编码单元, 则此处的第 一个编码单元和最后一个编码单元是同一个编码单元, 即 /I’汀和九即相同。 如果第 j个文 本单元包括多个编码单元, 则此处的第一个编码单元和最后一个编码单元不同, 即么寸 和姐/不同。 可以理解的是, 在预训练的过程中, 呢也汗和 "end分别是待训练的参数。 Wstarths.表示全连接层 1预测的第 i轮文本中第 j个文本单元在第 i轮语音中的开始时间, Wendheij表示全连接层 2 预测的第 i轮文本中第 J个文本单元在第 i轮语音中的结束时间。 S ”表示归一化之前, 预先标注的第 i轮文本中第 j个文本单元在第 i轮语音中的开始位置, ⑶表示归一化之前, 预先标注的第 i轮文本中第 j个文本单元在第 i轮语音中的结束位置。 垢表示第 Z轮语音的时长, 或者表示多轮语音中的最大时长, 垢被设置为进行如上所述
的归一化处理。 另外, 根据该第一损失函数对如图 3或图 6所示的第一机器学习模型进行预训练 时, 可以对如图 3或图 6所示的各个待训练结构, 例如文本编码器、 语音编码器、 模 态融合层、 全连接层 1、 全连接层 2 中的参数进行迭代更新, 直到迭代次数达到预设 次数, 或者参数收敛。 例如, 根据该第一机器学习模型输出的预测结果和预先标注的真实位置之间的相 似度或差值, 调整如图 3或图 6所示的各个待训练结构中的参数, 使得该第一机器学 习模型输出的预测结果和预先标注的真实位置在后续的迭代训练过程中逐渐的相似 O 示例性地, 可根据该第一机器学习模型输出的预测结果和预先标注的真实位置之间的 梯度数据, 引导参数调整。 其中, 梯度的本意是一个向量 (矢量) , 表示某一函数在 该点处的方向导数沿着该方向取得最大值, 即函数在该点处沿着该方向 (此梯度的方 向) 变化最快, 变化率最大。 也正是基于此原理, 可以引导参数的调整方向, 使得该 第一机器学习模型输出的预测结果向预先标注的真实位置靠近。 如上所述, 对第一机器学习模型进行预训练时采用的样本数据包括文本信息和语 音信息。 例如, 该文本信息包括 7轮历史文本和 1轮当前文本, 该语音信息包括 1轮 历史语音和 1轮当前语音, 且 7轮历史文本和 1轮当前文本是同一对话中连续的 8个 句子, 同理 1轮历史语音和 1轮当前语音是该同一对话中连续的 2个语音。 即 7轮历 史文本和 1轮当前文本之间存在连贯的语义, 1轮历史语音和 1轮当前语音之间存在 连贯的语义。在其他实施例中,根据该样本数据可以衍生出另外三种样本数据,例如, 将该样本数据中的 1轮当前文本替换为其他对话中的一个句子后得到第一种衍生的样 本数据, 从而导致 7轮历史文本和 1轮当前文本之间的语义不再连贯, 但 1轮历史语 音和 1轮当前语音之间保留连贯的语义。 再例如, 将该样本数据中的 1轮当前语音替 换为其他对话中的一个语音后得到第二种衍生的样本数据, 从而导致 1轮历史语音和 1轮当前语音之间的语义不再连贯, 但 7轮历史文本和 1轮当前文本之间保留连贯的 语义。 叉例如, 将该样本数据中的 1轮当前文本替换为其他对话中的一个句子、 且将 该样本数据中的 1轮当前语音替换为其他对话中的一个语音后得到第三种衍生的样本 数据, 从而导致 7轮历史文本和 1轮当前文本之间的语义不再连贯, 1轮历史语音和 1 轮当前语音之间的语义也不再连贯。 如果将原始的样本数据记为如图 8所示的标签 (Label) 为 0的样本数据, 那么根据该原始的样本数据衍生出的另外三种样本数据, 依次是图 8所示的 Label为 1、 Label为 2、 Label为 3的样本数据。 其中, QueryJ表 示历史文本, Queryl表示当前文本, Query 表示历史语音, Query?表示当前语音, Query妇 "表示替换成其他句子之后的当前文本, Query^and表示替换成其他语音之后的 当前语音。 在对第一机器学习模型进行预训练的过程中, 该预训练方法还包括如图 9所示的 如下几个步骤:
S901、 根据所述融合处理后的编码信息, 判断所述历史语音和所述当前语音是否 匹配, 得到第一判断结果, 以及判断所述历史文本和所述当前文本是否匹配, 得到第 二判断结果。 本实施例可以将 Label为 0、 Label为 1、 Label为 2、 或 Label为 3的样本数据作
 果。 可以理解的是, 如果当前文本是 Queryl , 那么历史文本和当前文本匹配, 即历史 文本和当前文本之间的语音是连贯的, 历史文本和当前文本在语义内容上具有明显的 上下文关联性, 此时的历史文本和当前文本是同一对话中的上下文。 如果当前文本是 Query^and , 那么历史文本和当前文本不匹配, 即历史文本和当前文本不是同一对话中 的上下文。 同理, 如果当前语音是 Query ( , 那么历史语音和当前语音匹配, 即历史语 音和当前语音之间的语音是连贯的, 历史语音和当前语音在语义内容上具有明显的上 下文关联性, 此时的历史语音和当前语音是同一对话中的上下文。 如果当前语音是 Query舄燮 那么历史语音和当前语音不匹配, 即历史语音和当前语音不是同一对话中 的上下文。 因此, 如上所述的第一判断结果有两种结果, 一种结果是历史语音和当前语音匹 配, 另一种结果是历史语音和当前语音不匹配。 同理, 第二判断结果也有两种结果, 一种结果是历史文本和当前文本匹配, 另一种结果是历史文本和当前文本不匹配。
5902、 根据所述第一判断结果和所述第二判断结果, 预测输入样本的类型, 所述 输入样本包括所述语音信息和所述文本信息。 例如, 全连接层 3 可以根据第一判断结果和第二判断结果预测输入样本的类型, 例如, 若第一判断结果表示历史语音和当前语音匹配, 第二判断结果表示历史文本和 当前文本匹配, 则全连接层 3预测输入样本是 Label为 0的样本。 若第一判断结果表 示历史语音和当前语音匹配, 第二判断结果表示历史文本和当前文本不匹配, 则全连 接层 3预测输入样本是 Label为 1 的样本。 若第一判断结果表示历史语音和当前语音 不匹配, 第二判断结果表示历史文本和当前文本匹配, 则全连接层 3预测输入样本是 Label 为 2 的样本。 若第一判断结果表示历史语音和当前语音不匹配, 第二判断结果 表示历史文本和当前文本不匹配, 则全连接层 3预测输入样本是 Label为 3的样本。 即全连接层 3可以根据第一判断结果和第二判断结果预测输入样本是 Label为 0、 Label 为 1、 Label为 2、 或 Label为 3 中的哪一种样本。 在一种可能的实现方式中, 全连接层 3可以直接输出其预测得到的输入样本的类 型, 例如, Label=O、 Label=l、 Label=2、 或 L abel=3。 在另一种可能的实现方式中, 全连接层 3 可以是一个四分类任务, 即全连接层 3 的输出可以是 4个概率值,该 4个概率值依次表示输入样本的类型是 Label为 0, Label 为 1 , Label为 2、 Label为 3 的概率。 进一步, 将该 4个概率值中最大概率值对应的 类型作为全连接层 3预测出的输入样本的类型。
5903、 根据所述预测的输入样本的类型、 以及预先标注的所述输入样本的类型, 构建第二损失函数, 并根据所述第二损失函数对所述第一机器学习模型进行预训练。 本实施例还可以预先标注输入样本中的历史语音和当前语音实际是否构成上下文信 息、 以及预先标注输入样本中的历史文本和当前文本实际是否构成上下文信息。 即本 实施例可以预先标注输入样本实际的类型, 即预先标注输入样本是 L abel为 0、 Label 为 1、 Label为 2、 或 Label为 3 中的哪一种样 ■本。 进一步, 本实施例可以根据全连接层 3预测的输入样本的类型、 以及预先标注的 输入样本实际的类型, 构建第二损失函数, 该第二损失函数可以是分类的交叉炳损失 函数。进一步,根据该第二损失函数对如图 10所示的第一机器学习模型进行预训练。 本实施例通过所述融合处理后的编码信息, 判断所述历史语音和所述当前语音是 否匹配, 得到第一判断结果, 以及判断所述历史文本和所述当前文本是否匹配, 得到 第二判断结果。 使得第一机器学习模型可以根据第一判断结果和第二判断结果预测输 入样本的类型。 另外, 根据所述历史语音和所述当前语音实际是否构成上下文信息、 以及所述历史文本和所述当前文本实际是否构成上下文信息, 预先标注输入样本的类 型。 从而根据预先标注的输入样本的类型、 以及第一机器学习模型预测的输入样本的
类型, 构建第二损失函数,并根据第二损失函数对所述第一机器学习模型进行预训练, 得到预训练模型。 使得预训练模型可以识别上下文信息, 有利于提高预训练模型对用 户意图的识别、 情感分析等的精准度。 可以理解的是, 本实施例可以根据第一损失函数或第二损失函数单独对第一机器 学习模型进行预训练, 或者可以根据第一损失函数和第二损失函数联合对第一机器学 习模型进行预训练。 此外, 对第一机器学习模型进行预训练的任务除了如上所述的时 序预测任务 (例如预测文本单元在语音中的开始时间和结束时间) 、 跨模态对话回复 选择任务 (例如预测输入样本的类型) 之外, 还可以通过其他任务来进行预训练。 例 如, 还可以通过掩码预测任务来对第一机器学习模型进行预训练。 例如, 本实施例可 以对历史文本或当前文本中的部分词进行掩码, 和 /或, 对历史语音或当前语音中的部 分语音片段进行掩码。 然后将掩码之后的样本输入到第一机器学习模型中, 进一步, 根据模态融合层输出的融合表示向量来预测被掩盖的部会词和 /或部分语音。从而根据 预测出的被掩盖的部分词和/或部分语音、 以及实际被掩盖的部分词和/或部分语音构 建第三损失函数, 并根据该第三损失函数对第一机器学习模型进行预训练。 从而利用 不同的模态信息, 例如, 文本和语音, 建模文本和语音两种模态的互动。 可以理解的是, 对第一机器学习模型进行预训练之后可以得到预训练模型, 该预 训练模型可作为模型基础, 进一步采用下游任务的样本数据, 对该预训练模型进行训 练或微调, 得到训练后的机器学习模型, 从而使得训练后的机器学习模型可以执行下 游任务。 图 1 1 为本公开另一实施例提供的机器学习模型训练方法流程图。 该机器学习模 型训练方法可以是对该预训练模型进行训练或微调的方法。 在本实施例中, 该方法具 体步骤如下:
S1101、 获取目标任务的样本数据, 所述样本数据包括待处理数据和所述待处理 数据的标注结果, 所述待处理数据包括样本语音、 以及所述样本语音对应的样本文本。 例如, 该预训练模型可以保留在服务器 22中, 进一步, 服务器 22可以对该预训 练模型进行训练或微调。 具体的, 服务器 22 可以获取目标任务的样本数据, 该目标 任务可以是如上所述的下游任务, 该样本数据包括待处理数据和该待处理数据的标注 结果, 该待处理数据包括样本语音、 以及该样本语音对应的样本文本。 该待处理数据 的标注结果是根据该样本语音和/或样本文本, 预先标注的用户情感类别、 用户情绪类 别、 用户意图、 或该样本语音或样本文本中的关键信息。 可选的, 所述目标任务包括如下至少一种: 情感分析任务、 情绪识别任务、 意图 分析任务、 关键信息收集任务。 例如, 当目标任务是情感分析任务时,服务器 22获取的样本数据包括样本语音、 该样本语音对应的样本文本、 以及预先标注的该样本语音或样本文本对应的用户情感 类别。 具体的, 样本文本中包括历史文本和当前文本, 样本语音中包括历史语音和当 前语音。
S1 102、 将所述待处理数据输入到第二机器学习模型中, 使得所述第二机器学习 模型输出处理后的结果, 所述第二机器学习模型是根据如上所述的预训练方法得到的 预训练模型。 例如, 将该历史文本、 当前文本、 历史语音和当前语音输入到第二机器学习模型 即预训练模型中, 使得该预训练模型中的文本编码器、 语音编码器、 模态融合层对该 预训练模型的输入进行处理, 并根据模态融合层输出的融合表示向量 (例如第一个融 合表示向量) 预测该样本语音或样本文本对应的用户情感类别。 该用户情感类别可作 为该预训练模型输出的处理结果。
S 1 103、 根据所述第二机器学习模型输出的处理后的结果、 以及所述待处理数据 的标注结果, 对所述第二机器学习模型进行训练, 得到训练后的机器学习模型。
例如, 根据该预训练模型预测的该样本语音或样本文本对应的用户情感类别、 以 及预先标注的该样本语音或样本文本对应的用户情感类别, 对该预训练模型进行训练 或微调, 从而得到训练后的机器学习模型。 同理, 可以采用情绪识别任务、 意图分析任务、 或关键信息收集任务的样本数据 对该预训练模型进行训练或微调。 可以理解的是, 本实施例可以通过情感分析任务、 情绪识别任务、 意图分析任务或关键信息收集任务单独对该预训练模型进行训练或微 调。 或者, 通过情感分析任务、 情绪识别任务、 意图分析任务和关键信息收集任务联 合对该预训练模型进行训练或微调。 此外, 不限于如上所述的几种任务对该预训练模 型进行训练或微调, 例如, 还可以采用其他任务, 对该预训练模型进行训练或微调。 例如, 样本语音是用户和智能对话系统之间的对话, 在对话过程中, 用户和智能 对话系统可能谈论一些关键信息。 例如, 在订机票的场景下, 智能对话系统可能会问 用户需要哪天哪个时间的机票、 哪种类型的机票 (例如打折机票、 非打折机票) 等。 而哪天哪个时间、 哪种类型等均是关键信息。 因此, 本实施例可以通过该预训练模型 预测出的关键信息和预先标注的关键信息, 对该预训练模型进行训练或微调。 可以理解的是, 根据情感分析任务、 情绪识别任务、 意图分析任务和 /或关键信息 收集任务对该预训练模型进行训练或微调时, 可以在该预训练模型中部署新的全连接 层, 而不需要如上所述的全连接层 1、 全连接层 2、 全连接层 3等。 本实施例首次在对话场景下, 基于语音语义进行联合建模, 根据语音的时序性特 征, 通过时序预测任务对第一机器学习模型进行预训练, 并引入了跨模态对话回复选 择任务对第一机器学习模型进行预训练。 使得经过预训练后得到的预训练模型, 不仅 可以将语音信息和文本信息在时序上进行对齐, 还可以识别上下文信息。 经过实验证 明, 本实施例提供的方案比已有的语音语义建模方法有 5-20个百分点的提升, 能够更 准确地理解用户的话语, 提升用户体验。 因此, 在使用中, 本实施例所述的方案不仅 能学到更细粒度更准确的语音文本对齐, 还可以捕捉到更多的语音信息, 更好地帮助 系统理解用户意图, 提升用户体验。 另外, 本实施例所述的方法比纯文本模型和纯语音模型都有所提升, 其中比语音 模型提升的更多一些, 说明我们的模型很好地促成了语音语义的联合建模。 并且, 我 们的方法相对已有最优的语音语义联合建模预训练方法提升是巨大的, 即使是非预训 练的方法, 我们也在所有任务上都比各自的当前最先进的 (state of the art, SOTA)方法 提升了 1 个百分点以上, 在多模态分析数据集 (Multimodal Dataset, MOSI) 上更是 取得了 3」个百分点的提升。 此外,在公开的数据集上, 与纯文本方法相比, 本方案在准确率上可以实现 10.1% 的提升, 即使与目前最先进的多模态方法相比, 也可以实现 5-6%的提升。 图 12 为本公开另一实施例提供的智能对话方法流程图。 该方法可以由云端服务 器来执行, 例如, 该云端服务器中部署有如上所述的经过训练或微调之后的机器学习 模型, 该云端服务器可以通过该训练或微调之后的机器学习模型来实现本实施例所述 的智能对话方法。 在本实施例中, 该方法具体步骤如下:
S1201、 获取目标用户和智能对话系统之间的历史对话, 以及所述历史对话对应 的文本信息。 例如, 该云端服务器中可以预先部署有智能对话系统, 该云端服务器可以获取目 标用户和智能对话系统之间的历史对话, 以及该历史对话对应的文本信息。
S1202、 将所述历史对话和所述文本信息输入到训练后的机器学习模型中, 使得 所述机器学习模型输出所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 所述机器学习模型是根据如上所述的方法训练得到的。 例如, 该云端服务器可以将该历史对话和该文本信息输入到经过训练或微调之后 的机器学习模型中, 使得该机器学习模型输出该目标用户的情感、 情绪、 意图、 关键
信息中的至少一种。
S1203、 根据所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 与所 述目标用户进行智能对话。 例如, 该云端服务器可以根据该目标用户的情感、 情绪、 意图、 关键信息中的至 少一种, 与所述目标用户进行智能对话。 例如, 如果历史对话中的最后一句话是目标 用户的提问, 则该云端服务器可以根据该目标用户的情感、 情绪、 意图、 关键信息中 的至少一种, 生成该提问的回复信息, 并将该回复信息反馈给该目标用户的终端。 如 果历史对话中的最后一句话是智能对话系统的回复, 则该云端服务器可以根据该目标 用户的情感、 情绪、 意图、 关键信息中的至少一种, 生成问句, 并将问句反馈给该目 标用户的终端, 从而使得该目标用户和该云端服务器中的智能对话系统继续进行对话。 本实施例通过获取目标用户和智能对话系统之间的历史对话, 以及所述历史对话 对应的文本信息, 并将历史对话和所述文本信息输入到训练后的机器学习模型中, 使 得该机器学习模型输出所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种。 从而提高了机器学习模型理解目标用户的精准度。进一步,根据所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 与所述目标用户进行智能对话。 使得该机器学 习模型在精准理解目标用户的基础上, 可以与目标用户进行精准的对话。 图 13 为本公开实施例提供的机器学习模型训练装置的结构示意图。 本公开实施 例提供的机器学习模型训练装置可以执行机器学习模型训练方法实施例提供的处理 流程, 如图 13所示, 机器学习模型训练装置 130包括: 获取模块 131 , 被设置为获取语音信息、 以及所述语音信息对应的文本信息; 编码模块 132, 被设置为分别对所述文本信息和所述语音信息进行编码, 得到文 本编码信息和语音编码信息; 融合处理模块 133 , 被设置为对所述文本编码信息和所述语音编码信息进行融合 处理, 得到融合处理后的编码信息; 预测模块 134, 被设置为根据所述融合处理后的编码信息中与所述文本信息对应 的编码信息, 预测所述文本信息中每个文本单元在所述语音信息中对应的时间信息; 预训练模块 135 , 被设置为根据所述预测的时间信息、 以及所述文本信息中每个 文本单元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预 训练。 可选的, 编码模块 132分别对所述文本信息和所述语音信息进行编码, 得到文本 编码信息和语音编码信息时, 具体被设置为: 通过文本编码器对所述文本信息中每个文本单元分别包括的至少一个编码单元 进行编码, 得到文本编码信息, 所述文本编码信息包括各个编码单元的表示向量; 通过语音编码器对所述语音信息中的每个语音片段进行编码, 得到语音编码信息, 所述语音编码信息包括各个语音片段的表示向量。 可选的, 所述融合处理后的编码信息包括所述各个编码单元分别对应的融合表示 向量、 以及所述各个语音片段分别对应的融合表示向量; 预测模块 134根据所述融合处理后的编码信息, 预测所述文本信息中每个文本单 元在所述语音信息中对应的时间信息时, 具体被设置为: 若所述文本单元包括一个编码单元, 则根据所述编码单元对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间和结束时间; 若所述文本单元包括多个编码单元, 则根据所述多个编码单元中第一个编码单元 对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间, 以及根 据所述多个编码单元中最后一个编码单元对应的融合表示向量, 预测所述文本单元在 所述语音信息中对应的结束时间。 可选的, 预训练模块 135根据所述预测的时间信息、 以及所述文本信息中每个文
本单元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训 练时, 具体被设置为: 根据所述文本单元在所述语音信息中对应的开始时间和结束时间, 以及预先标注 的所述文本单元对应的语音单元在所述语音信息中的开始位置和结束位置, 构建第一 损失函数; 根据所述第一损失函数, 对第一机器学习模型进行预训练。 可选的, 所述第一损失函数包括第一差值和第二差值, 所述第一差值是根据所述 开始时间和所述开始位置得到的差值, 所述第二差值是根据所述结束时间和所述结束 位置得到的差值。 可选的, 所述语音信息包括历史语音和当前语音, 所述文本信息包括历史文本和 当前文本; 模型预训练装置 130还包括: 判断模块 136, 被设置为根据所述融合处理 后的编码信息, 判断所述历史语音和所述当前语音是否匹配, 得到第一判断结果, 以 及判断所述历史文本和所述当前文本是否匹配, 得到第二判断结果; 预训练模块 135 还被设置为根据所述第一判断结果和所述第二判断结果, 预测输入样本的类型, 所述 输入样本包括所述语音信息和所述文本信息; 根据所述预测的输入样本的类型、 以及 预先标注的所述输入样本的类型, 构建第二损失函数, 并根据所述第二损失函数对所 述第一机器学习模型进行预训练, 得到预训练模型。 图 13所示实施例的模型预训练装置可被设置为执行上述方法实施例的技术方案, 其实现原理和技术效果类似, 此处不再赘述。 图 14 为本公开实施例提供的机器学习模型训练装置的结构示意图。 本公开实施 例提供的机器学习模型训练装置可以执行机器学习模型训练方法实施例提供的处理 流程, 如图 14所示, 机器学习模型训练装置 140包括: 获取模块 141 , 被设置为获取目标任务的样本数据, 所述样本数据包括待处理数 据和所述待处理数据的标注结果, 所述待处理数据包括样本语音、 以及所述样本语音 对应的样本文本; 输入模块 142, 被设置为将所述待处理数据输入到第二机器学习模型中, 使得所 述第二机器学习模型输出处理后的结果, 所述第二机器学习模型是根据如上所述的预 训练方法得到的预训练模型; 训练模块 143 , 被设置为根据所述第二机器学习模型输出的处理后的结果、 以及 所述待处理数据的标注结果, 对所述第二机器学习模型进行训练, 得到训练后的机器 学习模型。 可选的, 所述目标任务包括如下至少一种: 情感分析任务、 情绪识别任务、 意图分析任务、 关键信息收集任务。 图 14 所示实施例的模型训练装置可被设置为执行上述方法实施例的技术方案, 其实现原理和技术效果类似, 此处不再赘述。 图 15 为本公开实施例提供的智能对话装置的结构示意图。 本公开实施例提供的 智能对话装置可以执行智能对话方法实施例提供的处理流程, 如图 15 所示, 智能对 话装置 150包括: 获取模块 151 , 被设置为获取目标用户和智能对话系统之间的历史对话, 以及所 述历史对话对应的文本信息; 输入模块 152, 被设置为将所述历史对话和所述文本信息输入到训练后的机器学 习模型中, 使得所述机器学习模型输出所述目标用户的情感、 情绪、 意图、 关键信息 中的至少一种, 所述机器学习模型是根据如上所述的方法训练得到的; 对话模块 153 , 被设置为根据所述目标用户的情感、 情绪、 意图、 关键信息中的 至少一种, 与所述目标用户进行智能对话。 图 15 所示实施例的智能对话装置可被设置为执行上述方法实施例的技术方案,
其实现原理和技术效果类似, 此处不再赘述。 以上描述了模型预训练装置、的内部功能和结构, 该装置可实现为一种电子设备。 图 16为本公开实施例提供的电子设备实施例的结构示意图。 如图 16所示, 该电子设 备包括存储器 161和处理器 162。 存储器 161被设置为存储程序。 除上述程序之外, 存储器 161还可被配置为存储 其它各种数据以支持在电子设备上的操作。 这些数据的示例包括被设置为在电子设备 上操作的任何应用程序或方法的指令, 联系人数据, 电话簿数据, 消息, 图片, 视频 等。 存储器 161 可以由任何类型的易失性或非易失性存储设备或者它们的组合实现, 如静态随机存取存储器 (SRAM), 电可擦除可编程只读存储器 (EEPROM), 可擦除可编 程只读存储器 (EPROM), 可编程只读存储器 (PROM), 只读存储器 (ROM), 磁存储器, 快闪存储器, 磁盘或光盘。 处理器 162与存储器 161耦合, 执行存储器 161所存储的程序, 以被设置为: 获取语音信息、 以及所述语音信息对应的文本信息; 分别对所述文本信息和所述语音信息进行编码, 得到文本编码信息和语音编码信 息; 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码 信息; 根据所述融合处理后的编码信息中与所述文本信息对应的编码信息, 预测所述文 本信息中每个文本单元在所述语音信息中对应的时间信息: 根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语音单元在 所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模型。 进一步, 如图 16所示, 电子设备还可以包括: 通信组件 163、 电源组件 164、 音 频组件 165、 显示器 166等其它组件。 图 16中仅示意性给出部分组件, 并不意味着电 子设备只包括图 16所示组件。 通信组件 163被配置为便于电子设备和其他设备之间有线或无线方式的通信。 电 子设备可以接入基于通信标准的无线网络, 如 WiFi, 2G或 3G, 或它们的组合。 在一 个示例性实施例中, 通信组件 163经由广播信道接收来自外部广播管理系统的广播信 号或广播相关信息。在一个示例性实施例中,所述通信组件 163还包括近场通信 (NFC) 模块, 以促进短程通信。 例如, 在 NFC模块可基于射频识别 (RFID)技术, 红外数据协 会 (IrDA)技术, 超宽带 (UWB)技术, 蓝牙 (BT)技术和其他技术来实现。 电源组件 164, 为电子设备的各种组件提供电力。 电源组件 164可以包括电源管 理系统,一个或多个电源,及其他与为电子设备生成、管理和分配电力相关联的组件。 音频组件 165被配置为输出和 /或输入音频信号。 例如, 音频组件 165包括一个麦 克风 (M1C), 当电子设备处于操作模式, 如呼叫模式、 记录模式和语音识别模式时, 麦克风被配置为接收外部音频信号。 所接收的音频信号可以被进一步存储在存储器 161 或经由通信组件 163 发送。 在一些实施例中, 音频组件 165还包括一个扬声器, 被设置为输出音频信号。 显示器 166 包括屏幕, 其屏幕可以包括液晶显示器 (LCD)和触摸面板 (TP)。 如果 屏幕包括触摸面板, 屏幕可以被实现为触摸屏, 以接收来自用户的输入信号。 触摸面 板包括一个或多个触摸传感器以感测触摸、 滑动和触摸面板上的手势。 所述触摸传感 器可以不仅感测触摸或滑动动作的边界, 而且还检测与所述触摸或滑动操作相关的持 续时间和压力。 另外, 本公开实施例还提供一种计算机可读存储介质, 其上存储有计算机程序, 所述计算机程序被处理器执行以实现上述实施例所述的模型预训练、 训练、 智能对话 方法。
需要说明的是, 在本文中, 诸如 ' '第一 ” 和 “第二” 等之类的关系术语用来将一 个实体或者操作与另一个实体或操作区分开来, 而不一定要求或者暗示这些实体或操 作之间存在任何这种实际的关系或者顺序。 而且, 术语 ' '包括 " 、 “包含" 或者其任 何其他变体意在涵盖非排他性的包含, 从而使得包括一系列要素的过程、 方法、 物品 或者设备不仅包括那些要素, 而且还包括没有明确列出的其他要素, 或者是还包括为 这种过程、 方法、物品或者设备所固有的要素。在没有更多限制的情况下, 由语句 “包 括一个 … … " 限定的要素, 并不排除在包括所述要素的过程、 方法、 物品或者设备中 还存在另外的相同要素。 以上所述是本公开的具体实施方式, 使本领域技术人员能够理解或实现本公开。 对这些实施例的多种修改对本领域的技术人员来说将是显而易见的, 本文中所定义的 一般原理可以在不脱离本公开的精神或范围的情况下, 在其它实施例中实现。 因此, 本公开将不会被隈制于本文所述的这些实施例, 而是要符合与本文所公开的原理和新 颖特点相一致的最宽的范围。 工业实用性 本公开实施例所提供的机器学习模型训练、 对话方法、 装置、 设备及介质应用于 机器学习场景中, 通过获取语音信息、 以及所述语音信息对应的文本信息, 并分别对 所述文本信息和所述语音信息进行编码,得到文本编码信息和语音编码信息。进一步, 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码信息, 根据所述融合处理后的编码信息, 预测所述文本信息中每个文本单元在所述语音信息 中对应的时间信息, 然后根据所述预测的时间信息、 以及所述文本信息中每个文本单 元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模型。 使得预训练模型可以将语音信息和文本信息在时序上进行对齐, 例 如, 文本信息中更细粒度的文本单元与语音信息中更细粒度的语音单元之间的对齐, 从而提高预训练模型对语音信息和文本信息的理解力, 从而提高预刮练模型对用户话 语理解的精准度。
Claims
1. 一种机器学习模型训练方法, 所述方法包括: 获取语音信息、 以及所述语音信息对应的文本信息; 分别对所述文本信息和所述语音信息进行编码, 得到文本编码信息和语音编码信 息; 对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码 信息; 根据所述融合处理后的编码信息中与所述文本信息对应的编码信息, 预测所述文 本信息中每个文本单元在所述语音信息中对应的时间信息; 根据所述预测的时间信息、 以及所述文本信息中每个文本单元对应的语音单元在 所述语音信息中的位置标注, 对第一机器学习模型进行预训练, 得到预训练模型。
2. 根据权利要求 1所述的方法, 其中, 分别对所述文本信息和所述语音信息进行编码, 得到文本编码信息和语音编码信息, 包括: 通过文本编码器对所述文本信息中每个文本单元分别包括的至少一个编码单元 进行编码, 得到文本编码信息, 所述文本编码信息包括各个编码单元的表示向量; 通过语音编码器对所述语音信息中的每个语音片段进行编码, 得到语音编码信息, 所述语音编码信息包括各个语音片段的表示向量。
3. 根据权利要求 2所述的方法, 其中, 所述融合处理后的编码信息包括所述各个编码单 元分别对应的融合表示向量、 以及所述各个语音片段分别对应的融合表示向量; 根据所述融合处理后的编码信息, 预测所述文本信息中每个文本单元在所述语音 信息中对应的时间信息, 包括: 若所述文本单元包括一个编码单元, 则根据所述编码单元对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间和结束时间; 若所述文本单元包括多个编码单元, 则根据所述多个编码单元中第一个编码单元 对应的融合表示向量, 预测所述文本单元在所述语音信息中对应的开始时间, 以及根 据所述多个编码单元中最后一个编码单元对应的融合表示向量, 预测所述文本单元在 所述语音信息中对应的结束时间。
4. 根据权利要求 3所述的方法, 其中, 根据所述预测的时间信息、 以及所述文本信息中 每个文本单元对应的语音单元在所述语音信息中的位置标注,对第一机器学习模型进 行预训练, 包括: 根据所述文本单元在所述语音信息中对应的开始时间和结束时间, 以及预先标注 的所述文本单元对应的语音单元在所述语音信息中的开始位置和结束位置, 构建第一 损失函数; 根据所述第一损失函数, 对第一机器学习模型进行预训练。
5. 根据权利要求 4所述的方法, 其中, 所述第一损失函数包括第一差值和笫二差值, 所 述第一差值是才艮据所述开始时间和所述开始位置得到的差值,所述第二差值是才艮据所 述结束时间和所述结束位置得到的差值。
6. 根据权利要求 1所述的方法, 其中, 所述语音信息包括历史语音和当前语音, 所述文 本信息包括历史文本和当前文本; 所述方法还包括: 根据所述融合处理后的编码信息, 判断所述历史语音和所述当前语音是否匹配, 得到第一判断结果, 以及判断所述历史文本和所述当前文本是否匹配, 得到第二判断 结果; 根据所述第一判断结果和所述第二判断结果, 预测输入样本的类型, 所述输入样 本包括所述语音信息和所述文本信息:
根据所述预测的输入样本的类型、 以及预先标注的所述输入样本的类型, 构建第 二损失函数, 并根据所述第二损失函数对所述第一机器学习模型进行预训练, 得到预 训练模型。
7. 一种机器学习模型训练方法, 所述方法包括: 获取目标任务的样本数据, 所述样本数据包括待处理数据和所述待处理数据的标 注结果, 所述待处理数据包括样本语音、 以及所述样本语音对应的样本文本; 将所述待处理数据输入到第二机器学习模型中, 使得所述第二机器学习模型输出 处理后的结果, 所述第二机器学习模型是根据如权利要求 1-6任一项所述的预训练方 法得到的预训练模型; 根据所述第二机器学习模型输出的处理后的结果、 以及所述待处理数据的标注结 果, 对所述第二机器学习模型进行训练, 得到训练后的机器学习模型。
8. 根据权利要求 7所述的方法, 其中, 所述目标任务包括如下至少一种: 情感分析任务、 情绪识别任务、 意图分析任务、 关键信息收集任务。
9. 一种智能对话方法, 所述方法包括: 获取目标用户和智能对话系统之间的历史对话, 以及所述历史对话对应的文本信 息; 将所述历史对话和所述文本信息输入到训练后的机器学习模型中, 使得所述机器 学习模型输出所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 所述机器 学习模型是根据权利要求 7所述的方法训练得到的; 才艮据所述目标用户的情感、 情绪、 意图、 关键信息中的至少一种, 与所述目标用 户进行智能对话。
10. 一种机器学习模型训练装置, 包括: 获取模块, 被设置为获取语音信息、 以及所述语音信息对应的文本信息; 编码模块, 被设置为分别对所述文本信息和所述语音信息进行编码, 得到文本编 码信息和语音编码信息; 融合处理模块, 被设置为对所述文本编码信息和所述语音编码信息进行融合处理, 得到融合处理后的编码信息; 预测模块, 被设置为根据所述融合处理后的编码信息中与所述文本信息对应的编 码信息, 预测所述文本信息中每个文本单元在所述语音信息中对应的时间信息; 预训练模块, 被设置为根据所述预测的时间信息、 以及所述文本信息中每个文本 单元对应的语音单元在所述语音信息中的位置标注, 对第一机器学习模型进行预训练。
11. 一种电子设备, 包括: 存储器; 处理器; 以及 计算机程序; 其中, 所述计算机程序存储在所述存储器中, 并被配置为由所述处理器执行以实 现如权利要求 1 -9中任一项所述的方法。
12. 一种计算机可读存储介质, 其上存储有计算机程序, 其中, 所述计算机程序被处理器 执行时实现如权利要求 1-9中任一项所述的方法。
Priority Applications (1)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| EP24789146.8A EP4654183A4 (en) | 2023-04-11 | 2024-03-29 | Machine learning model training method and apparatus, dialogue method and apparatus, device, and medium |
Applications Claiming Priority (2)
| Application Number | Priority Date | Filing Date | Title |
|---|---|---|---|
| CN202310397072.3 | 2023-04-11 | ||
| CN202310397072.3A CN116758917A (zh) | 2023-04-11 | 2023-04-11 | 机器学习模型训练、对话方法、装置、设备及介质 |
Publications (2)
| Publication Number | Publication Date |
|---|---|
| WO2024215250A1 true WO2024215250A1 (zh) | 2024-10-17 |
| WO2024215250A8 WO2024215250A8 (zh) | 2025-09-12 |
Family
ID=87948469
Family Applications (1)
| Application Number | Title | Priority Date | Filing Date |
|---|---|---|---|
| PCT/SG2024/050199 Ceased WO2024215250A1 (zh) | 2023-04-11 | 2024-03-29 | 机器学习模型训练、对话方法、装置、设备及介质 |
Country Status (3)
| Country | Link |
|---|---|
| EP (1) | EP4654183A4 (zh) |
| CN (1) | CN116758917A (zh) |
| WO (1) | WO2024215250A1 (zh) |
Families Citing this family (1)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN120673991A (zh) * | 2025-06-23 | 2025-09-19 | 北京博智酝育医疗科技有限公司 | 一种基于大语言模型的心理诊疗辅助分析方法及系统 |
Citations (4)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN114267345A (zh) * | 2022-02-25 | 2022-04-01 | 阿里巴巴达摩院(杭州)科技有限公司 | 模型训练方法、语音处理方法及其装置 |
| CN114360504A (zh) * | 2021-11-26 | 2022-04-15 | 腾讯科技(深圳)有限公司 | 音频处理方法、装置、设备、程序产品及存储介质 |
| CN114691852A (zh) * | 2022-06-01 | 2022-07-01 | 阿里巴巴达摩院(杭州)科技有限公司 | 人机对话系统及方法 |
| CN114936560A (zh) * | 2022-04-11 | 2022-08-23 | 阿里巴巴(中国)有限公司 | 人机交互方法、智能机器人和存储介质 |
Family Cites Families (13)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| KR102221513B1 (ko) * | 2019-02-28 | 2021-03-03 | 전남대학교산학협력단 | 음성 감정 인식 방법 및 시스템 |
| KR102862266B1 (ko) * | 2020-05-07 | 2025-09-19 | 구글 엘엘씨 | 종단 간 모델로 단어 타이밍 방출 |
| CN111898670B (zh) * | 2020-07-24 | 2024-04-05 | 深圳市声希科技有限公司 | 多模态情感识别方法、装置、设备及存储介质 |
| CN112069816A (zh) * | 2020-09-14 | 2020-12-11 | 深圳市北科瑞声科技股份有限公司 | 中文标点符号添加方法和系统及设备 |
| CN112435656B (zh) * | 2020-12-11 | 2024-03-01 | 平安科技(深圳)有限公司 | 模型训练方法、语音识别方法、装置、设备及存储介质 |
| CN112820281B (zh) * | 2020-12-31 | 2022-09-23 | 北京声智科技有限公司 | 一种语音识别方法、装置及设备 |
| CN113723105B (zh) * | 2021-04-13 | 2026-02-03 | 腾讯科技(北京)有限公司 | 语义特征提取模型的训练方法、装置、设备及存储介质 |
| CN114495938B (zh) * | 2021-12-04 | 2024-03-08 | 腾讯科技(深圳)有限公司 | 音频识别方法、装置、计算机设备及存储介质 |
| CN114373480B (zh) * | 2021-12-17 | 2025-08-05 | 腾讯音乐娱乐科技(深圳)有限公司 | 语音对齐网络的训练方法、语音对齐方法及电子设备 |
| CN115062691B (zh) * | 2022-05-26 | 2024-09-06 | 支付宝(杭州)信息技术有限公司 | 属性识别方法和装置 |
| CN115146743B (zh) * | 2022-08-31 | 2022-12-16 | 平安银行股份有限公司 | 性格识别模型的训练方法、性格识别方法、装置及系统 |
| CN115512695B (zh) * | 2022-09-15 | 2025-11-07 | 科大讯飞股份有限公司 | 语音识别方法、装置、设备及存储介质 |
| CN115599894A (zh) * | 2022-09-22 | 2023-01-13 | 号百信息服务有限公司(Cn) | 情绪识别的方法、装置、电子设备及存储介质 |
-
2023
- 2023-04-11 CN CN202310397072.3A patent/CN116758917A/zh active Pending
-
2024
- 2024-03-29 EP EP24789146.8A patent/EP4654183A4/en active Pending
- 2024-03-29 WO PCT/SG2024/050199 patent/WO2024215250A1/zh not_active Ceased
Patent Citations (4)
| Publication number | Priority date | Publication date | Assignee | Title |
|---|---|---|---|---|
| CN114360504A (zh) * | 2021-11-26 | 2022-04-15 | 腾讯科技(深圳)有限公司 | 音频处理方法、装置、设备、程序产品及存储介质 |
| CN114267345A (zh) * | 2022-02-25 | 2022-04-01 | 阿里巴巴达摩院(杭州)科技有限公司 | 模型训练方法、语音处理方法及其装置 |
| CN114936560A (zh) * | 2022-04-11 | 2022-08-23 | 阿里巴巴(中国)有限公司 | 人机交互方法、智能机器人和存储介质 |
| CN114691852A (zh) * | 2022-06-01 | 2022-07-01 | 阿里巴巴达摩院(杭州)科技有限公司 | 人机对话系统及方法 |
Non-Patent Citations (1)
| Title |
|---|
| See also references of EP4654183A4 * |
Also Published As
| Publication number | Publication date |
|---|---|
| CN116758917A (zh) | 2023-09-15 |
| EP4654183A1 (en) | 2025-11-26 |
| WO2024215250A8 (zh) | 2025-09-12 |
| EP4654183A4 (en) | 2026-03-04 |
Similar Documents
| Publication | Publication Date | Title |
|---|---|---|
| CN108509619A (zh) | 一种语音交互方法及设备 | |
| US20220076674A1 (en) | Cross-device voiceprint recognition | |
| CN113327609B (zh) | 用于语音识别的方法和装置 | |
| CN111368541B (zh) | 命名实体识别方法及装置 | |
| CN108831439A (zh) | 语音识别方法、装置、设备和系统 | |
| CN114627856A (zh) | 语音识别方法、装置、存储介质及电子设备 | |
| US11289075B1 (en) | Routing of natural language inputs to speech processing applications | |
| CN108564953A (zh) | 一种语音识别文本的标点处理方法及装置 | |
| CN108899013A (zh) | 语音搜索方法、装置和语音识别系统 | |
| WO2024088039A1 (zh) | 人机对话方法、对话网络模型的训练方法及装置 | |
| US20210327415A1 (en) | Dialogue system and method of controlling the same | |
| CN117992601B (zh) | 基于人工智能的公文生成方法及装置 | |
| CN108650543A (zh) | 视频的字幕编辑方法及装置 | |
| CN115270728A (zh) | 会议记录处理方法、装置、设备及存储介质 | |
| US12615254B2 (en) | Methods and systems for identifying communication sources across channels | |
| CN113590769A (zh) | 任务驱动型多轮对话系统中的状态追踪方法及装置 | |
| US11380308B1 (en) | Natural language processing | |
| WO2025096191A1 (en) | Entity resolution using audio signals | |
| CN111554300A (zh) | 音频数据处理方法、装置、存储介质及设备 | |
| RU2759090C1 (ru) | Способ управления диалогом и система понимания естественного языка в платформе виртуальных ассистентов | |
| CN113836932B (zh) | 交互方法、装置和系统,以及智能设备 | |
| CN116910297A (zh) | 歌曲搜索方法、装置、存储介质和计算设备 | |
| EP4139784B1 (en) | Hierarchical context specific actions from ambient speech | |
| CN116910249B (zh) | 一种文本情感分析方法、装置、电子设备及存储介质 | |
| CN114882880A (zh) | 基于解码器的语音唤醒方法及其相关设备 |
Legal Events
| Date | Code | Title | Description |
|---|---|---|---|
| 121 | Ep: the epo has been informed by wipo that ep was designated in this application |
Ref document number: 24789146 Country of ref document: EP Kind code of ref document: A1 |
|
| NENP | Non-entry into the national phase |
Ref country code: DE |
|
| WWP | Wipo information: published in national office |
Ref document number: 2024789146 Country of ref document: EP |